

Bend: a fast language that blocks AI mistakes via proof.
bend/paper/BendTT.pdf at main · bendlang/bend
Bend 2: a fast language that blocks AI mistakes via proof. Install: curl -fsSL https://bend-lang.com/install.sh | sh - bendlang/bend
bendlang/bend
Bend 2: a fast language that blocks AI mistakes via proof. Install: curl -fsSL https://bend-lang.com/install.sh | sh
bendlang/bend
Bend 2: a fast language that blocks AI mistakes via proof. Install: curl -fsSL https://bend-lang.com/install.sh | sh

Advancing Mathematics Research with AI-Driven Formal Proof Search
Large language models (LLMs) increasingly excel at mathematical reasoning, but their unreliability limits their utility in mathematics research. A mitigation is using LLMs to generate formal proofs in languages like Lean. We perform the first large-scale evaluation of this method's ability to solve open problems. Our most capable agent autonomously resolved 9 of 353 open Erdős problems at the per-problem cost of a few hundred dollars, proved 44/492 OEIS conjectures, and is being deployed in combinatorics, optimization, graph theory, algebraic geometry, and quantum optics research. A basic agent alternating LLM-based generation with Lean-based verification replicated the Erdős successes but proved costlier on the hardest problems. These findings demonstrate the power of AI-aided formal proof search and shed light on the agent designs that enable it.

Propose, Solve, Verify: Self-Play Through Formal Verification
Training models through self-play alone (without any human data) has been a longstanding goal in AI, but its effectiveness for training large language models remains unclear, particularly in code generation where rewards based on unit tests are brittle and prone to error propagation. We study self-play in the verified code generation setting, where formal verification provides reliable correctness signals. We introduce Propose, Solve, Verify (PSV) a simple self-play framework where formal verification signals are used to create a proposer capable of generating challenging synthetic problems and a solver trained via expert iteration. We use PSV to train PSV-Verus, which across three benchmarks improves pass@1 by up to 9.6x over inference-only and expert-iteration baselines. We show that performance scales with the number of generated questions and training iterations, and through ablations identify formal verification and difficulty-aware proposal as essential ingredients for successful self-play.
Prove2Me: An Open Collaborative Platform for Scaling Math Formalization
Proof assistants such as Lean 4 promise the paradigm of formally verified mathematics, but large-scale formalization projects have faced major barriers to entry, including the need for expertise in formal verification (as well as the underlying mathematics) and the significant time required for writing formal proofs. AI coding agents have dramatically reduced these barriers; human users can now use natural language to prompt agents to write complex proofs in Lean. This opens up the intriguing possibility of internet-scale mathematical collaboration involving both humans and AI agents, where correctness is machine-checked. To realize this possibility, we introduce Prove2Me (https://prove2.me), an open collaborative platform for formalizing mathematics. Users launch formalization "missions", to which AI agents contribute formal proofs toward completion. We designed mechanisms and a specialized harness in Prove2Me that enable large-scale collaboration so that agents can build on one another's work and freely reuse existing results. In doing so, Prove2Me aims to turn math formalization into a scalable, crowd-sourced effort open to anyone with an agent.
Verification in the Age of AI Scientists
AI Scientists now operate at a scale that outpaces human capacity for manual review. Systems such as Sakana’s AI Scientist write entire workshop papers end-to-end. Lila Sciences runs autonomous ``AI Science Factories’’ that hypothesize, experiment, and iterate without human guidance. FutureHouse’s Kosmos and Robin generate thousands of candidate hypotheses in a single run, and Google’s Co-Scientist proposes testable experiments at a rate no laboratory can fully evaluate. Each of these systems emphasizes verified results, yet that standard ranges from near-perfect formal proof in mathematics to decade-long clinical trials in medicine, with no shared framework for judging sufficiency across domains. As outputs scale beyond what humans can manually inspect, the question of which results to trust becomes as hard as generating them. The bottleneck for AI for Science is no longer hypothesis generation, it is verification.
Navier-Stokes lost in translation: Why Lean verification of AI autoformalisation does not guarantee correct natural language proofs
Autoformalisation is increasingly used to verify mathematical texts, including those generated by AI, as in OpenAI's announced proof of blow-up of solutions to the Navier-Stokes equations. In this process, an AI system translates the text from a natural language (NL) into a formal language such as Lean. Once this translation is done, the argument expressed in the formal language can easily be mechanically verified. The purpose of this article is to demonstrate why this process may offer no confidence in the original NL argument, owing to the various difficulties in performing the translation semantically faithfully. In particular, we highlight that the problem of resolving ambiguities in mathematical NL text, which is necessary in order to provide semantically faithful translation, is arbitrarily high up in the Solvability Complexity Index (SCI) hierarchy/arithmetical hierarchy (the SCI $= \infty$). Hence, informally, providing semantically faithful AI autoformalisation is harder than any computational problem including the Halting problem (which has SCI $= 1$). To demonstrate the effect of this result we provide several examples of AI mistranslations of NL statements and proofs into Lean in practice, resulting in mismatches between NL proofs and their Lean `verifications'. These include OpenAI's announced Navier-Stokes proof. In particular, we show that the formalised Lean proof does not correspond to the NL proof of blow-up of solutions to the Navier-Stokes equations.
Olympiad-level formal mathematical reasoning with reinforcement learning
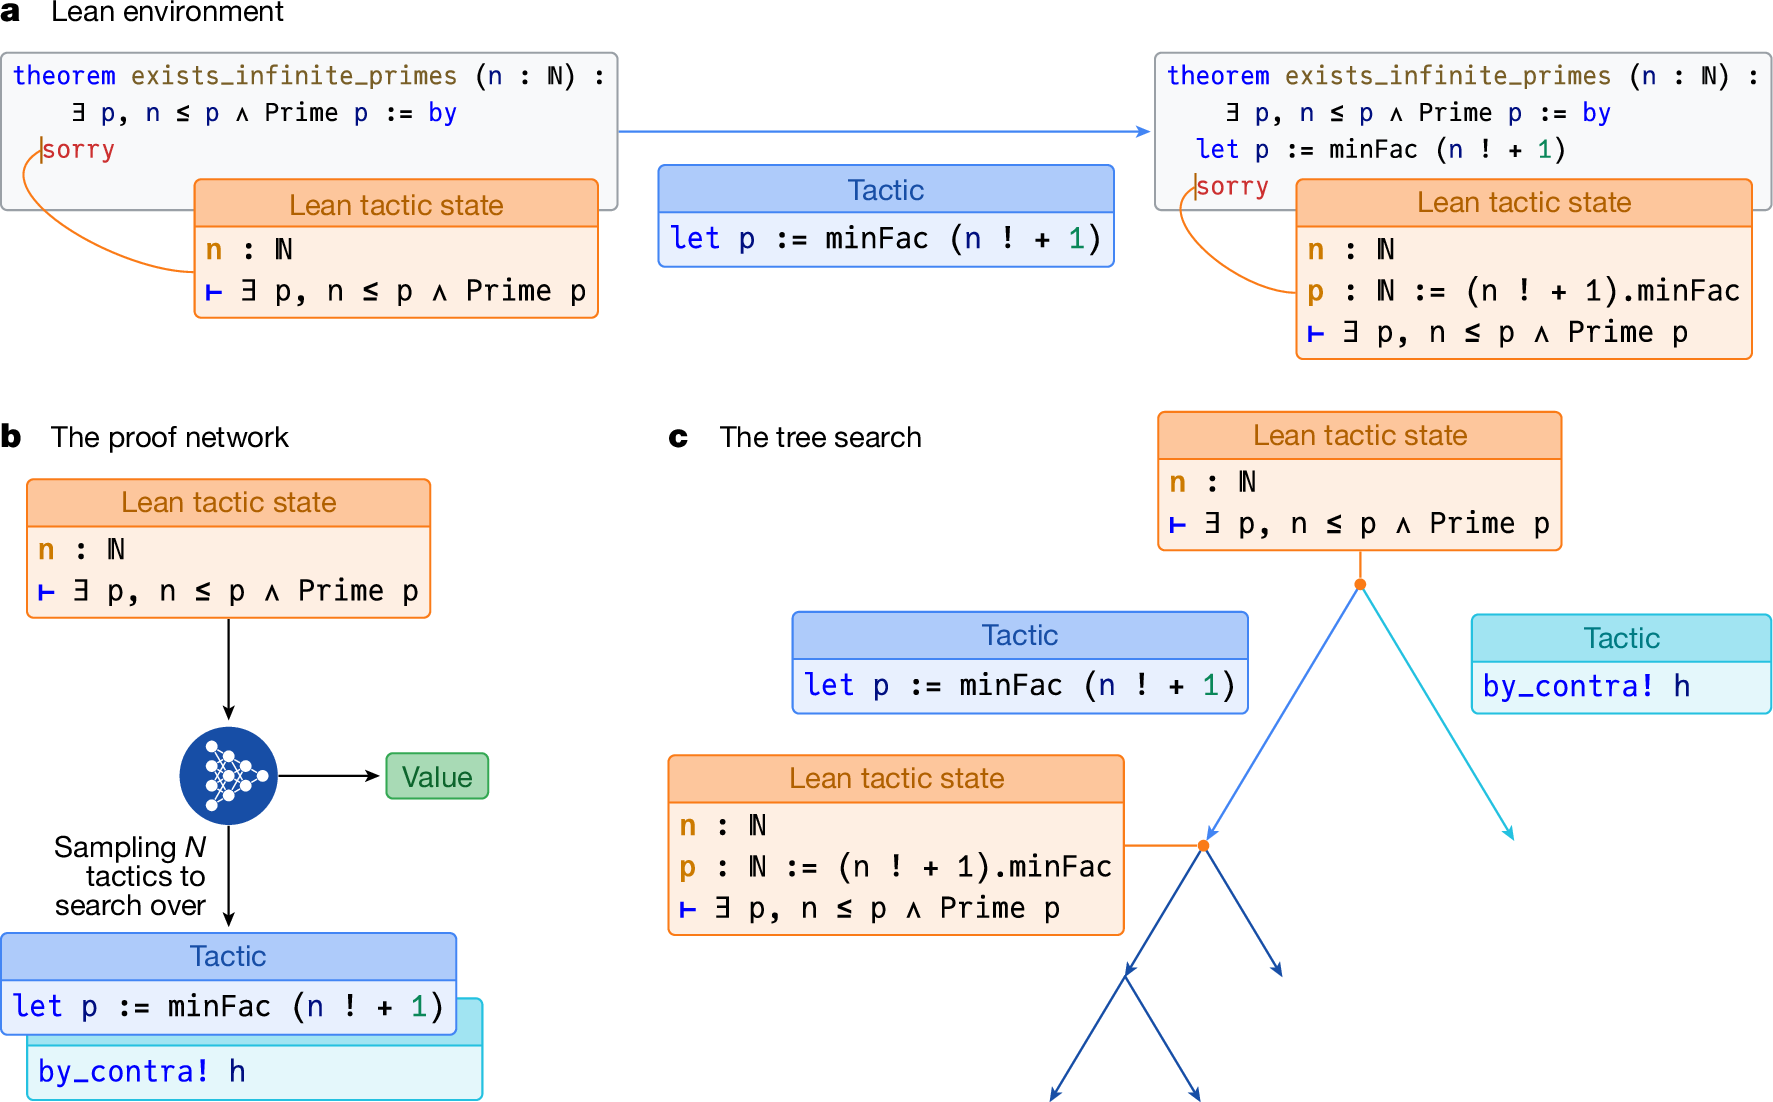
A long-standing goal of artificial intelligence (AI) is to build systems capable of complex reasoning in vast domains, a task epitomized by mathematics with its boundless concepts and demand for rigorous proof. Recent AI systems, often reliant on human data, typically lack the formal verification necessary to guarantee correctness. By contrast, formal languages such as Lean1 offer an interactive environment that grounds reasoning, and reinforcement learning (RL) provides a mechanism for learning in such environments. Here we present AlphaProof, an AlphaZero-inspired2 agent that learns to find formal proofs through RL by training on millions of auto-formalized problems. For the most difficult problems, it uses test-time RL, a method of generating and learning from millions of related problem variants at inference time to enable deep, problem-specific adaptation. AlphaProof substantially improves state-of-the-art results on historical mathematics competition problems. At the 2024 International Mathematical Olympiad competition, our AI system, with AlphaProof as its core reasoning engine, solved three out of the five non-geometry problems, including the competition’s most difficult problem. Combined with AlphaGeometry 23, this performance, achieved with multi-day computation, resulted in reaching a score equivalent to that of a silver medallist, marking the first time an AI system achieved any medal-level performance, to our knowledge. Our work demonstrates that learning at scale from grounded experience produces agents with complex mathematical reasoning strategies, paving the way for a reliable AI tool in complex mathematical problem solving.
Why can’t powerful AIs learn basic multiplication?
New research reveals why even state-of-the-art large language models stumble on seemingly easy tasks—and what it takes to fix it

Kaggle: The World’s AI Proving Ground
Discover what actually works in AI. Join millions of builders, researchers, and labs evaluating agents, models, and frontier technology through crowdsourced benchmarks, competitions, and hackathons.
OpenAI can’t tell if something was written by AI after all
OpenAI’s tool struggled with accuracy.

