

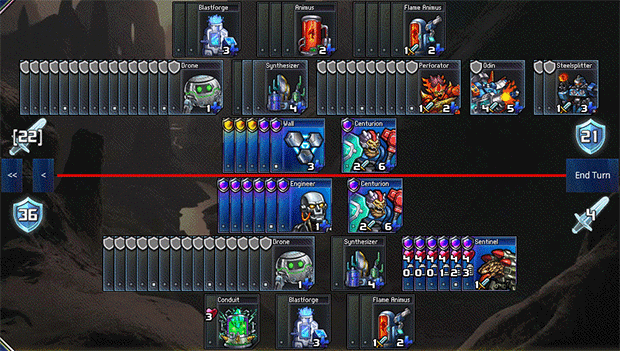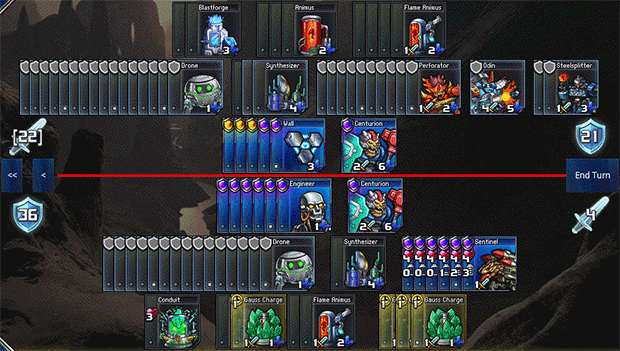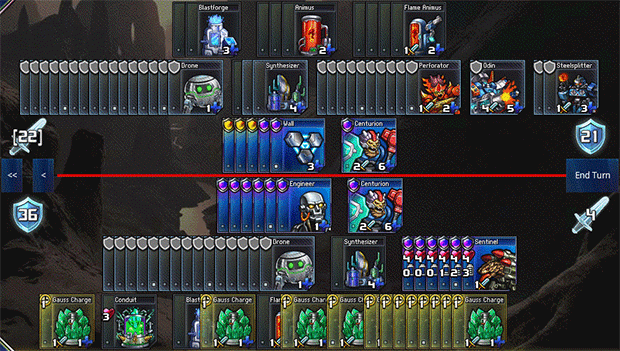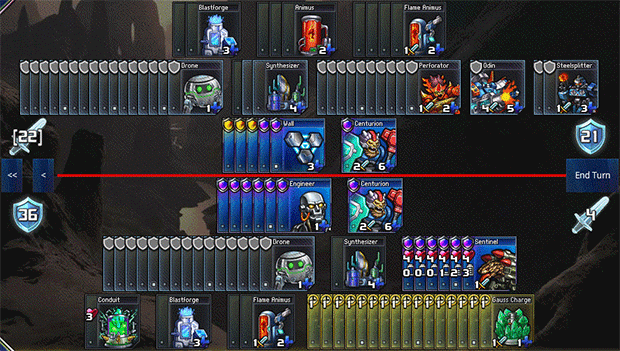
I write a lot about how bad output randomness is for games, but today I want to write about a problem common in many deterministic games – specifically ones that lack hidden information. Why …
The Law of Conservation of Information: Search Processes Only Redistribute Existing Information
Conservation of information sparked scientific interest once a recurring pattern was noticed in the evolutionary computing literature. In grappling with the creation of information through evolutionary algorithms, this literature consistently revealed that the information outputted by such algorithms always needed first to be programmed into them. Thus, the primary goal of this literature—to uncover how information could be created from scratch or de novo —was shown to be misconceived: the information was not created but instead shuffled around or smuggled in, implying that it already existed in some form or other. Information output in these situations therefore always presupposed a counterbalancing input of prior information. Once this pattern was seen, the next logical step was to quantify the amount of information inputted and outputted, demonstrating a consistent mathematical relation between the two. This led to the proof of a number of theorems about search. In these theorems, a baseline search with probability p of success gave way to an improved search with probability q of success. Typically p would be very small and close to zero, implying a practically impossible search (like searching for a needle in a haystack). By contrast, q would be much larger and close to one, implying an eminently doable search. The punchline of these theorems was that, as the improved search became itself the subject of a search (a search for a search , or S4S), the probability of finding it could not exceed p / q , rendering success of the improved search no more probable than success of the original baseline search, in effect filling one hole by digging another. Such conservation-of-information theorems, as they came to be called, were search-space specific, adapted to different kinds of search across a range of search spaces. There was a measure-theoretic theorem in which probability measures guided search. There were also function-theoretic and fitness-theoretic theorems where mappings into the search space as well as fitness functions on the search space respectively guided search. The key insight of this paper is that all these conservation-of-information theorems are special cases of a simple probabilistic relation based on elementary probability theory. This paper identifies the underlying rationale that makes all the previous conservation-of-information theorems work. In so doing, it provides a straightforward proof and general formulation of what may rightly be called the Law of Conservation of Information.
Execution in strategy games should be considered “randomness”
I have long considered execution to be basically a form of randomness, similar to dice rolls or card draws. I have also long recognized that not everyone agrees with me, and some people find the id…

Scalable decision-making for games of imperfect information
Real-world decision-making generally involves hidden information, that is, information that is unknown to one agent but possessed by another. Unfortunately, the presence of large amounts of hidden information renders established reinforcement learning and search approaches ineffective. Even with multimillion-dollar industrial research efforts1, top-human-level play at Stratego—a board wargame with hidden information on a massive scale—has remained beyond the reach of artificial intelligence (AI). Here we introduce Ataraxos, an AI for Stratego based on general techniques that we developed for both self-play reinforcement learning and test-time search under hidden information. Ataraxos defeated the most decorated human Stratego player of all time by a large margin—achieving, to our knowledge, the first superhuman result in the game’s history—while consuming orders of magnitude less compute and data than previous efforts. Using the same techniques, we built a superhuman AI for Barrage Stratego and state-of-the-art AIs for Hanabi and dou dizhu, all with low cost and high sample efficiency. The success of this approach across adversarial, cooperative and team games establishes a design pattern for reinforcement learning and search that is effective under large amounts of hidden information, a longstanding desideratum of the field of strategic decision-making.

Game Theory | Open Yale Courses
This course is an introduction to game theory and strategic thinking. Ideas such as dominance, backward induction, Nash equilibrium, evolutionary stability, commitment, credibility, asymmetric information, adverse selection, and signaling are discussed and applied to games played in class and to examples drawn from economics, politics, the movies, and elsewhere.
Look-ahead Reasoning with a Learned Model in Imperfect Information Games
Test-time reasoning significantly enhances pre-trained AI agents' performance. However, it requires an explicit environment model, often unavailable or overly complex in real-world scenarios....

Predicting outcomes for games of skill by redefining what it means to win
The Elo rating system is a highly successful ranking algorithm for games of skill where, by construction, one team wins and the other loses. A primary limitation of the original Elo algorithm is its inability to predict information beyond a match's win-loss probability. Specifically, the victor is awarded the same point bounty if he beats a team by 1 point or 10 points; only the rating difference between the team and its opponent affects the match bounty. In this work, we explain that Elo ratings and predictions can be naturally extended to include margin-of-victory information by simply redefining "what it means to win." We create ratings for each value of the margin-of-victory and use these ratings to predict the full distribution of point spread outcomes for matches which have not yet been played.
The Myth of Deterministic Software
How I've come to terms with LLM non-determinism in software and abandoned the comforting lies we've been telling ourselves about traditional software.
Magic: The Gathering is Turing Complete
$\textit{Magic: The Gathering}$ is a popular and famously complicated trading card game about magical combat. In this paper we show that optimal play in real-world $\textit{Magic}$ is at least as...
The Futility of Bias-Free Learning and Search
Building on the view of machine learning as search, we demonstrate the necessity of bias in learning, quantifying the role of bias (measured relative to a collection of possible datasets, or more generally, information resources) in increasing the probability of success. For a given degree of bias towards a fixed target, we show that the proportion of favorable information resources is strictly bounded from above. Furthermore, we demonstrate that bias is a conserved quantity, such that no algorithm can be favorably biased towards many distinct targets simultaneously. Thus bias encodes trade-offs. The probability of success for a task can also be measured geometrically, as the angle of agreement between what holds for the actual task and what is assumed by the algorithm, represented in its bias. Lastly, finding a favorably biasing distribution over a fixed set of information resources is provably difficult, unless the set of resources itself is already favorable with respect to the given task and algorithm.
Data Banzhaf: A Robust Data Valuation Framework for Machine Learning
Data valuation has wide use cases in machine learning, including improving data quality and creating economic incentives for data sharing. This paper studies the robustness of data valuation to noisy model performance scores. Particularly, we find that the inherent randomness of the widely used stochastic gradient descent can cause existing data value notions (e.g., the Shapley value and the Leave-one-out error) to produce inconsistent data value rankings across different runs. To address this challenge, we introduce the concept of safety margin, which measures the robustness of a data value notion. We show that the Banzhaf value, a famous value notion that originated from cooperative game theory literature, achieves the largest safety margin among all semivalues (a class of value notions that satisfy crucial properties entailed by ML applications and include the famous Shapley value and Leave-one-out error). We propose an algorithm to efficiently estimate the Banzhaf value based on the Maximum Sample Reuse (MSR) principle. Our evaluation demonstrates that the Banzhaf value outperforms the existing semivalue-based data value notions on several ML tasks such as learning with weighted samples and noisy label detection. Overall, our study suggests that when the underlying ML algorithm is stochastic, the Banzhaf value is a promising alternative to the other semivalue-based data value schemes given its computational advantage and ability to robustly differentiate data quality.
Cryptographic Nature
I consider the many ways in which evolved information-flows are restricted and metabolic resources protected and hidden -- the thesis of living phenomena as evolutionary cryptosystems. I present the information theory of secrecy systems and discuss mechanisms acquired by evolved lineages that encrypt sensitive heritable information with random keys. I explore the idea that complexity science is a cryptographic discipline as "frozen accidents", or various forms of regularized randomness, historically encrypt adaptive dynamics.
Building AI Products In The Probabilistic Era
AI turns products from deterministic functions into probabilistic systems. That requires expanding old playbooks (SLOs, funnels, siloed finance), and reasoning in terms of trajectories, Minimum Viable Intelligence thresholds, and data as company operating system.
From Predictive Algorithms to Automatic Generation of Anomalies
Machine learning algorithms can find predictive signals that researchers fail to notice; yet they are notoriously hard-to-interpret. How can we extract theoretical insights from these black boxes? History provides a clue. Facing a similar problem – how to extract theoretical insights from their intuitions – researchers often turned to “anomalies:” constructed examples that highlight flaws in an existing theory and spur the development of new ones. Canonical examples include the Allais paradox and the Kahneman-Tversky choice experiments for expected utility theory. We suggest anomalies can extract theoretical insights from black box predictive algorithms. We develop procedures to automatically generate anomalies for an existing theory when given a predictive algorithm. We cast anomaly generation as an adversarial game between a theory and a falsifier, the solutions to which are anomalies: instances where the black box algorithm predicts - were we to collect data - we would likely observe violations of the theory. As an illustration, we generate anomalies for expected utility theory using a large, publicly available dataset on real lottery choices. Based on an estimated neural network that predicts lottery choices, our procedures recover known anomalies and discover new ones for expected utility theory. In incentivized experiments, subjects violate expected utility theory on these algorithmically generated anomalies; moreover, the violation rates are similar to observed rates for the Allais paradox and Common ratio effect.

For something so important for applications (arguably moreso than the forward Game Theory problem), I was surprised at how scattered are the resources to learn about it. Feels very jagged. Started a semble collection: semble.so/profile/mptouzel.bsky.social/…! Will add more later. Please consider adding as well!

Mechanism Design - Learning Resources (by Max Puelma Touzel) — Semble
semble.so