Learn how Warren Buffett and Charlie Munger turn curiosity into insight. Discover how interest-driven learning builds understanding and reveals hidden opportunities.
Large-Scale Study of Curiosity-Driven Learning
Burda*, Edwards*, Pathak* et.al. (* equal contribution, alphabetical order) Large-Scale Study of Curiosity-Driven Learning. 2018.

Opinion | Can You Get Smarter? (Published 2015)
There is much that you can do to keep cognitively sharp.

The Busy Person's Guide to Thinking
Thinking better isn't about learning more; it's about doing a few simple things that really help create unstoppable progress.
Mental Models: The Best Way to Make Intelligent Decisions (~100 Models Explained)
The smartest people in the world use mental models to make intelligent decisions, avoid stupidity, and increase productivity. Let's take a look at how ...
The Wisdom of Individuals: Exploring People's Knowledge About Everyday Events Using Iterated Learning
Abstract Determining the knowledge that guides human judgments is fundamental to understanding how people reason, make decisions, and form predictions. We use an experimental procedure called ‘‘iterated learning,’’ in which the responses that people give on one trial are used to generate the data they see on the next, to pinpoint the knowledge that informs people's predictions about everyday events (e.g., predicting the total box office gross of a movie from its current take). In particular, we use this method to discriminate between two models of human judgments: a simple Bayesian model ( Griffiths & Tenenbaum, 2006 ) and a recently proposed alternative model that assumes people store only a few instances of each type of event in memory (Min K ; Mozer, Pashler, & Homaei, 2008 ). Although testing these models using standard experimental procedures is difficult due to differences in the number of free parameters and the need to make assumptions about the knowledge of individual learners, we show that the two models make very different predictions about the outcome of iterated learning. The results of an experiment using this methodology provide a rich picture of how much people know about the distributions of everyday quantities, and they are inconsistent with the predictions of the Min K model. The results suggest that accurate predictions about everyday events reflect relatively sophisticated knowledge on the part of individuals.

Thinking Fast, Slow, Artificially: AI and Your Brain
AI can boost your decisions — or quietly undermine them. Wharton researchers introduce a new theory of cognition that every leader needs to understand.

Introducing Nested Learning: A new ML paradigm for continual learning
Ali Behrouz, Student Researcher, and Vahab Mirrokni, VP and Google Fellow, Google Research

Learning with AI falls short compared to old-fashioned web search
Doing the mental work of connecting the dots across multiple web queries appears to help people understand the material better compared to an AI summary.
Learning with AI falls short compared to old-fashioned web search
Doing the mental work of connecting the dots across multiple web queries appears to help people understand the material better compared to an AI summary.
Learning to Learn: You, Too, Can Rewire Your Brain (Published 2017)
How an engineering professor who “flunked my way” through high school math and science went on to create the world’s most popular online course.

How Learning Happens | Seminal Works in Educational Psychology and Wha
How Learning Happens introduces 28 giants of educational research and their findings on how we learn and what we need to learn effectively, efficiently, and

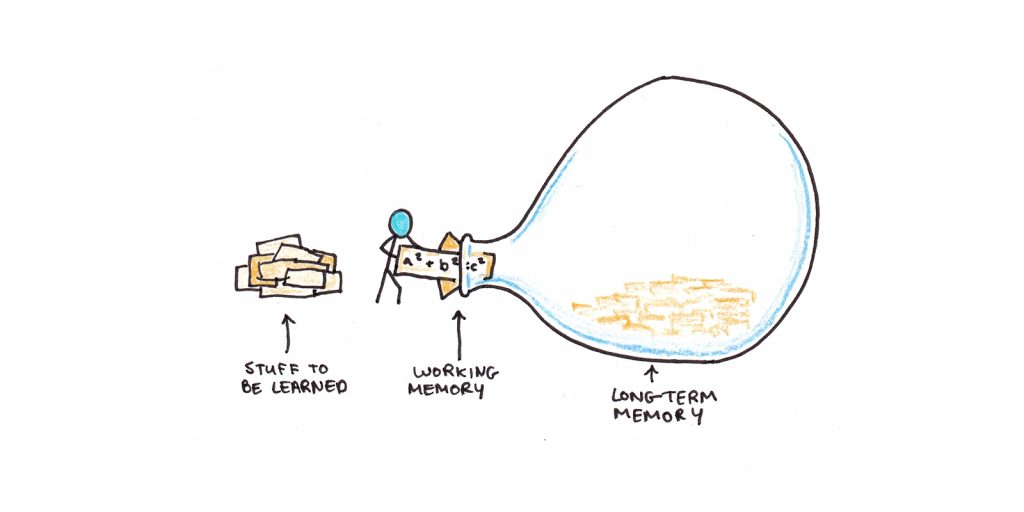
Cognitive Load Theory and its Applications for Learning - Scott H Young
What makes learning hard? How can we make it easier? Cognitive load theory explains how we learn and how to do it better.
Build a Reasoning Model (From Scratch)
"An exceptional deep dive into the next frontier of AI.” —Aman Chadha, Google Build a Reasoning Model (From Scratch) is a practical guide to understanding how modern reasoning-oriented LLMs work by building their core methods step by step. The book tells a clear engineering story: start with a conventional pre-trained LLM, learn how text generation works, build reliable evaluation tools, improve reasoning through inference-time methods, then move into training-based approaches such as reinforcement learning and distillation. The progression is deliberate. Early chapters establish the baseline model and explain text generation, KV caching, and evaluation with math verifiers. The middle chapters show how reasoning can be improved without changing model weights, using chain-of-thought prompting, sampling, self-consistency, response scoring, and self-refinement. Later chapters move to changing the model itself through reinforcement learning with verifiable rewards, GRPO improvements, format rewards, and finally distillation from stronger reasoning models into smaller ones. The book is especially useful because it implements the core methods from scratch rather than treating them as black-box library calls. Readers see how self-consistency, self-refinement, Best-of-N, and training-based methods actually work, including their cost and latency trade-offs. It also discusses common failure modes, including cases where refinement can make answers worse. Difficult concepts such as softmax, temperature, and top-p sampling are clarified with code-linked explanations and diagrams, and visual workflows make pipelines and scoring methods easier to follow. Reading the book feels like following a guided technical build rather than a loose survey of AI topics. Each concept is introduced because the project now needs it. Diagrams, roadmaps, code listings, exercises, and repeated workflow summaries help readers stay oriented through advanced material. This structure reflects Sebastian Raschka’s professional strength: explaining complex machine learning topics by making every detail concrete and showing exactly where each section fits in the larger story. He does not treat mechanisms like evaluation, log-probabilities, KL regularization, or distillation as isolated abstractions; he connects them to the goal of making reasoning models understandable and implementable. Physically and organizationally, the book has eight chapters and seven substantial appendixes. That design keeps the main narrative focused while moving supporting material like references, exercise solutions, model source code, larger models, batching, evaluation alternatives, and chat interfaces into ordered appendixes. The result is a logically flowing book that remains hands-on, navigable, and technically deep without constantly interrupting the central build.
Works in Progress: The Long Journey to Doing Good Better
The more I learn, the more I realize how much I don’t know. — Albert Einstein