

User intent declarations can be viewed as propositional attitudes (permission, prohibition, desire, intention, belief, etc.) over structured descriptions of data use. Treating them that way gives you composable building blocks from existing theory and lens-based translations between community vocabularies that make explicit what each translation cannot carry through.
User Intents as Living Data — A Descriptive Meta-Framework
A response to Bluesky's User Intents proposal: instead of prescribing a fixed set of intent categories, treat them as living data and use panproto lenses to map between the vocabularies that different communities will inevitably create.
Proposal: User Intents for Data Reuse · bluesky-social atproto · Discussion #3617
This is a discussion thread for the User Intents for Data Reuse proposal.
De-anthropomorphizing “AI”: From wishful mnemonics to accurate nomenclature
Language matters. How we describe “AI” technology influences how it is perceived, deployed, and trusted. Extravagant and persuasive language incites hype. It is the responsibility of journalists, companies, and scholars to characterize technology in ways that inform and empower their readers by using appropriate terminology and avoiding inflated claims. One type of inflated claim comes from using anthropomorphizing language to describe system functionality. Anthropomorphization is the attribution of human capabilities and characteristics to the inanimate system. In this paper, we present a linguistic analysis of anthropomorphizing language in 29 texts (a total of 1,368 sentences) from academic articles, online news articles, and company blog posts. We construct a taxonomy of eight categories of anthropomorphization: Cognizer, Products of cognition, Emotion, Communication, Agent, Human role analogy, Names and pronouns, and Biological metaphors. Following this taxonomy we present concrete strategies for how to de-anthropomorphize the language we use to describe “AI” based on a functionality-first principle.
Biased AI writing assistants shift users’ attitudes on societal issues
Artificial intelligence (AI) writing assistants powered by large language models (LLMs) are increasingly used to make autocomplete suggestions to people as they write text. Can these AI writing assistants affect people’s attitudes in this process? In two large-scale preregistered experiments ( N = 2582), we exposed participants writing about important societal issues to an AI writing assistant that provided biased autocomplete suggestions. When using the AI assistant, the attitudes participants expressed in a posttask survey converged toward the AI’s position. However, a majority of participants were unaware of the AI suggestions’ bias and their influence. Further, the influence of the AI writing assistant was stronger than the influence of similar suggestions presented as static text, showing that the influence is not fully explained by these suggestions, increasing accessibility of the biased information. Last, warning participants about assistants’ bias before or after exposure does not mitigate the attitude-shift effect. , Biased AI writing assistants shift people’s attitudes about societal issues; common interventions do not prevent this influence.
Permissioned data by dholms · Pull Request #94 · bluesky-social/proposals
This is an initial proposal for permissioned data. Details, terminology, and behaviors are all likely to change. For a friendly introduction to the protocol, check my my Leaflets. For discussion, f...
A Human-Centric Framework for Data Attribution in Large Language Models
In the current Large Language Model (LLM) ecosystem, creators have little agency over how their data is used, and LLM users may find themselves unknowingly plagiarizing existing sources. Attribution of LLM-generated text to LLM input data could help with these challenges, but so far we have more questions than answers: what elements of LLM outputs require attribution, what goals should it serve, how should it be implemented? We contribute a human-centric data attribution framework, which situates the attribution problem within the broader data economy. Specific use cases for attribution, such as creative writing assistance or fact-checking, can be specified via a set of parameters (including stakeholder objectives and implementation criteria). These criteria are up for negotiation by the relevant stakeholder groups: creators, LLM users, and their intermediaries (publishers, platforms, AI companies). The outcome of domain-specific negotiations can be implemented and tested for whether the stakeholder goals are achieved. The proposed approach provides a bridge between methodological NLP work on data attribution, governance work on policy interventions, and economic analysis of creator incentives for a sustainable equilibrium in the data economy.

LLM-generated messages can persuade humans on policy issues
The emergence of large language models (LLMs) has made it possible for generative artificial intelligence (AI) to tackle many higher-order cognitive tasks, with critical implications for industry, government, and labor markets. Here, we investigate whether existing, openly-available LLMs can be used to create messages capable of influencing humans’ political attitudes. Across three pre-registered experiments (total N = 4829), participants who read persuasive messages generated by LLMs showed significantly more attitude change across a range of policies - including polarized policies, like an assault weapons ban, a carbon tax, and a paid parental-leave program - relative to control condition participants who read a neutral message. Overall, LLM-generated messages were similarly effective in influencing policy attitudes as messages crafted by lay humans. Participants’ reported perceptions of the authors of the persuasive messages suggest these effects occurred through somewhat distinct causal pathways. While the persuasiveness of LLM-generated messages was associated with perceptions that the author used more facts, evidence, logical reasoning, and a dispassionate voice, the persuasiveness of human-generated messages was associated with perceptions of the author as unique and original. These results demonstrate that recent developments in AI make it possible to create politically persuasive messages quickly, cheaply, and at massive scale.

Add community.lexicon.preference.ai lexicon by ngerakines · Pull Request #72 · lexicon-community/lexicon
Summary Introduces the community.lexicon.preference.ai lexicon for declaring user preferences regarding AI usage of their public data Decomposes AI usage into four distinct categories (training, i...
On the Conversational Persuasiveness of Large Language Models: A Randomized Controlled Trial
The development and popularization of large language models (LLMs) have raised concerns that they will be used to create tailor-made, convincing arguments to push false or misleading narratives online. Early work has found that language models can generate content perceived as at least on par and often more persuasive than human-written messages. However, there is still limited knowledge about LLMs' persuasive capabilities in direct conversations with human counterparts and how personalization can improve their performance. In this pre-registered study, we analyze the effect of AI-driven persuasion in a controlled, harmless setting. We create a web-based platform where participants engage in short, multiple-round debates with a live opponent. Each participant is randomly assigned to one of four treatment conditions, corresponding to a two-by-two factorial design: (1) Games are either played between two humans or between a human and an LLM; (2) Personalization might or might not be enabled, granting one of the two players access to basic sociodemographic information about their opponent. We found that participants who debated GPT-4 with access to their personal information had 81.7% (p < 0.01; N=820 unique participants) higher odds of increased agreement with their opponents compared to participants who debated humans. Without personalization, GPT-4 still outperforms humans, but the effect is lower and statistically non-significant (p=0.31). Overall, our results suggest that concerns around personalization are meaningful and have important implications for the governance of social media and the design of new online environments.
Directing large language models to follow the letter or spirit of the law
The distinction between the spirit and letter of the law is a central issue across research and everyday life, and a growing concern for building safe, intelligent machines. What is this distinction based on, and how can we develop machines that follow the intention behind a rule? We used targeted adaptation that made large language models prioritize the spirit or letter of the law. With minimal modifications, our method significantly changed LLM behavior across diverse measures, novel vignettes, real-world scenarios, and influential legal cases. An analysis of model internals revealed a low-dimensional space with three interpretable dimensions matching a formal pre-specified framework for the geometry of legal concepts. These findings show how legal thought in LLMs may be organized and directed.
The potential of generative AI for personalized persuasion at scale
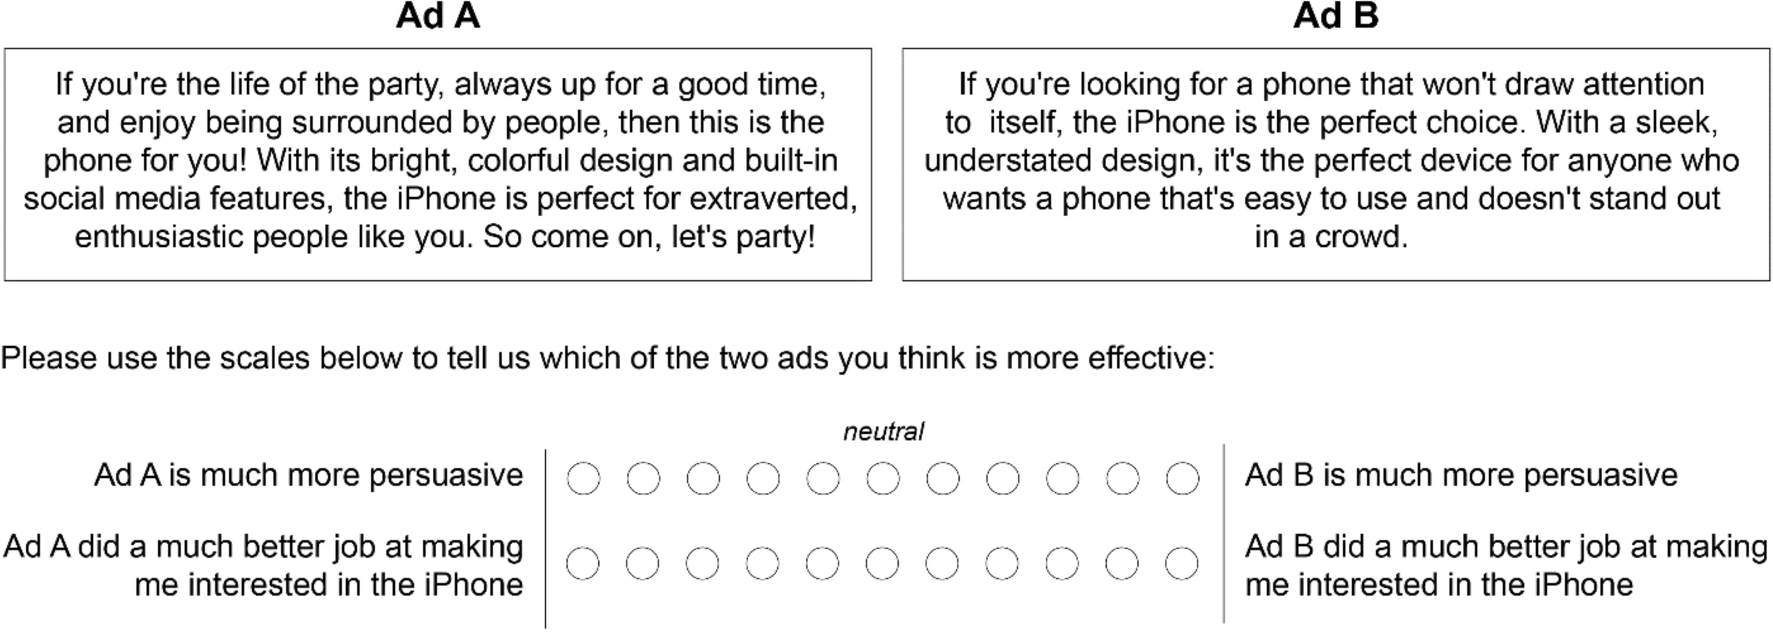
Matching the language or content of a message to the psychological profile of its recipient (known as “personalized persuasion”) is widely considered to be one of the most effective messaging strategies. We demonstrate that the rapid advances in large language models (LLMs), like ChatGPT, could accelerate this influence by making personalized persuasion scalable. Across four studies (consisting of seven sub-studies; total N = 1788), we show that personalized messages crafted by ChatGPT exhibit significantly more influence than non-personalized messages. This was true across different domains of persuasion (e.g., marketing of consumer products, political appeals for climate action), psychological profiles (e.g., personality traits, political ideology, moral foundations), and when only providing the LLM with a single, short prompt naming or describing the targeted psychological dimension. Thus, our findings are among the first to demonstrate the potential for LLMs to automate, and thereby scale, the use of personalized persuasion in ways that enhance its effectiveness and efficiency. We discuss the implications for researchers, practitioners, and the general public.
Lexicon Service Docs - at:// pizza thoughts
Riffing on some ways to make network services more legible to humans and machines
A Theory of Response Sampling in LLMs: Part Descriptive and Part Prescriptive
Large Language Models (LLMs) are increasingly utilized in autonomous decision-making, where they sample options from vast action spaces. However, the heuristics that guide this sampling process remain under-explored. We study this sampling behavior and show that this underlying heuristics resembles that of human decision-making: comprising a descriptive component (reflecting statistical norm) and a prescriptive component (implicit ideal encoded in the LLM) of a concept. We show that this deviation of a sample from the statistical norm towards a prescriptive component consistently appears in concepts across diverse real-world domains like public health, and economic trends. To further illustrate the theory, we demonstrate that concept prototypes in LLMs are affected by prescriptive norms, similar to the concept of normality in humans. Through case studies and comparison with human studies, we illustrate that in real-world applications, the shift of samples toward an ideal value in LLMs' outputs can result in significantly biased decision-making, raising ethical concerns.
looking for feedback on the first pass of permissioned data protocol lexicons! hop in & let me know your thoughts! discourse.atprotocol.community/t/permissioned-data-pds-lexic…

Permissioned Data PDS Lexicons
discourse.atprotocol.communityNew blog post: Signaling AI Preferences on ATProto. Introducing community.lexicon.preference.ai, a lexicon for granular AI data usage preferences with scoped overrides for specific entities and collections. #AI #atproto

Signaling AI Preferences on ATProto
ngerakines.leaflet.pub
