

This paper presents and tests AllAI, an app that utilizes state-of-the-art NLP technology to assist second language acquisition through a novel method of sentence-based spaced repetition. Diverging from current single word or fixed sentence repetition, AllAI dynamically combines words due for repetition into sentences, enabling learning words in context while scheduling them independently. This research explores various suitable NLP paradigms and finds a few-shot prompting approach and retrieval of existing sentences from a corpus to yield the best correctness and scheduling accuracy. Subsequently, it evaluates these methods on 26 learners of Danish, finding a four-fold increase in the speed at which new words are learned, compared to conventional spaced repetition. Users of the retrieval method also reported significantly higher enjoyment, hinting at a higher user engagement.
Spaced repetition
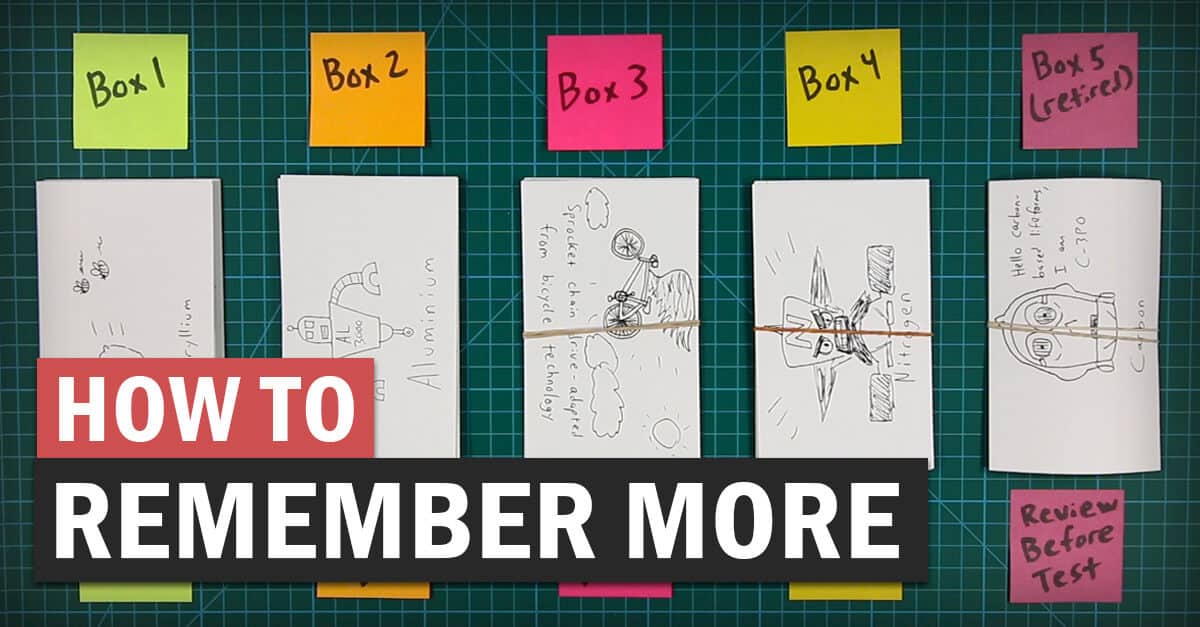
Spaced repetition is an evidence-based learning technique that is usually performed with flashcards. Newly introduced and more difficult flashcards are shown more frequently, while older and less difficult flashcards are shown less frequently in order to exploit the psychological spacing effect. The use of spaced repetition has been proven to increase the rate of learning.

How to Remember More of What You Learn with Spaced Repetition
Using spaced repetition in conjunction with other study techniques can help you memorize information much, much more quickly. Here's how to do it.
Mochi - Spaced repetition flashcards
Take notes and make flashcards using markdown, then study them using spaced repetition.
Do LLMs write like humans? Variation in grammatical and rhetorical styles
As large language models (LLMs) have grown in power and become more widely available, research has focused on their ability to complete various tasks and the biases they exhibit when doing so. In this study, we instead examine their writing style in detail. We show that instruction-tuned models, which are trained to answer questions and solve problems, have a distinct noun-heavy, informationally dense writing style, even when prompted to match the style of informal speech and writing. These findings suggest that instruction-tuned models generate text that does not align with genre conventions familiar to human audiences, and demonstrate the value of linguistic variables in evaluating the output of LLMs., Large language models (LLMs) are capable of writing grammatical text that follows instructions, answers questions, and solves problems. As they have advanced, it has become difficult to distinguish their output from human-written text. While past research has found some differences in features such as word choice and punctuation and developed classifiers to detect LLM output, none has studied the rhetorical styles of LLMs. Using several variants of Llama 3 and GPT-4o, we construct two parallel corpora of human- and LLM-written texts from common prompts. Using Douglas Biber’s set of lexical, grammatical, and rhetorical features, we identify systematic differences between LLMs and humans and between different LLMs. These differences persist when moving from smaller models to larger ones and are larger for instruction-tuned models than base models. This observation of differences demonstrates that despite their advanced abilities, LLMs struggle to match human stylistic variation. Attention to more advanced linguistic features can hence detect patterns in their behavior not previously recognized.

Math Academy
Q. Michael Pershan’s main critique of spaced repetition in the context of Math Academy?A. It reinforces his memory of a shallow understanding.
Do language models accommodate their users? A study of linguistic convergence
While large language models (LLMs) are generally considered proficient in generating language, how similar their language usage is to that of humans remains understudied. In this paper, we test whether models exhibit linguistic convergence, a core pragmatic element of human language communication: do models adapt, or converge, to the linguistic patterns of their user? To answer this, we systematically compare model completions of existing dialogues to original human responses across sixteen language models, three dialogue corpora, and various stylometric features. We find that models strongly converge to the conversation's style, often significantly overfitting relative to the human baseline. While convergence patterns are often feature-specific, we observe consistent shifts in convergence across modeling settings, with instruction-tuned and larger models converging less than their pretrained and smaller counterparts. Given the differences in human and model convergence patterns, we hypothesize that the underlying mechanisms driving these behaviors are very different.
Do language models accommodate their users? A study of linguistic convergence
While large language models (LLMs) are generally considered proficient in generating language, how similar their language usage is to that of humans remains understudied. In this paper, we test whether models exhibit linguistic convergence, a core pragmatic element of human language communication: do models adapt, or converge, to the linguistic patterns of their user? To answer this, we systematically compare model completions of existing dialogues to original human responses across sixteen language models, three dialogue corpora, and various stylometric features. We find that models strongly converge to the conversation's style, often significantly overfitting relative to the human baseline. While convergence patterns are often feature-specific, we observe consistent shifts in convergence across modeling settings, with instruction-tuned and larger models converging less than their pretrained and smaller counterparts. Given the differences in human and model convergence patterns, we hypothesize that the underlying mechanisms driving these behaviors are very different.
OpenDeck · Learn languages you own
Learn languages with spaced-repetition flashcards you own.
MCIF: Multimodal Crosslingual Instruction-Following Benchmark from Scientific Talks
Recent advances in large language models have laid the foundation for multimodal LLMs (MLLMs), which unify text, speech, and vision within a single framework. As these models are rapidly evolving toward general-purpose instruction following across diverse and complex tasks, a key frontier is evaluating their crosslingual and multimodal capabilities over both short- and long-form inputs. However, existing benchmarks fall short in evaluating these dimensions jointly: they are often limited to English, mostly focus on a single modality at a time, rely on short-form inputs, or lack human annotations--hindering comprehensive assessment of model performance across languages, modalities, and task complexity. To address these gaps, we introduce MCIF (Multimodal Crosslingual Instruction Following), the first crosslingual human-annotated benchmark based on scientific talks on NLP and beyond. MCIF evaluates instruction following in crosslingual, multimodal settings over different input lengths and spans four macro-tasks: recognition, translation, question answering, and summarization. It covers three core modalities (speech, vision, and text) and four diverse languages (English, German, Italian, and Chinese), fully aligned across all dimensions. This parallel design enables a systematic evaluation of MLLMs' abilities to interpret instructions across languages and effectively integrate multimodal contextual information. Our benchmarking and analysis of 23 models highlight universal challenges across modalities and tasks, indicating substantial room for improvement in future MLLMs development. MCIF is released under CC-BY 4.0 license to promote open research.

Greedy or not, here I come: Language production under vocabulary constraints in humans and resource-rational models
Communicating using only a limited vocabulary is a common but challenging cognitive phenomenon, requiring an ideal communicator to plan carefully to optimize for intelligibility while circumventing a constrained lexicon. In this work, we investigate how humans respond to a broad array of questions under variable vocabulary limitations, consisting of only 250 highly frequent words at the most restrictive. We provide theoretically motivated comparisons to greedy and globally optimal sampling algorithms using Sequential Monte Carlo inference with large language models. Humans generally resemble greedy sampling more than globally optimal sampling, though more skilled humans are more likely to backtrack and revise -- a non-greedy behavior. An observed human pattern of leaning on semantically light words in high-constraint settings falls out of both greedy and globally optimal sampling. We discuss the results and their broader implications for resource-rational cognition, psycholinguistics, L2 communication, and language impairments.
Using spaced repetition systems to see through a piece of mathematics
By Michael Nielsen, January 2019
Improving Cross-Lingual Factual Recall via Consistency-Driven Reinforcement Learning
Large language models (LLMs) trained predominantly on English data encode substantial world knowledge, yet often fail to express it reliably in other languages, a phenomenon known as cross-lingual...
Methodologies for Improving the Quality of AI Tutoring in K-12 Education
Many AI tutors leverage large language models (LLMs) today. Given that LLMs are opaque black boxes, robust evaluation and live experimentation to measure the impact of every change are essential. We pioneered AI-powered tutoring for K-12 with the launch of Khanmigo (Khan Academy 2023). We describe the metrics we use to measure AI tutoring quality and student engagement as well as various experiments we have run. We highlight the changes that have moved our metrics, including models, prompting, personalization and agents.
Why Do Large Language Models (LLMs) Struggle to Count Letters?
Large Language Models (LLMs) have achieved unprecedented performance on many complex tasks, being able, for example, to answer questions on almost any topic. However, they struggle with other simple tasks, such as counting the occurrences of letters in a word, as illustrated by the inability of many LLMs to count the number of "r" letters in "strawberry". Several works have studied this problem and linked it to the tokenization used by LLMs, to the intrinsic limitations of the attention mechanism, or to the lack of character-level training data. In this paper, we conduct an experimental study to evaluate the relations between the LLM errors when counting letters with 1) the frequency of the word and its components in the training dataset and 2) the complexity of the counting operation. We present a comprehensive analysis of the errors of LLMs when counting letter occurrences by evaluating a representative group of models over a large number of words. The results show a number of consistent trends in the models evaluated: 1) models are capable of recognizing the letters but not counting them; 2) the frequency of the word and tokens in the word does not have a significant impact on the LLM errors; 3) there is a positive correlation of letter frequency with errors, more frequent letters tend to have more counting errors, 4) the errors show a strong correlation with the number of letters or tokens in a word and 5) the strongest correlation occurs with the number of letters with counts larger than one, with most models being unable to correctly count words in which letters appear more than twice.