

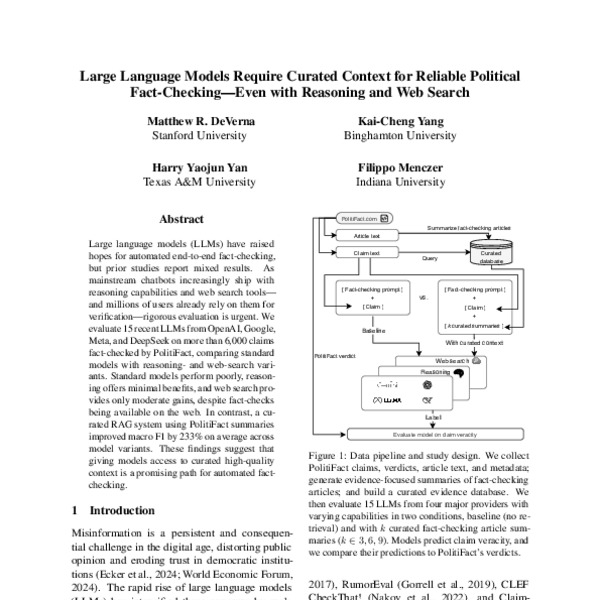
Large language models (LLMs) have raised hopes for automated end-to-end fact-checking, but prior studies report mixed results. As mainstream chatbots increasingly ship with reasoning capabilities and web search tools—and millions of users already rely on them for verification—rigorous evaluation is urgent. We evaluate 15 recent LLMs from OpenAI, Google, Meta, and DeepSeek on more than 6,000 claims fact-checked by PolitiFact, comparing standard models with reasoning- and web-search variants. Standard models perform poorly, reasoning offers minimal benefits, and web search provides only moderate gains, despite fact-checks being available on the web. In contrast, a curated RAG system using PolitiFact summaries improved macro F1 by 233% on average across model variants. These findings suggest that giving models access to curated high-quality context is a promising path for automated fact-checking.
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Large Language Models (LLMs) hold significant potential for advancing fact-checking by leveraging their capabilities in reasoning, evidence retrieval, and explanation generation. However, existing benchmarks fail to comprehensively evaluate LLMs and Multimodal Large Language Models (MLLMs) in realistic misinformation scenarios. To bridge this gap, we introduce RealFactBench, a comprehensive benchmark designed to assess the fact-checking capabilities of LLMs and MLLMs across diverse real-world tasks, including Knowledge Validation, Rumor Detection, and Event Verification. RealFactBench consists of 6K high-quality claims drawn from authoritative sources, encompassing multimodal content and diverse domains. Our evaluation framework further introduces the Unknown Rate (UnR) metric, enabling a more nuanced assessment of models' ability to handle uncertainty and balance between over-conservatism and over-confidence. Extensive experiments on 7 representative LLMs and 4 MLLMs reveal their limitations in real-world fact-checking and offer valuable insights for further research. RealFactBench is publicly available at https://github.com/kalendsyang/RealFactBench.git.

RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Large Language Models (LLMs) hold significant potential for advancing fact-checking by leveraging their capabilities in reasoning, evidence retrieval, and explanation generation. However, existing benchmarks fail to comprehensively evaluate LLMs and Multimodal Large Language Models (MLLMs) in realistic misinformation scenarios. To bridge this gap, we introduce RealFactBench, a comprehensive benchmark designed to assess the fact-checking capabilities of LLMs and MLLMs across diverse real-world tasks, including Knowledge Validation, Rumor Detection, and Event Verification. RealFactBench consists of 6K high-quality claims drawn from authoritative sources, encompassing multimodal content and diverse domains. Our evaluation framework further introduces the Unknown Rate (UnR) metric, enabling a more nuanced assessment of models' ability to handle uncertainty and balance between over-conservatism and over-confidence. Extensive experiments on 7 representative LLMs and 4 MLLMs reveal their limitations in real-world fact-checking and offer valuable insights for further research. RealFactBench is publicly available at https://github.com/kalendsyang/RealFactBench.git.
Language agents achieve superhuman synthesis of scientific knowledge
Language models are known to hallucinate incorrect information, and it is unclear if they are sufficiently accurate and reliable for use in scientific research. We developed a rigorous human-AI comparison methodology to evaluate language model agents on real-world literature search tasks covering information retrieval, summarization, and contradiction detection tasks. We show that PaperQA2, a frontier language model agent optimized for improved factuality, matches or exceeds subject matter expert performance on three realistic literature research tasks without any restrictions on humans (i.e., full access to internet, search tools, and time). PaperQA2 writes cited, Wikipedia-style summaries of scientific topics that are significantly more accurate than existing, human-written Wikipedia articles. We also introduce a hard benchmark for scientific literature research called LitQA2 that guided design of PaperQA2, leading to it exceeding human performance. Finally, we apply PaperQA2 to identify contradictions within the scientific literature, an important scientific task that is challenging for humans. PaperQA2 identifies 2.34 +/- 1.99 contradictions per paper in a random subset of biology papers, of which 70% are validated by human experts. These results demonstrate that language model agents are now capable of exceeding domain experts across meaningful tasks on scientific literature.
We tested how AI chatbots would handle foreign propaganda. They did surprisingly well
In a test, popular AI chatbots mostly debunked falsehoods spread by other countries and avoided uncritically spreading falsehoods better than search engines. AI summaries above search results fared worse.

People who frequently use ChatGPT for writing tasks are accurate and robust detectors of AI-generated text
In this paper, we study how well humans can detect text generated by commercial LLMs (GPT-4o, Claude, o1). We hire annotators to read 300 non-fiction English articles, label them as either human-written or AI-generated, and provide paragraph-length explanations for their decisions. Our experiments show that annotators who frequently use LLMs for writing tasks excel at detecting AI-generated text, even without any specialized training or feedback. In fact, the majority vote among five such “expert” annotators misclassifies only 1 of 300 articles, significantly outperforming most commercial and open-source detectors we evaluated even in the presence of evasion tactics like paraphrasing and humanization. Qualitative analysis of the experts' free-form explanations shows that while they rely heavily on specific lexical clues (`AI vocabulary'), they also pick up on more complex phenomena within the text (e.g., formality, originality, clarity) that are challenging to assess for automatic detectors. We release our annotated dataset and code to spur future research into both human and automated detection of AI-generated text.

People who frequently use ChatGPT for writing tasks are accurate and robust detectors of AI-generated text
In this paper, we study how well humans can detect text generated by commercial LLMs (GPT-4o, Claude, o1). We hire annotators to read 300 non-fiction English articles, label them as either human-written or AI-generated, and provide paragraph-length explanations for their decisions. Our experiments show that annotators who frequently use LLMs for writing tasks excel at detecting AI-generated text, even without any specialized training or feedback. In fact, the majority vote among five such “expert” annotators misclassifies only 1 of 300 articles, significantly outperforming most commercial and open-source detectors we evaluated even in the presence of evasion tactics like paraphrasing and humanization. Qualitative analysis of the experts' free-form explanations shows that while they rely heavily on specific lexical clues (`AI vocabulary'), they also pick up on more complex phenomena within the text (e.g., formality, originality, clarity) that are challenging to assess for automatic detectors. We release our annotated dataset and code to spur future research into both human and automated detection of AI-generated text.
GermanPartiesQA: Benchmarking Commercial Large Language Models and AI Companions for Political Alignment and Sycophancy
Large language models (LLMs) are increasingly shaping citizens’ information ecosystems. Products incorporating LLMs, such as chatbots and AI Companions, are now widely used for decision support and information retrieval, including in sensitive domains, raising concerns about hidden biases and growing potential to shape individual decisions and public opinion. This paper introduces GermanPartiesQA, a benchmark of 418 political statements from German Voting Advice Applications across 11 elections to evaluate six commercial LLMs. We evaluate their political alignment based on role-playing experiments with political personas. Our evaluation reveals three specific findings: (1) Factual limitations: LLMs show limited ability to accurately generate factual party positions, particularly for centrist parties. (2) Model-specific ideological alignment: We identify consistent alignment patterns and degree of political steerability for each model across temperature settings and experiments. (3) Claim of sycophancy: While models adjust to political personas during role-play, we find this reflects persona-based steerability rather than the increasingly popular, yet contested concept of sycophancy. Our study contributes to evaluating the political alignment of closed-source LLMs that are increasingly embedded in electoral decision support tools and AI Companion chatbots.
GermanPartiesQA: Benchmarking Commercial Large Language Models and AI Companions for Political Alignment and Sycophancy
Large language models (LLMs) are increasingly shaping citizens’ information ecosystems. Products incorporating LLMs, such as chatbots and AI Companions, are now widely used for decision support and information retrieval, including in sensitive domains, raising concerns about hidden biases and growing potential to shape individual decisions and public opinion. This paper introduces GermanPartiesQA, a benchmark of 418 political statements from German Voting Advice Applications across 11 elections to evaluate six commercial LLMs. We evaluate their political alignment based on role-playing experiments with political personas. Our evaluation reveals three specific findings: (1) Factual limitations: LLMs show limited ability to accurately generate factual party positions, particularly for centrist parties. (2) Model-specific ideological alignment: We identify consistent alignment patterns and degree of political steerability for each model across temperature settings and experiments. (3) Claim of sycophancy: While models adjust to political personas during role-play, we find this reflects persona-based steerability rather than the increasingly popular, yet contested concept of sycophancy. Our study contributes to evaluating the political alignment of closed-source LLMs that are increasingly embedded in electoral decision support tools and AI Companion chatbots.
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
As part of the Digital Library's transition to Open Access, new features for researchers are available in the Premium Edition. Click here to learn more.

RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
As part of the Digital Library's transition to Open Access, new features for researchers are available in the Premium Edition. Click here to learn more.
NewsBench: Expert-Grounded Evaluation of Epistemic Quality in AI News Reporting
As frontier AI systems increasingly serve as sources of political and current-events information, evaluating the epistemic quality of their responses is now especially consequential. Existing evaluations often focus narrowly on ideological alignment, rely on measures not validated for this setting, or depend on reference labels derived from public opinion or non-expert annotation, potentially producing misleading or miscalibrated results. To address these limitations, we introduce NewsBench, an expert-grounded benchmark that reframes evaluation around editorial standards developed by senior practitioners in journalism, policy, and intelligence analysis. NewsBench operationalizes quality across three dimensions, source quality, factuality, and neutrality, using a two-phase pipeline in which domain experts first define and calibrate evaluation guidelines, which are then transferred to automated AI judges validated against expert-adjudicated gold labels. The benchmark includes approximately $3,000$ evaluation prompts, with roughly $500$ refreshed monthly to capture emerging current events, roughly $2,500$ human expert-annotated items for calibration and validation, and a suite of AI judges designed to enable scalable evaluation. To validate our methodology, we report both inter-rater reliability among human experts and AI judge--human agreement across all three dimensions. Finally, we apply NewsBench to four frontier models, revealing distinct and non-overlapping failure profiles in sourcing, factuality, and neutrality.
NewsBench: Expert-Grounded Evaluation of Epistemic Quality in AI News Reporting
As frontier AI systems increasingly serve as sources of political and current-events information, evaluating the epistemic quality of their responses is now especially consequential. Existing evaluations often focus narrowly on ideological alignment, rely on measures not validated for this setting, or depend on reference labels derived from public opinion or non-expert annotation, potentially producing misleading or miscalibrated results. To address these limitations, we introduce NewsBench, an expert-grounded benchmark that reframes evaluation around editorial standards developed by senior practitioners in journalism, policy, and intelligence analysis. NewsBench operationalizes quality across three dimensions, source quality, factuality, and neutrality, using a two-phase pipeline in which domain experts first define and calibrate evaluation guidelines, which are then transferred to automated AI judges validated against expert-adjudicated gold labels. The benchmark includes approximately $3,000$ evaluation prompts, with roughly $500$ refreshed monthly to capture emerging current events, roughly $2,500$ human expert-annotated items for calibration and validation, and a suite of AI judges designed to enable scalable evaluation. To validate our methodology, we report both inter-rater reliability among human experts and AI judge--human agreement across all three dimensions. Finally, we apply NewsBench to four frontier models, revealing distinct and non-overlapping failure profiles in sourcing, factuality, and neutrality.
Relying on AI chatbots for historical facts can influence your political beliefs, new study shows
A recent study in PNAS Nexus suggests that reading history summaries generated by artificial intelligence can subtly shift your political opinions. Even when factually accurate, chatbots carry hidden biases that influence how people view the world.
AI Fact-Checking in the Wild: A Field Evaluation of LLM-Written Community Notes on X
Large language models (LLMs) show promising capabilities for fact-checking, yet prior work evaluates them only in controlled offline settings using benchmarks or crowdworker judgments. Success in real-world fact-checking depends also on how content is judged within a live platform environment. We present the first field evaluation of LLM fact-checking deployed on a live social media platform, testing performance directly through X Community Notes’ “AI writer” feature over a three-month period. Our LLM writer, a multi-step pipeline that handles multimodal content, conducts web and platform-native search, and writes contextual notes, was deployed to write 1,614 notes on 1,597 tweets and compared against 1,332 human-written notes on the same tweets using 108,169 ratings from 42,521 raters. Direct comparison of note-level platform outcomes is complicated by differences in submission timing and exposure between LLM and human notes; we therefore pursue two analysis strategies: a rating-level analysis modeling individual rater evaluations, and a note-level analysis that relies on common raters who rated all notes on the same post. Rating-level analysis shows that LLM notes receive more positive ratings than human notes across raters with different political viewpoints, and note-level analysis shows LLM notes achieve significantly higher helpfulness scores among common raters. Rater-provided tags suggest that people consider LLM notes to use more neutral language and cite better sources. These findings provide field evidence that LLMs can contribute broadly helpful fact-checking notes at scale, while showing that their evaluation is shaped by platform dynamics absent from controlled offline settings.
kalendsyang/RealFactBench
RealFactBench: A Benchmark for Evaluating Large Language Models in Real-World Fact-Checking
Can Language Models Play the Wikipedia Game?
Language models increasingly support or automate information retrieval from document collections too large to index. This task is difficult when it requires specialist linguistic or scientific knowledge. We used the Wikipedia Game to test language models on an analogous information retrieval task. In the game, players must reach a target article using only article links. We compared sentence embedding models and LLMs across five Wikipedia languages and five academic-literature datasets. We construct very large local graphs of Wikipedia pages and of paper citations using OpenAlex and provide code to build and navigate them. This allows the study of language models' navigation capabilities without relying on third-party APIs. We compared the models with human and TF-IDF benchmarks. The Wikipedia Game format enables robust comparisons across techniques, languages, and domains. No model significantly outperformed humans, although the best models (GPT-o3 mini, GPT-4o, QwQ:32B, and DeepSeek-R1:70B) achieved comparable success. Performance and rankings varied across languages and topics, with implications for practitioners utilising these techniques.