


With SAM Audio, you can use simple text prompts to accurately separate any sound from any audio or audio-visual source.
Our New SAM Audio Model Transforms Audio Editing
We're introducing SAM Audio, a state-of-the-art AI model that enables you to segment sound.
Online AI Vocal Remover & Stem Splitter | Gaudio Studio
Try it for free♬ The best AI-powered tool for making karaoke tracks, removing background music and more. Split your music into vocal and instrumental tracks.
Realtime and audio | OpenAI API
Learn which realtime and audio guide to use for each speech application.
WhisperSpeech/WhisperSpeech
An Open Source text-to-speech system built by inverting Whisper.
How to make your mic sound dogshit
Spatial programming without escape
turantekin/Parrot
Meeting recorder for your Mac with a live AI copilot. On-device transcription, answers from your own docs mid-call. Local-first and open source.
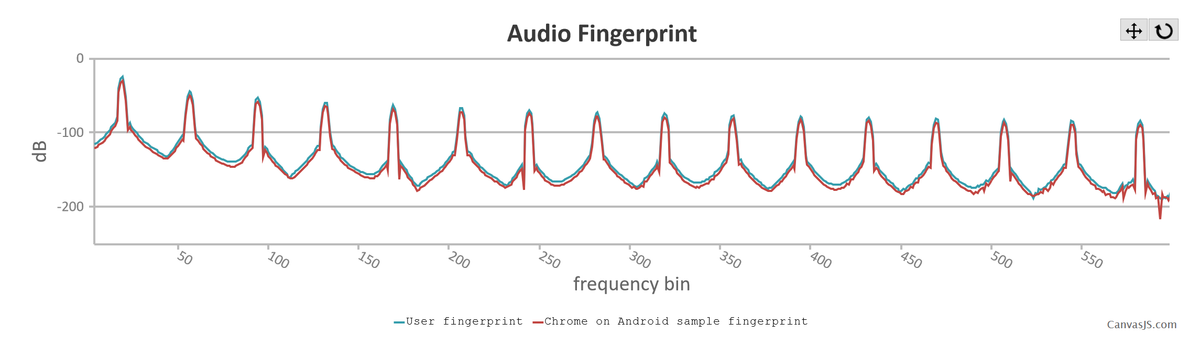
Audio Fingerprinting using the AudioContext API
Audio fingerprinting takes advantage of device performance specs to build up an identifying fingerprint of a user. It uses the AudioContext API for this
Audiobox: Meta's new foundation research model for audio generation | Hacker News
The more rational voices in my mind, though, become more and more afraid of a world where the only thing you can trust is people sitting right in front of you. That makes the world of information pretty small again.
Strobe Audio — Open Source Multiroom Music System
Play the same song in every room, listen to different things upstairs & downstairs or make every room different — either way Strobe will ensure that everything sounds perfect.
Soundify: Matching Sound Effects to Video
Soundify helps video editors add sound effects: it finds matching sounds, syncs them to the video, and adjusts panning and volume to create spatial audio.
innovatorved/whisper.api
This project provides an API with user level access support to transcribe speech to text using a finetuned and processed Whisper ASR model.