


Building a fully functional, code-editing agent in less than 400 lines.
New tools for building agents
Agents Done Right: A Framework Vision for 2026
Agents choke on context, loop on failures, and dump walls of code for review. It's time to rethink the architecture.
Designing agentic loops
Coding agents like Anthropic’s Claude Code and OpenAI’s Codex CLI represent a genuine step change in how useful LLMs can be for producing working code. These agents can now directly …
evalstate/fast-agent
Code, Build and Evaluate agents - excellent Model and Skills/MCP/ACP Support
Agent Skills
AI coding agents take the shortest path to done, which usually means skipping the specs, tests, and reviews that make software reliable at scale. Agent Skill...
Agentic Coding Things That Didn’t Work
Some of my attempts to make agents work better that just didn’t work.
OpenCode Zen | A curated set of reliable optimized models for coding agents
OpenCode - The open source coding agent.
My Agentic Coding Setup, July 2026
With the right tools, coding agents can run autonomously, in parallel, and be reachable from anywhere. Here's how I've stitched them together.
The End of Code Review: Coding Agents Supersede Human Inspection
Code review has been the primary quality gate in software development since Fagan formalised code inspection in 1976. For five decades, having a human examine and comment on a colleague's changes before merge has been a cornerstone practice at organisations of every size. Coding agents are large language model (LLM)-based autonomous systems capable of reading, writing, testing, and repairing software. We argue that coding agents have crossed a threshold of capability at which traditional human code review is no longer a necessary component of a software quality pipeline. Our argument rests on two claims: every stated goal of code review can be served by agents at lower cost and higher throughput; the naive integration in which agents write code and humans remain the mandatory reviewers is a dead end because it neither provides meaningful assurance nor scales with AI-assisted throughput.

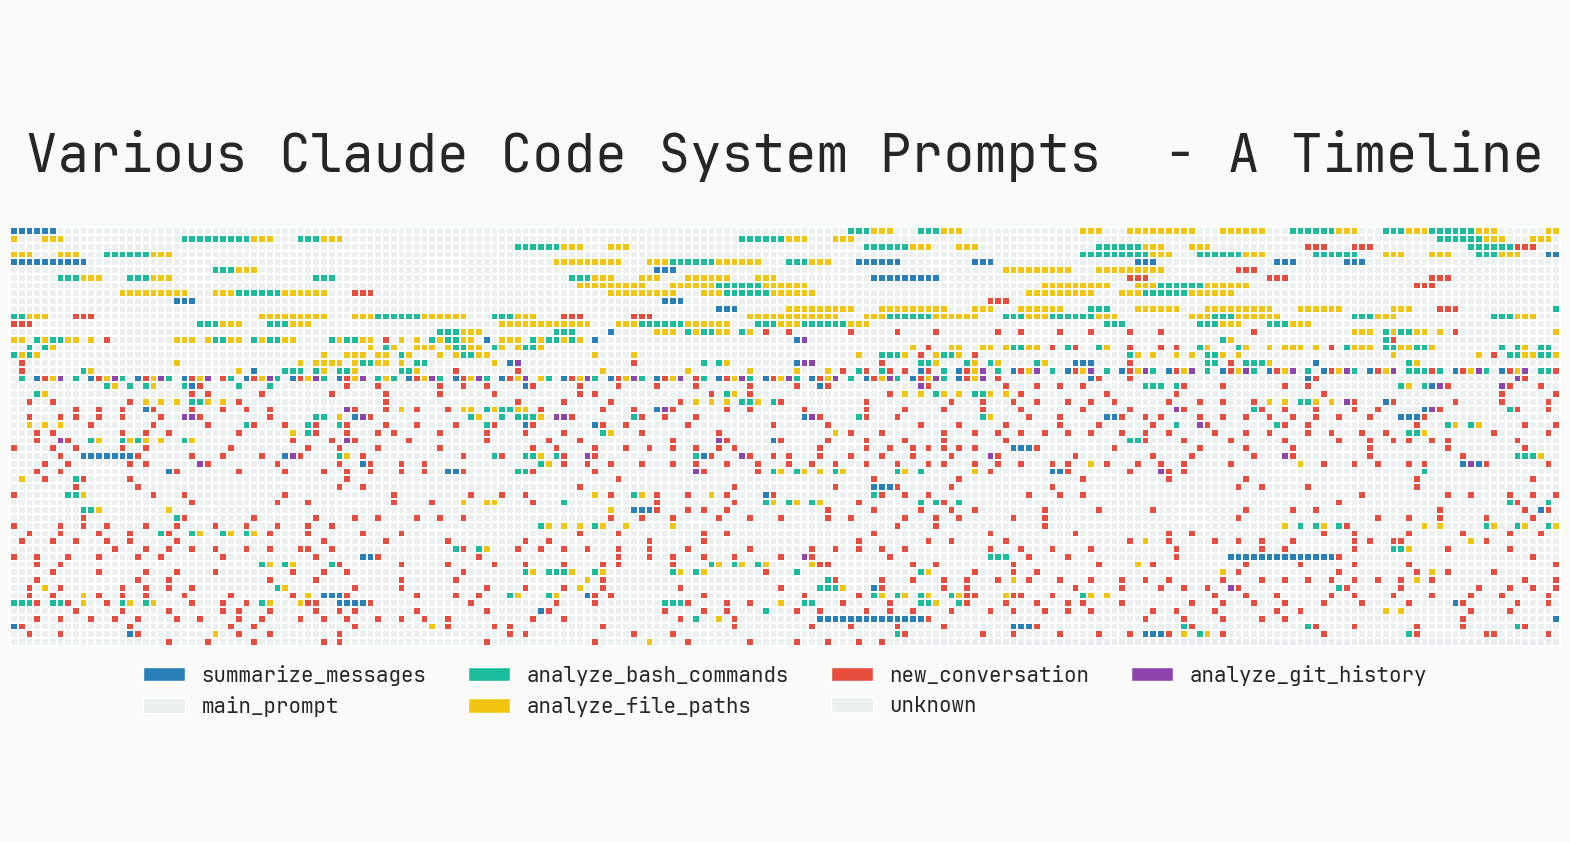
What makes Claude Code so damn good (and how to recreate that magic in your agent)!?
Claude Code is the most delightful AI agent/workflow I have used so far. Not only does it make targeted edits or vibe coding throwaway tools less annoying, ...
Agent READMEs: An Empirical Study of Context Files for Agentic Coding
Agentic coding tools receive goals written in natural language, break them down into specific tasks, and write or execute code with minimal human intervention. Central to this process are agent context files (e.g., AGENTS.md and CLAUDE.md) that provide persistent, project-level instructions. In this paper, we conduct the first large-scale empirical study of 2,303 agent context files from 1,925 repositories to characterize their structure, maintenance, and content. We find that these files are not static documentation but complex, difficultto-read artifacts that evolve like configuration code through frequent, small additions. Our content analysis of 16 instruction types shows that developers prioritize functional context, such as test procedures (75.9%), implementation details (70.8%), and architecture (68.1%). We also identify a significant gap: non-functional requirements such as security (14.8%) and performance (14.5%) are rarely specified. These findings indicate that while developers use context files to make agents functional, they provide few guardrails to ensure that agent-written code is secure or performant, highlighting the need for improved tools and practices.
Introducing Agentic Editing in Zed
Claude Code, Codex and Agentic Coding #8
When I started this series, everyone was going crazy for coding agents.
Humans are Missing from AI Coding Agent Research
Recent progress in AI coding agent research has led to rapid improvements in agents' ability to autonomously perform complex software engineering tasks, from editing large codebases to executing long-horizon development workflows. As these systems make strides, however, the primary bottleneck to practical usefulness increasingly shifts away from pure task-solving capability, and toward challenges in how users communicate with, supervise, and trust agents. In this position paper, we argue for a reorientation from autonomous to human-centered coding agents: systems designed not only to complete tasks, but to collaborate effectively with people. We identify four core interaction-level dimensions that characterize the human-agent task-solving loop: task alignment, verifiability, steerability, and adaptability. Finally, we outline concrete research directions to advance these dimensions, including user-involved coding environments, comprehensive verification mechanisms, and principled measures of human-agent interaction quality.