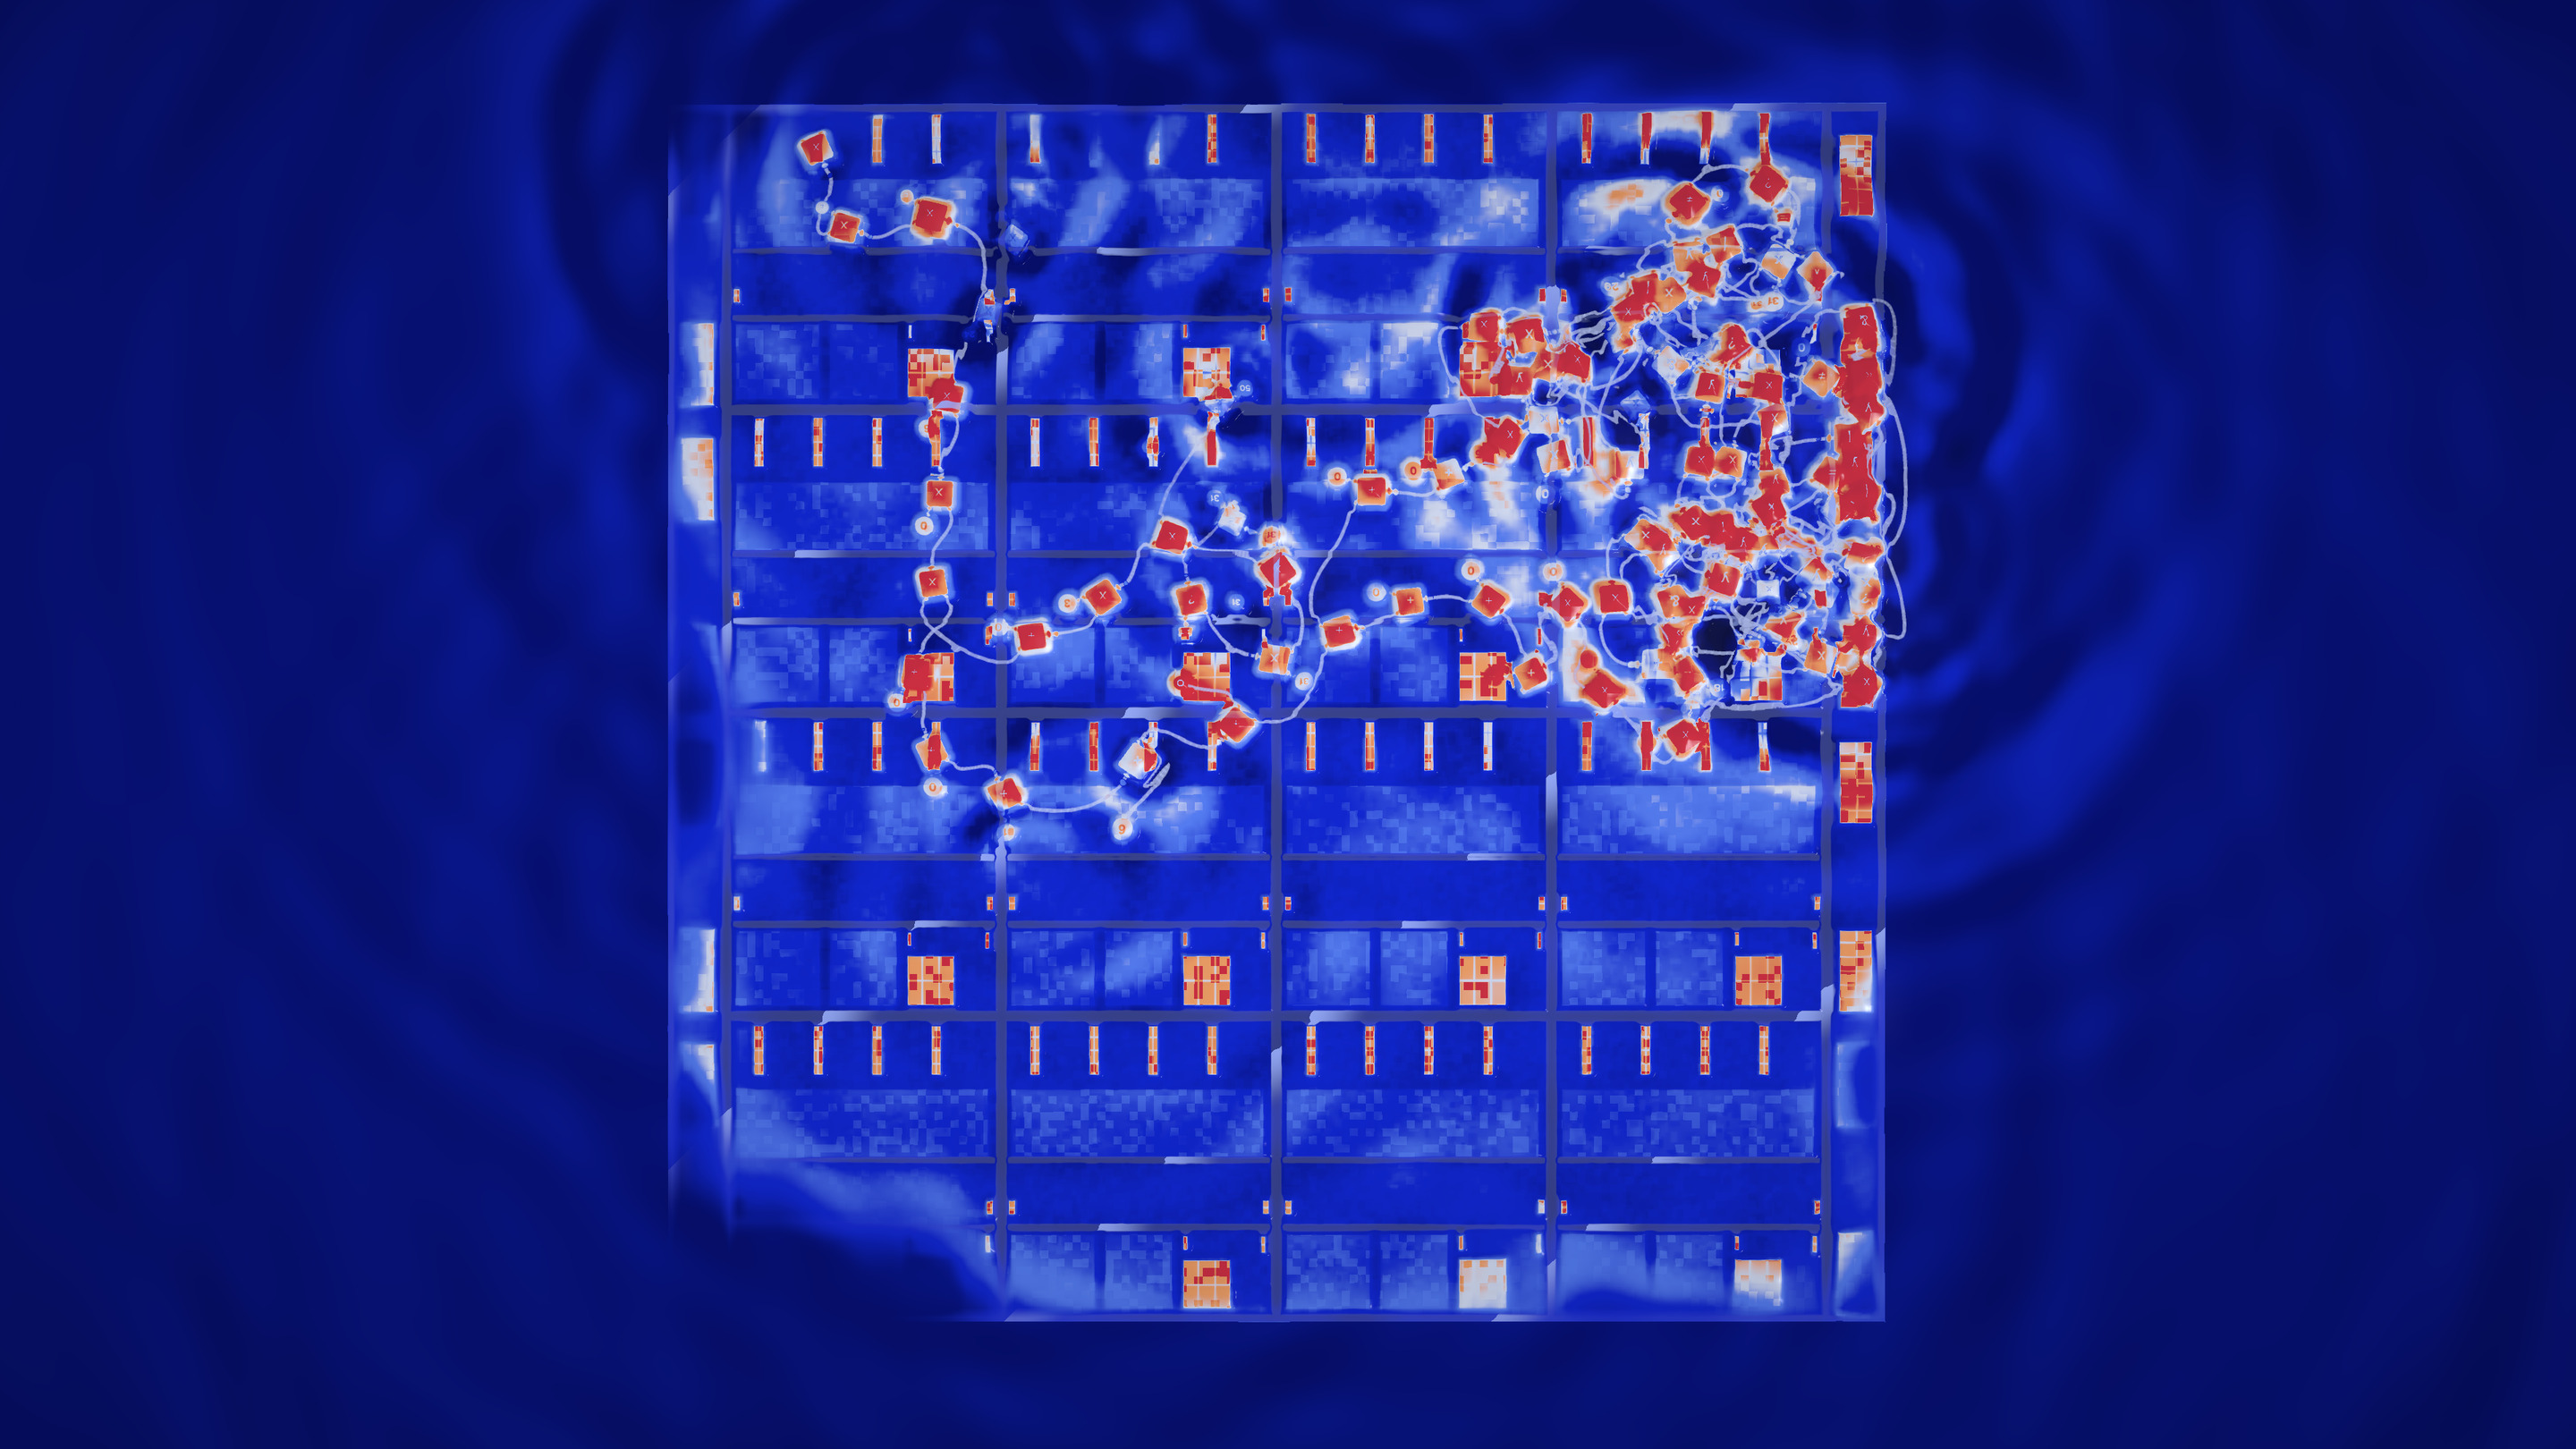
Frostbite is a general-purpose CPU built around interaction nets, discovered, designed, and verified end-to-end by our AI systems, reaching 4.59x the performance-per-watt of a modern superscalar (dual-issue, in-order) CPU core.
Together AI | The AI Native Cloud
Build what's next on the AI Native Cloud. Full-stack AI platform for inference, fine-tuning, and GPU clusters — powered by cutting-edge research.
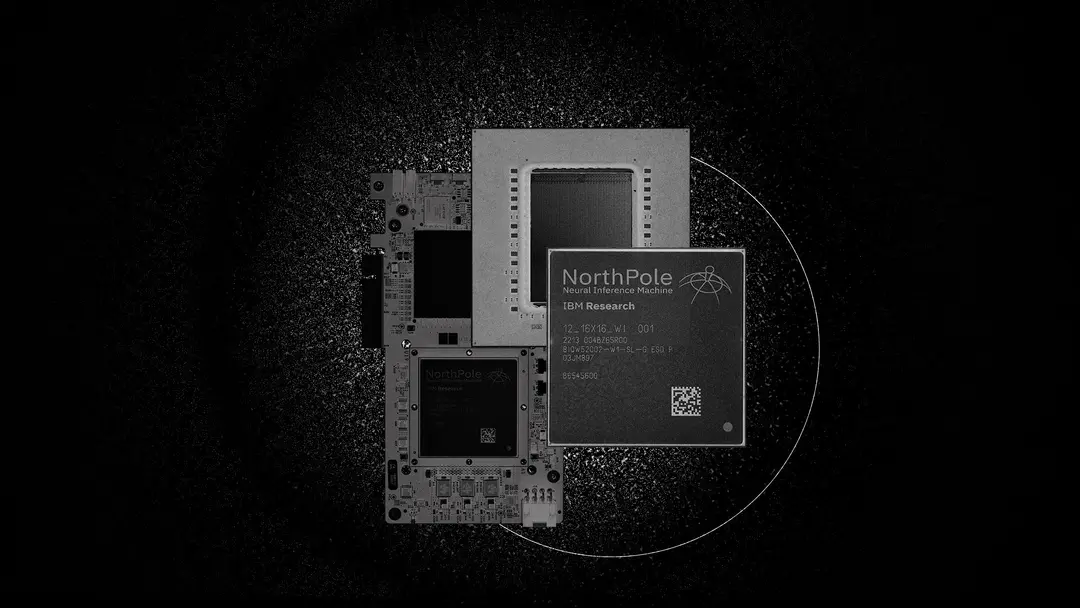
IBM has made a new, highly efficient AI processor
A very unusual chip design provides a distinct approach to cutting AI's energy cost.
The Universal Execution Layer for AI
Optimize any AI model on any engine, across all hardware. Dria’s topology-aware compiler and peer-to-peer runtime merge CPUs, GPUs, NPUs & chiplets into one fabric—maximising utilisation, cutting inference cost and ending vendor lock-in.

BISCUT | AI Chips for Edge
The BISCUT Coldfoot microchip brings AI to the ultra-low-power edge with biological efficiency.

The Ma of a New Machine – Scott Jenson
The current Silicon Valley flex is trading notes on your favorite new AI tools over lunch. Each week brings another one to explore. Some of these tools are very impressive; I’ve been able to reply to someone with an alternative UI design in less than a minute, and they were dumbfounded: “How did you do that so fast?”

Alex Cheema on Twitter / X
This is why we need open benchmarks for local AI.Otherwise it turns into tribalism and name calling.We will be publishing the largest database of open benchmarks for local AI, tested on 1,000+ real hardware setups. Every device, every interconnect, different… https://t.co/ZsU3PCdSsZ— Alex Cheema (@alexocheema) March 9, 2026
AI Promised Less Work. I Have Never Worked More. - Orestis Ioannou
Agents made implementation cheap, so I started doing far more of it in parallel. My GitHub history since 2019 shows what that did: as VP of Technology I am back at my full-stack engineer pace, with bursts, burnout and a low season that is no longer low.
Lilypad-Tech/lilypad
Run AI workloads easily in a decentralized GPU network. https://www.youtube.com/watch?v=yQnB2Yxia4Y
Teaching AI to Optimize AI Models for Edge Deployment
How our agent, Möbius automated a Core ML port in ~12 h (vs. 2 weeks), hit 0.99998 parity, and made it 3.5× faster, while staying on the CPU.
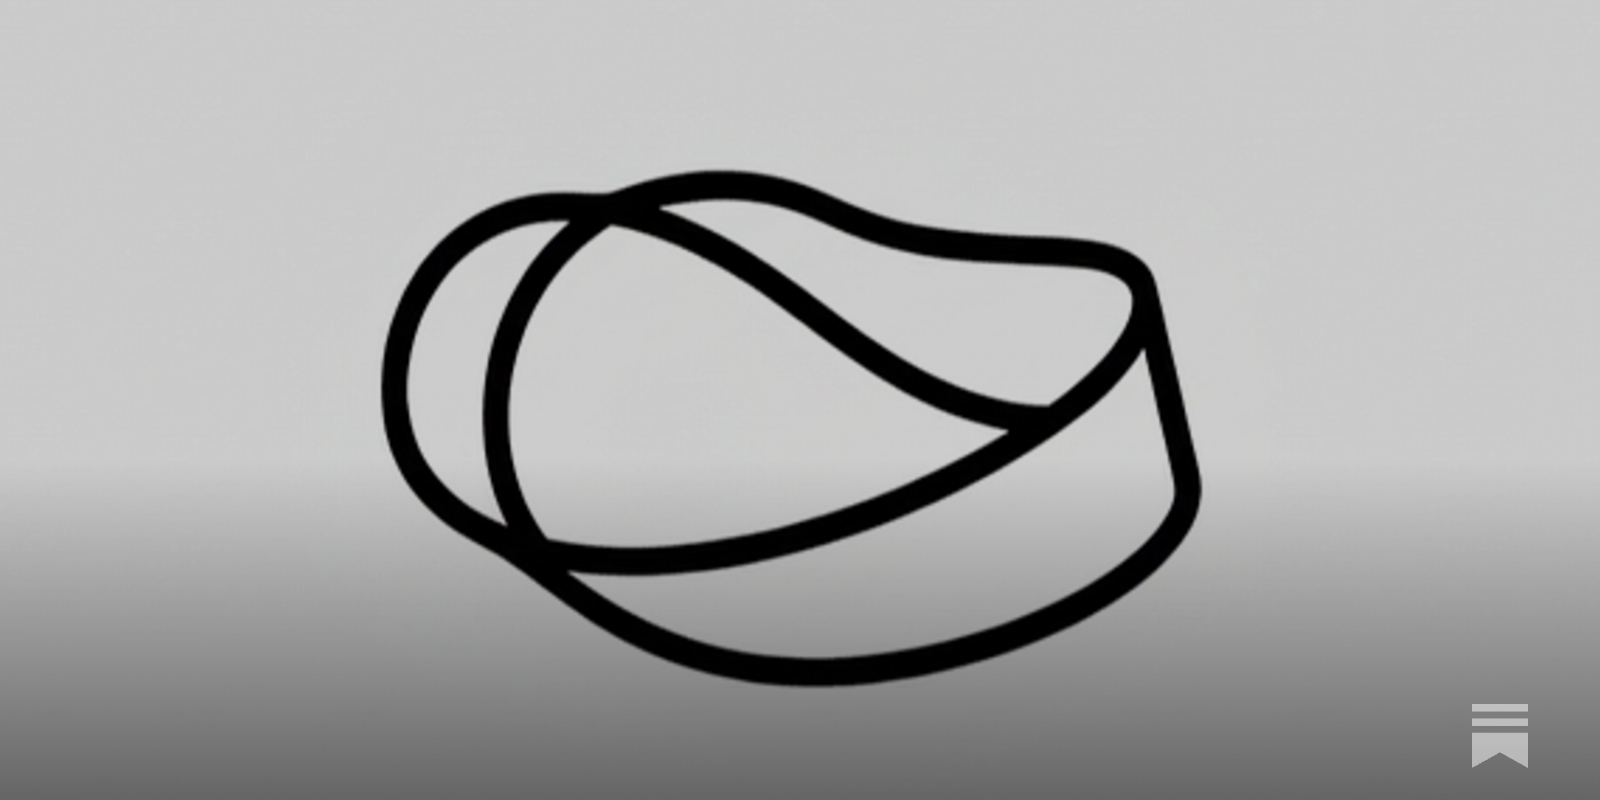
AI Chip Architectures
A look at AI Chip Architectures. NVIDIA, AMD, TPUs, Trainium, Groq, Cerebras.
Computational Power and AI - AI Now Institute
By Jai Vipra & Sarah Myers WestSeptember 27, 2023 In this article What is compute and why does it matter? How is the demand for compute shaping AI development? What kind of hardware is involved? What are the components of compute hardware? What does the supply chain for AI hardware look like? What does the […]
Desktop, Touch, Browser, Now AI? The Next OS in Computing
Explore how AI is reshaping human-computer interaction, from command lines to modern SaaS. Key insights on the next computing paradigm for startups and tech leaders.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
Import AI 470: No rights for machines; automating environment generation with SPADE; and building better GPU kernels with Hawkeye
Differential acceleration of cyber, math, and AI
Introducing Pipette: A benchmarking suite for on-device intelligence — Blog
Meet Pipette, an open-source platform for reproducible on-device AI benchmarks across models, quantization, runtimes and hardware.