

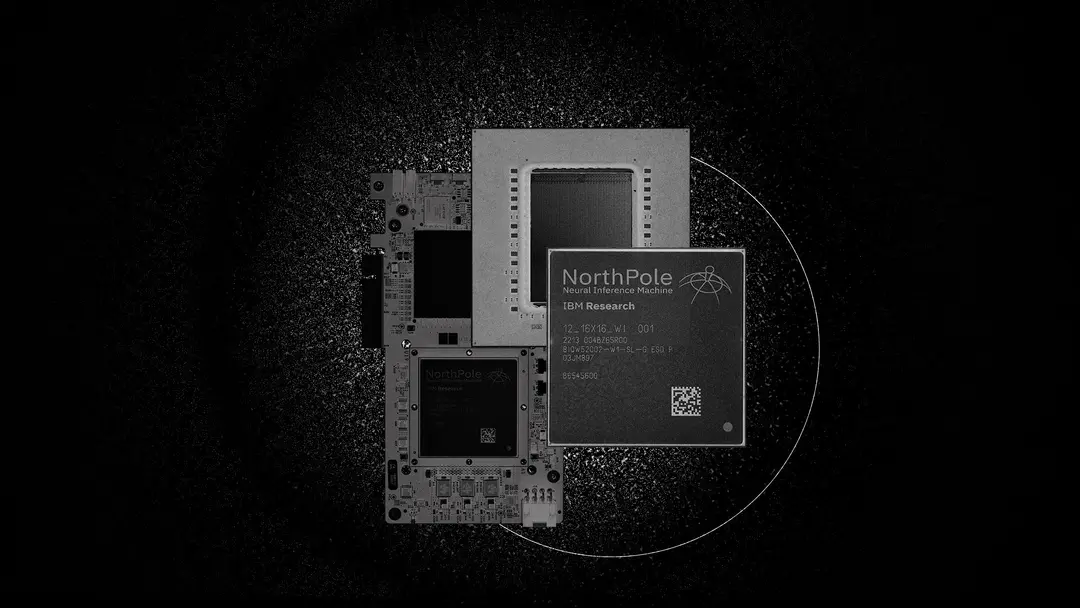
A very unusual chip design provides a distinct approach to cutting AI's energy cost.
Introducing Frostbite: A new CPU architecture discovered, designed, and verified end-to-end by AI
Frostbite is a general-purpose CPU built around interaction nets, discovered, designed, and verified end-to-end by our AI systems, reaching 4.59x the performance-per-watt of a modern superscalar (dual-issue, in-order) CPU core.
Dean W. Ball on Twitter / X
Ok two more:1. AI will enable the design of custom enzymes that can catalyze industrial processes and chemical manufacturing faster than existing methods. In some cases this will make existing chemicals cheap enough that it becomes possible to use them for totally new use… https://t.co/jL3bNm0s9w— Dean W. Ball (@deanwball) October 9, 2026
AI Promised Less Work. I Have Never Worked More. - Orestis Ioannou
Agents made implementation cheap, so I started doing far more of it in parallel. My GitHub history since 2019 shows what that did: as VP of Technology I am back at my full-stack engineer pace, with bursts, burnout and a low season that is no longer low.
Computational Power and AI - AI Now Institute
By Jai Vipra & Sarah Myers WestSeptember 27, 2023 In this article What is compute and why does it matter? How is the demand for compute shaping AI development? What kind of hardware is involved? What are the components of compute hardware? What does the supply chain for AI hardware look like? What does the […]
The Ma of a New Machine – Scott Jenson
The current Silicon Valley flex is trading notes on your favorite new AI tools over lunch. Each week brings another one to explore. Some of these tools are very impressive; I’ve been able to reply to someone with an alternative UI design in less than a minute, and they were dumbfounded: “How did you do that so fast?”

Intel launches its next-generation neuromorphic processor—so, what’s that again?
Intel's Loihi processors have electronics that behave a lot like neurons.

The Universal Execution Layer for AI
Optimize any AI model on any engine, across all hardware. Dria’s topology-aware compiler and peer-to-peer runtime merge CPUs, GPUs, NPUs & chiplets into one fabric—maximising utilisation, cutting inference cost and ending vendor lock-in.

Recursive Self-Improvement via AI for Chip Design & Chip Design for AI - Ricursive Intelligence
We develop frontier AI methods to reinvent chip development, collapsing traditional design timelines, closing the loop between AI and the hardware that fuels it, and enabling a Cambrian explosion of custom silicon.

AI’s energy usage is less than previously thought | Waterloo News
Contrary to popular belief, new research finds that the use of artificial intelligence has a minimal effect on global greenhouse gas emissions and may actually benefit the environment and the
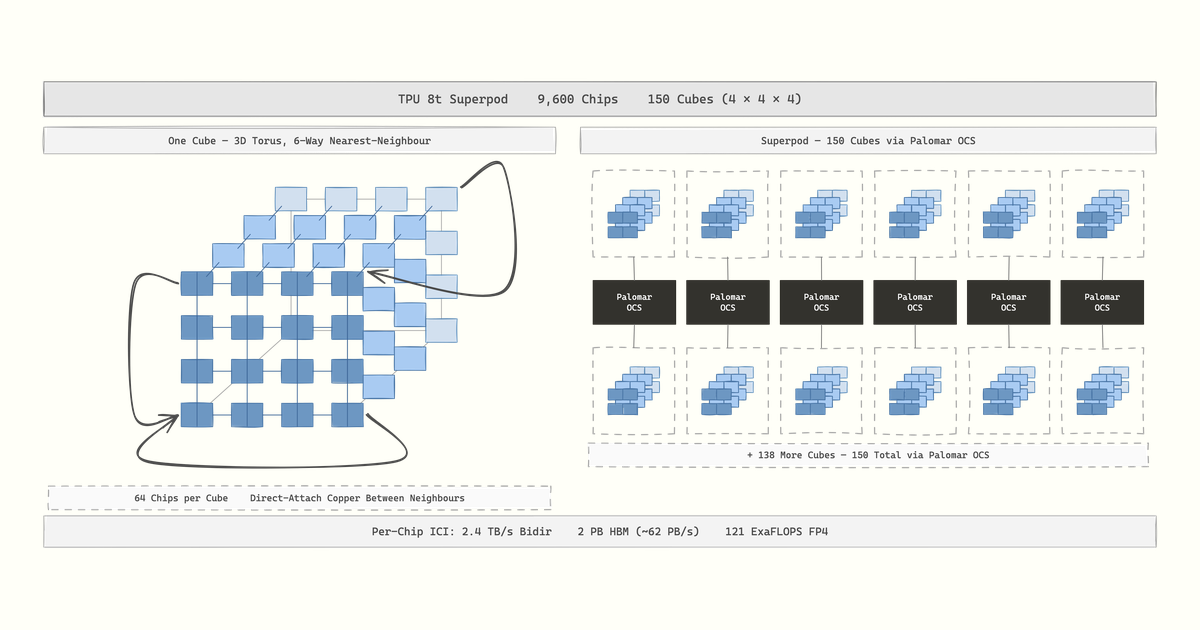
AI Chip Architectures
A look at AI Chip Architectures. NVIDIA, AMD, TPUs, Trainium, Groq, Cerebras.
Teaching AI to Optimize AI Models for Edge Deployment
How our agent, Möbius automated a Core ML port in ~12 h (vs. 2 weeks), hit 0.99998 parity, and made it 3.5× faster, while staying on the CPU.
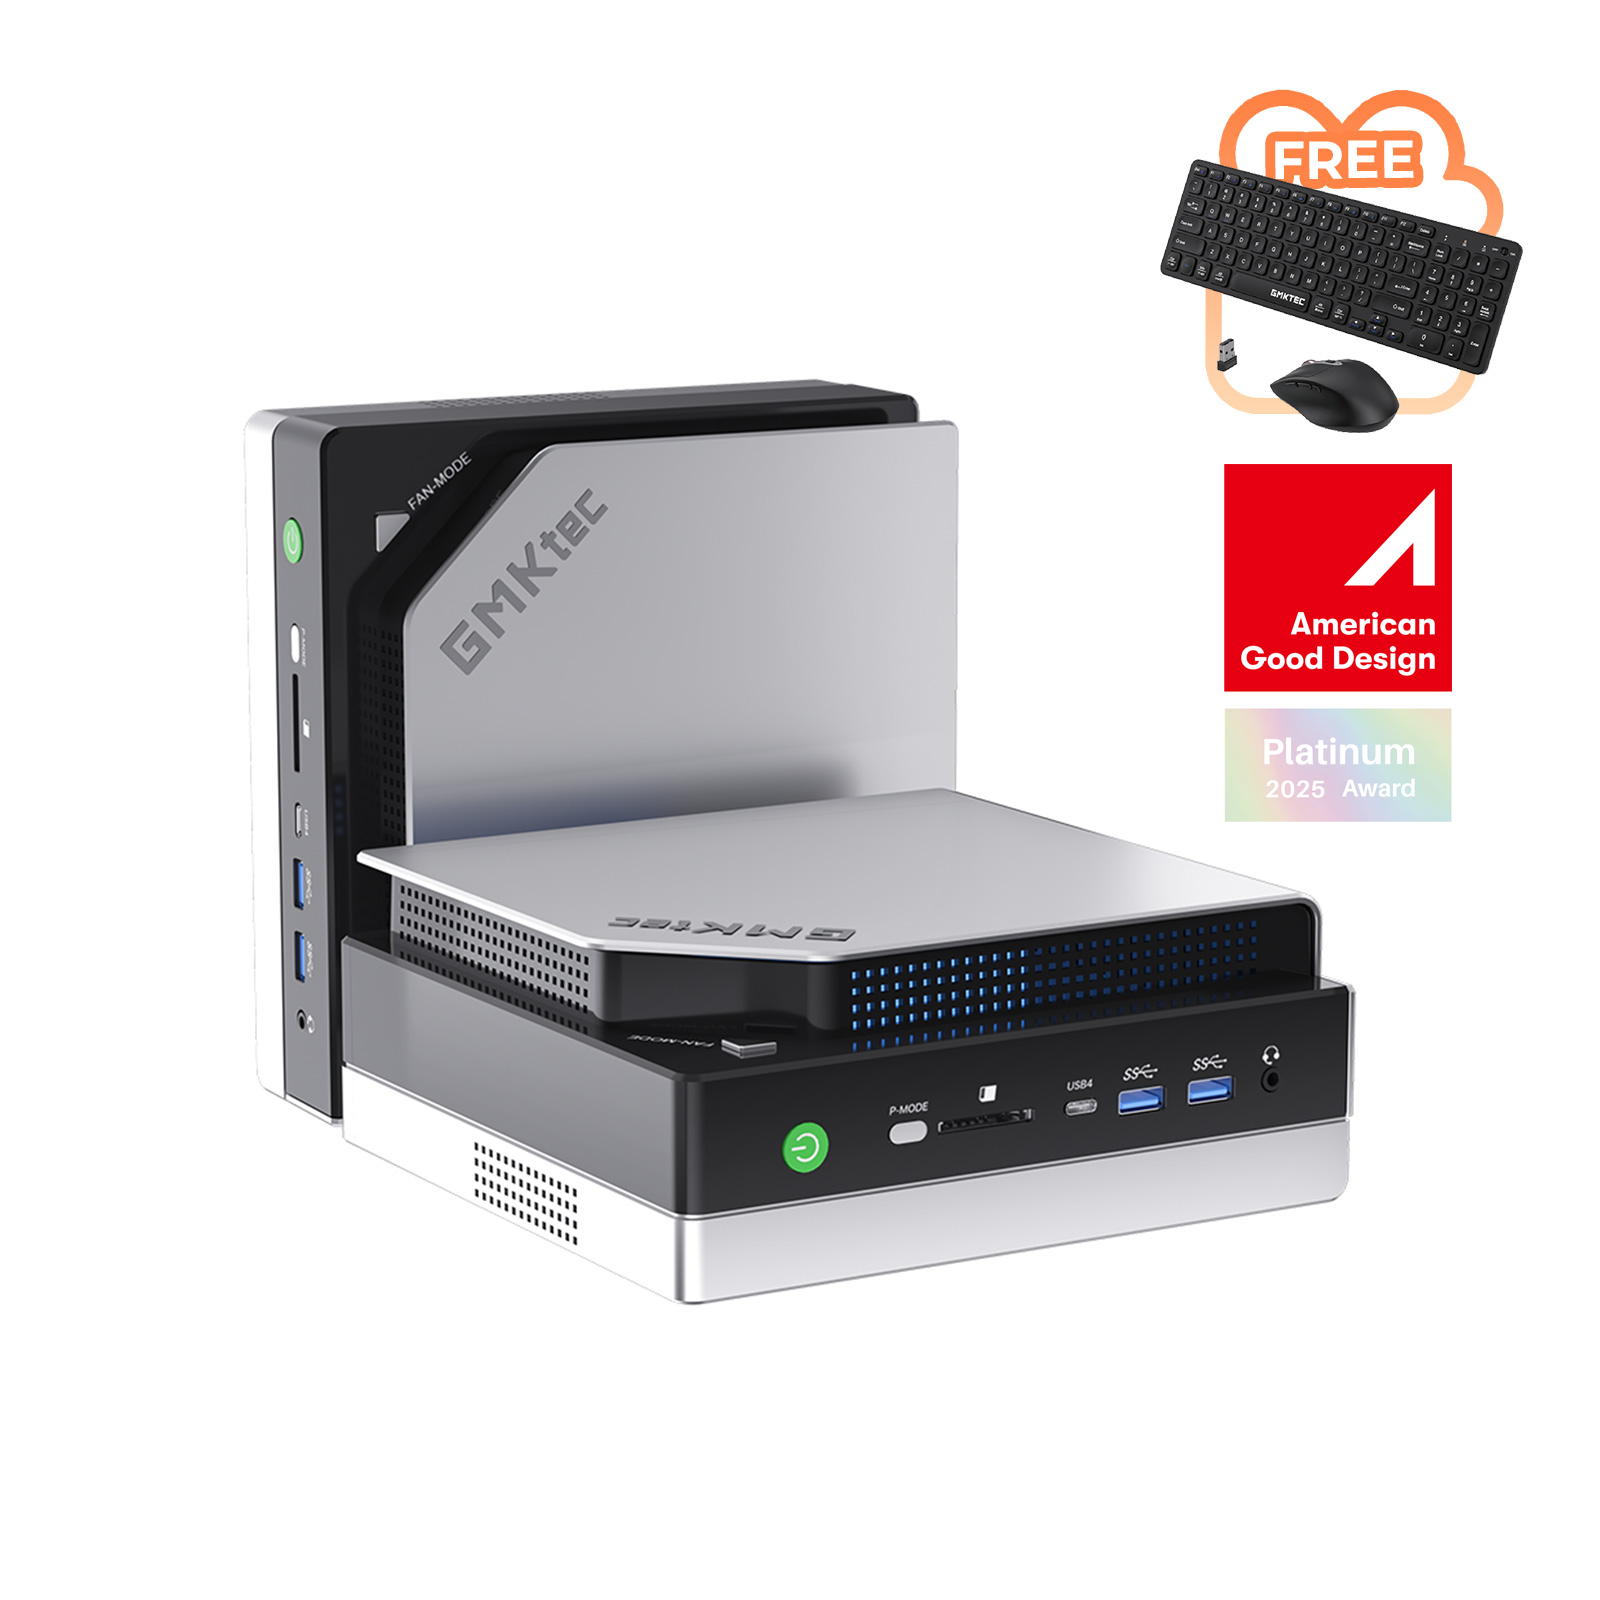
GMKtec EVO-X2 AI Mini PC AMD Ryzen™ AI Max+ 395
EVO-X2 AMD Ryzen™ Al Max+ 395 Mini PC, the World’s First Windows 11 AI+ PC APU Supporting 70B LLM, Experience relentless power with the AMD Ryzen™ AI Max+ 395. With 16 cores and 32 threads built on the groundbreaking Zen 5 architecture, it clocks up to 5.1GHz. Crafted using TSMC’s advanced 4nm FinFET process and armed with a massive 16MB L2 and 64MB L3 cache, it delivers seamless multitasking and unrivaled parallel processing.
Feeding the machine
The fastest growing companies in the world aren’t AI companies, but the startups that supply them with warm bodies.

raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
The energy and carbon costs of deploying AI models have largely been unknown.. until now! 🌏🚀 With @strubell and @YJernite, We tested 88 models on 30 datasets from 10 different tasks from different modalities and found some pretty cool stuff! A thread 🧵:
The energy and carbon costs of deploying AI models have largely been unknown.. until now! 🌏🚀With @strubell and @YJernite, We tested 88 models on 30 datasets from 10 different tasks from different modalities and found some pretty cool stuff! A thread 🧵: pic.twitter.com/0Ac7OsIcPg— Sasha Luccioni, PhD 🦋🌎✨🤗 (@SashaMTL) December 1, 2023
