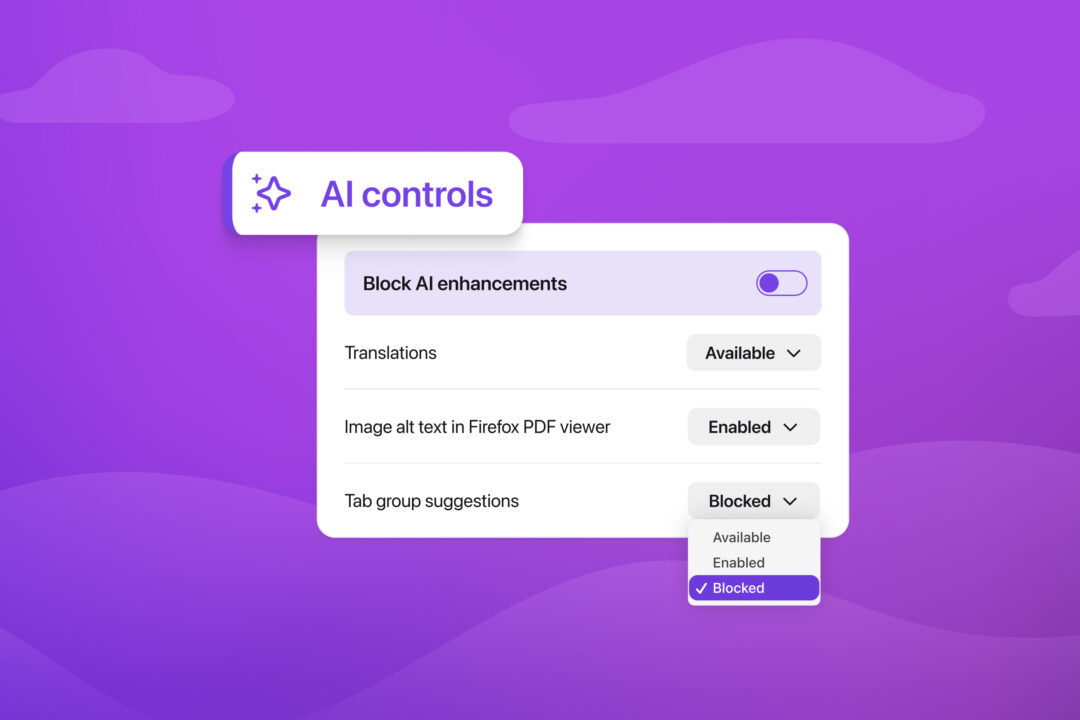
Cloudflare is giving site owners a way to stay discoverable while disallowing AI training. New controls and an Accountable designation establish a shared model with Apple, Google, and Microsoft.
Control content use for AI training with Cloudflare’s managed robots.txt and blocking for monetized content
Cloudflare is making it easier for publishers and content creators of all sizes to prevent their content from being scraped for AI training by managing robots.txt on their behalf, and allowing targeted blocking of AI crawling on sites that serve ads.
Cloudflare、検索を許可しながらAI学習を拒否する「Disallow AI Training」を発表 | gihyo.jp
Cloudflareは2026年9月15日、Webサイトの検索インデックスへの登録を維持しながら、コンテンツのAI学習への利用を拒否する設定「Disallow AI Training」を発表した。

Content Independence Day: no AI crawl without compensation!
It’s Content Independence Day: Cloudflare, along with a majority of the world's leading publishers and AI companies, is changing the default to block AI crawlers unless they pay creators for content.
healsdata/ai-training-opt-out
Known tags and settings suggested to opt out of having your content used for AI training.
Cloudflare gives AI agents an identity and a wallet | Cloudflare
New tools mean businesses will be able to see who's behind an AI agent, and those agents will be able to pay for things safely on their owner's behalf.

Trapping misbehaving bots in an AI Labyrinth
How Cloudflare uses generative AI to slow down, confuse, and waste the resources of AI Crawlers and other bots that don’t respect “no crawl” directives.

Firms like Meta and A16z admit having to pay billions for training data would ruin their generative-AI plans as they fight new copyright rules
Meta, Google, Microsoft, and Andreessen Horowitz are trying to keep AI developers from having to pay for copyrighted material used in AI training.
There’s a 100% Chance AI Agents Are Already Ruining the Internet
“AI agents” now have enough power and permission to be extremely annoying online.
Cloudflare Workers AI | Open-source AI inference
Workers AI facilitates the scalable development & deployment of AI applications at the edge.

How to disable or avoid intrusive AI – librarian.net
One of the biggest questions I get at Drop-In Time at the library (besides “what is taking up all my cloud storage?”) is how to disable or avoid intrusive AI that shows up where people don’t want it. I’m going to make a handout that explains how to do some of the basic AI-removal or AI-avoidance things. This is a guide for people who would like less intrusive AI in their tech environment. Maybe you like AI and find it useful? That’s fine, this document is probably not for you. Additions/edits welcome. Leave a comment or drop me an email.
Project Think: building the next generation of AI agents on Cloudflare
Announcing a preview of the next edition of the Agents SDK — from lightweight primitives to a batteries-included platform for AI agents that think, act, and persist.

Twitch is Mining Peoples' Streams to Train Amazon's AI
Here's how to opt out of Twitch's new generative AI training setting.
A Strategy for Protecting Content from AI
Because that’s the world we live in these days.
Introducing Kitesurf: The agent-first browser that runs in V8 isolates on Cloudflare Workers
We should be giving all agents tools that excel at what’s important for an AI model. Kitesurf is Cloudflare’s new stateless, highly scalable, and cost-effective web browser that runs entirely on top of Workers and was designed specifically for the Agentic Cloud.

AI is eating website traffic, websites are blocking AI – and reliable information is getting harder to find
AI has broken the economic bargain behind the web, and everybody is losing.
AI controls are coming to Firefox | The Mozilla Blog
AI is changing the web, and people want very different things from it. We’ve heard from many who want nothing to do with AI. We’ve also heard from