

Over the last few years, I have spent a lot of time thinking, speaking, and discussing about the reproducibility crisis in scientific research. An obvious but hard to answer question is: Why has reproducibility become such a major problem, in so many disciplines? And why now? In this post, I will make an attempt at formulating an hypothesis: the underlying cause for the reproducibility crisis is the ongoing industrialization of scientific research.
Konrad Hinsen's blog
Thirty years after my first contact with computational (ir)reproducibility, I am happy to note that many things have improved. Reproducibility, computational and otherwise, is increasingly recognized as an important aspect of scientific quality control, and mostly considered worth striving for. However, I also note that more and more people, including reproducibility activists, have lost contact with the day-to-day reality in which reproducibility matters. Reproducibility is becoming an item on a checklist, and its precise incarnation the subject of political bickering aimed at making it easy to check off that item. So let's take a look at why computational reproducibility matters for researchers.
Science has been in a “replication crisis” for a decade. Have we learned anything?
Bad papers are still published. But some other things might be getting better.

Reproducibility in Machine Learning-based Research: Overview, Barriers and Drivers
The concept of reproducibility can have different interpretations across various research fields and even within the same field [39]. To avoid confusion, we first specify our terms, broadly defining reproducibility and then further categorizing it into various types and degrees. The first distinction comes from Goodman et al. [42], who specify a fundamental division between whether we (i) mean reproducible in principle (termed “methods” reproducibility) due to sufficient description/sharing of methodologies, materials, etc., or (ii) whether results/conclusions actually prove to be reproducible when experiments or analyses are re-done. In the second category, they distinguish “results” and “inferential” reproducibility, depending on whether the analyses or inferences to broader conclusions are reproduced.
The Engine of Scientific Discovery: How New Methods and Tools Spark Major Breakthroughs
Abstract. How do we spark new scientific discoveries? Why do some breakthroughs seem even accidental? And most importantly, how can we accelerate them and
The Discovery Engine: A Framework for AI-Driven Synthesis and Navigation of Scientific Knowledge Landscapes
Scientific progress relies on the effective accumulation, synthesis, and critical evaluation of knowledge. Traditionally, the well-documented, peer reviewed publication served as the primary standard for filtering and disseminating credible findings within the scientific community. Recently, however, we are witnessing an unprecedented acceleration in research output, a veritable explosion of scientific publications across all disciplines [1]. Yet, this very abundance creates a paradox: the sheer volume threatens to overwhelm the mechanisms designed for its assimilation and synthesis. Researchers, even within highly specialized subfields, face an almost insurmountable challenge in keeping abreast of relevant developments, integrating disparate findings, and identifying the truly novel signals amidst the noise [2]. This information overload contributes to disciplinary fragmentation, hindering the cross-pollination of ideas essential for disruptive innovation [3]. Furthermore, persistent concerns regarding "reproducibility crisis" [2], predatory journals, inflation of research areas[4], growing retractions and the potential influences of bibliometrics on research direction [5] highlight systemic challenges in validating and prioritizing scientific contributions to fundamental knowledge.
The Bazaar of Scientific Knowledge | shishyko!
Is the current form of the scientific paper still optimal in 2025? How do we preserve, and efficiently leverage, the uncut gems of the scientific process?
Science Must Decentralize
Knowledge production doesn’t happen in a vacuum. Every great scientific breakthrough is built on prior work, and an ongoing exchange with peers in the field. That’s why we need to address the threat
ReScience organization
Reproducible Science is good. Replicated Science is better. - ReScience organization

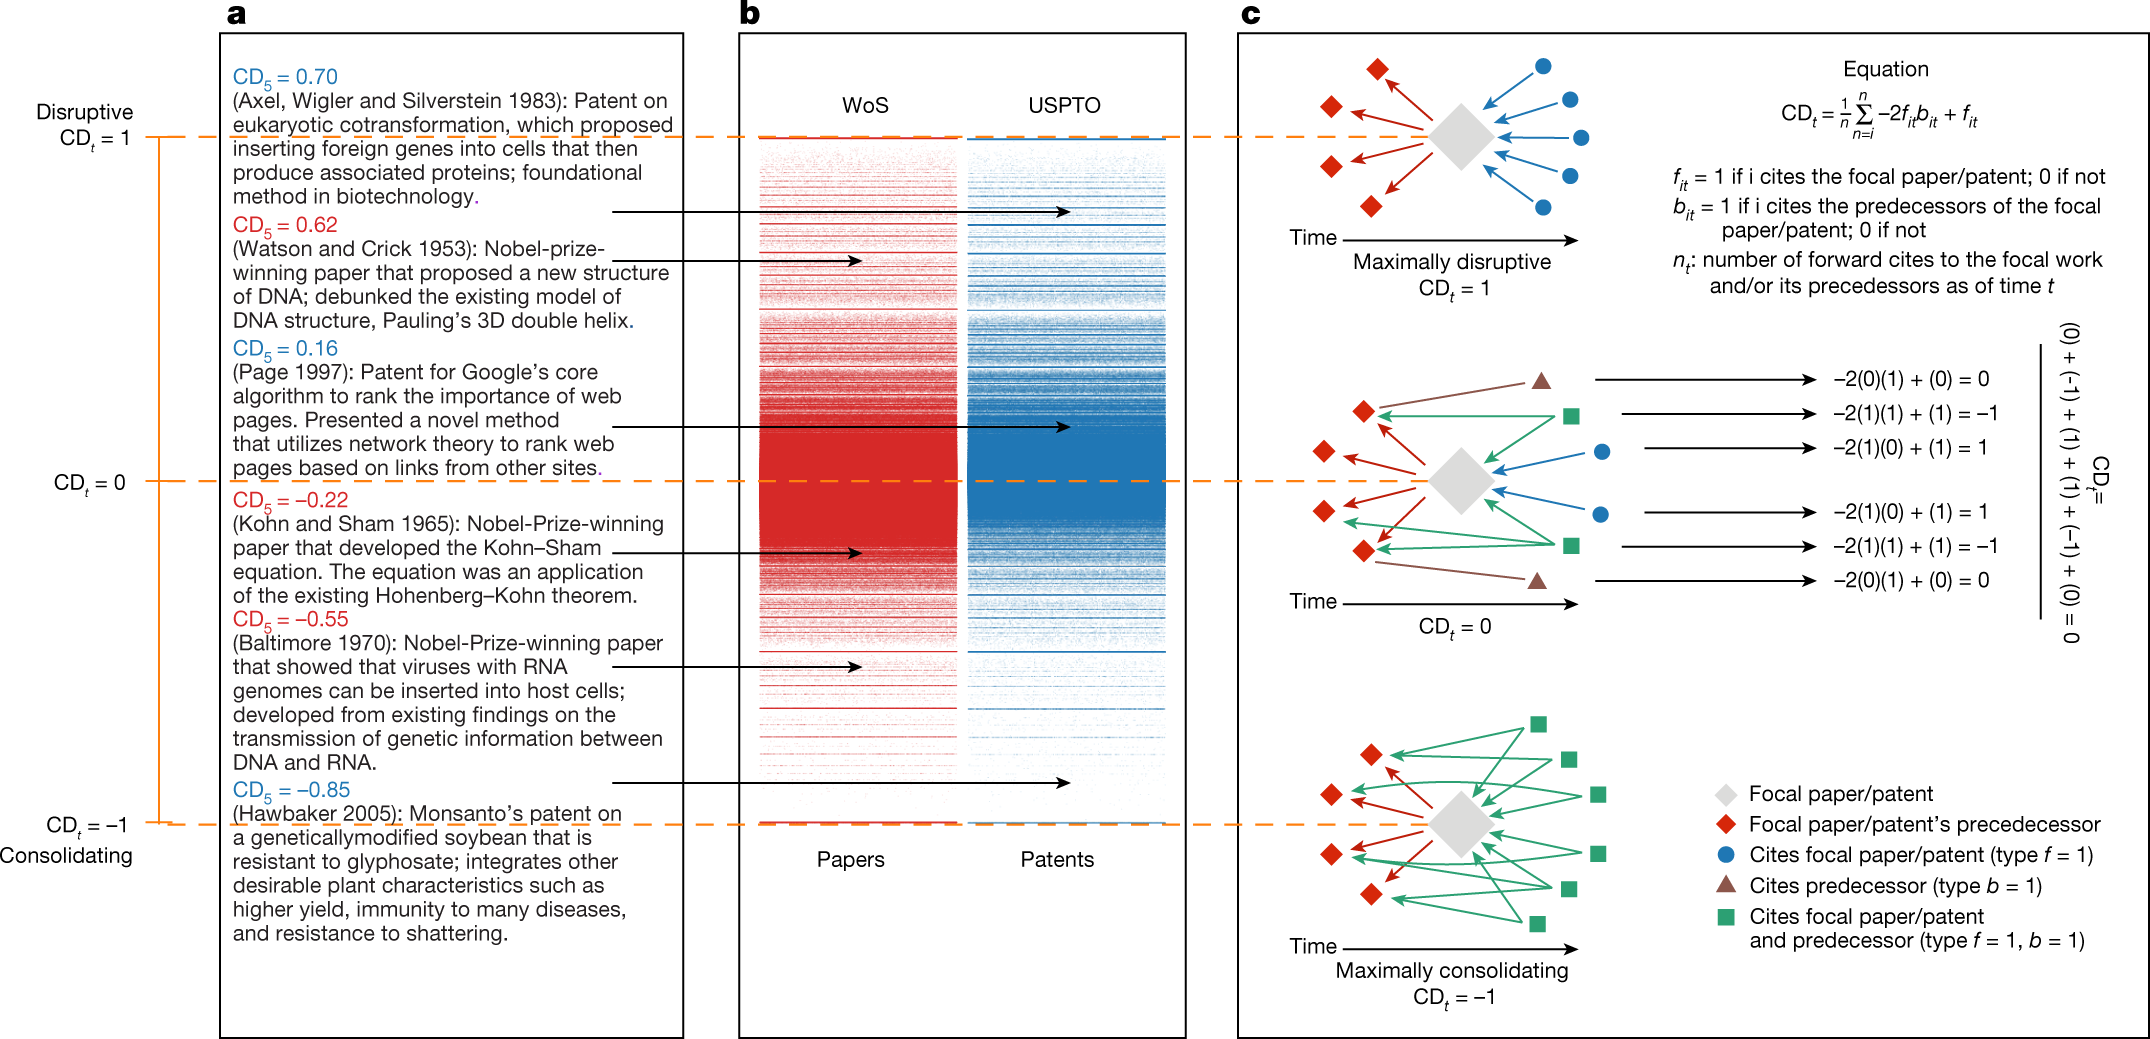
Papers and patents are becoming less disruptive over time
Theories of scientific and technological change view discovery and invention as endogenous processes1,2, wherein previous accumulated knowledge enables future progress by allowing researchers to, in Newton’s words, ‘stand on the shoulders of giants’3–7. Recent decades have witnessed exponential growth in the volume of new scientific and technological knowledge, thereby creating conditions that should be ripe for major advances8,9. Yet contrary to this view, studies suggest that progress is slowing in several major fields10,11. Here, we analyse these claims at scale across six decades, using data on 45 million papers and 3.9 million patents from six large-scale datasets, together with a new quantitative metric—the CD index12—that characterizes how papers and patents change networks of citations in science and technology. We find that papers and patents are increasingly less likely to break with the past in ways that push science and technology in new directions. This pattern holds universally across fields and is robust across multiple different citation- and text-based metrics1,13–17. Subsequently, we link this decline in disruptiveness to a narrowing in the use of previous knowledge, allowing us to reconcile the patterns we observe with the ‘shoulders of giants’ view. We find that the observed declines are unlikely to be driven by changes in the quality of published science, citation practices or field-specific factors. Overall, our results suggest that slowing rates of disruption may reflect a fundamental shift in the nature of science and technology.
Unreproducible Research is Reproducible
The apparent contradiction in the title is a wordplay on the different meanings attributed to the word reproducible across different scientific fields. What we imply is that unreproducible findings can be built upon reproducible methods. Without denying the importance of facilitating the reproduction of methods, we deem important to reassert that reproduction of findings is a fundamental step of the scientific inquiry. We argue that the commendable quest towards easy deterministic reproducibility of methods and numerical results should not have us forget the even more important necessity of ensuring the reproducibility of empirical findings and conclusions by properly accounting for essential sources of variations. We provide experiments to exemplify the brittleness of current common practice in the evaluation of models in the field of deep learning, showing that even if the results could be reproduced, a slightly different experiment would not support the findings. We hope to help clarify the distinction between exploratory and empirical research in the field of deep learning and believe more energy should be devoted to proper empirical research in our community. This work is an attempt to promote the use of more rigorous and diversified methodologies. It is not an attempt to impose a new methodology and it is not a critique on the nature of exploratory research.
The Current Crisis: What's Happening to Science in America
Speculations on the Future of the Scientific Method
The following essay was published 20 years ago (January, 2006) on my blog The Technium. I edited the intro here, but the speculations are basically unchanged.
What happened to Science Goodreads and how do we rebuild it? A 65 million dollar question (at least) - Cosmik Labs
The story of the rise and fall of Mendeley
Maybe scientific progress isn’t slowing, after all
A new paper takes aim at the claim that science has become less disruptive

Where does the rigor go? Research software and the future of trustworthy science.
Generative AI now makes it dramatically easier to produce something that looks like research: analysis code, figures, literature reviews, even whole pap…
Computational reproducibility

The why and how of making scientific computations reproducible
Konrad Hinsen's blog
Home Page - Software Heritage
GNU Guix transactional package manager and distribution — GNU Guix

Keynote: Reproducibility and replicability of computer simulations | Canal U
Reproducible research: methodological principles for transparent…
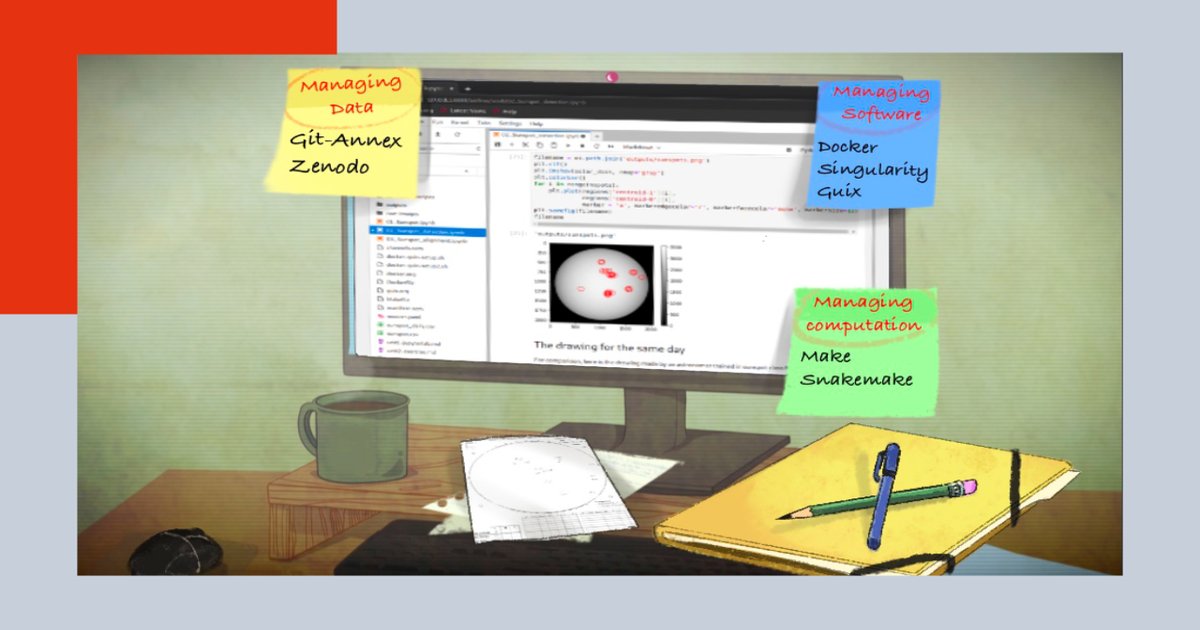
Reproducible Research II: Practices and tools for managing compu…