By now, most scientists have probably seen figures, tables, and even entire journal articles made by so-called "generative AI", containing more or less subtle mistakes or inconsistencies. What I haven't seen yet, but expect to see soon, is the scientific equivalent of deepfakes: made-up results that come with made-up code that reproduces them. This is likely to become a new challenge for reproducible research.
Where does the rigor go? Research software and the future of trustworthy science.
Generative AI now makes it dramatically easier to produce something that looks like research: analysis code, figures, literature reviews, even whole pap…
Pentagon boasts of using AI to write reports mandated by Congress
Pentagon also claims 1.5 million personnel are using generative AI tools.
AI agents are checking the scientific literature — and spotting decades-old errors
The technology is proving adept at finding faults in decades-old papers and reference databases.
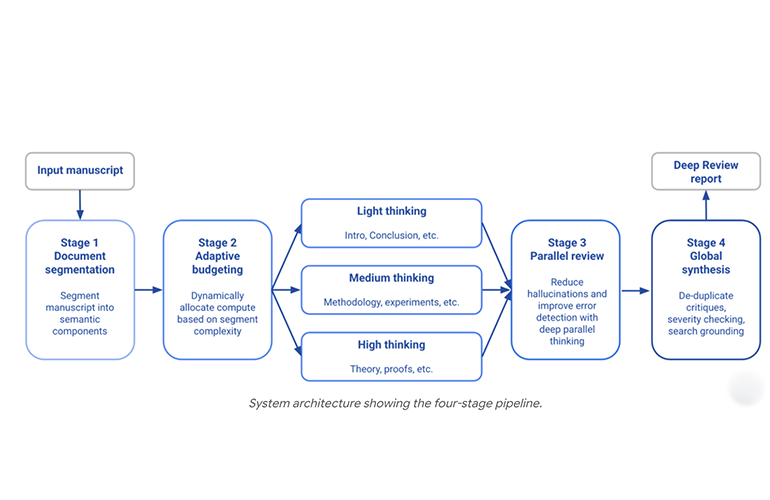
Google opens Deep Review AI tool to help researchers catch manuscript errors
Google Research on Oct. 14 released Deep Review, an AI system designed to flag mathematical errors, logical gaps and unsupported claims in technical documents. The public launch follows pilots that provided feedback on more than 15,000 manuscripts, according to Google. Speaking at Google’s Research@ event in Mountain View, California, Rajesh Jayaram, a research scientist at…
Unmasking Synthetic Realities in Generative AI: A Comprehensive...
The rapid advancement of Generative Artificial Intelligence has fueled deepfake proliferation-synthetic media encompassing fully generated content and subtly edited authentic material-posing...

Andrej Karpathy Stopped Using AI to Write Code. He’s Using It to Build a Second Brain Instead
His new workflow turns raw research into a self-maintaining wiki.No vector databases, no RAG pipelines, just markdown files and an LLM that…
OpenAI admits AI hallucinations are mathematically inevitable, not just engineering flaws
In a landmark study, OpenAI researchers reveal that large language models will always produce plausible but false outputs, even with perfect data, due to fundamental statistical and computational limits.

Reify This
The authors contend that contemporary efforts to render AI systems interpretable rest on a mistake: reification, the process of treating abstractions and statistical artifacts as if they were concrete realities.…
AI is turning research into a scientific monoculture
Generative AI deserves scientific attention. But the rush to study it is producing a feedback loop of topical and methodological convergence, flattening scientific imagination and crowding out the pluralism needed to keep research adaptive, resilient, and intellectually generative.

AI That Evolves in the Wild | Edge.org
I’m interested not in domesticated AI—the stuff that people are trying to sell. I'm interested in wild AI—AI that evolves in the wild. I’m a naturalist, so that’s the interesting thing to me. Thirty-four years ago there was a meeting just like this in which Stanislaw Ulam said to everybody in the room—they’re all mathematicians—"What makes you so sure that mathematical logic corresponds to the way we think?" It’s a higher-level symptom. It’s not how the brain works. All those guys knew fully well that the brain was not fundamentally logical.
The Myth of the Instant Cake Mix
How to think about creative tooling in the new world of generative AI
Verification in the Age of AI Scientists
AI Scientists now operate at a scale that outpaces human capacity for manual review. Systems such as Sakana’s AI Scientist write entire workshop papers end-to-end. Lila Sciences runs autonomous ``AI Science Factories’’ that hypothesize, experiment, and iterate without human guidance. FutureHouse’s Kosmos and Robin generate thousands of candidate hypotheses in a single run, and Google’s Co-Scientist proposes testable experiments at a rate no laboratory can fully evaluate. Each of these systems emphasizes verified results, yet that standard ranges from near-perfect formal proof in mathematics to decade-long clinical trials in medicine, with no shared framework for judging sufficiency across domains. As outputs scale beyond what humans can manually inspect, the question of which results to trust becomes as hard as generating them. The bottleneck for AI for Science is no longer hypothesis generation, it is verification.
Guest Post — When Errors Become Consensus: Science’s Self-Correction Can No Longer Keep Up - The Scholarly Kitchen
From 19th-century beef tea to paper mills and generative AI, the challenge is no longer detection alone; it is preventing bad claims from becoming embedded knowledge.
Can AI Agents Synthesize Scientific Conclusions?
Scientific AI agents increasingly retrieve evidence, reason across sources, and synthesize conclusions used in consequential decisions. Yet, their ability to do so in high-stakes domains such as health remains unclear. We introduce SciConBench, a large-scale live benchmark of 9.11K questions and expert-written conclusions from systematic reviews to evaluate open-domain scientific conclusion synthesis. The benchmark draws on an expert-validated automated evaluation pipeline that decomposes conclusions into atomic facts and measures correctness and comprehensiveness via factual precision and recall. To mitigate data leakage, we further introduce SciConHarness, a clean-room evaluation harness that equips agents with controlled web interaction to ensure valid measurement. Evaluating 8 frontier models and deep research agents, we find that factual quality remains low: under clean-room settings, the best agent achieves only a factual F1 of 0.337. Our clean-room setting consistently reduces performance relative to unconstrained evaluation, suggesting that leakage inflates estimates of models' true synthesis capabilities. Finally, we audit consumer-facing agents (e.g., Google AI Overview, OpenEvidence) and find they frequently generate incomplete and sometimes contradictory conclusions, even when the ground-truth answer is available. Overall, our results show that reliable synthesis of scientific conclusions remains an open challenge, and that clean-room evaluation is essential for assessing open-domain AI agents.
Generative artificial intelligence: The Times and Sunday Times editorial guidelines
As we explore the potential of generative artificial intelligence our commitment is to uphold our high editorial standards.
Deep Research, information vs. insight, and the nature of science
What AI will accelerate in the scientific process, what it cannot do, and how we can prepare for new manners of scientific investigation.