


Build AI applications faster with LangChain and Chroma's integration. Get an easy-to-use vector store that runs locally for seamless LLM app prototyping.
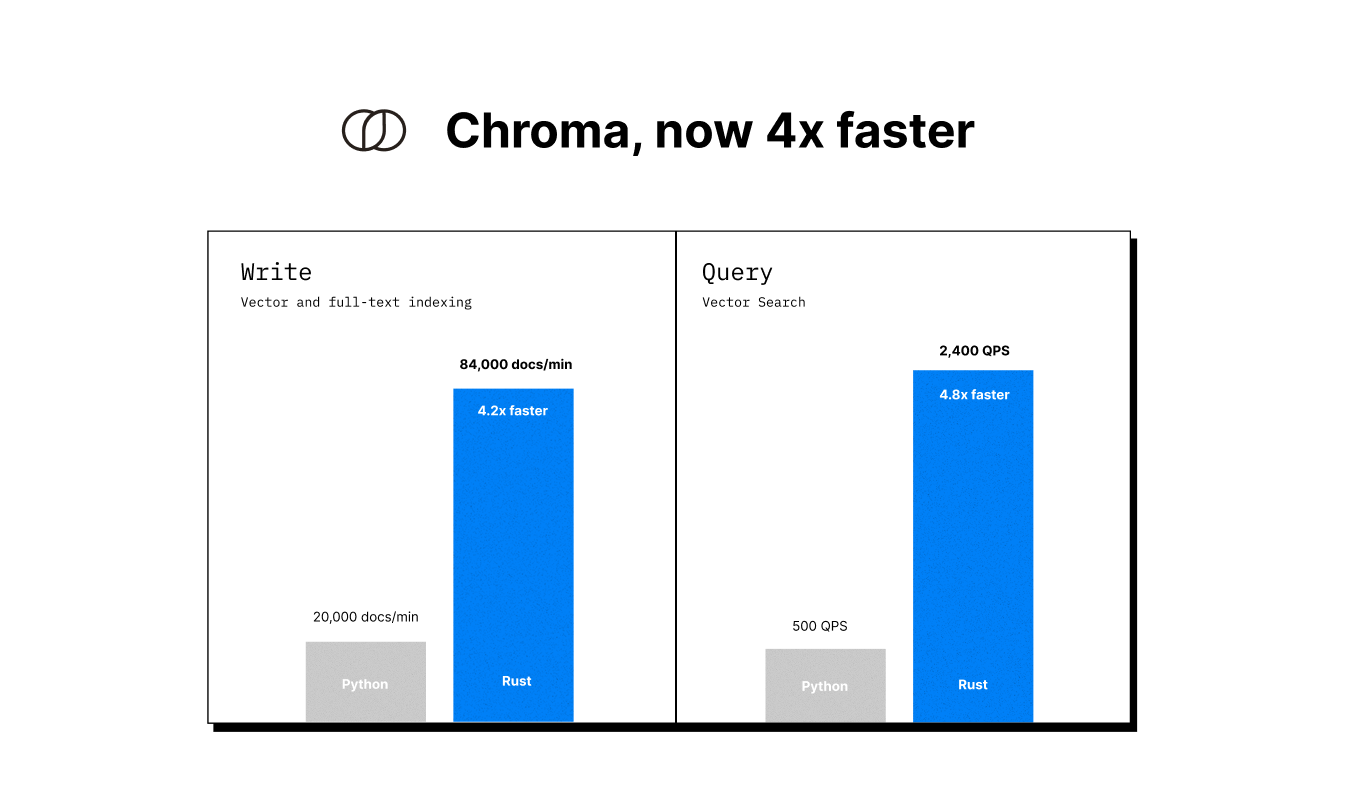
Chroma is now 4x faster
Two years ago, we set out to make AI retrieval effortless for developers. 30+ million downloads later, that vision is becoming reality with widespread adoption across hackathon projects, fast-growing AI startups, and Fortune 500 companies.
WebAssembly, Large Language Models, and Kubernetes Matter
WebAssembly makes it quick and easy to download and run a complete LLM on a machine without any major setup.

Native Development
I’ve been on a long-term quest to find a simple, fast, and user-friendly way to develop native applications for a variety of platforms, and this page holds ...

Tiiny Pocket | Personal AI Infrastructure for Local LLMs
Run open-source LLMs locally on Tiiny AI Pocket, with 80GB of memory, simple setup, API access for agents and workflows, and zero token fees.
Multi-platform Development (Introduction)
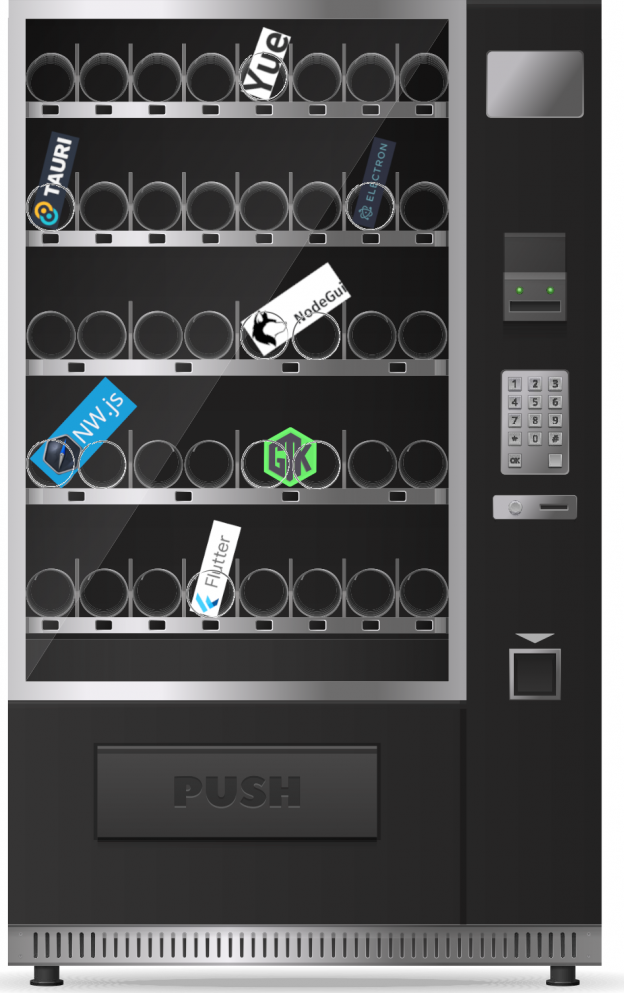
Over the last several months I have been testing several HTML/CSS/JavaScript based cross platform development systems. When trying out a new technology, I spend several full days playing with it learning the in's and out's. Its awesomeness and its gotchas. I am going to go over Tauri, NodeGui, Flutter, NW.JS, Yue, Node-GTK+ and Electron over the next couple posts. (These link to the actual tool sites, not to any of my blog posts on them)
open-slopware
Free/Open Source Software choosing to use and/or support LLM usage/AI, as well as alternatives and tips to requesting better policies or forking.
Google for Developers Blog - News about Web, Mobile, AI and Cloud
LiteRT is the universal framework for on-device AI. The production stack delivers 1.4x faster cross-platform GPU performance, streamlined NPU acceleration, and superior GenAI support for open models like Gemma.

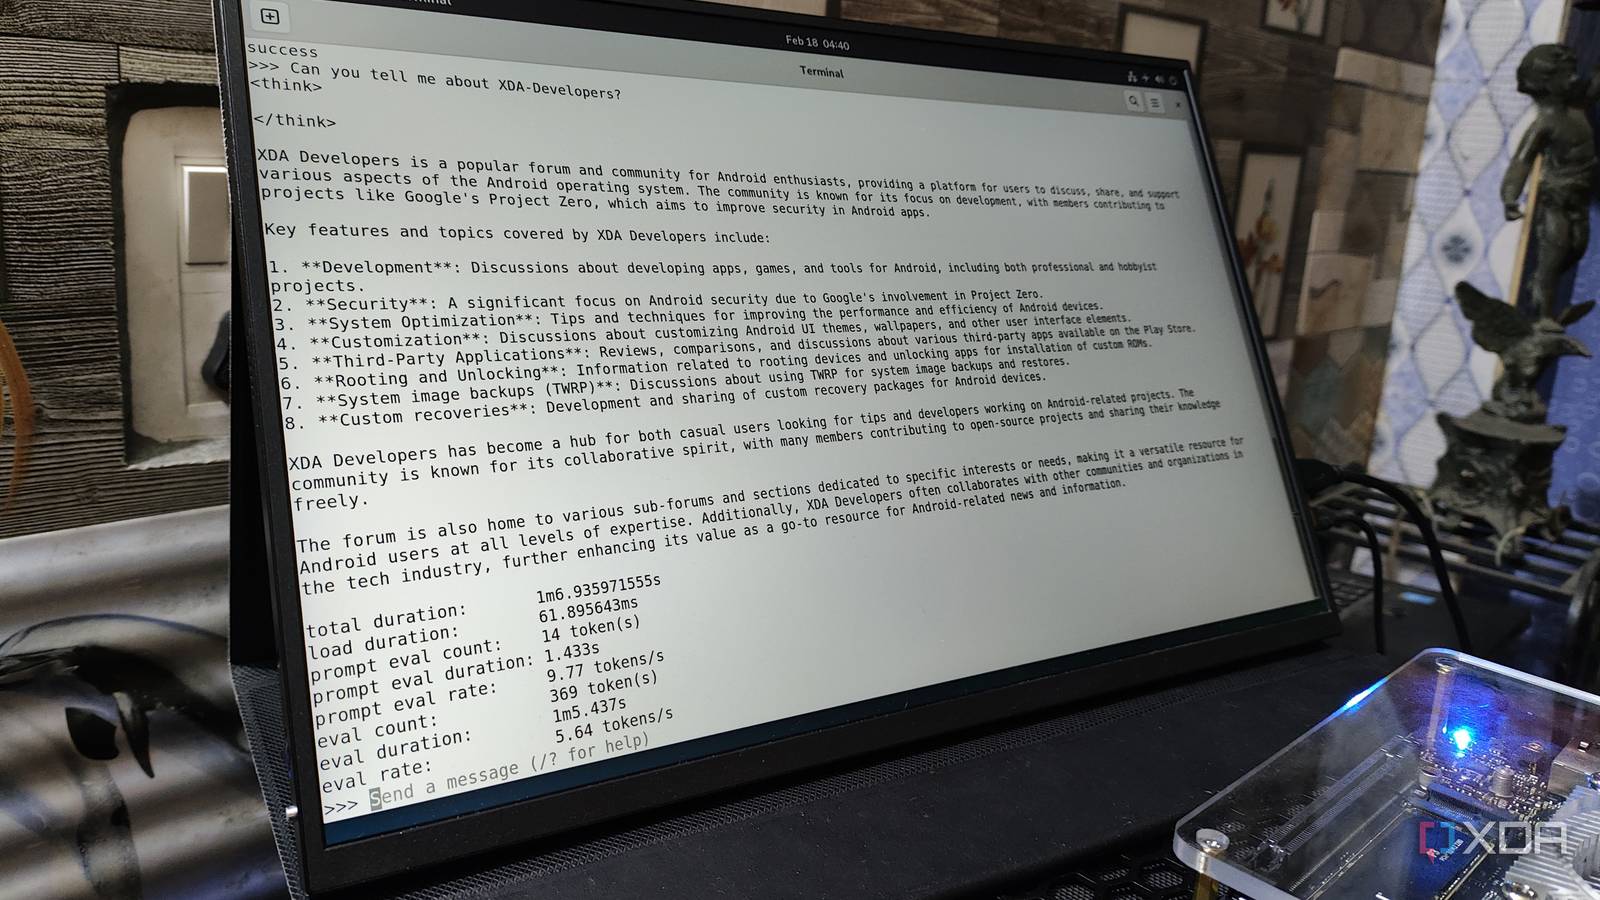
I don't pay for ChatGPT, Perplexity, Gemini, or Claude – I stick to my self-hosted LLMs instead
There's no point in relying on AI tools when my local LLMs can handle everything
Introducing LFM2: The Fastest On-Device Foundation Models on the Market | Liquid AI
Today, we release LFM2, a new class of Liquid Foundation Models (LFMs) that sets a new standard in quality, speed, and memory efficiency for on-device deployment. Built on a hybrid architecture, LFM2 delivers 200% faster decode and prefill performance than Qwen3 and Gemma 3 on CPU. It also significantly outperforms models in each size class on instruction-following and function calling—the core capabilities that make LLMs reliable for building AI agents.

Replit: Make an app for that
Announcing the General Availability of LangSmith and Our Series A Led By Sequoia Capital
LangSmith is now generally available. Build, test, and monitor LLM applications from prototyping to production with debugging and evaluations.
