

Luminal compiles off-the-shelf models to Positron Atlas and Nvidia Blackwell to unlock fast and cheap inference across heterogeneous chips.
Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
Open-Source Agentic Inference Benchmark | InferenceX
Compare AgentX, InferenceX's long-context, multi-turn coding scenario, with fixed-sequence AI inference across chips and frameworks. Public NVIDIA and AMD runs update when configurations change.
NVIDIA Rubin CPX Accelerates Inference Performance and Efficiency for 1M+ Token Context Workloads | NVIDIA Technical Blog
Inference has emerged as the new frontier of complexity in AI. Modern models are evolving into agentic systems capable of multi-step reasoning, persistent memory, and long-horizon context—enabling…

InferenceMAX™: Open Source Inference Benchmarking
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B
GPU Pricing — Live Platform Rates | Vast.ai
Live GPU pricing on Vast.ai. Prices set by supply and demand across 40+ data centers. On-demand, interruptible, or reserved — find the right GPU at the right price.
TheStage AI – Faster, Cheaper AI Inference
Accelerate models on NVIDIA & edge. Full guides for setup, optimization & deploy. ANNA, QLIP, Elastic Models, CLI & API. Built for AI teams & devs.

Advancing AI Infrastructure for Agentic AI with NVIDIA DOCA In-Silicon Security | NVIDIA Technical Blog
The AI era is driving a new class of infrastructure: AI factories that transform data into intelligence for autonomous AI agents operating at unprecedented scale. Powered by accelerated computing…

AI Inference Pricing, EU Hosted, Per Token | TensorX
Transparent, pay-as-you-go pricing for private AI inference on TensorX. No lock-in, EU-hosted, with zero data retention and an OpenAI-compatible API.
Building with Open Models
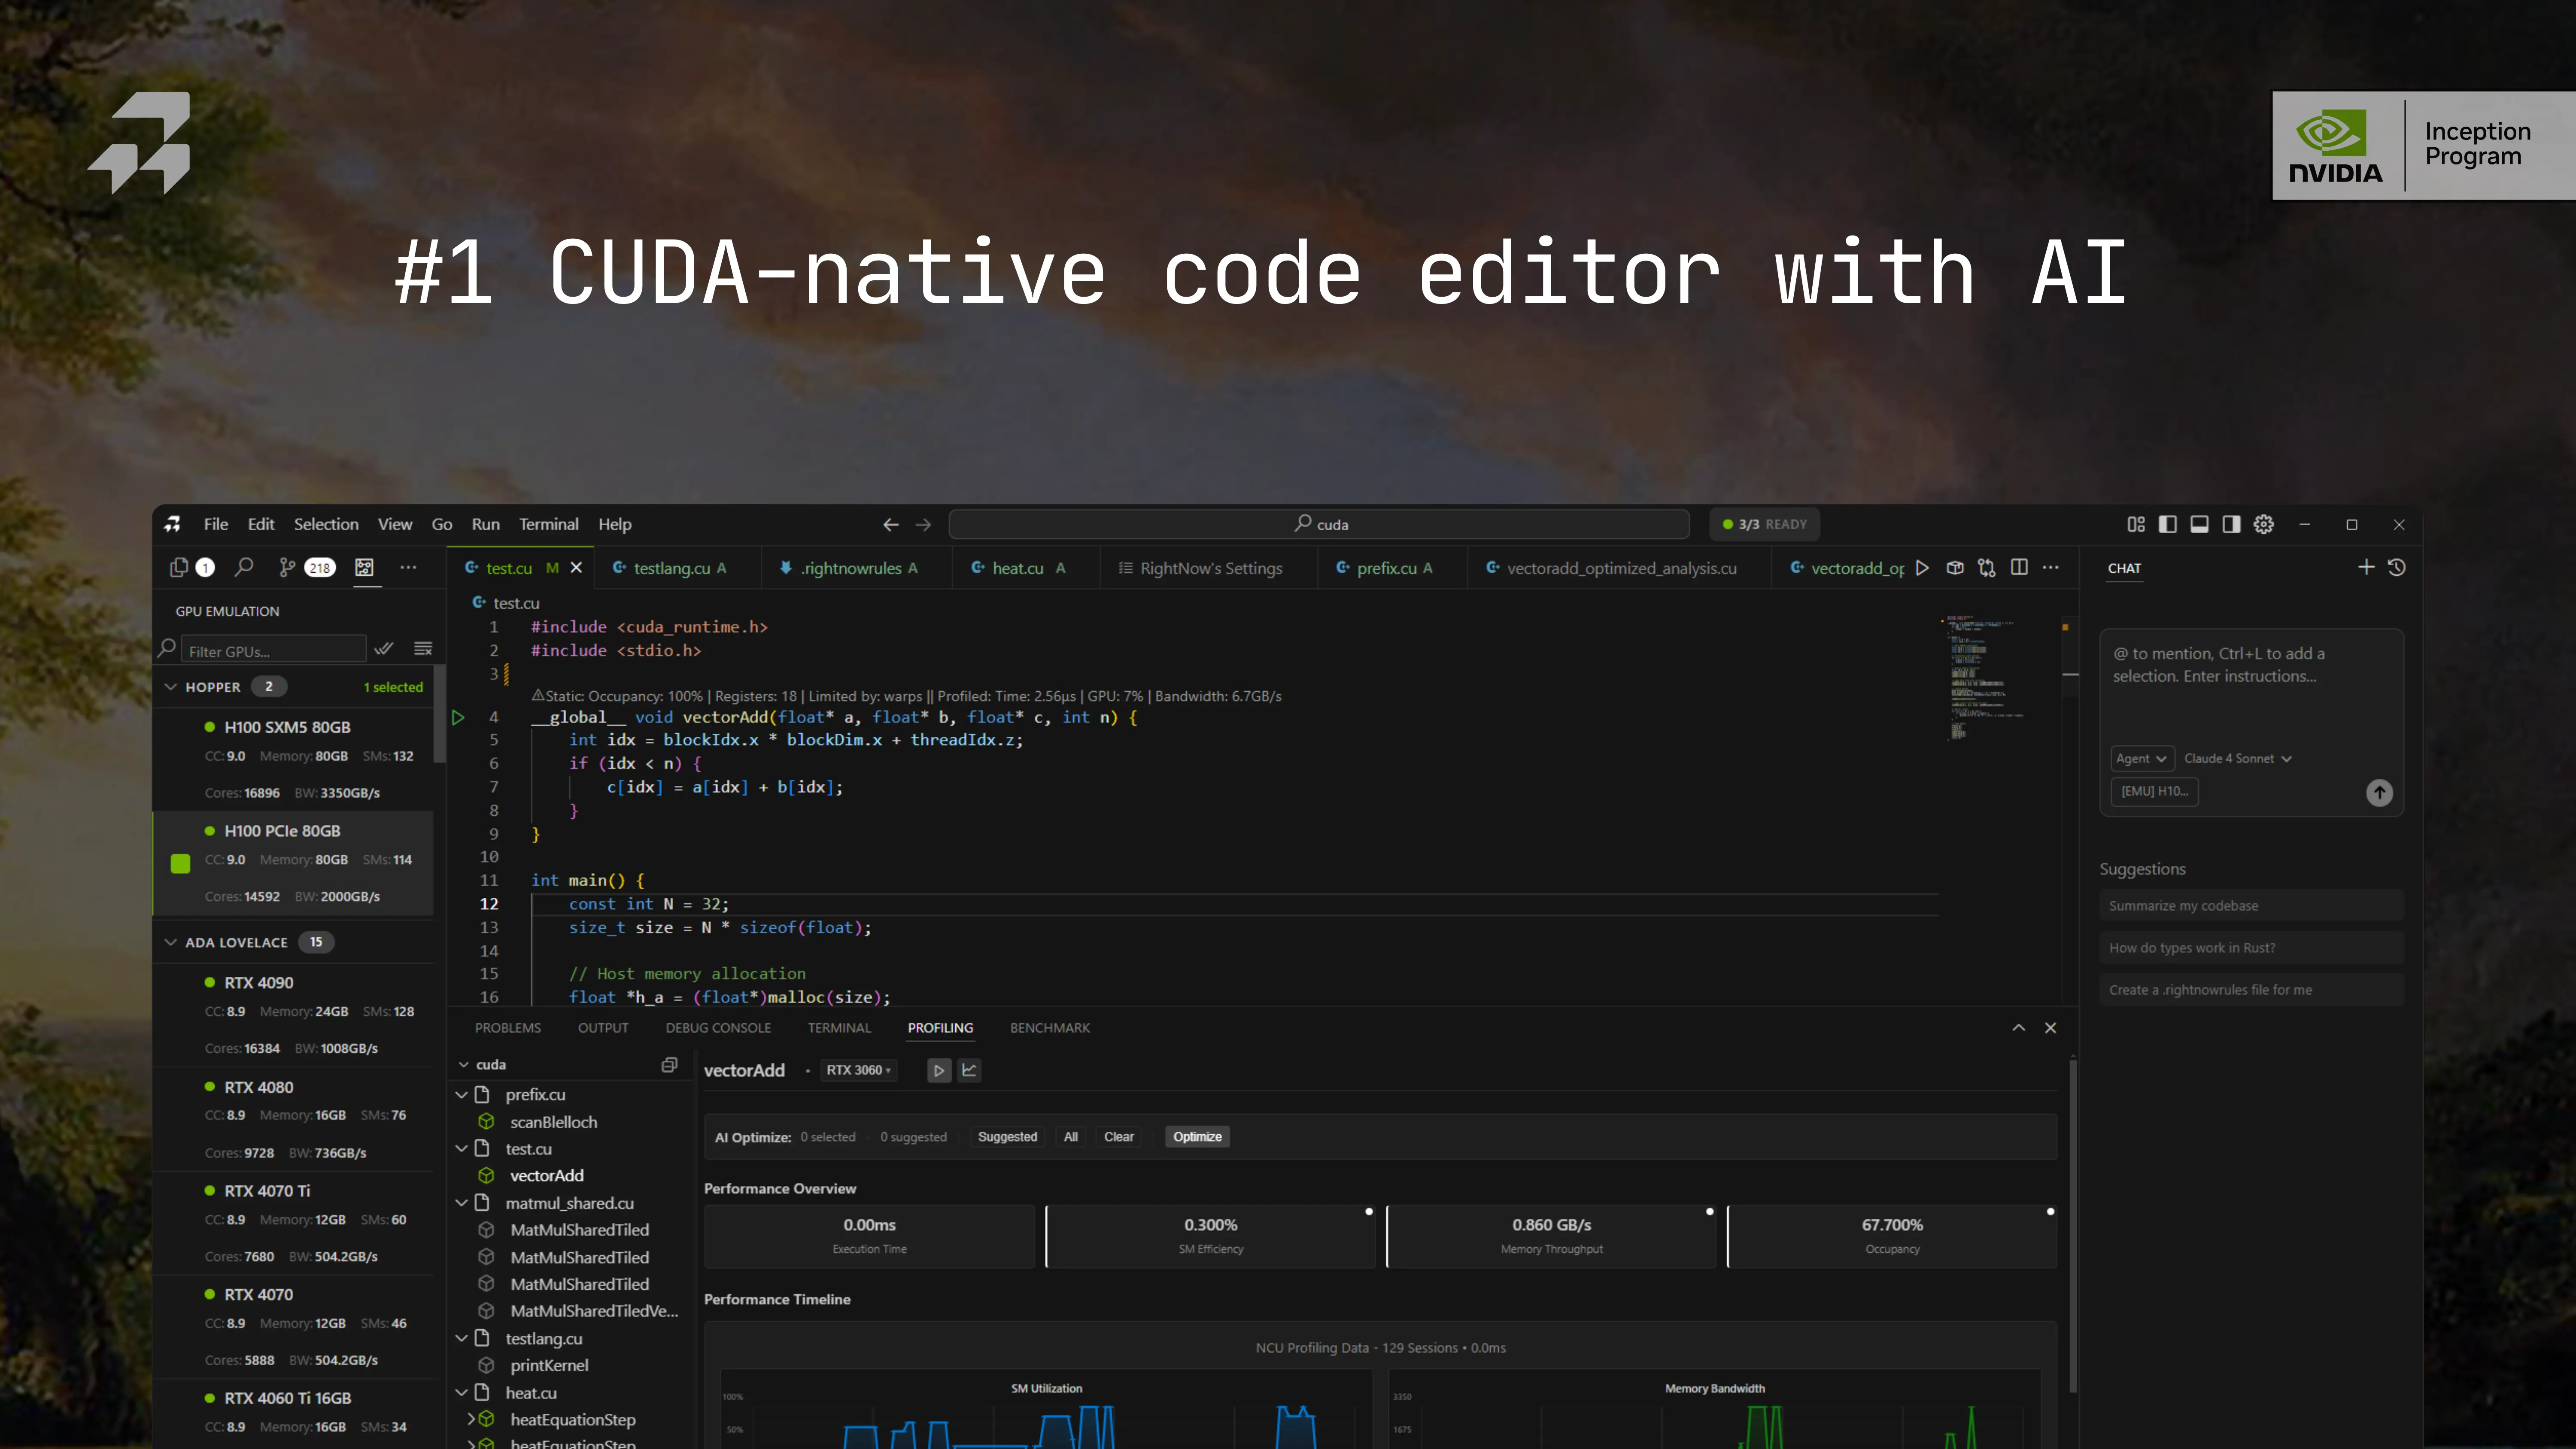
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
The Universal Execution Layer for AI
Optimize any AI model on any engine, across all hardware. Dria’s topology-aware compiler and peer-to-peer runtime merge CPUs, GPUs, NPUs & chiplets into one fabric—maximising utilisation, cutting inference cost and ending vendor lock-in.

Import AI 470: No rights for machines; automating environment generation with SPADE; and building better GPU kernels with Hawkeye
Differential acceleration of cyber, math, and AI
AI GPUs probably live longer than three years
People who think current AI use is unsustainable often rely on the claim that inference GPUs only last “three years at the most” under load1. The idea here is that once the AI bubble money drains away, current infrastructure will rapidly become obsolete, and there won’t be enough money floating around to buy a whole slate of brand-new GPUs. Inference costs would thus rapidly become way too expensive for current AI products to make any financial sense.
Wafer - Ship the fastest inference in the world
Autonomous AI agents that profile, diagnose, and optimize GPU inference across your entire stack — from kernels to models to production pipelines.

NVIDIA Shatters MoE AI Performance Records With a Massive 10x Leap on GB200 'Blackwell' NVL72 Servers, Fueled by Co-Design Breakthroughs
Scaling performance on MoE AI models is one of the industry constraints, but it appears that NVIDIA has managed to make a breakthrough.

Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026