

Converting hex numbers like 51ac0759fc4d into singable and memorable sirings like kalo-tadu-komu-tigi.
\robotoslablightdots.tts Technical Report
Text-to-speech (TTS) systems have largely solved intelligibility on standard read-speech benchmarks. What users expect from a modern system is broader: expressive and controllable output, real-time synthesis, and coverage of neutral reading, emotional dialogue, paralinguistic events, singing, and general audio. Current systems pursue this goal along three roughly distinct technical routes, and each route has its own unresolved problem.
Ivan Fioravanti ᯅ on Twitter / X
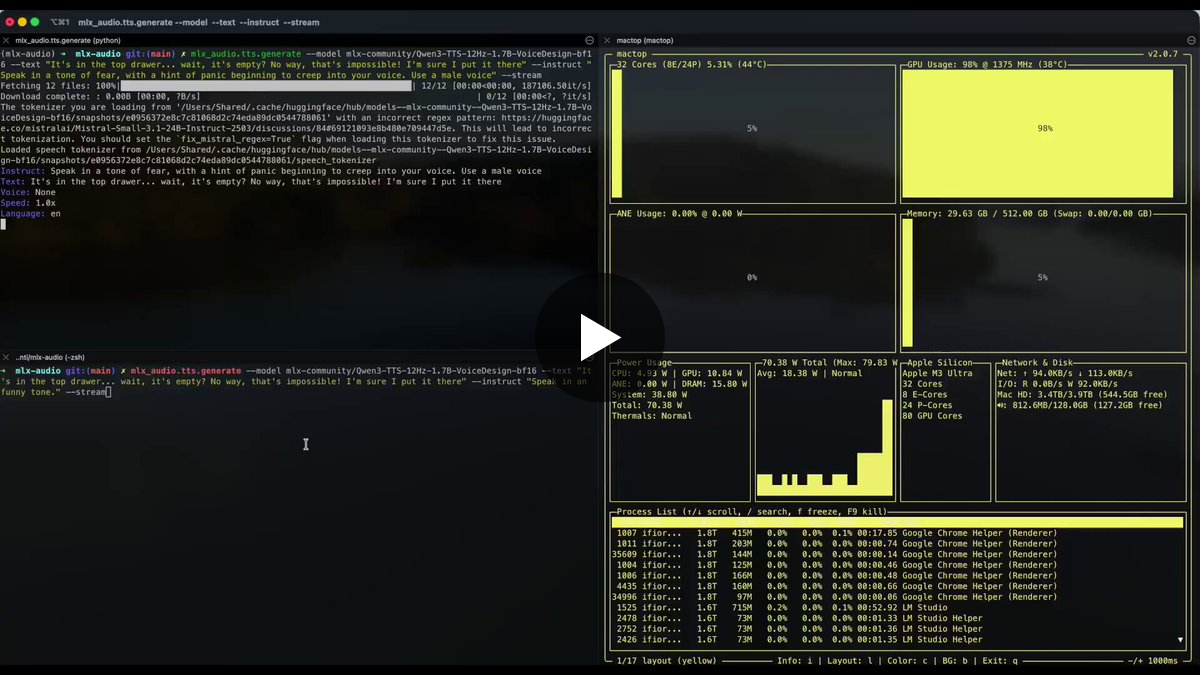
Playing with Qwen3-TTS is and MLX-Audio locally on Mac Studio M3 Ultra 🔥Amazing model by @Alibaba_Qwen and great work by @Prince_Canuma bringing this magic to MLX!Tuning the voice with instructions feels like magic!Command and prompts to run it are in the video. pic.twitter.com/qIfWKOedXr— Ivan Fioravanti ᯅ (@ivanfioravanti) January 23, 2026
mikegee on Twitter / X
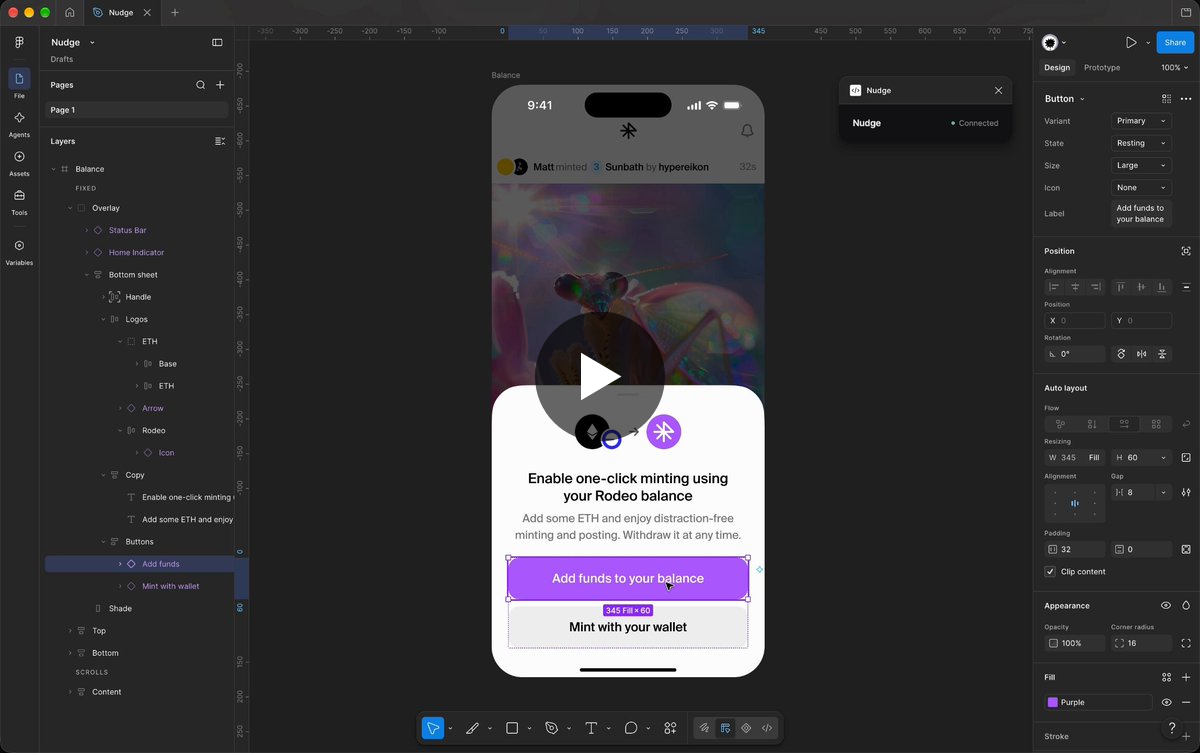
Controlling Figma with voice using Jev from @typesafeaiTotal cost from first line of code to recording this video: $0.01🤯 pic.twitter.com/HTGcrBYpTb— mikegee (@mikegee) September 18, 2026
Voice AI & Voice Agents | An Illustrated Primer
A comprehensive guide to voice AI in 2026
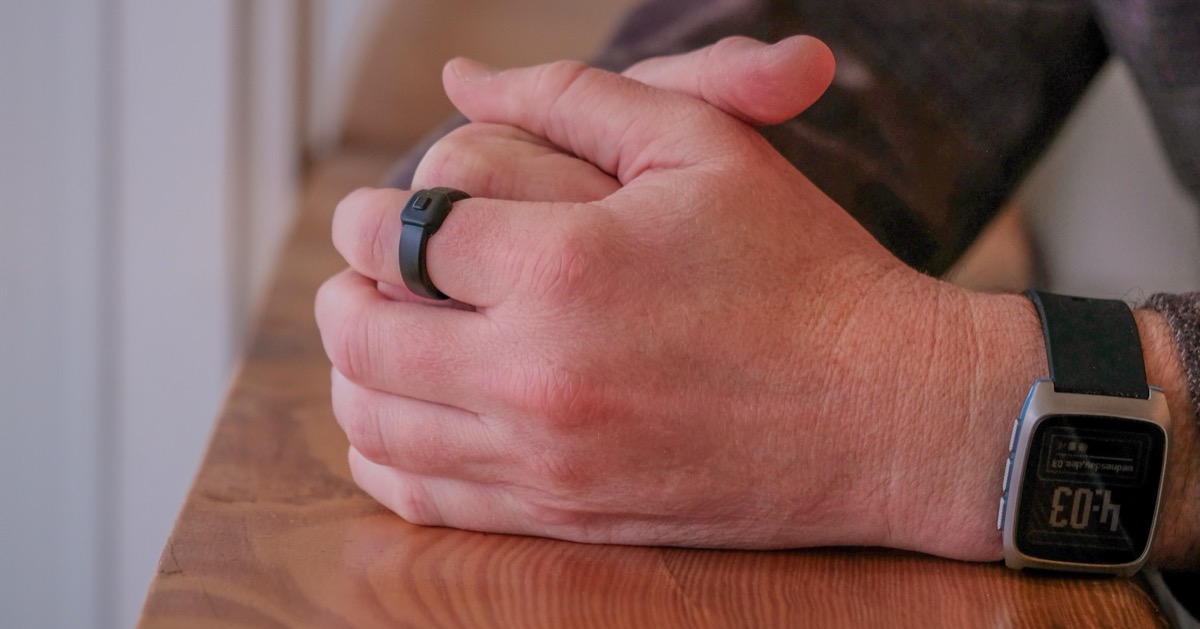
Pebble Index 01
A smart ring that records voice notes at the press of a button and transcribes them to your phone. External memory for your brain.
The secret story of the vocoder, the military tech that changed music forever
On Version History: how to play your voice like an instrument, with a little help from Chromeo.

Voice messengers built for childhood
Karri Messenger is a data and GPS enabled screen-free device enabling communication between you and your kids, and them and their friends.
Unicode Toys
Transliterate plain text (letters, sometimes numbers, sometimes punctuation) to obscure characters from Unicode. The output is fully cut-n-pastable text.
Advanced aspects of karaoke timing :: Karaoke Mugen Documentation
On this page, we will go into more detail which cues the blue sound spectrum in Aegisub can give you to make your timing precise and hopefully more efficient. Therefore, several aspects that were mentioned in the general tutorial will be explained in more depth here. Beat Most syllables in most songs will be on beat and therefore should also be timed there. However, recognizing the beat is not always easy.
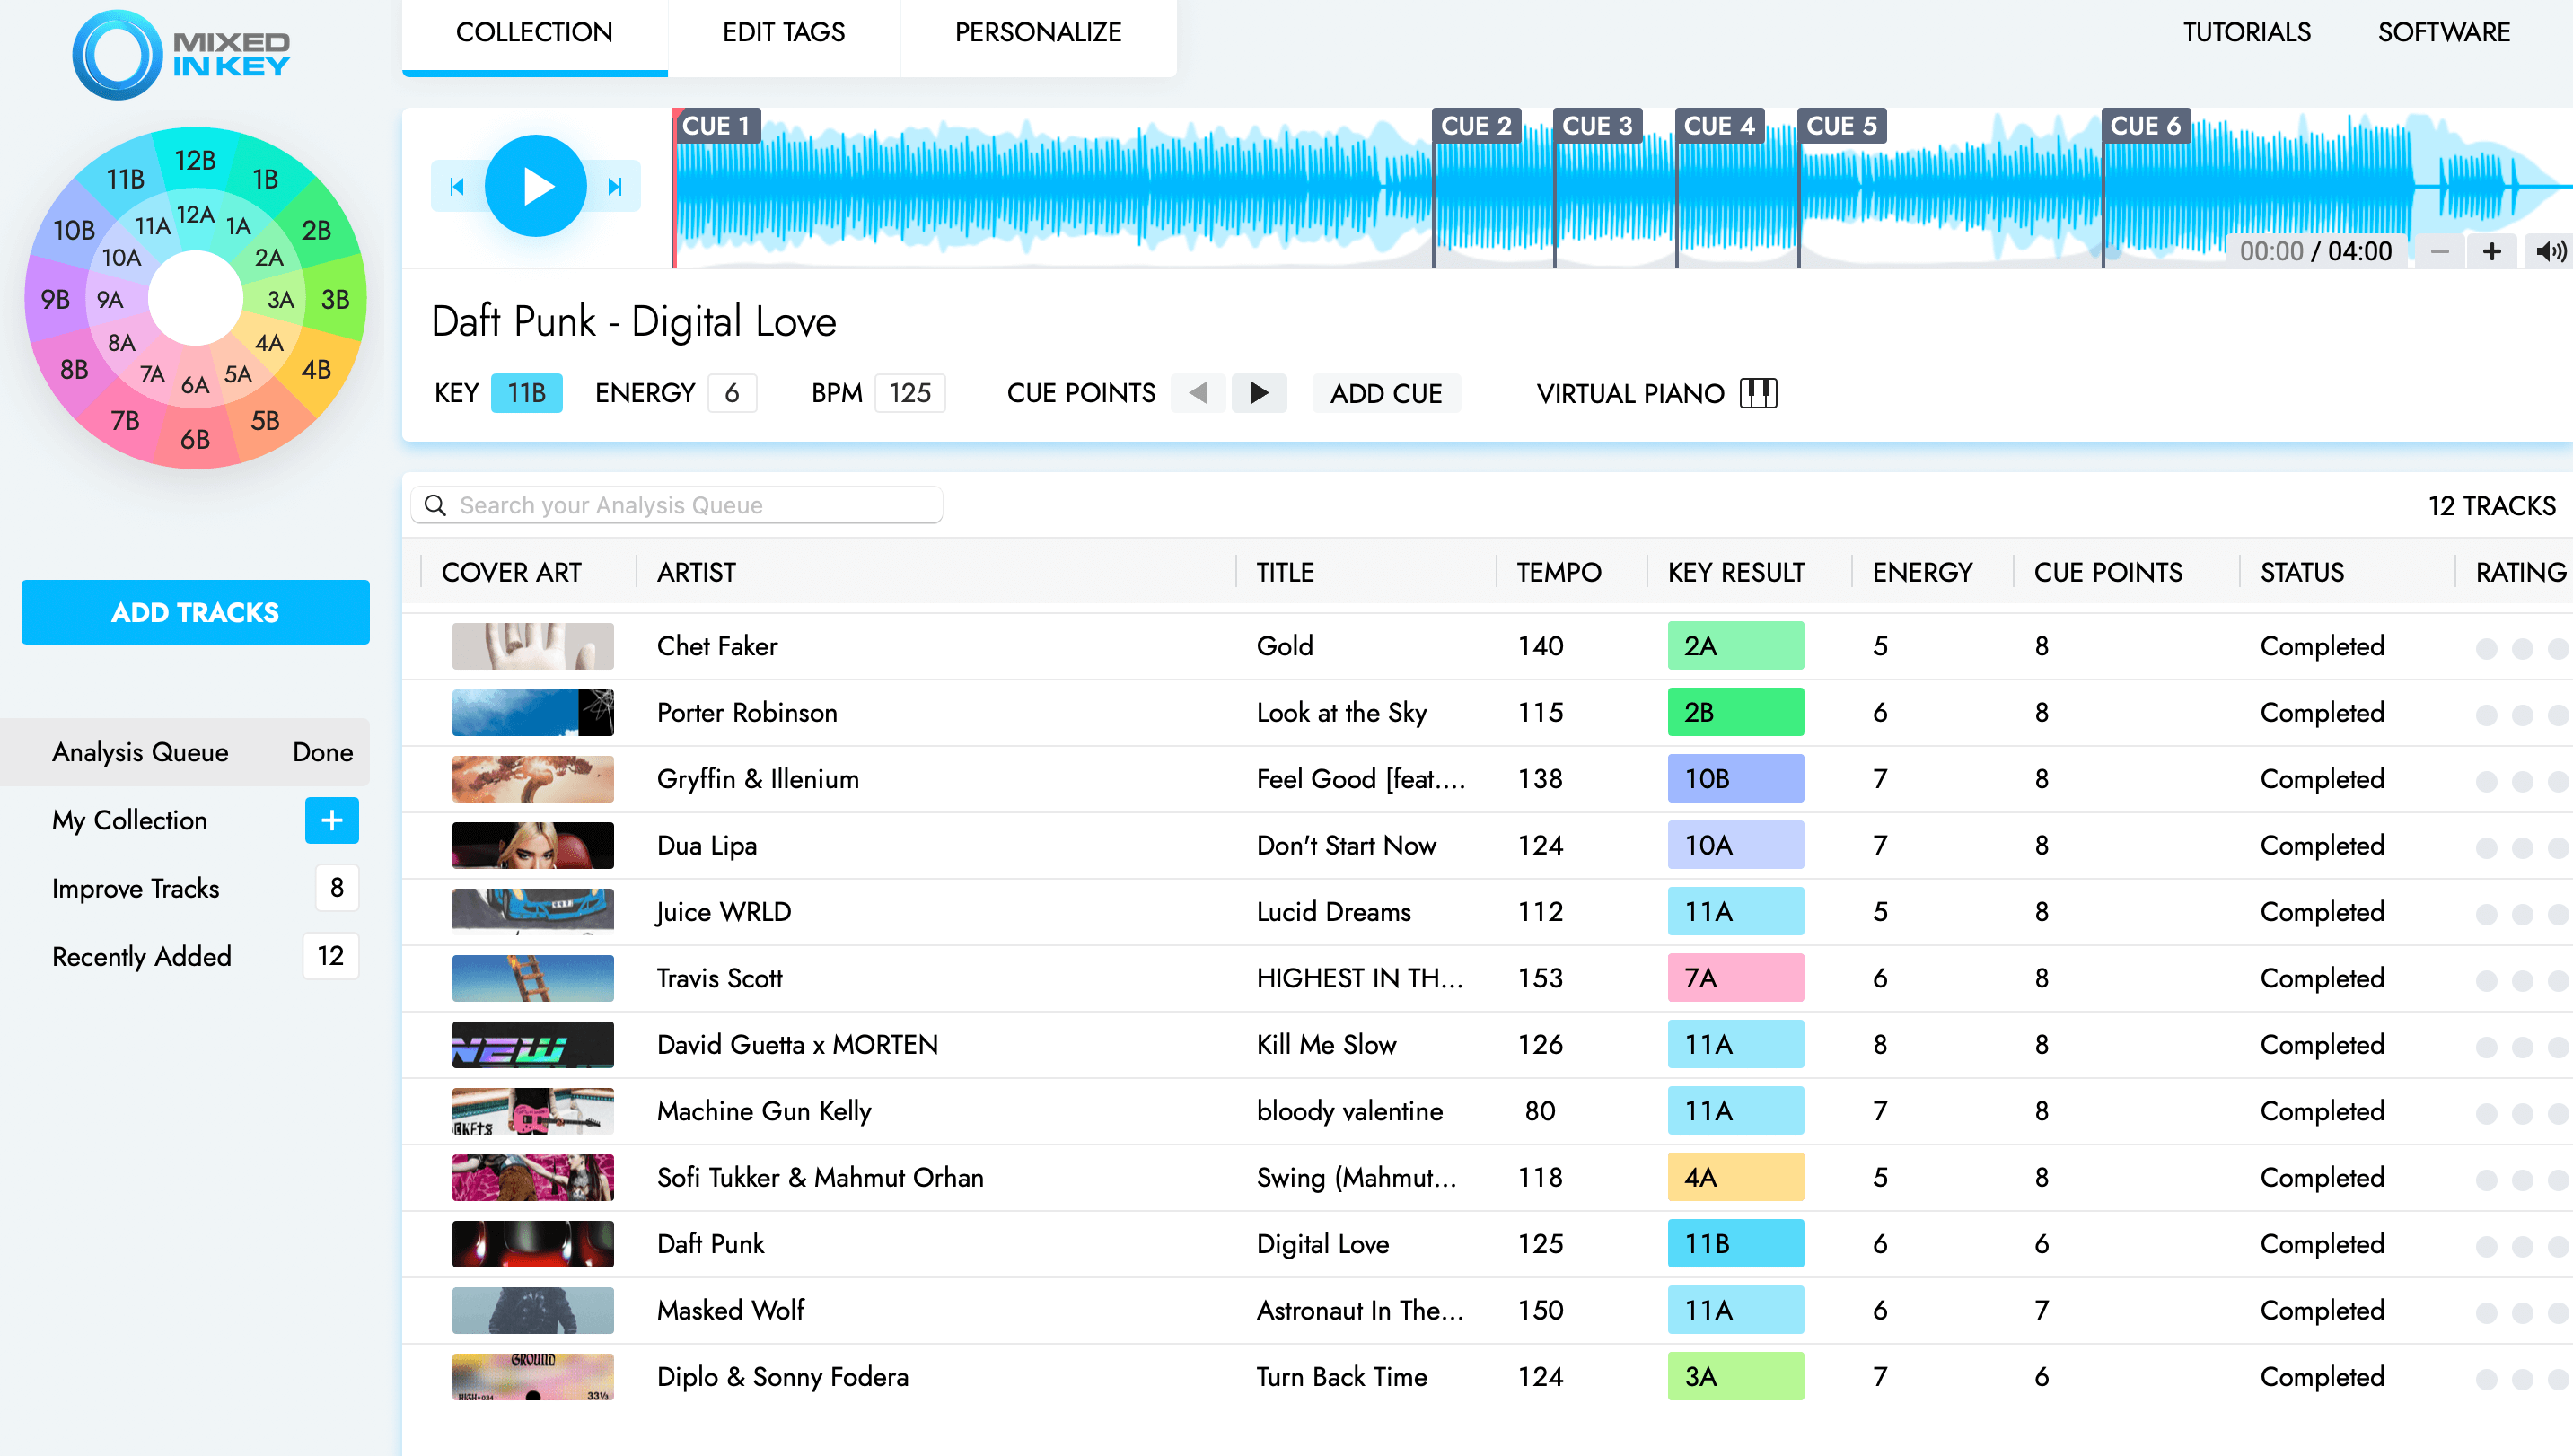
Mixed In Key: Software for DJs and Music Producers
Award-Winning software for DJs and Producers Mixed in Key Pro Wingman Captain Plugins Platinum Notes Pilot Plugins Mixed In Key Live Complete Collection Mixed In...
kwindla on Twitter / X
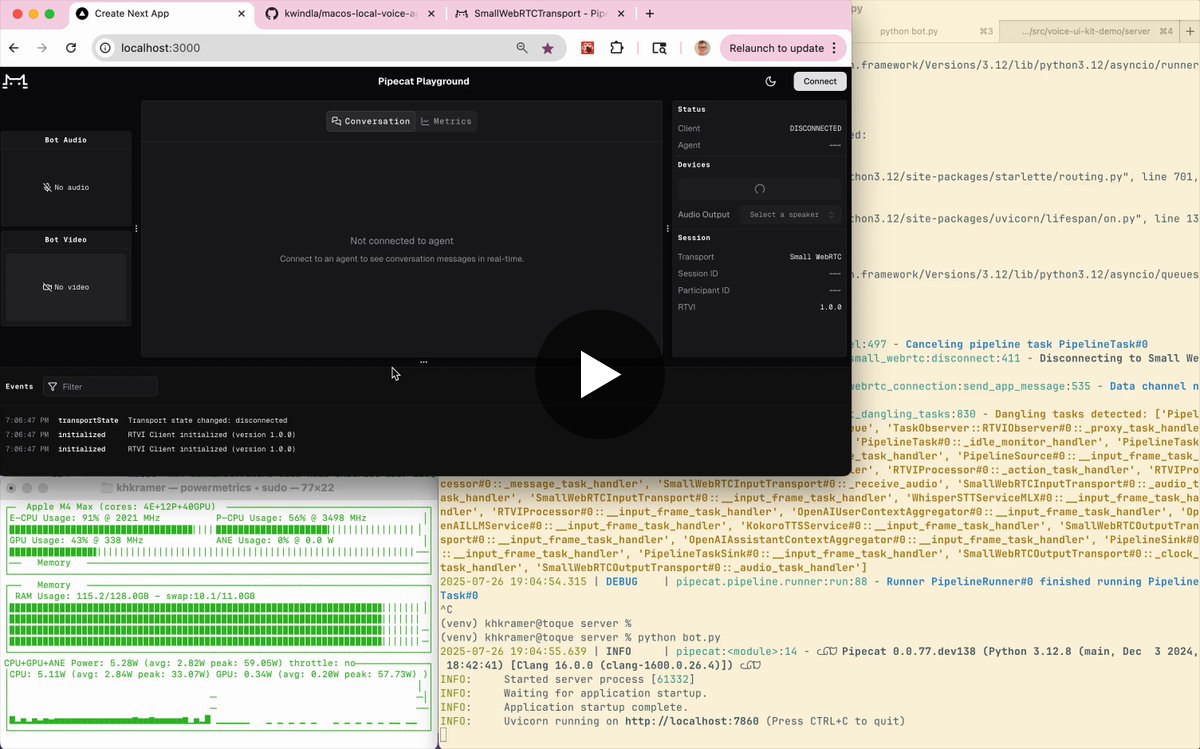
Local voice AI with a 235 billion parameter LLM. ✅- smart-turn v2- MLX Whisper (large-v3-turbo-q4)- Qwen3-235B-A22B-Instruct-2507-3bit-DWQ- KokoroAll models running local on an M4 mac. Max RAM usage ~110GB.Voice-to-voice latency is ~950ms. There are a couple of… pic.twitter.com/iYNQlb9JkI— kwindla (@kwindla) July 27, 2025
Superwhisper — AI Voice to Text for macOS, Windows & iOS
AI powered voice to text for macOS, Windows, and iOS. Dictate in any app with offline and cloud speech recognition, 100+ languages, and custom AI modes.
The Millions of Songs Mashed Into AI-Generated Music
Explore the astonishing amount of music available to AI developers.
Coqui TTS & XTTS V2: AI Text to Speech in 8 Languages
Experience natural speech synthesis with Coqui TTS and XTTS V2 technology. Features voice cloning and support for 8 languages.