

in my head i think of microcosm services as targeting audible-frequency request rates. right now constellation is receiving 150 req/sec, which is within fundamental human vocal range and sounds like this: szynalski.com/tone#150,squ,v0.5
Online Tone Generator - generate pure tones of any frequency
szynalski.comMay 11, 2026 at 3:48 PM
microcosm 2025 - microcosm
A quick (and almost complete) retrospective of what happened in microcosm's first year
microcosm.blue/microcosm-rs
Constellation, Spacedust, Slingshot, UFOs: atproto crates and services for microcosm
Microcosm | Granular Looper & Glitch Pedal
Microcosm reinterprets your sound in exciting ways using various granular sampling, delay, pitch-shifting and micro-looping techniques. Create ambient, glitch, and other wild sounds with your guitar, synthesizer, or other instrument. Features include Stereo In/Out, MIDI sync, tap tempo, hold sampler, and built-in looper.
Use One Big Server
A lot of ink is spent on the "monoliths vs. microservices" debate, but the real issue behind this debate is about whether distributed system …
Making MLS more decentralized
It’s no secret that we at Phoenix R&D are big fans of the Messaging Layer Security (MLS) protocol, having helped it to come into existence. It’s a versatile group key agreement and messaging protocol that’s used to power both asynchronous and real-time applications. MLS is
You Want Modules, Not Microservices
Dissecting why everybody keeps talking about microservices.
Introducing Hubble: A Public Mirror for the Whole Atmosphere - AT Protocol
Bluesky is providing a grant to the creator of Microcosm to build a full mirror of public data on the Atmosphere to help make the network more resilient.
SomaFM
Over 30 unique channels of commercial-free, listener-supported radio. All music hand-picked by SomaFM's award-winning DJs and music directors.

Vaibhav (VB) Srivastav on Twitter / X
I do agree to some extent - I do use variety of proprietary models for day to day use both as a soundboard and for workHowever, majority of the issues with local LLMs today is in the scaffolding/ runner - in most cases if you’re getting sub-par outputs - it’s the chat template,…— Vaibhav (VB) Srivastav (@reach_vb) November 25, 2025
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.
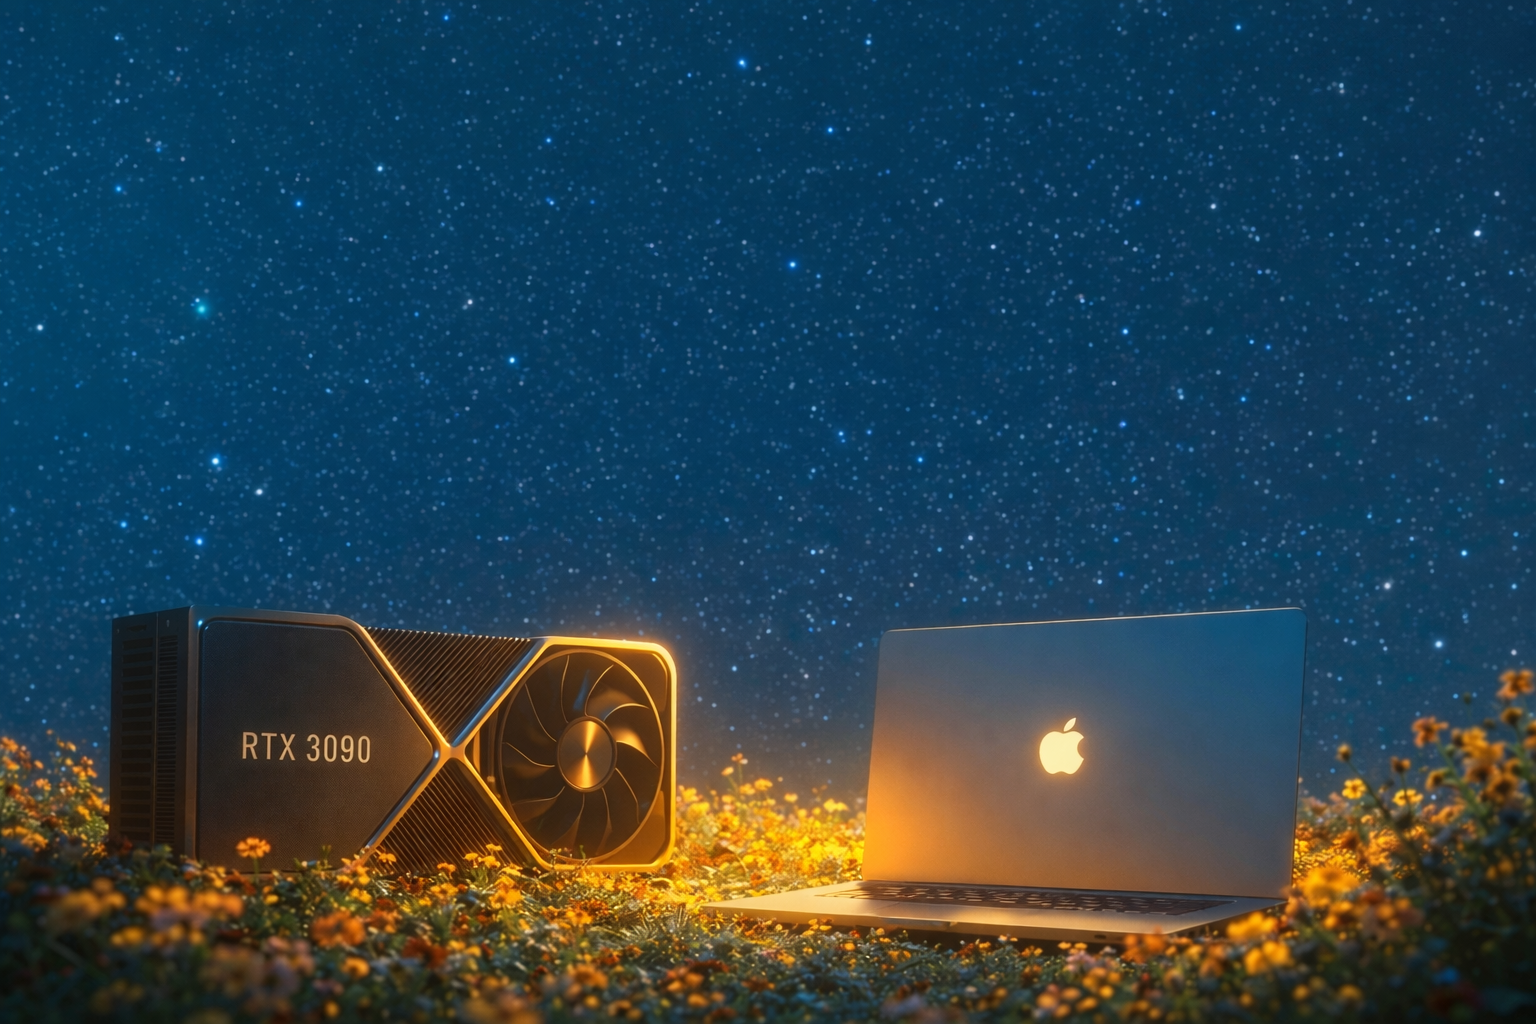
results
microcosm should run jetstreamv2, but it would push costs above current support. how do we fund this?
Signal v. Noise moves to Medium
When Jason Fried a few months ago suggested that we should start posting articles on Medium, I was skeptical. What possible gain could we have from sharing our stories on someone else’s platform ra…
Open Responses
This is the standardization effort I've most wanted in the world of LLMs: a vendor-neutral specification for the JSON API that clients can use to talk to hosted LLMs. Open …
ACMA research reveals media and communications trends | ACMA
The ACMA has released new research revealing current trends and developments in the Australian media and communications sectors.
okay hear me out I had an idea in my dreams last night for an aproto game powered by the live stream out of spacedust.microcosm.blue is this anything

