

Magic: The Gathering is Turing Complete
$\textit{Magic: The Gathering}$ is a popular and famously complicated trading card game about magical combat. In this paper we show that optimal play in real-world $\textit{Magic}$ is at least as...

Jevons Paradox: A personal perspective
What if the most game-optimal play in the new system is actually to become relentlessly, unapologetically you?
Execution in strategy games should be considered “randomness”
I have long considered execution to be basically a form of randomness, similar to dice rolls or card draws. I have also long recognized that not everyone agrees with me, and some people find the id…

Play is doing its work even if we’re not keeping score | Aeon Essays
We are most human when we play freely, imaginatively, pointlessly. Gamification risks atrophying that most precious capacity
Look-ahead Reasoning with a Learned Model in Imperfect Information Games
Test-time reasoning significantly enhances pre-trained AI agents' performance. However, it requires an explicit environment model, often unavailable or overly complex in real-world scenarios....
17. A Value for n-Person Games
17. A Value for n-Person Games was published in Contributions to the Theory of Games, Volume II on page 307.
Sᴜɴʀɪsᴇ Oᴀᴛʜ 十 Tʜᴇ Sʏʟʟᴀʙᴜꜱ (ORI) - CC0 on Twitter / X
I like using poker as an example. Even as a game-theory-optimal strategy will beat any non-optimal strategy over enough hands, the pot it lost on the first hand is not itself actually recovered. That wound still is there.— Sᴜɴʀɪsᴇ Oᴀᴛʜ 十 Tʜᴇ Sʏʟʟᴀʙᴜꜱ (ORI) - CC0 (@sunriseoath) August 6, 2026
Predicting outcomes for games of skill by redefining what it means to win
The Elo rating system is a highly successful ranking algorithm for games of skill where, by construction, one team wins and the other loses. A primary limitation of the original Elo algorithm is its inability to predict information beyond a match's win-loss probability. Specifically, the victor is awarded the same point bounty if he beats a team by 1 point or 10 points; only the rating difference between the team and its opponent affects the match bounty. In this work, we explain that Elo ratings and predictions can be naturally extended to include margin-of-victory information by simply redefining "what it means to win." We create ratings for each value of the margin-of-victory and use these ratings to predict the full distribution of point spread outcomes for matches which have not yet been played.
Feedbackmaxxing
You know the TV gameshow Play Your Cards Right? Contestants are shown a sequence – in two rows – of giant playing cards presented face-down. The host turns over the first card. The cont…

Clockwork Criteria: 6 Guidelines for Ideal Strategy Game Design
What are the criteria that make something a good “Clockwork Game”? The Clockwork Game Design model is something I have been working on for the last five years or so. It is specifically …
Starting Point
You compete with others, on an unfair playing field. Are you aware of this? Are you good at games? Starting equally Starting unequally Advantages in Games Life is Competitive Seeing Life as a Game What to keep in mind When to use this View Your Starting Point Starting equally You...

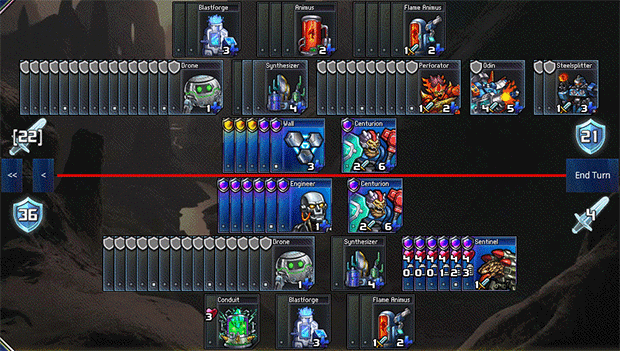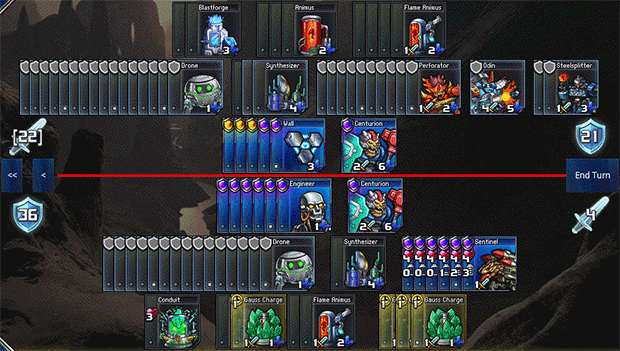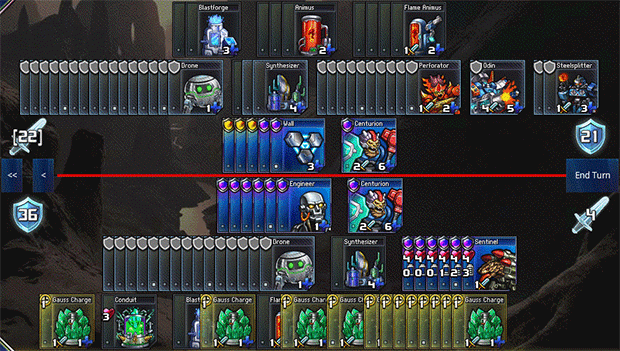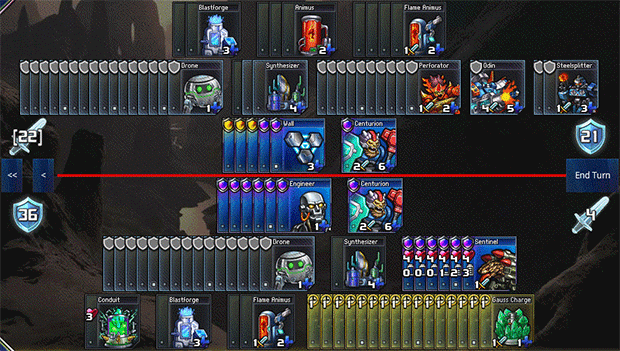
Uncapped Look-Ahead and the Information Horizon
I write a lot about how bad output randomness is for games, but today I want to write about a problem common in many deterministic games – specifically ones that lack hidden information. Why …
Axes of Victory
Here is a game design concept we’ve been talking about on the Keith Burgun Discord. I think it is useful for creating and honing the type of “strategic dance” we find in games lik…

Reward is not the optimization target — LessWrong
TurnTrout discusses a common misconception in reinforcement learning: that reward is the optimization target of trained agents. He argues reward is b…
#Exploration: A Study of Count-Based Exploration for Deep...
Count-based exploration algorithms are known to perform near-optimally when used in conjunction with tabular reinforcement learning (RL) methods for solving small discrete Markov decision...