

Why Are LLMs Smart?
A popular way to explain how current LLMs work is to say that “all” they do is predict the next most likely word in a sentence.
Dan Shipper 📧 on Twitter / X
this is true and is a big reason why you don’t need to be a highly technical researcher to use LLMs in surprising and novel ways https://t.co/TuxNzXzToU— Dan Shipper 📧 (@danshipper) July 27, 2025
LLM APIs are a Synchronization Problem
Maybe the LLM message APIs should be rethought as a synchronization problem.
The LLM Critics Are Right. I Use LLMs Anyway.
I almost agree with all of the LLM critics, yet I still use LLMs a lot. I know this sounds like I am delusional, but I don't think I am alone with it.
The LLM Critics Are Right. I Use LLMs Anyway.
I almost agree with all of the LLM critics, yet I still use LLMs a lot. I know this sounds like I am delusional, but I don't think I am alone with it.
There's Something Fundamentally Wrong With LLMs
LLMs aren't trained on the "vast majority of speech," experts warn, a major blind spot that could have sweeping consequences.
Is the LLM response wrong, or have you just failed to iterate it?
Many "errors" in search-assisted LLMs are not errors at all, but the result of an investigation aborted too soon. Here's how to up your LLM-based verification game by going to round two.
The two worlds of programming: why developers who make the same observations about LLMs come to opposite conclusions
Writing at the end of the world, from Hveragerði, Iceland
LLMs are good at playing you
Large language models seem just like humans, but some of this is in our heads.
Isn't the fundamental problem that LLM's don't actually understand anything (as ... | Hacker News
My 2 month active experience with ChatGPT-4 gave me the following takeaways:
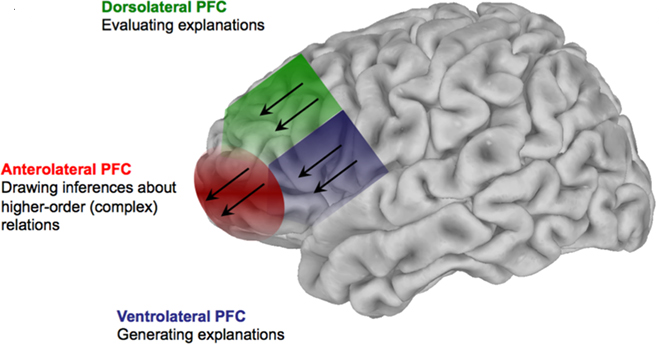
How LLMs are and are not like the brain
Hi from buttondown! At the bottom of this newsletter is a bit of administrivia about the new platform How LLMs are and are not like the brain Beneath all the...
LLM is a learned distribution p on sequences of tokens. If you just sample a bunch of text from p willy nilly and put it in the training data and train you just get back p. But if you sample a bunch of text from p and throw out whatever's bad and train on what's left then you learn p(x|x is not bad)

