

An update on the scheduled Colibri release for July 25.
GPU Support [Open Beta] - Polars user guide
Polars provides an in-memory, GPU-accelerated execution engine for Python users of the Lazy API on NVIDIA GPUs using RAPIDS cuDF. This functionality is available in Open Beta and is undergoing rapid development.
Introducing CUDA Rust: Two Tracks for Writing GPU Kernels | NVIDIA Technical Blog
In September 2026, NVIDIA announced it is leaning into native GPU programming in Rust. CUDA C++ and CUDA Python are mature, enterprise-grade toolchains, and NVIDIA will be growing and maturing CUDA…

WebGPU is now supported in major browsers | Blog | web.dev
Read about the biggest web graphics launch since WebGL. WebGPU is supported across major browsers, bringing unparalleled performance to the web.
Where AI Startups Scale to Production
Discover the most efficient way to build, tune and run your AI models and applications on top-notch NVIDIA® GPUs.

Shipping WebGPU on Windows in Firefox 141
After years in development, we will be releasing WebGPU on Windows in Firefox 141! WebGPU gives web content a modern interface to the user’s graphics processor, enabling high-performance comp…
Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026
NVIDIA CEO Jensen Huang GTC 2026 Full Keynote
Iwo Plaza – Your GPU is a JavaScript runtime* (TypeGPU deep-dive)
the tiny corp on Twitter / X
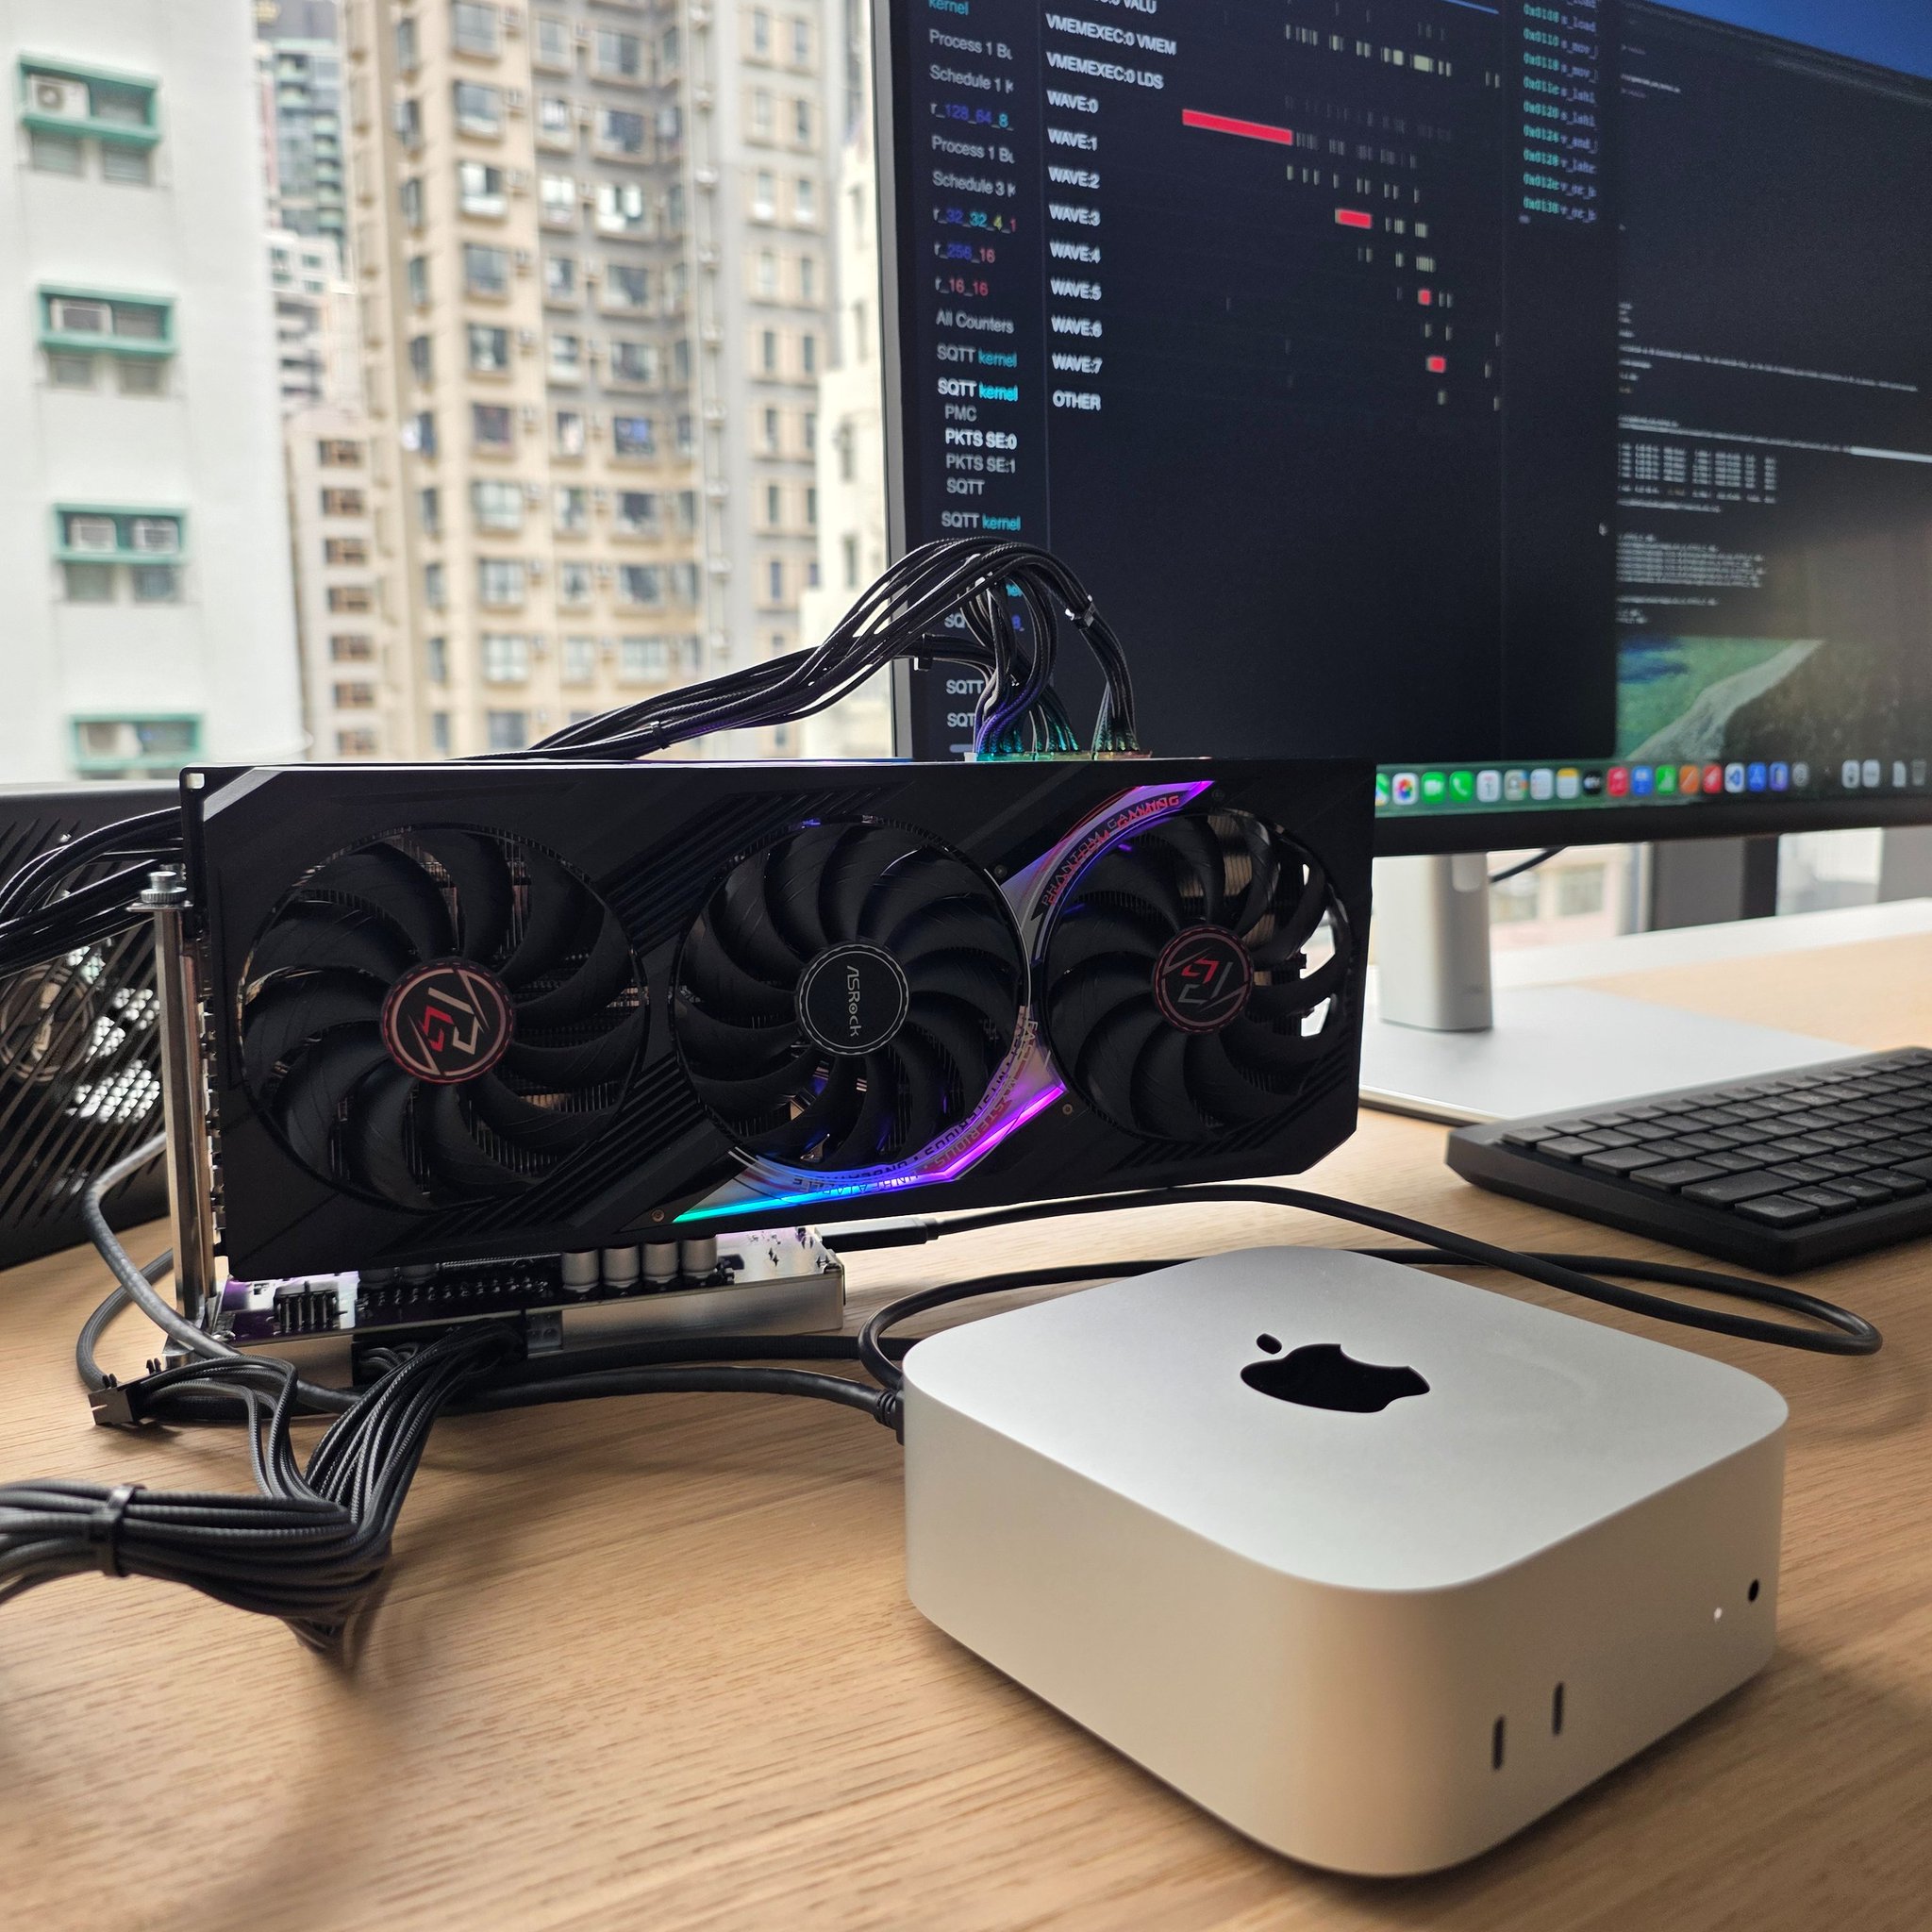
If you have a Thunderbolt or USB4 eGPU and a Mac, today is the day you've been waiting for! Apple finally approved our driver for both AMD and NVIDIA. It's so easy to install now a Qwen could do it, then it can run that Qwen... pic.twitter.com/daUsyBHh1W— the tiny corp (@__tinygrad__) April 1, 2026
AI GPUs probably live longer than three years
People who think current AI use is unsustainable often rely on the claim that inference GPUs only last “three years at the most” under load1. The idea here is that once the AI bubble money drains away, current infrastructure will rapidly become obsolete, and there won’t be enough money floating around to buy a whole slate of brand-new GPUs. Inference costs would thus rapidly become way too expensive for current AI products to make any financial sense.
HipScript: Run HIP and CUDA code with WebGPU
Online compiler for HIP and NVIDIA® CUDA® code to WebGPU
NVIDIA DGX Spark· Ollama Blog
The latest NVIDIA DGX Spark is here! Ollama has partnered with NVIDIA to ensure it runs fast and efficiently out-of-the-box.
TypeGPU – Type-safe WebGPU toolkit
Discover how it can change the way you work with GPU rendering and computing.
Tiles version 0.4.18 Alpha 22 has been released. Tiles now supports the Vulkan backend, enabling GPU acceleration beyond NVIDIA across vendors on Linux, with fixes for MTP speculative decoding, Linux tool calls, and an occasional OAuth callback failure during ATproto login. Release notes ↗

Shared chat session by @tiles.run | Tiles
chat.tiles.run