

Automated exploitation of command and code injection flaws, from detection to full control of the underlying operating system.
Frida • A world-class dynamic instrumentation toolkit
Observe and reprogram running programs on Windows, macOS, GNU/Linux, iOS, watchOS, tvOS, Android, FreeBSD, and QNX
Composio
Just-in-time tool calls, secure delegated auth, sandboxed environments, and parallel execution across 1,000+ apps.
Using Claude to reduce the attack surface of code
Automated attack surface analysis and reduction can meaningfully improve the security of deployed software in the near term. In this post, we preview data we’ve collected from applying attack surface reduction techniques to large open-source codebases using Claude.

39C3 - Agentic ProbLLMs: Exploiting AI Computer-Use and Coding Agents
Relyze - Interactive x86, x64, ARM32 and ARM64 software reverse engineering
Relyze lets you disassemble, decompile and binary diff native code software.
[oss-security] Fwd: Protecting against CVE-2026-98432 when using Go programs [LWN.net]
System prompt injection — CodeQL query help documentation
If user-controlled data is included in a system prompt or the description of tools for an agentic system, an attacker can manipulate the instructions that govern the AI model’s behavior, bypassing intended restrictions and potentially causing sensitive data leaks or unintended operations.
GTFOBins
GTFOBins is a curated list of Unix-like executables that can be used to bypass local security restrictions in misconfigured systems.
Advanced macOS Commands - saurabhs.org
A comprehensive reference for advanced command-line utilities that provide unique macOS functionality.
oss-security - Dirty Frag: Universal Linux LPE
Please check out the Open Source Software Security Wiki, which is counterpart to this mailing list.
OpenFang — The Agent Operating System
Open-source Agent OS built in Rust. 7 autonomous Hands. 16 security layers. 40 channels. 27 providers. Single binary. Battle-tested.
Xous: A Pure-Rust Rethink of the Embedded Operating System
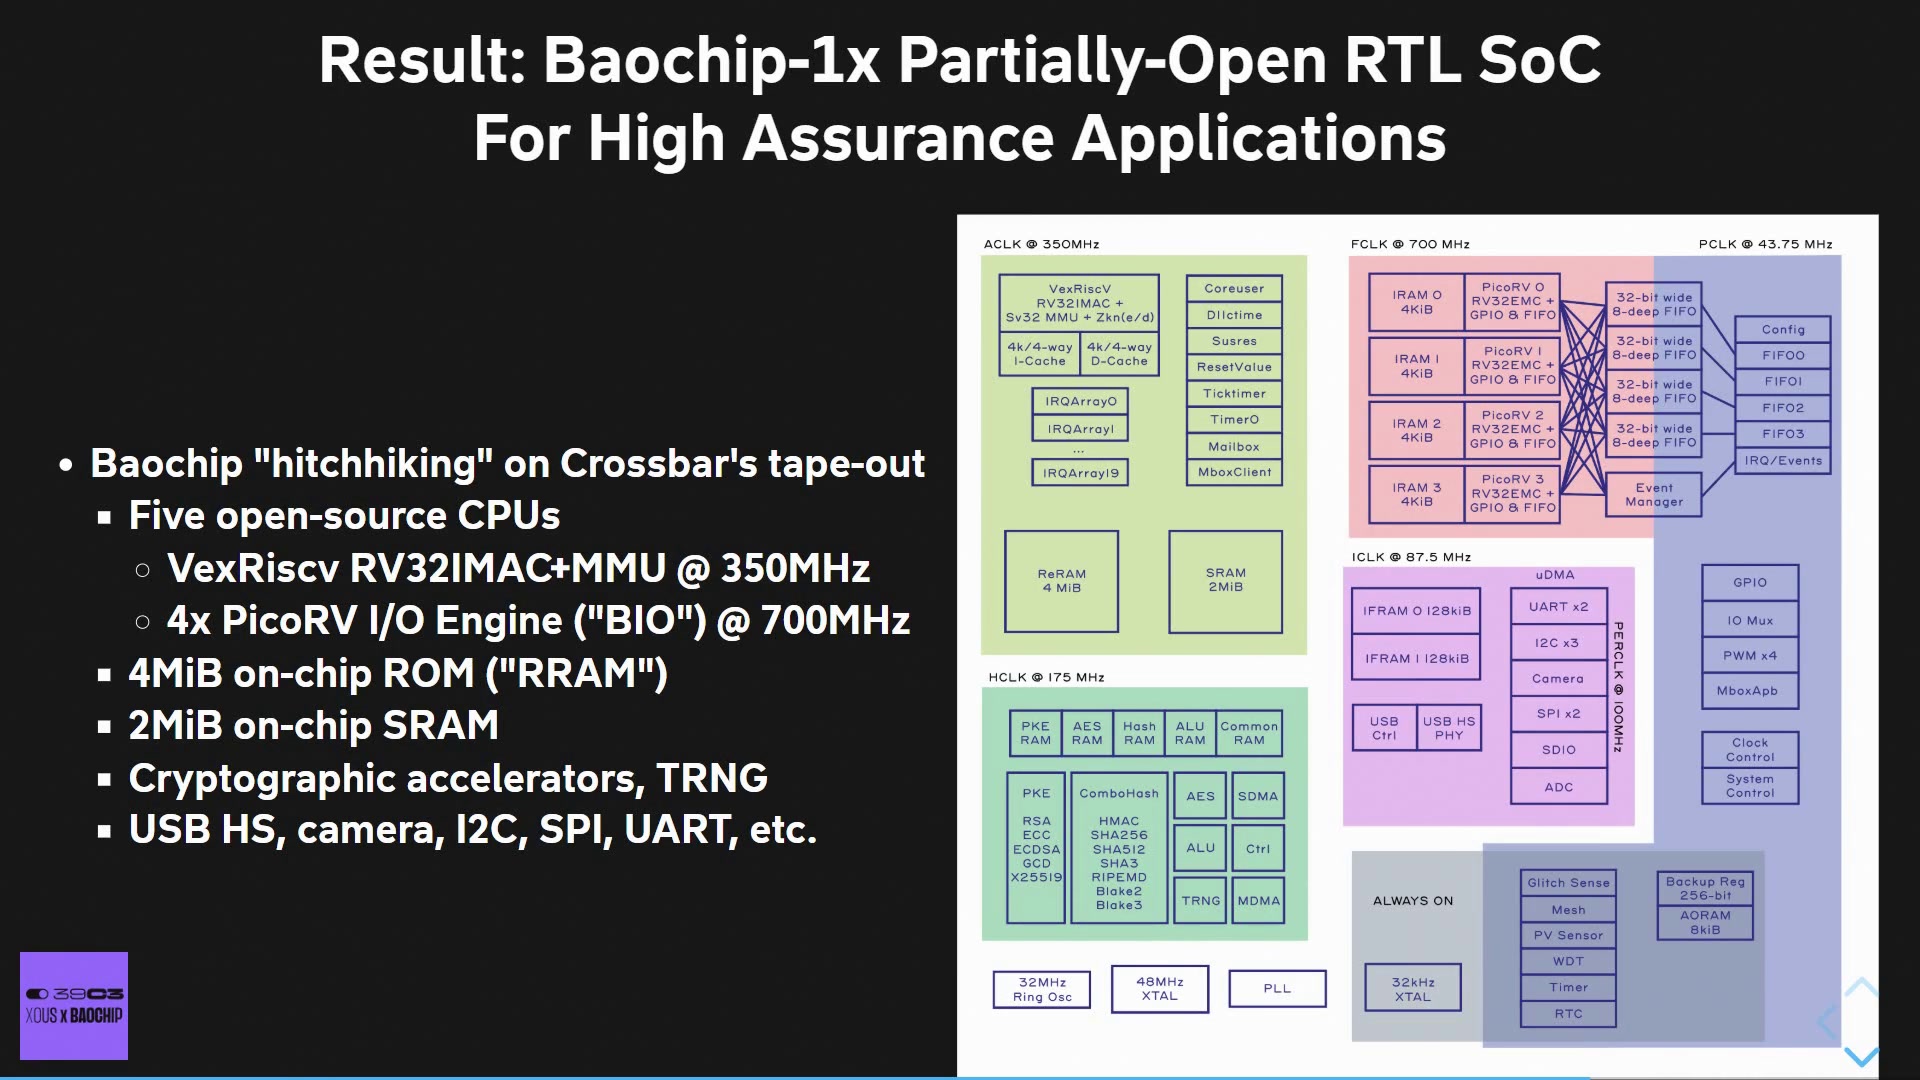
Xous is a message-passing microkernel implemented in pure Rust, targeting secure embedded applications. This talk covers three novel aspe...
DOS
DOS is designed to only run one program at a time with minimal external dependencies. It is thus quite immune to many problems of more modern OSes, such as software rot. It may well be used as a bedrock platform or as a "bare-bones" system that may work for basic tasks even when everything else fails. The main compatibility issue in DOS is that a lot of hardware is commonly used by "banging the bare metal", which makes e.g. old sound applications incompatible with modern hardware.
Toit — scripts and embedded applications
A readable programming language for scripts, command-line tools, and ESP32 applications. Free, open source, and maintained by volunteers.
ExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks?
AI agents are rapidly gaining capabilities that could significantly reshape cybersecurity, making rigorous evaluation urgent. A critical capability is exploitation: turning a vulnerability, which is not yet an attack, into a concrete security impact, such as unauthorized file access or code execution. Exploitation is a particularly challenging task because it requires low-level program reasoning (e.g., about memory layout), runtime adaptation, and sustained progress over long horizons. Meanwhile, it is inherently dual-use, supporting defensive workflows while lowering the barrier for offense. Despite its importance and diagnostic value, exploitation remains under-evaluated. To address this gap, we introduce ExploitGym, a large-scale, diverse, realistic benchmark on the exploitation capabilities of AI agents. Given a program input that triggers a vulnerability, ExploitGym tasks agents with progressively extending it into a working exploit. The benchmark comprises 898 instances sourced from real-world vulnerabilities across three domains, including userspace programs, Google's V8 JavaScript engine, and the Linux kernel. We vary the security protections applied to each instance, isolating their impact on agent performance. All configurations are packaged in reproducible containerized environments. Our evaluation shows that while exploitation remains challenging, frontier models can successfully exploit a non-trivial fraction of vulnerabilities. For example, the strongest configurations are Anthropic's latest model Claude Mythos Preview and OpenAI's GPT-5.5, which produce working exploits for 157 and 120 instances, respectively. Notably, even with widely used defenses enabled, models retain non-trivial success rates. These results establish ExploitGym as an effective testbed for exploitation and highlight the growing cybersecurity risks posed by increasingly capable AI agents.

ExploitGym: Can AI Agents Turn Security Vulnerabilities into Real Attacks?
AI agents are rapidly gaining capabilities that could significantly reshape cybersecurity, making rigorous evaluation urgent. A critical capability is exploitation: turning a vulnerability, which is not yet an attack, into a concrete security impact, such as unauthorized file access or code execution. Exploitation is a particularly challenging task because it requires low-level program reasoning (e.g., about memory layout), runtime adaptation, and sustained progress over long horizons. Meanwhile, it is inherently dual-use, supporting defensive workflows while lowering the barrier for offense. Despite its importance and diagnostic value, exploitation remains under-evaluated. To address this gap, we introduce ExploitGym, a large-scale, diverse, realistic benchmark on the exploitation capabilities of AI agents. Given a program input that triggers a vulnerability, ExploitGym tasks agents with progressively extending it into a working exploit. The benchmark comprises 898 instances sourced from real-world vulnerabilities across three domains, including userspace programs, Google's V8 JavaScript engine, and the Linux kernel. We vary the security protections applied to each instance, isolating their impact on agent performance. All configurations are packaged in reproducible containerized environments. Our evaluation shows that while exploitation remains challenging, frontier models can successfully exploit a non-trivial fraction of vulnerabilities. For example, the strongest configurations are Anthropic's latest model Claude Mythos Preview and OpenAI's GPT-5.5, which produce working exploits for 157 and 120 instances, respectively. Notably, even with widely used defenses enabled, models retain non-trivial success rates. These results establish ExploitGym as an effective testbed for exploitation and highlight the growing cybersecurity risks posed by increasingly capable AI agents.