

Ready to make it official? Here you’ll find guides, samples and examples to make the process a bit easier.
The Comprehensive Digital Preservation Platform
Create, curate, and collaborate on living archives. Start with a FREE GB.
Building great open source documentation

IIPC WAC 2024 Presentation: A Conceptual Model of Decentralized Storage for Community-Based Archives
Archiving web sites
I recently took a deep dive into web site archival for friends who were worried about losing co [...]
Rethinking Digital Storage for Community-Based Archives
Over the last few decades, the standard procedure for storing and backing up data has been ‘put it in the cloud.’ Many of us use cloud…

Publishing with GitHub Pages, now as easy as 1, 2, 3
Publishing a website or software documentation with GitHub Pages now requires far fewer steps — three to be exact: Create a repository (or navigate to an existing repository) Commit a Markdown…
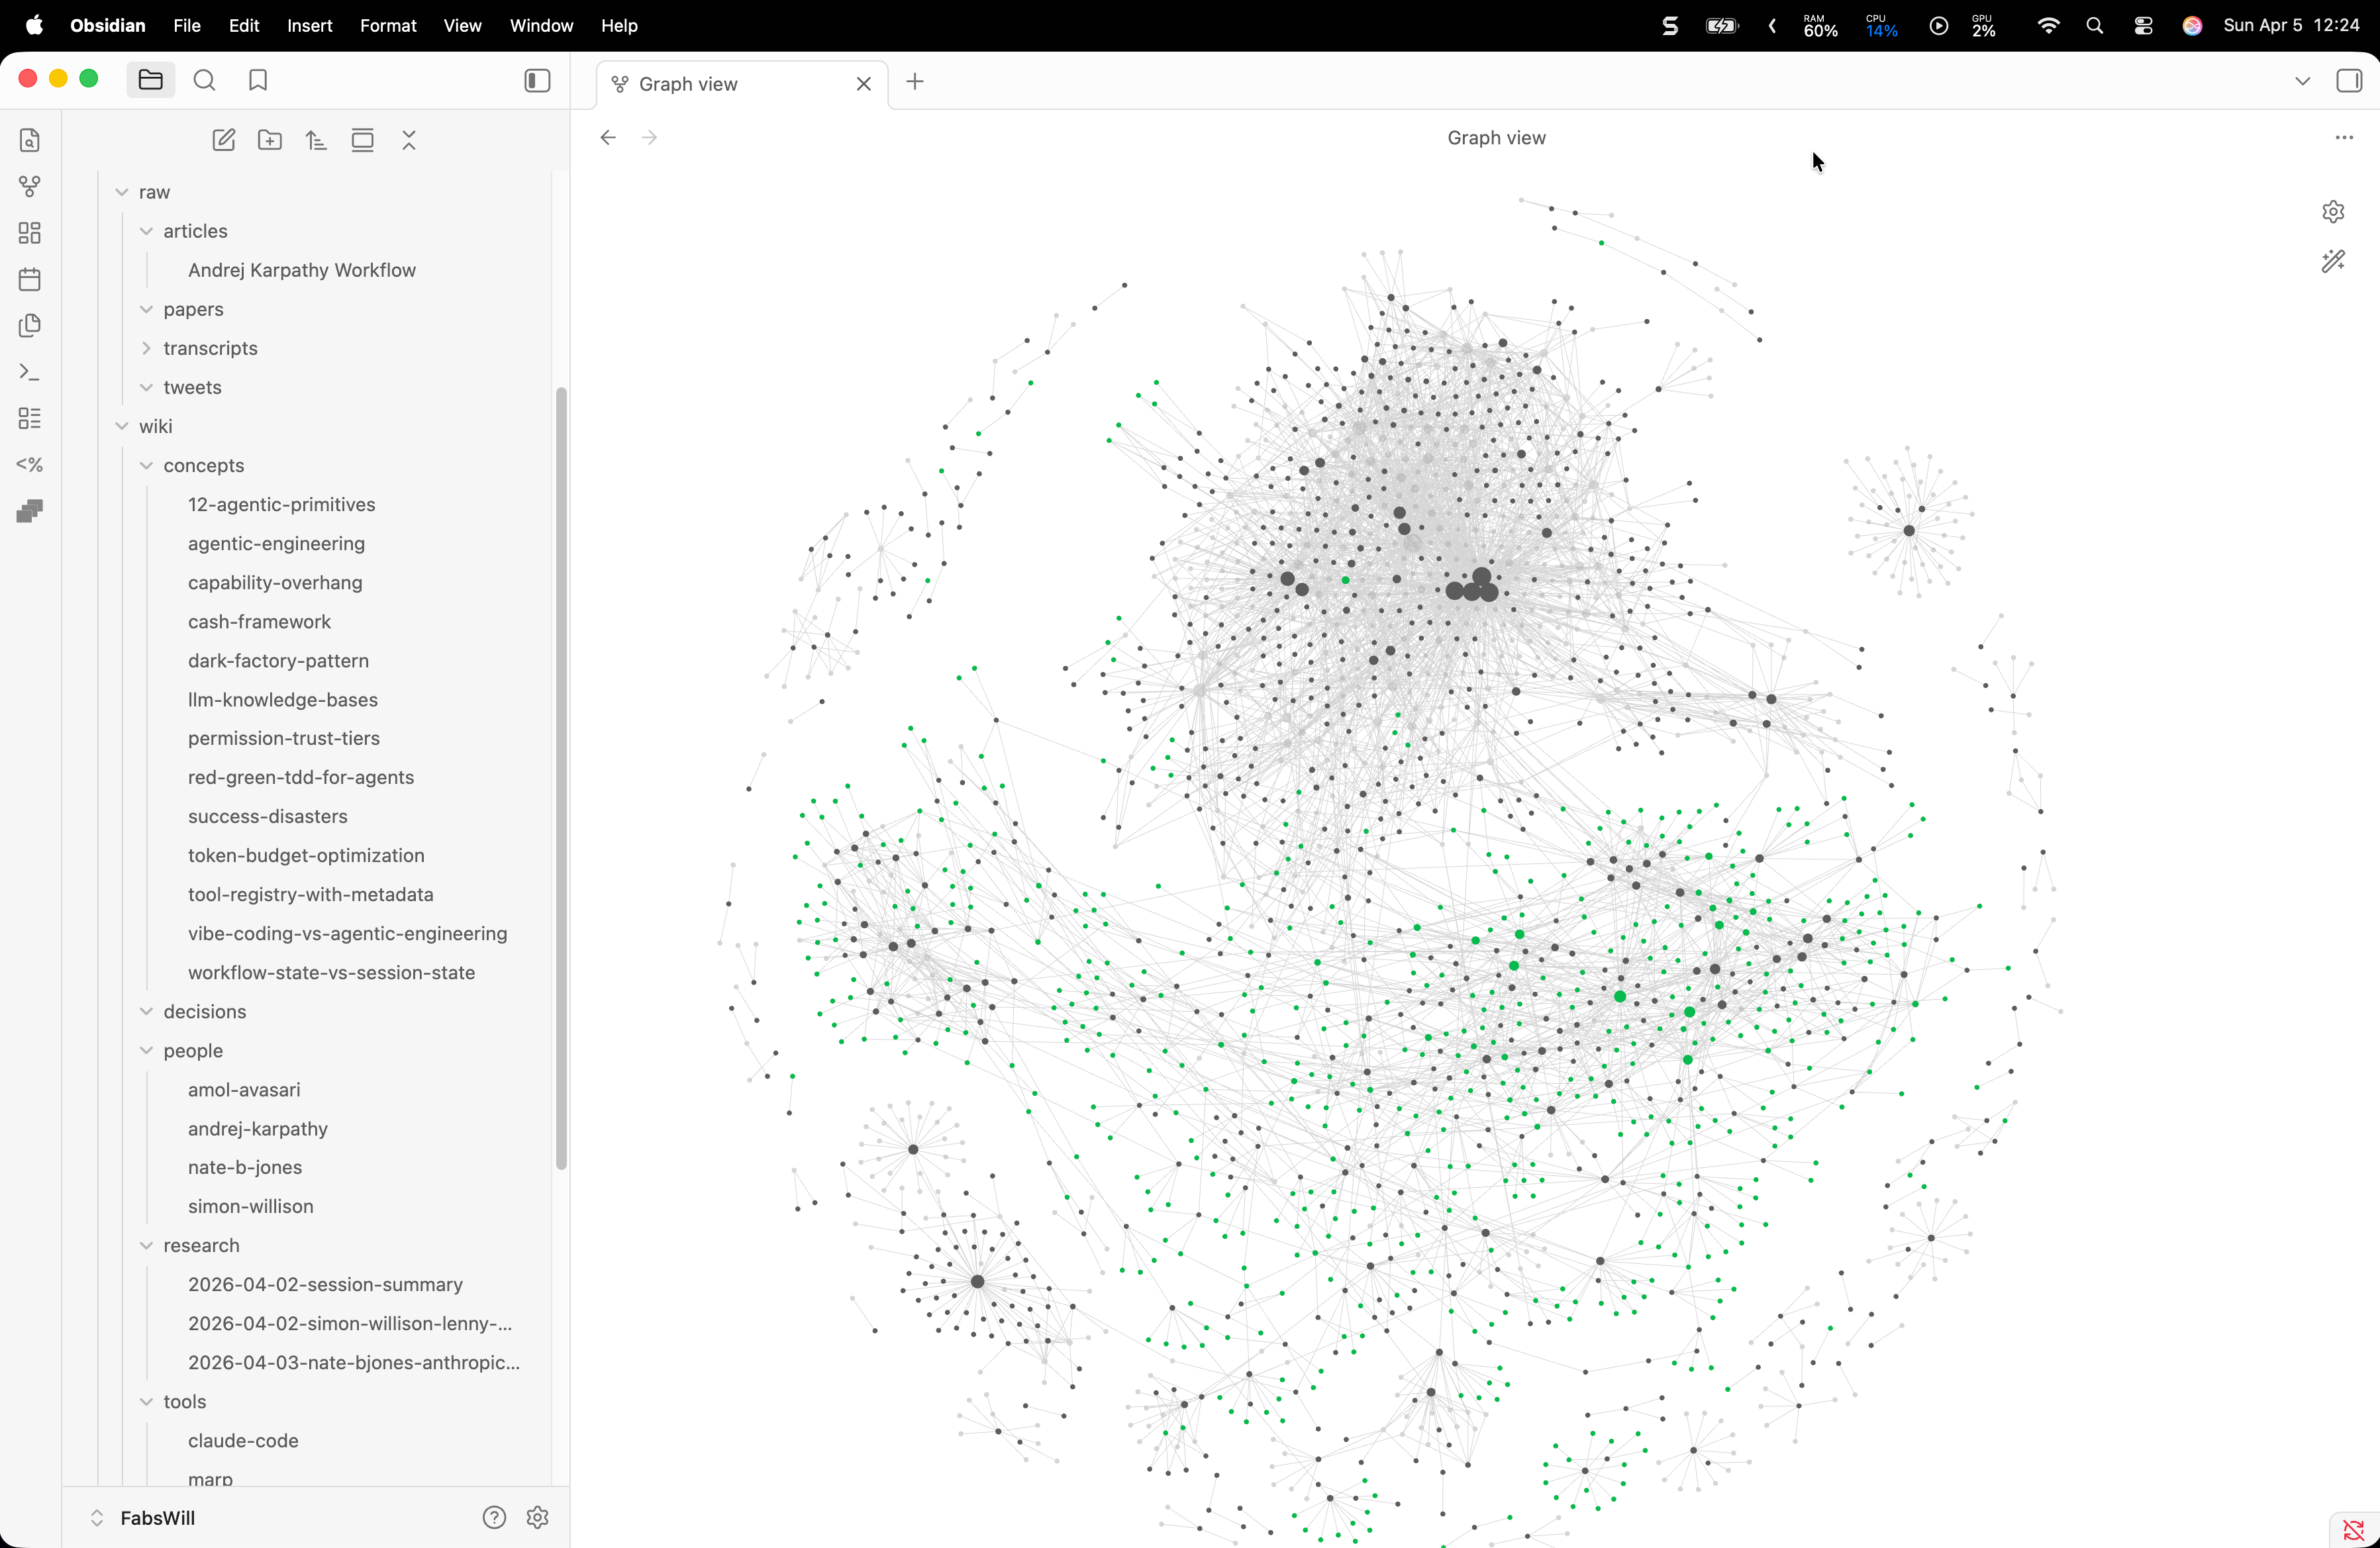
I Built a Knowledge Base That Writes Itself. Here Is What Andrej Karpathy Got Right.
Andrej Karpathy posted about using LLMs to build personal knowledge bases. I took his workflow, wired it into my Obsidian vault with Claude Code, and within an hour had 21 cross-linked wiki articles compiled from YouTube transcripts. Here is how it works and why it matters.
Data‐ and code‐archiving in the British Ecological Society journals: Present status and recommendations for future improvements
Abstract Data‐ and code‐archiving are important components of open science, as both make research more transparent, reproducible, accountable and credible, allowing future researchers to build on previous work. Despite progress in implementing data‐ and code‐archiving policies in journals publishing ecology and evolution research, issues remain. To be more useful to future researchers, archived data and code must not only be archived but also meet good practice standards. We collected data from 1861 papers published between 2017 and 2024 in the seven British Ecological Society (BES) journals, during a hackathon event. We systematically checked associated data and/or code, metadata, help files and annotations to assess archiving practices. We determined if and where data and code files were archived, whether they could be located, downloaded and opened, and whether they had associated READMEs, digital object identifiers (DOI) and licences. We also recorded the file extensions used to save data/code files, and which programming languages code was written in. 93% of the 1861 papers we examined used data and ~90% used code. While 97% of the 1735 papers that used data also archived it, only 35% of the 1670 papers that used code also archived code. Over 85% of archived data and code could be located, downloaded and opened. Reusability, however, was more limited; around a third of papers did not have a README or similar to explain their data/code files, and the quality of READMEs varied substantially. We recommend that researchers archive their code and that archived code be explicitly mentioned in the Data (or Code) Availability statement. We also encourage researchers to provide more accessible and informative READMEs for data and code. To help achieve these recommendations, we advocate that journals employ Data/Code editors to review data and code quality, research institutions deliver more training in open science practices, and funding bodies set clear expectations on open data and code practices.

Sez Where? — Ask questions about your documents
Ask a question about your document and find the relevant passages. Paste text or upload a PDF, Word document, text file, or Markdown.
Publishing My Eleventy Blog to the ATmosphere with Standard.site
A walkthrough of how I wired up Standard.site AT Protocol lexicons into this 11ty blog: from writing a custom publish script to migrating to Sequoia, with code for the link tags, and handle verification.
Introducing Aris: The publishing platform for the Post-PDF Era - Aris
We're building the future of academic publishing: tools that make it easy to create, share, and preserve knowledge in formats designed for the web, not the printing press.
What's new? - Sri's leaflets
Launching at.new - a new way to create atproto records and share drafts
Universal Version Control
Building tools to help people explore alternatives, keep track of history, and collaborate better, across all kinds of media.
RFCs on the Atmosphere
I was recently working on an RFC for some open source work and didn't have a good place to post it. Google Docs is annoying for anything technical and a git repo is heavy if you don't already have one set up and a process ready to go.
Back into blogging and just published something I've been thinking about for a while now – making archival content more resilient and discoverable on atproto. Oral history, interactive transcripts, content addressing, and keeping important stories from being quietly erased. maboa.it/resilient-archives-on-the-at-…

Keeping Archives Alive: Resilience and Discovery on ATProto
maboa.itNot quite the same but I made a little go cli that turns a list of standard.site documents into an epub making that cover with svgo was the hardest part

Anuj Ahooja
Where do I send the invoice?

