

Although managing data in relational databases has plenty of benefits, they’re rarely used in day-to-day work with small to medium scale datasets. But why is that? Why do we see an awful lot of data stored in static files in CSV or JSON format, even though they are hard to query and update incrementally?
BigQuery public datasets | Google Cloud Documentation
A public dataset is any dataset that is stored in BigQuery and made available to the general public through the Google Cloud Public Dataset Program. The public datasets are datasets that BigQuery hosts for you to access and integrate into your applications. Google pays for the storage of these datasets and provides public access to the data using a project. You pay only for the queries that you perform on the data. The first 1 TB per month is free, subject to query pricing details.

Datasheets for Datasets
The machine learning community currently has no standardized process for documenting datasets, which can lead to severe consequences in high-stakes domains. To address this gap, we propose...

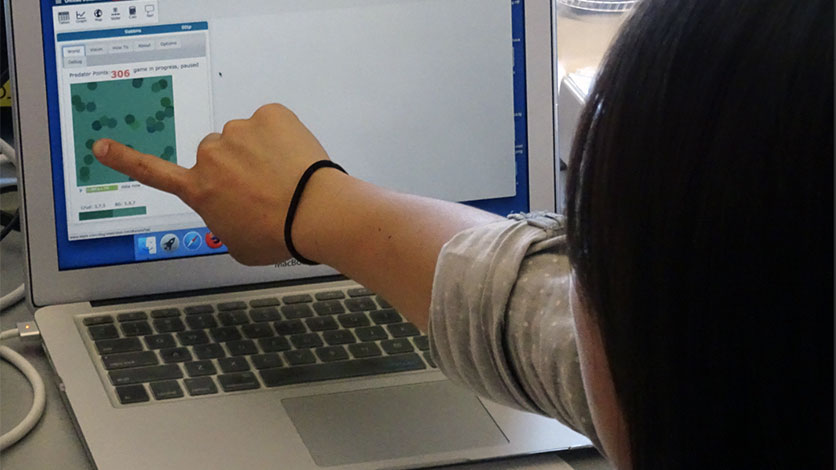
Dynamic Data Science
<p>Use our Common Online Data Analysis Platform (CODAP) to explore dynamic data science activities and gain fluency in data moves to examine large datasets.</p>
Data Supply Chains
Data is a critical resource. Like oil, gold, or lithium, both companies and countries covet data. Ultimately, like oil, data’s flow can enrich those that posses

Doing Data Science on the Shoulders of Giants: The Value of Open Source Software for the Data Science Community · Issue 2.2, Spring 2020
Open source software is ubiquitous throughout data science, and enables the work of nearly every data scientist in some way or another. Open source projects, however, are disproportionately maintained by a small number of individuals, some of whom are institutionally supported, but many of whom do this maintenance on a purely volunteer basis. The health of the data science ecosystem depends on the support of open source projects, on an individual and institutional level.

datasetpapers — a public research experiment
An experimental approach to versioned, forkable, machine-readable analyses. A prototype, not a product or service.
datasetpapers — a public research experiment
An experimental approach to versioned, forkable, machine-readable analyses. A prototype, not a product or service.
Datasette
Datasette is a tool for exploring and publishing data. It helps people take data of any shape, analyze and explore it, and publish it as an interactive website and accompanying API.
Democratizing Data
Democratizing Data builds a community-driven data ecosystem by identifying how datasets are used and reducing barriers to accessing high-quality public data. The initiative enhances the discoverability, usability, and relevance of data for researchers, policymakers, and stakeholder communities. A suite of tools and strategic partnerships supports this work by connecting users to the data, insights, and networks needed to inform decisions and generate impact.
Parquet
Apache Parquet Documentation Releases Apache Parquet is an open source, column-oriented data file format designed for efficient data storage and retrieval. It provides high performance compression and encoding schemes to handle complex data in bulk and is supported in many programming languages and analytics tools.
Columnar Storage is Normalization
Something I didn't understand for a while is that the process of turning row-oriented data into column-oriented data isn't a totally bespoke, foreign concept...

Dremel: interactive analysis of web-scale datasets: Proceedings of the VLDB Endowment: Vol 3, No 1-2
Dremel is a scalable, interactive ad-hoc query system for analysis of read-only nested data. By combining multi-level execution trees and columnar data layout, it is capable of running aggregation queries over trillion-row tables in seconds. The system ...

Why Are Geospatial Databases So Hard To Build? · J. Andrew Rogers
In 2005, I decided to design my first geospatial database engine. PostGIS was unable to keep up with the modest volumes of sensor data I was working with and while I was new to geospatial data, I had skill designing database engines. It seemed simple enough to get the scale and performance I required. Nothing could have been further from the truth and the reasons were rarely obvious.
Linked Data is a Political Agenda
This approach to a data commons could extend to so many typically shared things. For businesses to easily and authoritatively publish things like open hours or product catalogs, discographies, every kind of -ography... creative appmakers could do so much with all that

JB Hutch
Testing an idea that I've had for a while, but I think is even better suited for atproto Internet, meet plts.at
