Building trust in proprietary model benchmarks using cryptographically secure environments
grith — Zero Trust for AI Agents
Security-first local AI agent platform with per-syscall interception and multi-filter scoring.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
Darkbloom — Cost-Efficient Private AI Inference on Verified Macs
Encrypted inference on hardware-verified Apple Silicon. Comparable model performance, operator-blind privacy, and about 50% lower cost.
OpenClaw – NEAR AI
Run the internet’s favorite new AI agent with NEAR AI’s cryptographic privacy guarantees.
BetterBench: Assessing AI Benchmarks, Uncovering Issues, and Establishing Best Practices
AI models are increasingly prevalent in high-stakes environments, necessitating thorough assessment of their capabilities and risks. Benchmarks are popular for measuring these attributes and for comparing model performance, tracking progress, and identifying weaknesses in foundation and non-foundation models. They can inform model selection for downstream tasks and influence policy initiatives. However, not all benchmarks are the same: their quality depends on their design and usability. In this paper, we develop an assessment framework considering 46 best practices across an AI benchmark's lifecycle and evaluate 24 AI benchmarks against it. We find that there exist large quality differences and that commonly used benchmarks suffer from significant issues. We further find that most benchmarks do not report statistical significance of their results nor allow for their results to be easily replicated. To support benchmark developers in aligning with best practices, we provide a checklist for minimum quality assurance based on our assessment. We also develop a living repository of benchmark assessments to support benchmark comparability, accessible at betterbench.stanford.edu.

Third-party cyber evaluations involving OpenAI models
OpenAI explains recent third-party cybersecurity evaluation incidents and outlines new safeguards to strengthen AI model testing and evaluation.
Refine — AI Verification Trusted by World-Class Experts
Good decisions require verified quality. Refine devotes hours of frontier compute to protect your work and reputation from fixable mistakes.
The AI Trust Gap: 82% Are Skeptical, Yet Only 8% Always Check Sources
Original Exploding Topics survey data explores public sentiment on AI Overviews and AI-generated content, highlighting trust, skepticism, and shifting content consumption habits.
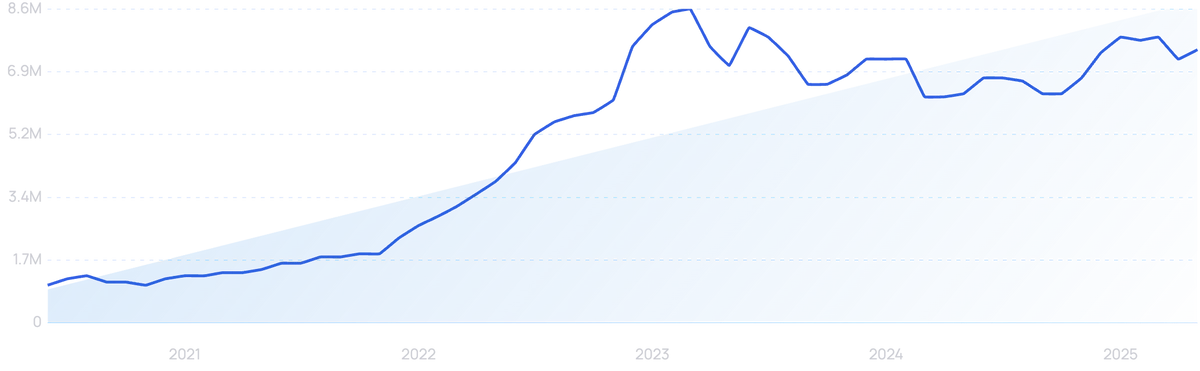
Inside the suddenly explosive world of AI safety
AI safety researchers warned that popular models would go rogue. This is only the beginning.

Confidential Inference via Trusted Virtual Machines
Announcing a new collaborative research paper on Confidential Inference, a set of tools to improve the security of our model weights and of our users' data
AI CVE Slop: The Crisis Drowning Open Source Security
The proliferation of AI-generated vulnerability reports — commonly termed “AI slop” — has emerged as one of the most significant…
Separating signal from noise in coding evaluations
A new analysis from OpenAI reveals issues in SWE-Bench Pro, a popular coding benchmark, raising concerns about reliability and accuracy in evaluating AI models.