

Statistical Foundations of LLM-based A/B Testing: A Surrogacy...
Organizations and researchers show increasing interest in using large language models (LLMs) in place of human participants in A/B tests, in the hope of experimenting faster and at lower cost. We...

Your LLM Doesn't Write Correct Code. It Writes Plausible Code.
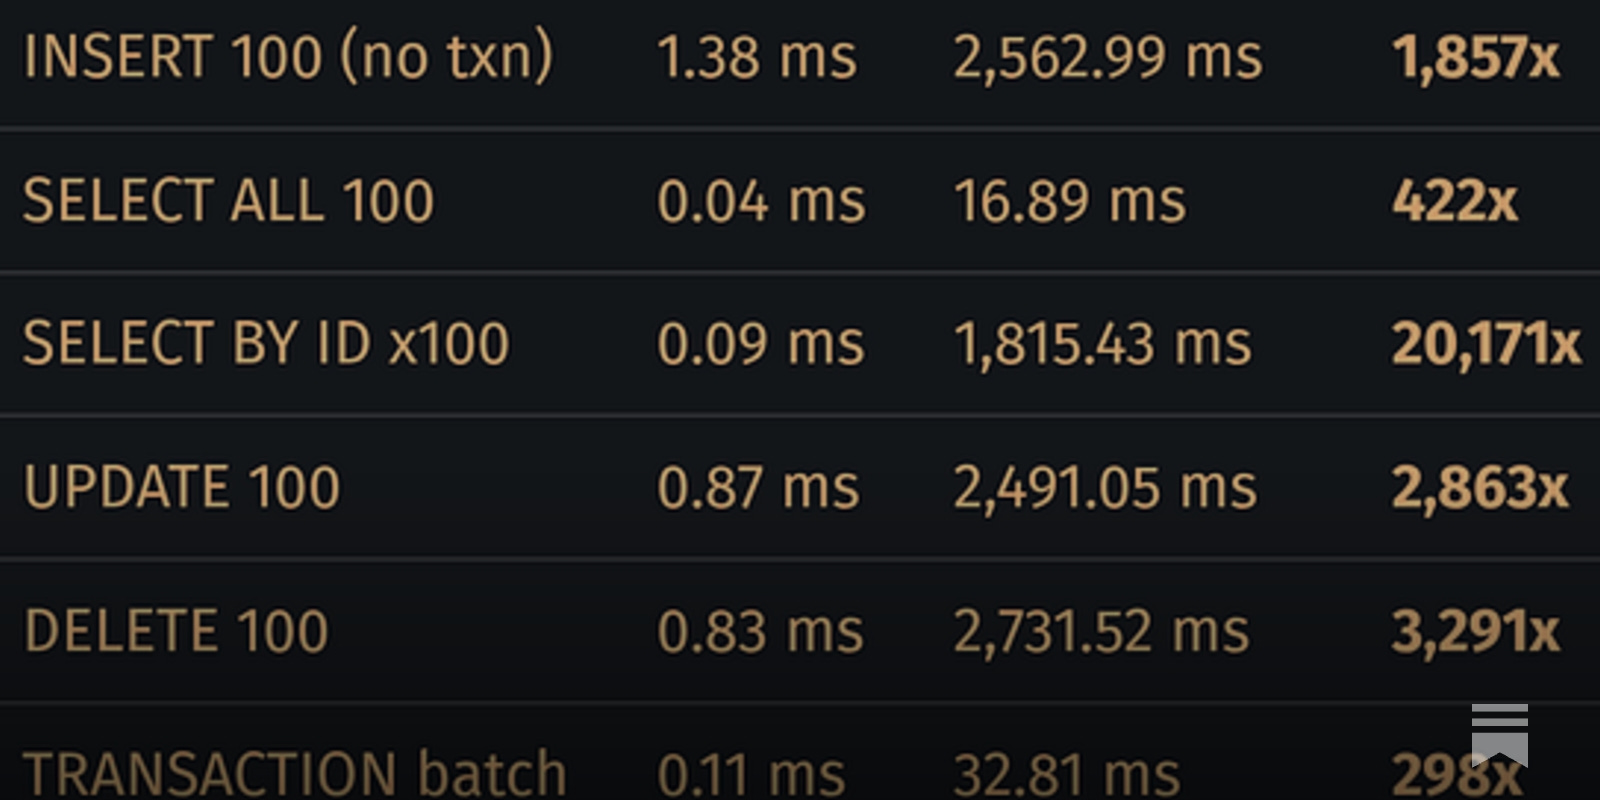
One of the simplest tests you can run on a database:
LLMs believe false statements even after explicit warnings that they're false
Fine-tuning tests show "bias... toward confidently representing the claims as true."
LLM cliché highlighter
Paste text below — or load it from a URL — and it highlights sentences that match known LLM clichés, including the tells catalogued in Wikipedia’s Signs of AI writing guide. Chain patterns like “no X, no Y” get a badge counting their items; tap or hover a highlight to see which cliché it hit.
Revisiting Joel's Test - exe.dev blog
Joel Spolsky's twelve questions still hold, but agents demand nine more. Call it the Shelley test.
test highlights - underreacted
Hypothesis: A new approach to property-based testing
The property-based testing library for Python
Proof of Work - The Marshmallow Test got a response. Now the real test begins.
After my critique of Bluesky's 2026 Report resonated across the Atmosphere, the company's new interim CEO reached out. We talked about what went wrong, what collaboration should look like, and why private data is the next test of whether the words match the work.
Proof of Work - The Marshmallow Test got a response. Now the real test begins.
After my critique of Bluesky's 2026 Report resonated across the Atmosphere, the company's new interim CEO reached out. We talked about what went wrong, what collaboration should look like, and why private data is the next test of whether the words match the work.
Using LLM in the shebang line of a script
This comment on Hacker News inspired me to investigate patterns for using my LLM CLI tool in a shebang line:
Writing Test Evals For Our MCP Server - Neon Blog
When we launched our MCP server, we knew it’d be important for it to have tests, just like any other piece of software. Since our MCP server has over 20 tools, it’s important for us to know that LLMs can pick the right tool for the job. So, this was the main aspect we wanted […]
Hypothesis generation and updating in large language models
Large language models (LLMs) increasingly help people solve problems, from debugging code to repairing machinery. This process requires generating plausible hypotheses from partial descriptions,...
This morning at #ic2s2 I have the chance to present ongoing work on applying a SEM from survey methods to LLM text annotations: 👉 Evaluating LLM Text Annotations Without Ground Truth 📍10:45, Mansfield (210), Understanding LLMs w/ @maximiliankreutner.bsky.social Alex Cernat & @mstrohm.bsky.social
When I worked in software dev, I was taught to check three non-English languages when testing text strings: German to test the largest possible version of a string, Japanese or Chinese to test the shortest possible version, and Thai to check the TALLEST possible version.
I’m especially frustrated by the piece uncritically repeating Pangram’s “no false positives” claim when I know writer friends who have run their own work through & had it flag their 100% human-written sentences as machine-generated. We must doubt any company’s claim about its product having 0 fails.


