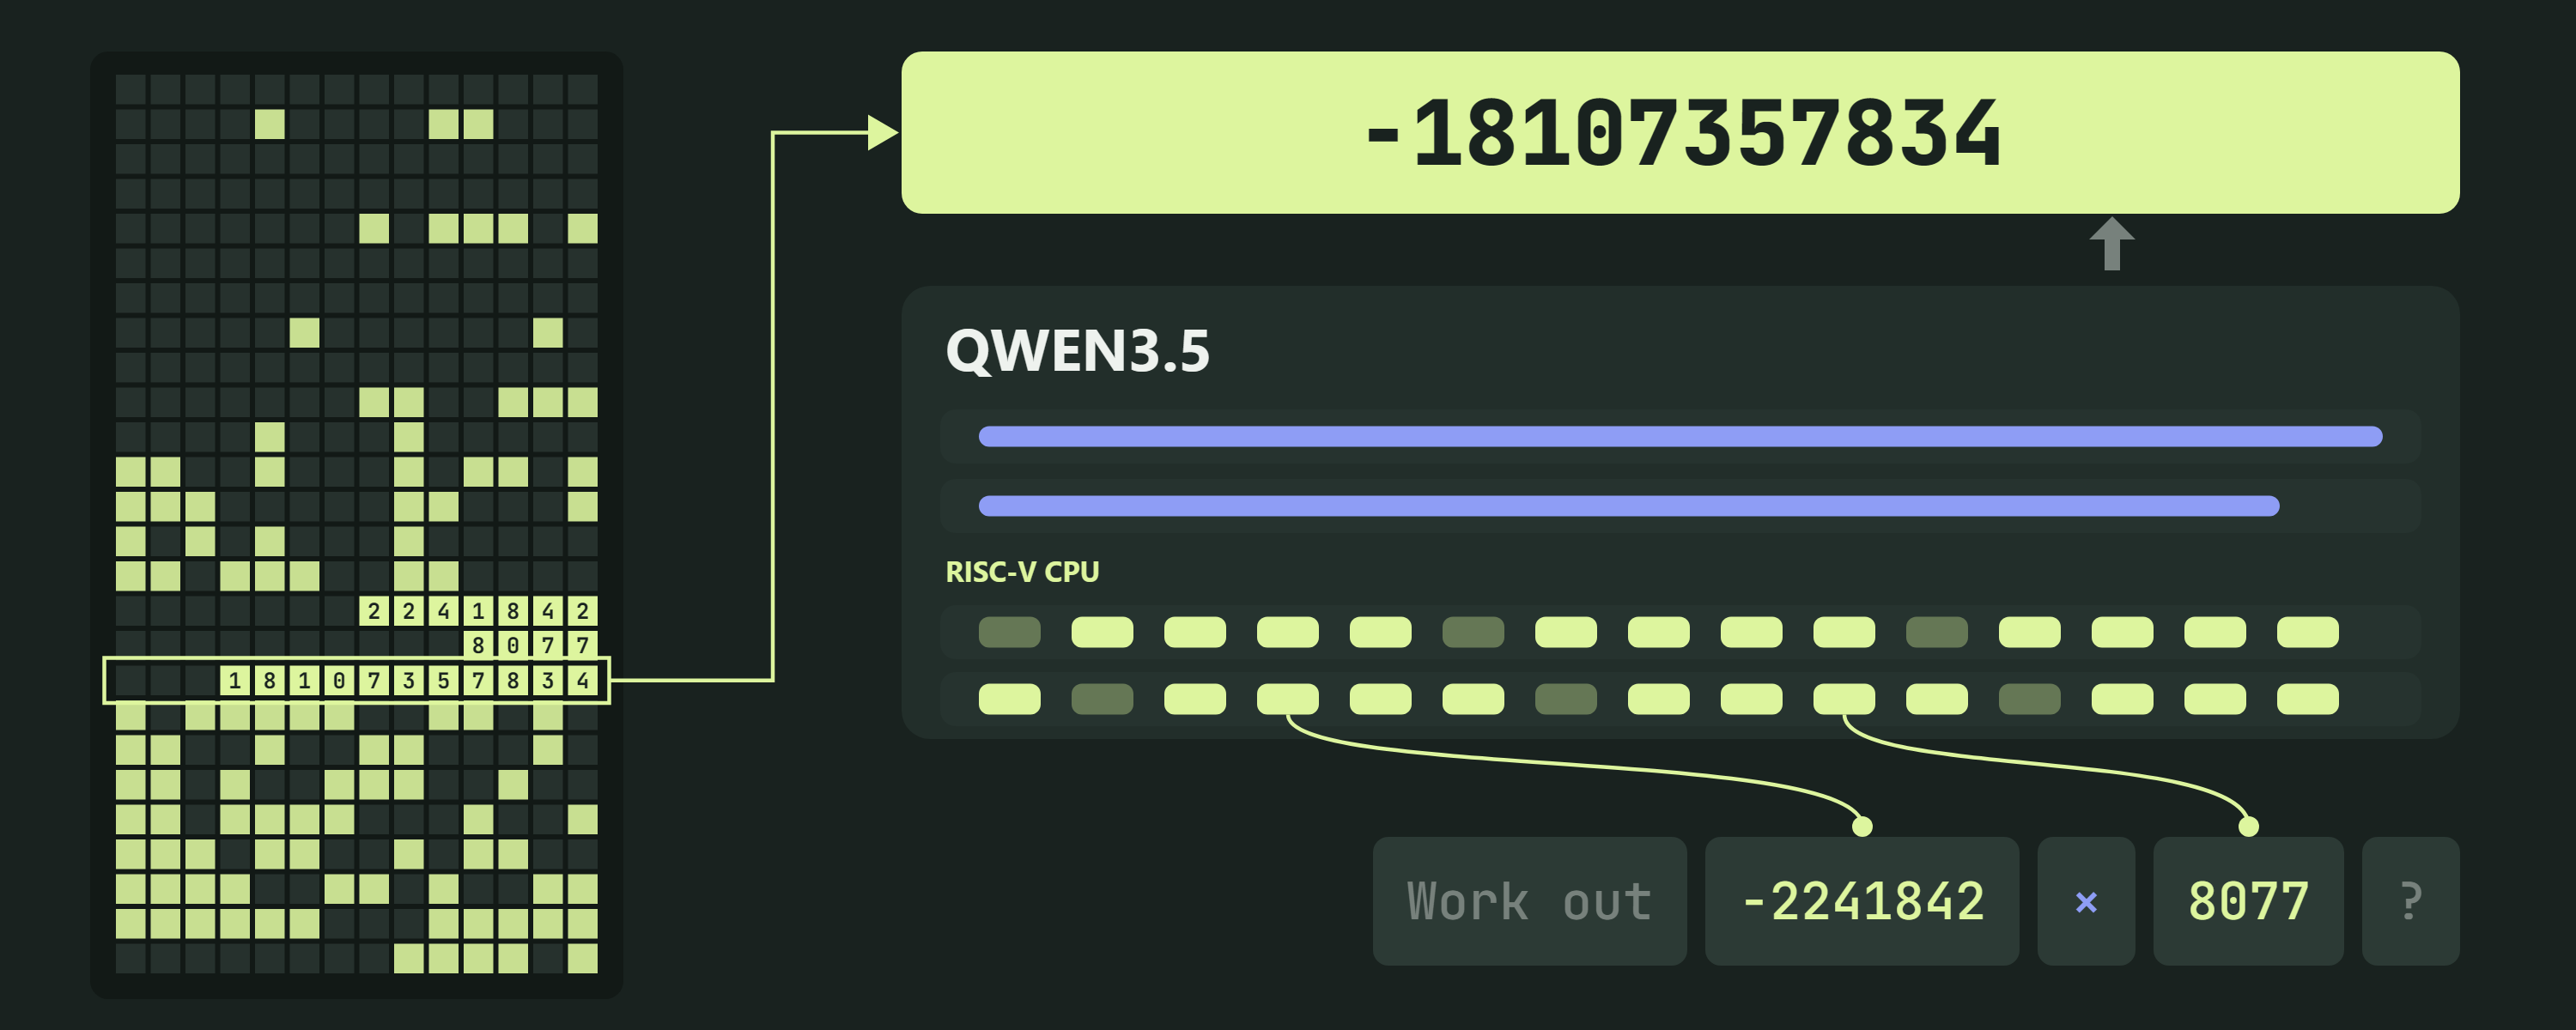
I compiled a RISC-V CPU into Qwen 3.5 4B's weights, using its Gated DeltaNet layers as RAM. It runs C and MicroPython inside the forward passes, and Qwen uses it for exact arithmetic.
A 30B Qwen Model Walks Into a Raspberry Pi… and Runs in Real Time
ByteShape's device-optimized release of Qwen3-30B-A3B-Instruct-2507.

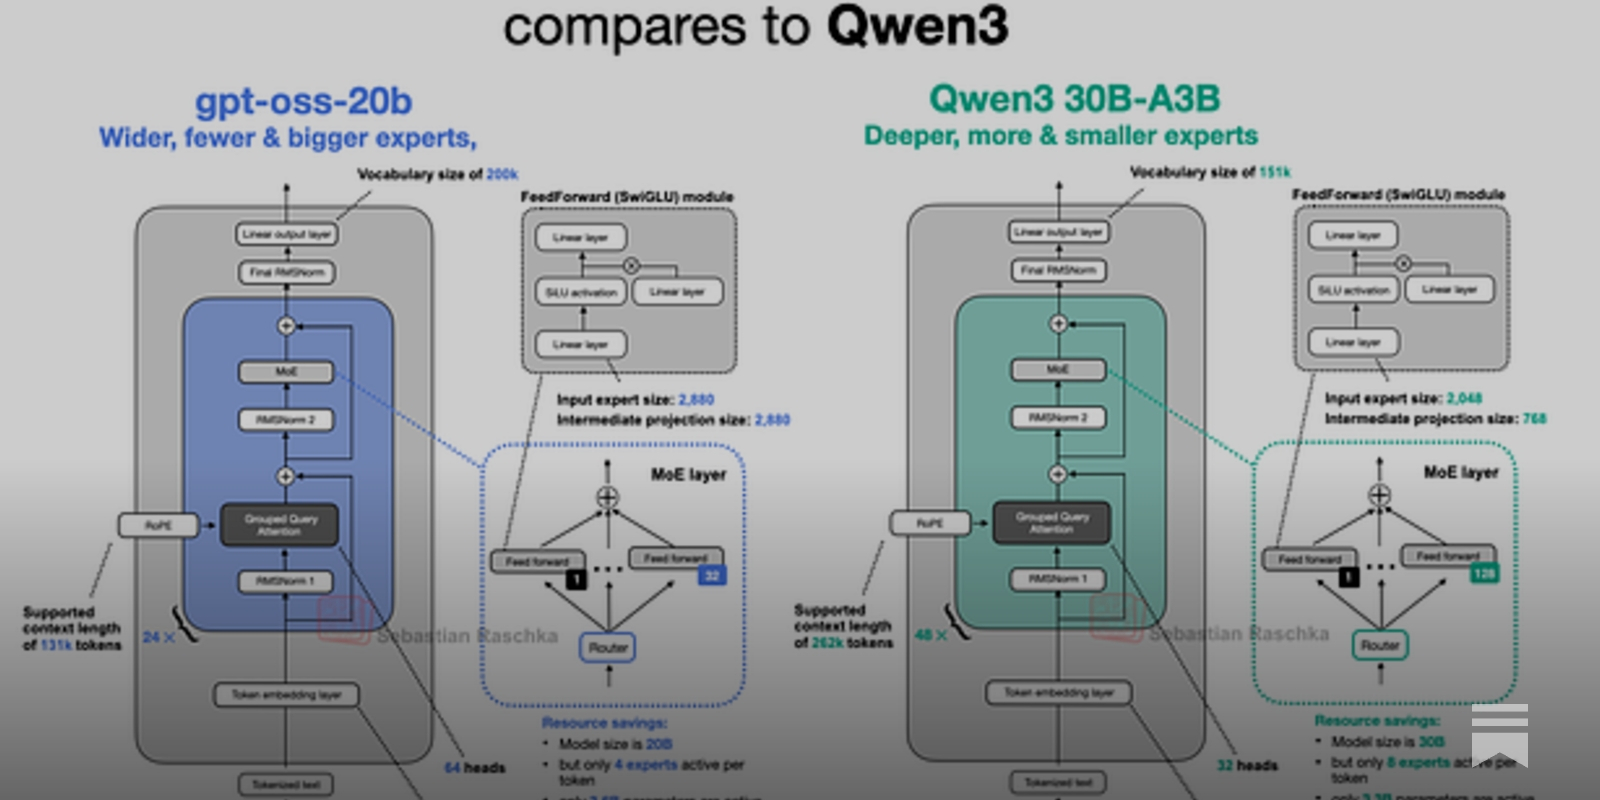
From GPT-2 to gpt-oss: Analyzing the Architectural Advances
And How They Stack Up Against Qwen3
Qwen on Twitter / X
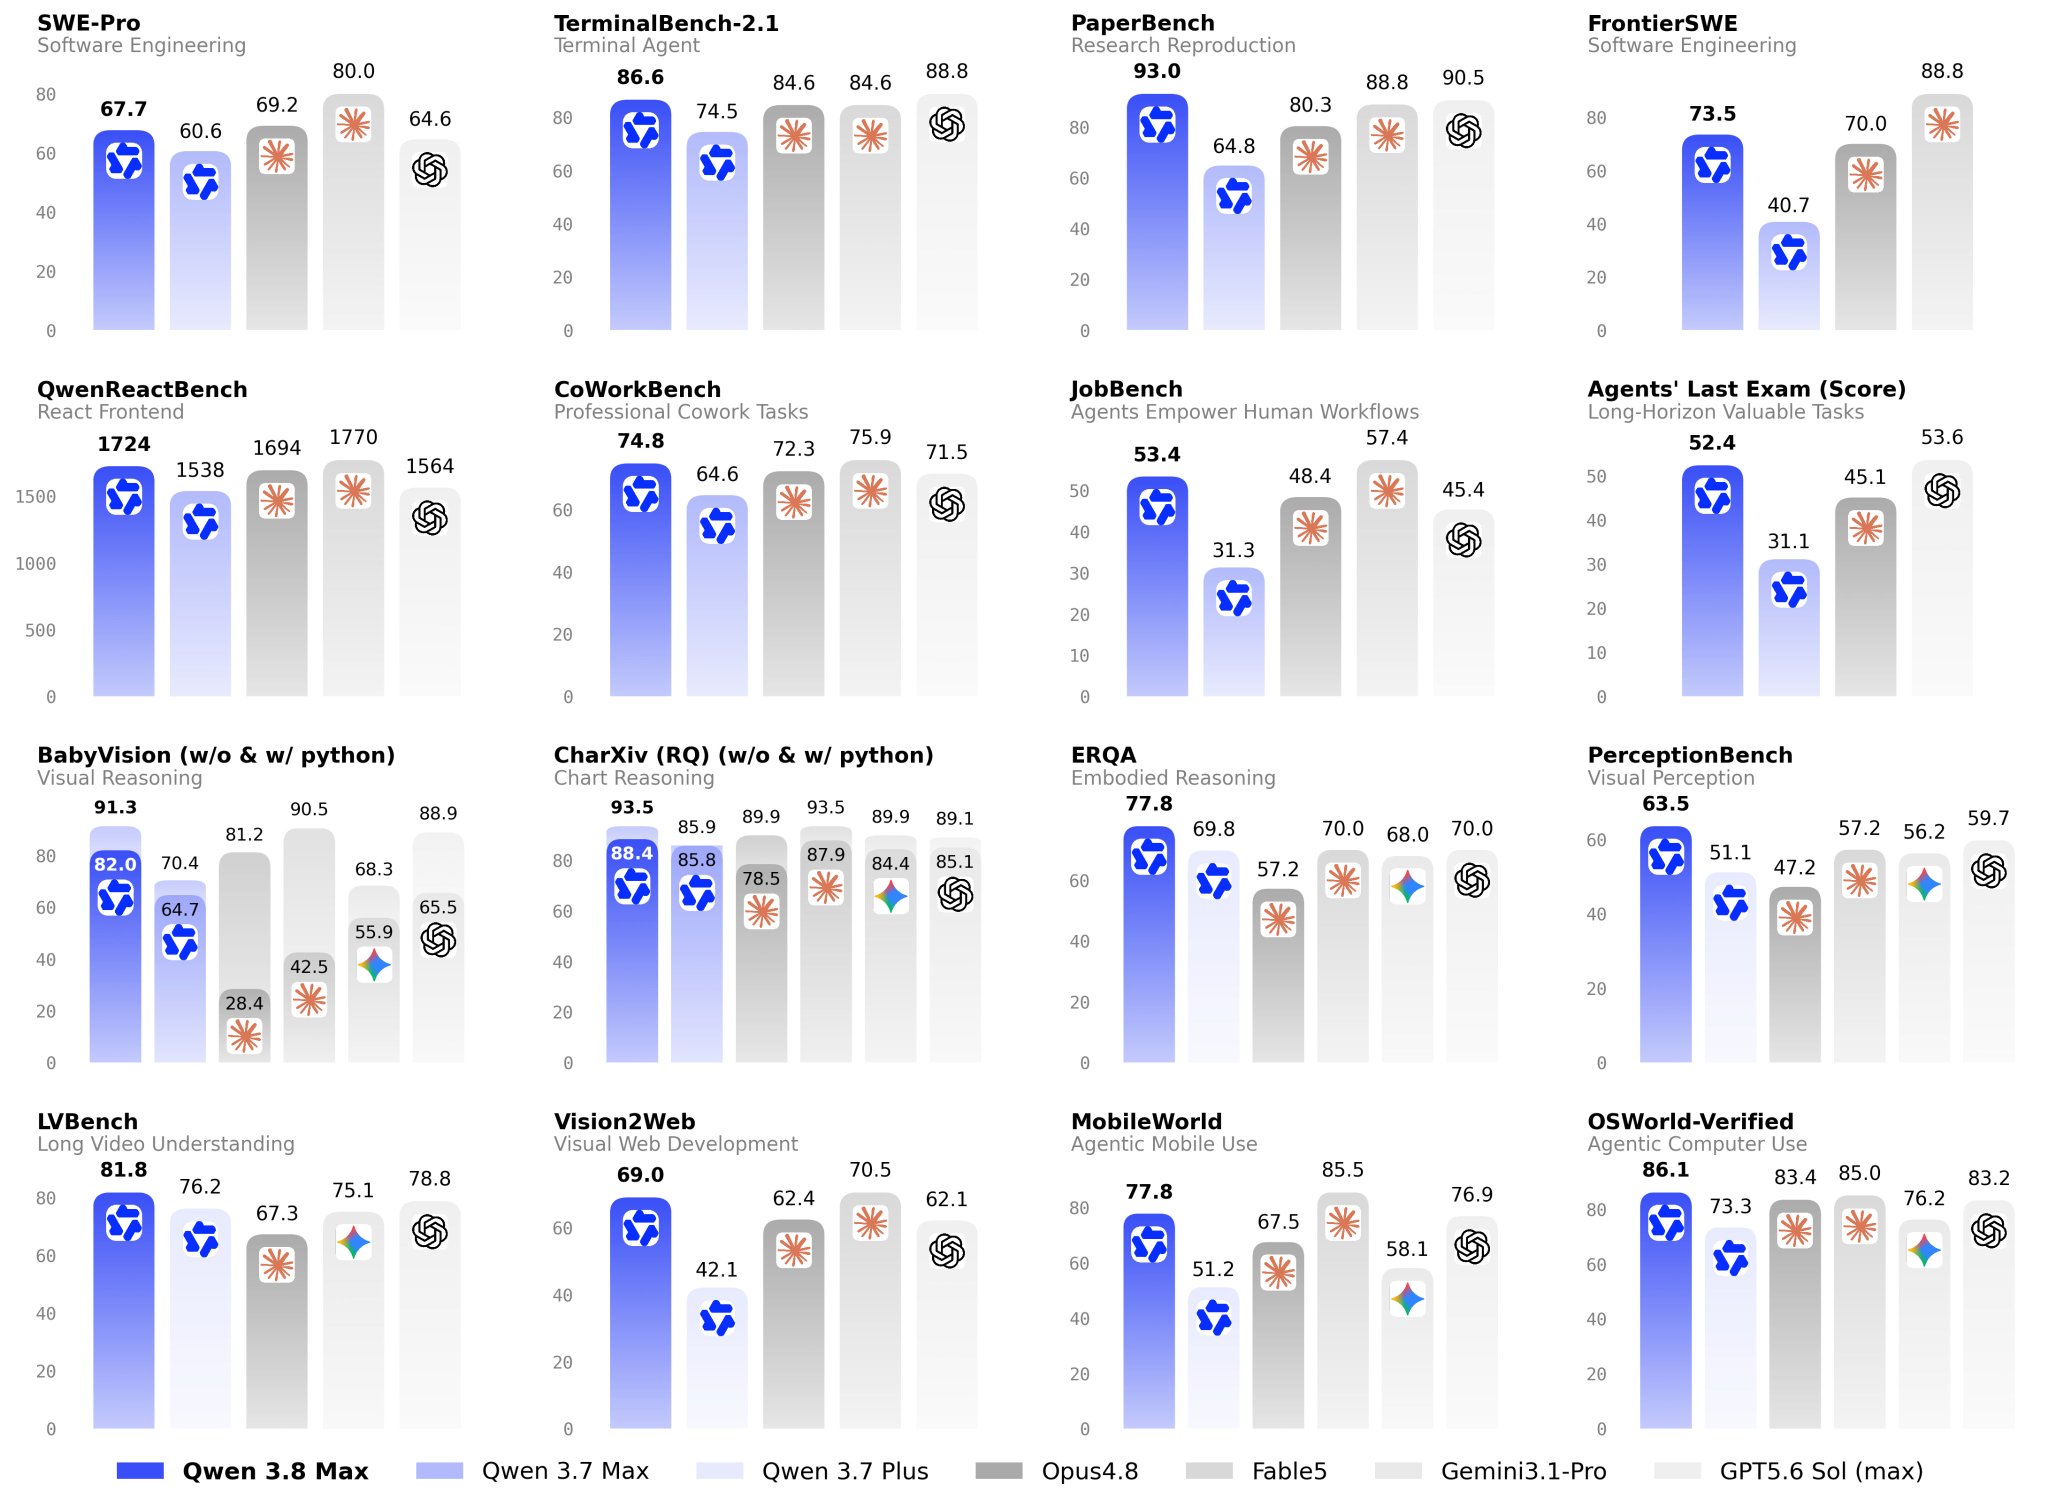
📢Meet Qwen3.8-Max — our most capable model to date. Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:- Autonomous coding: 10+ days of… pic.twitter.com/e3YFj2hqcT— Qwen (@Alibaba_Qwen) August 3, 2026
Georgi Gerganov on Twitter / X
I think the consensus is that Qwen3.5 is a step change so atm I would recommend explore that, given that it covers a range of sizes suitable for all devices.Note that the main issues that people currently unknowingly face with local models mostly revolve around the harness and…— Georgi Gerganov (@ggerganov) March 30, 2026
Casper Hansen on Twitter / X
Qwen3.5 Small models about to release!Qwen3.5 9B, 4B, 2B, 0.8B, or something in between is possible.- imagine 9B beating Qwen3-Next-80B- or 4B beating Qwen3-VL-30B in multimodal reasoningBuying a GPU is starting to have high return of intelligence on investment— Casper Hansen (@casper_hansen_) March 1, 2026
0xSero on Twitter / X
Are you compute poor? Do you want to run Qwen3.8-27B? Dude, if you have 8-16gb of vram or 16-24gb of MacOS memory this is by far the smartest model you can runPrimML is doing something phenomenal, they've created a ternary version of Qwen3.8-27B9x smaller 98.2% as smart! https://t.co/rtmNCsIQbA— 0xSero (@0xSero) September 17, 2026
Artur Chakhvadze on Twitter / X
We are releasing our first quantized checkpoints for the Qwen3.5 series of models, co-designed jointly with our inference engine to achieve maximum possible performance on Apple hardwareStarting from 0.8B, 2B and 4B modelshttps://t.co/2R8BdhAfzv— Artur Chakhvadze (@norpadon) June 8, 2026
Eric on Twitter / X
Qwen3.5 27B is awesome (the entire family above 9B is impressive). You can now try it directly in your browser at SOTA speeds with whatever GPU you have: https://t.co/avWxUd8vNLMy previous research in practice - The `Intel/Qwen3.5-27B-int4-AutoRound` is particularly good. https://t.co/QVSVNKM0Nk— Eric (@Ex0byt) March 21, 2026
The 'Astra can read and write weights to improve Qwen' post is misleading · honnibal.dev
The experiments that read raw weights and the ones that fix Qwen use completely different techniques.

Qwen 3 offers a case study in how to effectively release a model
Alibaba’s Qwen team released the hotly anticipated Qwen 3 model family today. The Qwen models are already some of the best open weight models—Apache 2.0 licensed and with a variety …
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an …
qwen3.5:27b
Qwen 3.5 is a family of open-source multimodal models that delivers exceptional utility and performance.
Rikiya Takehi on Twitter / X
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.We call this Weight-Space Programming:… pic.twitter.com/DwTwzXzSbE— Rikiya Takehi (@rikiyatakehi) November 2, 2026

Prince Canuma on Twitter / X
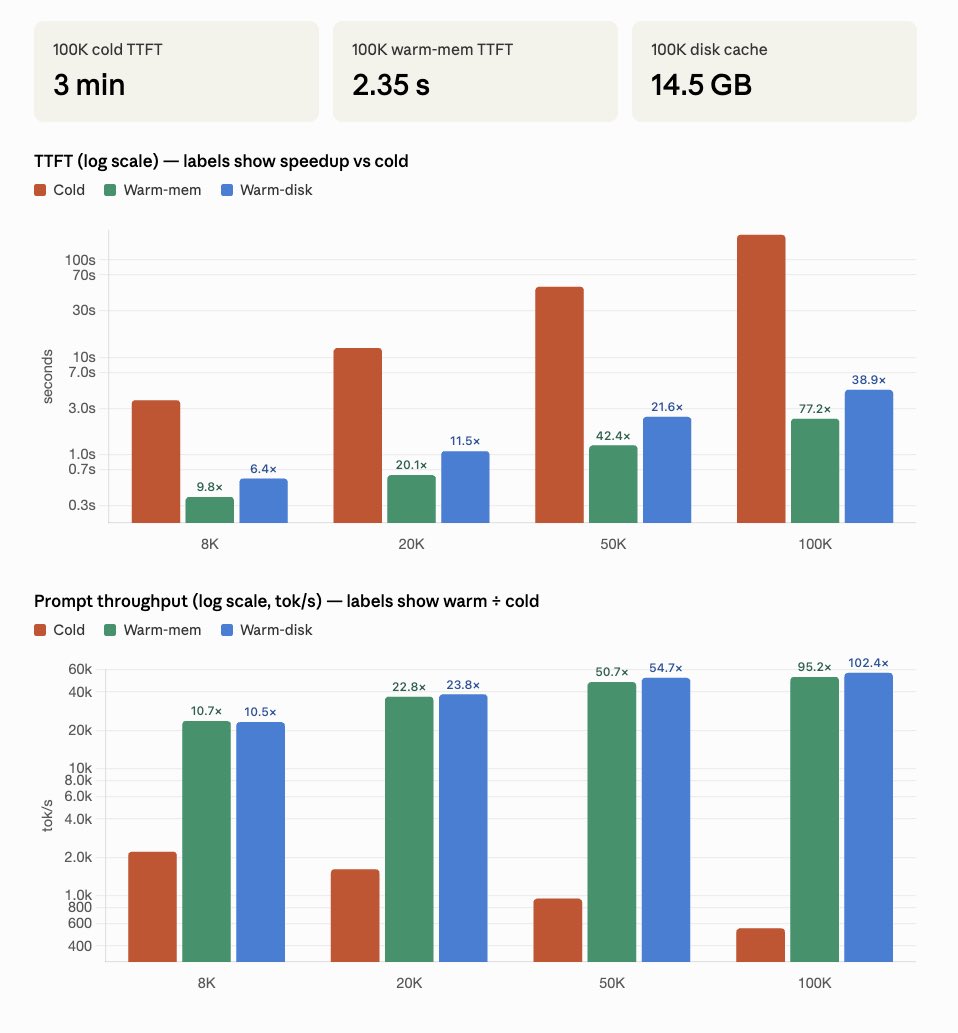
Prompt caching with SSD offloading now active and works with all your favourite harnesses: Pi, Hermes, OpenCode, Claude code and more.Here is the performance of Qwen3-VL-4B-Instruct when using our new prompt caching. pic.twitter.com/ikMktUgpqB— Prince Canuma (@Prince_Canuma) May 6, 2026