

Polars provides an in-memory, GPU-accelerated execution engine for Python users of the Lazy API on NVIDIA GPUs using RAPIDS cuDF. This functionality is available in Open Beta and is undergoing rapid development.
Introducing CUDA Rust: Two Tracks for Writing GPU Kernels | NVIDIA Technical Blog
In September 2026, NVIDIA announced it is leaning into native GPU programming in Rust. CUDA C++ and CUDA Python are mature, enterprise-grade toolchains, and NVIDIA will be growing and maturing CUDA…

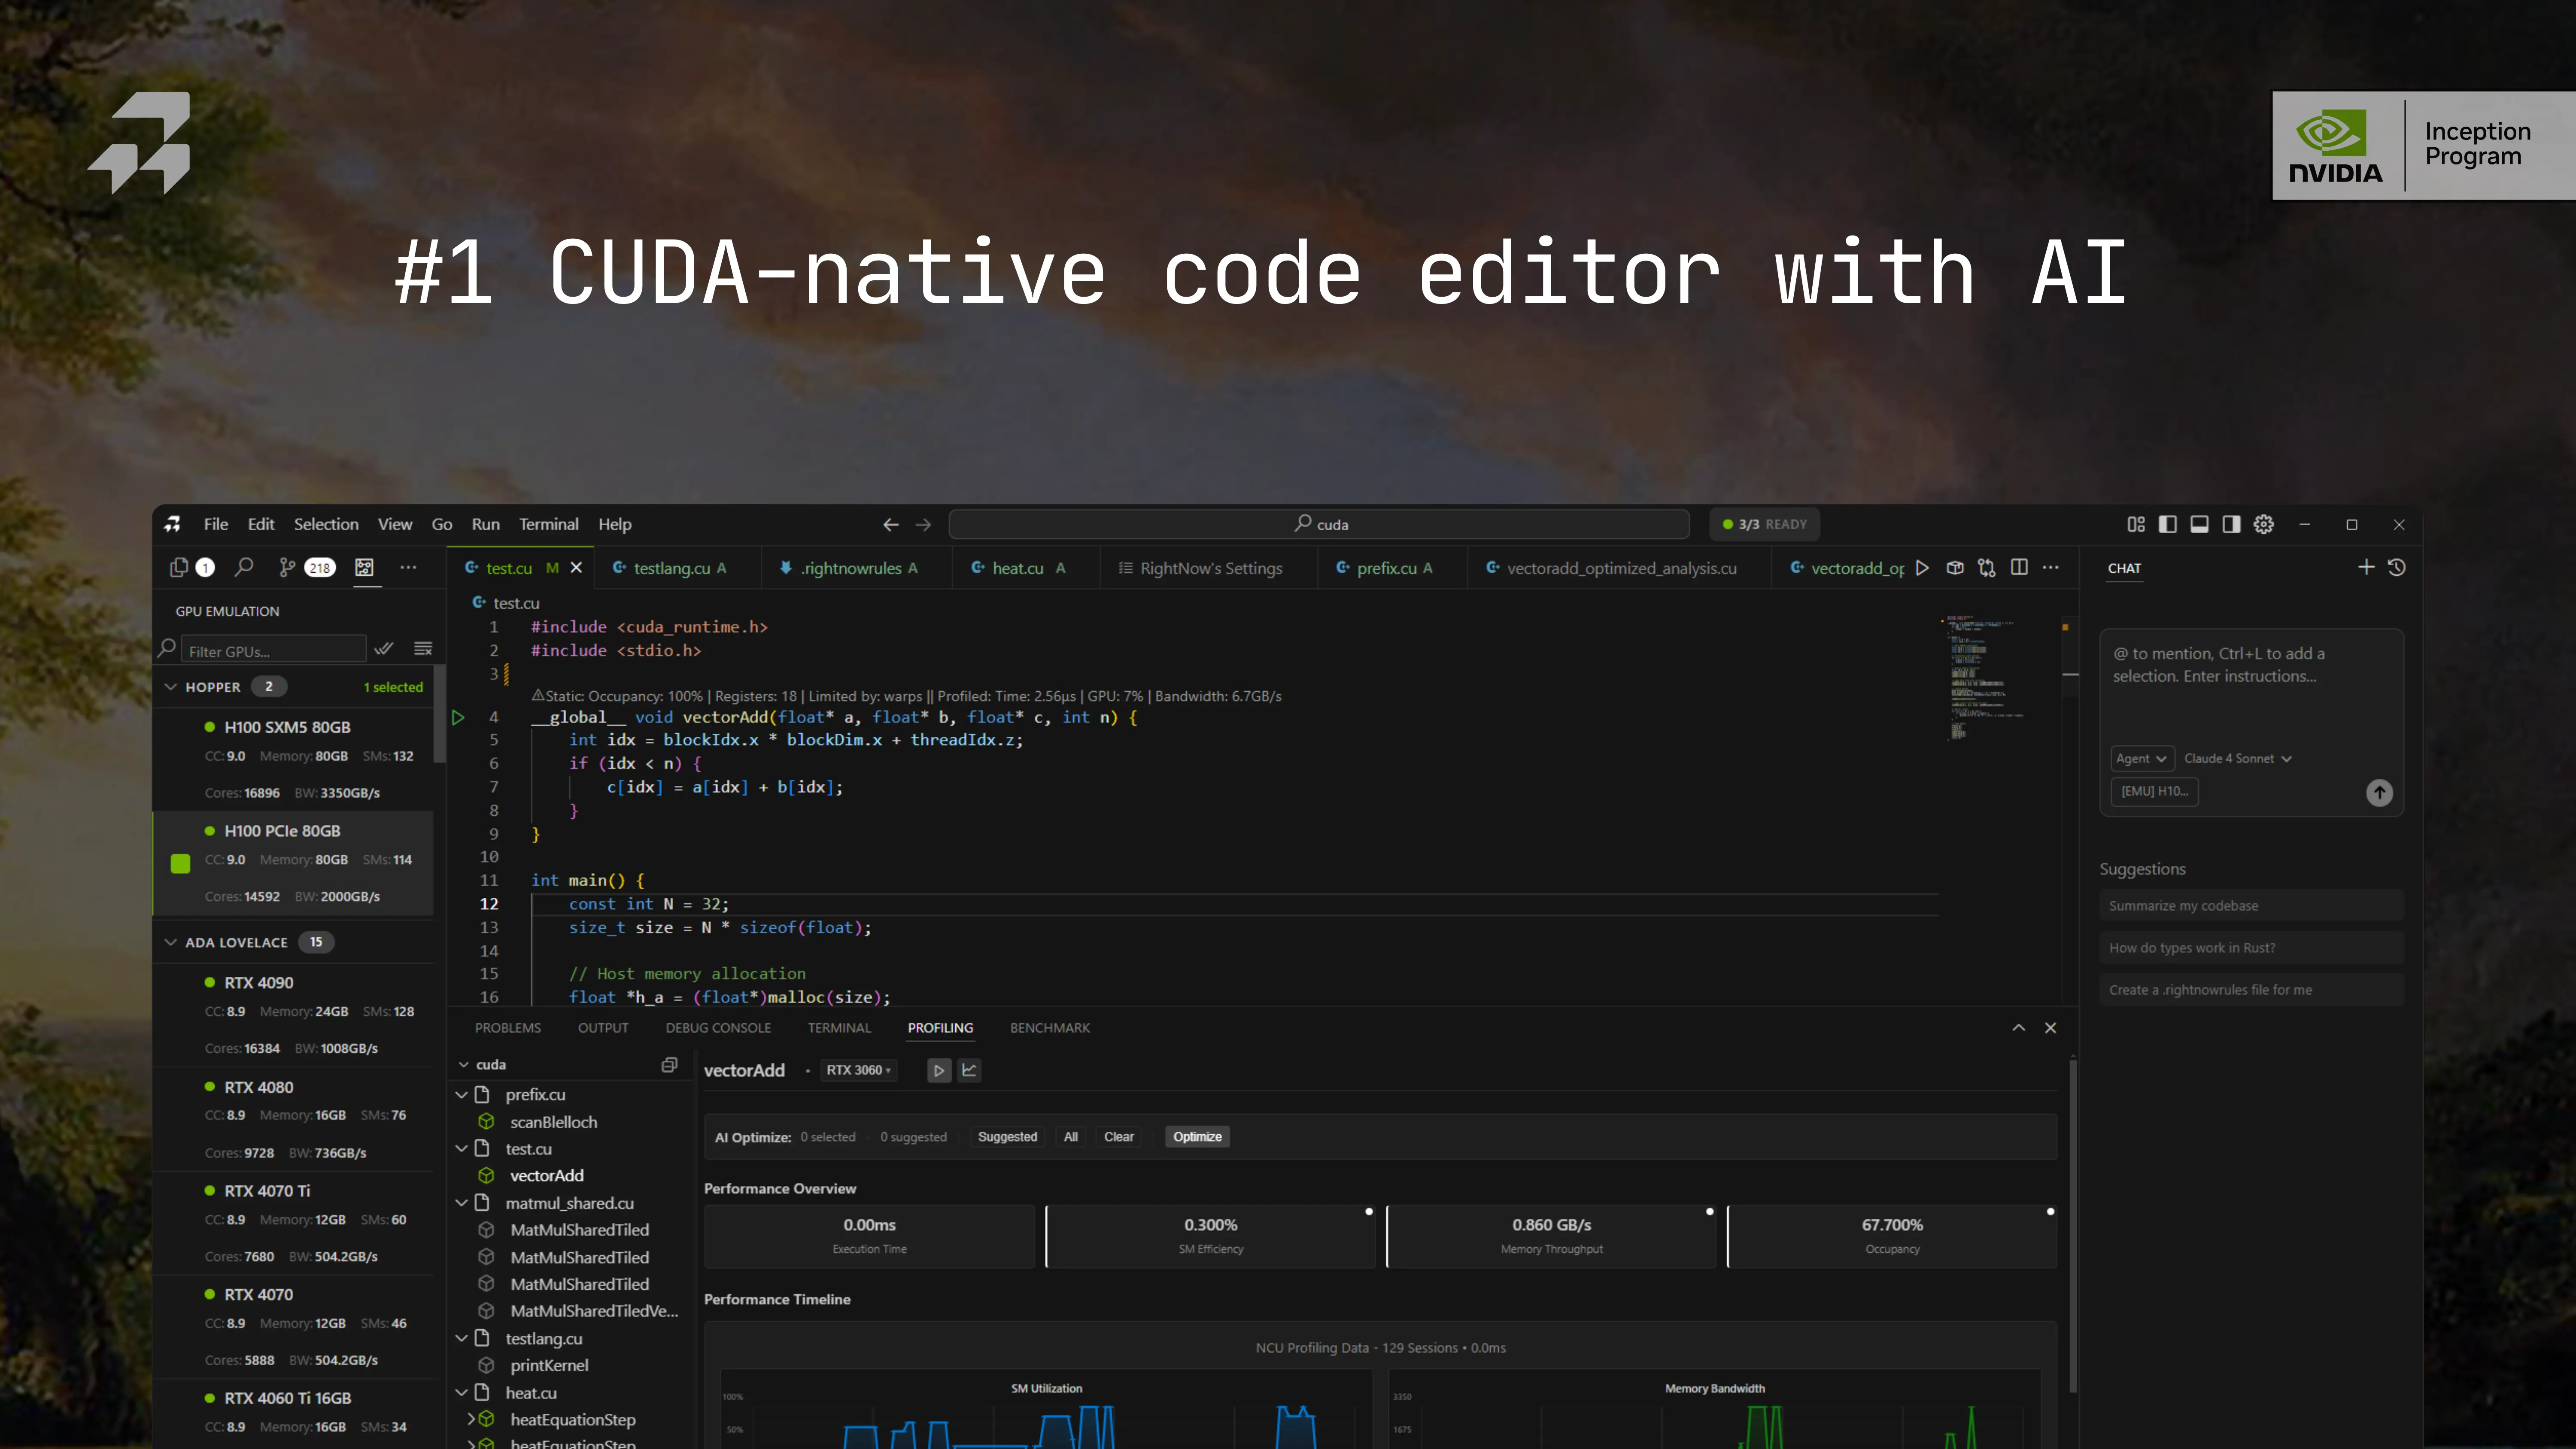
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
HipScript: Run HIP and CUDA code with WebGPU
Online compiler for HIP and NVIDIA® CUDA® code to WebGPU

TypeGPU – Type-safe WebGPU toolkit
Discover how it can change the way you work with GPU rendering and computing.
FOSDEM 2022 - LibVF.IO: vGPU & SR-IOV on Consumer GPUs using Nim
I'd like to showcase LibVF.IO's new LIME Runtime feature (Lime Is Mediated Emulation) and do a deep dive on open source vGPU technology in general.
Christian Legnitto Interview, Maintainer: rust-gpu, rust-cuda [Rust Project Content @ RustConf 2025]
Iwo Plaza – Your GPU is a JavaScript runtime* (TypeGPU deep-dive)
Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026
ASUS Ascent GX10
Desktop AI supercomputer delivering up to 1 petaFLOP performance, powered by NVIDIA GB10 Grace Blackwell Superchip, supporting OpenClaw and Hermes Agent.
software-mansion/TypeGPU
A modular and open-ended toolkit for WebGPU, with advanced type inference and the ability to write shaders in TypeScript
If NVIDIA can un-launch a GPU, we can delay an app launch | Colibri Blog
An update on the scheduled Colibri release for July 25.
Modern GPU Programming For MLSys — Modern GPU Programming For MLSys
Machine learning systems sit at the heart of modern AI workloads. In these systems, performance often comes down to the quality of a small number of GPU kernels. Attention kernels, LLM prefill and decode kernels, low-precision block-scaled GEMMs, fused MoE layers, and other large fused kernels all directly shape end-to-end speed in both training and serving.