

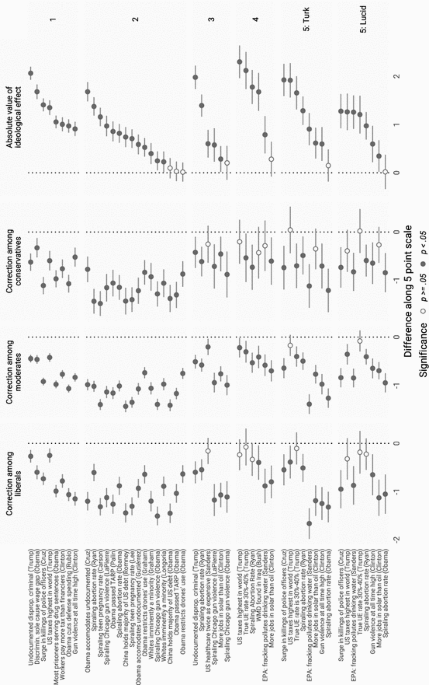
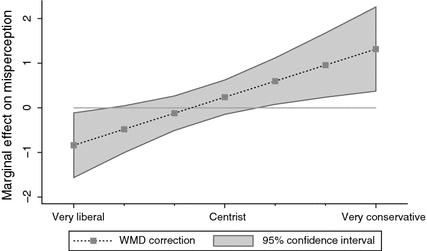
Can citizens heed factual information, even when such information challenges their partisan and ideological attachments? The “backfire effect,” described by Nyhan and Reifler (Polit Behav 32(2):303–330. https://doi.org/10.1007/s11109-010-9112-2, 2010), says no: rather than simply ignoring factual information, presenting respondents with facts can compound their ignorance. In their study, conservatives presented with factual information about the absence of Weapons of Mass Destruction in Iraq became more convinced that such weapons had been found. The present paper presents results from five experiments in which we enrolled more than 10,100 subjects and tested 52 issues of potential backfire. Across all experiments, we found no corrections capable of triggering backfire, despite testing precisely the kinds of polarized issues where backfire should be expected. Evidence of factual backfire is far more tenuous than prior research suggests. By and large, citizens heed factual information, even when such information challenges their ideological commitments.
When Corrections Fail: The Persistence of Political Misperceptions
An extensive literature addresses citizen ignorance, but very little research focuses on misperceptions. Can these false or unsubstantiated beliefs about politics be corrected? Previous studies have not tested the efficacy of corrections in a realistic format. We conducted four experiments in which subjects read mock news articles that included either a misleading claim from a politician, or a misleading claim and a correction. Results indicate that corrections frequently fail to reduce misperceptions among the targeted ideological group. We also document several instances of a “backfire effect” in which corrections actually increase misperceptions among the group in question.
Facts and Myths about Misperceptions
Misperceptions threaten to warp mass opinion and public policy on controversial issues in politics, science, and health. What explains the prevalence and persistence of these false and unsupported beliefs, which seem to be genuinely held by many people? Though limits on cognitive resources and attention play an important role, many of the most destructive misperceptions arise in domains where individuals have weak incentives to hold accurate beliefs and strong directional motivations to endorse beliefs that are consistent with a group identity such as partisanship. These tendencies are often exploited by elites who frequently create and amplify misperceptions to influence elections and public policy. Though evidence is lacking for claims of a “post-truth” era, changes in the speed with which false information travels and the extent to which it can find receptive audiences require new approaches to counter misinformation. Reducing the propagation and influence of false claims will require further efforts to inoculate people in advance of exposure (for example, media literacy), debunk false claims that are already salient or widespread (for example, fact-checking), reduce the prevalence of low-quality information (for example, changing social media algorithms), and discourage elites from promoting false information (for example, strengthening reputational sanctions).
The Liar’s Dividend: Can Politicians Claim Misinformation to Evade Accountability?
This study addresses the phenomenon of misinformation about misinformation, or politicians "crying wolf"' over fake news. Strategic and false claims that stories are fake news or deepfakes may benefit politicians by helping them maintain support after a scandal. We posit that this benefit, known as the "liar's dividend," may be achieved through two politician strategies: by invoking informational uncertainty or by encouraging oppositional rallying of core supporters. We administer five survey experiments to over 15,000 American adults detailing hypothetical politician responses to stories describing real politician scandals. We find that claims of misinformation representing both strategies raise politician support across partisan subgroups. These strategies are effective against text-based reports of scandals, but are largely ineffective against video evidence and do not reduce general trust in media. Finally, these false claims produce greater dividends for politicians than alternative responses to scandal, such as remaining silent or apologizing.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Dialogues on Democracy: Belief-Tailored AI Conversations Reduce Inaccurate Election Denial Beliefs
Elections, while central to democratic functioning, have become increasingly threatened by beliefs about election fraud. Artificial intelligence (AI) provides a novel opportunity to address such false beliefs through dynamic conversation and debunking. Through two experiments (N = 1,802 Republicans from Lucid who endorsed election fraud claims), we examined the use of AI to fact-check 2020 election conspiracies prior to the 2024 US Presidential election. We tested the effects of two treatments (an information-tailored and values-tailored AI dialogue) in which AI fact-checked their claims and tailored arguments to the specific election conspiracy that the participant themselves articulated. Both treatment conditions, when compared to a control dialogue and a simple statement that the conspiracy was incorrect, reduced confidence in their election conspiracy claims. There was no significant difference between information-tailored and values-tailored feedback. Promisingly, participants with the strongest baseline denialism experienced the largest decreases in denialism beliefs. These studies highlight the potential of AI-driven interventions to address election misinformation.
Leveraging Motivations to Curb Misinformation: Self-Affirmation Reduces the Appeal of Political Conspiracy Theories
Abstract: In an era where digital misinformation poses significant challenges to societal well-being, this study explores a novel approach to preserving information integrity by addressing the motivational underpinnings of conspiracy theory engagement. As conspiracy theories proliferate online, traditional fact-checking and debunking strategies often prove ineffective due to the self-reinforcing nature of conspiracy theories. This research investigates whether a priori self-affirmation interventions can reduce individuals’ propensity to engage with conspiracy theories by preemptively fulfilling the ego-protective function these theories often serve. Using a randomized experiment ( N = 451), this study finds that participants who completed a self-affirmation task were less likely to read politicized conspiracy theories, and those who chose to read a conspiracy theory reported greater feelings of affirmation than those who did not. Thus, bolstering individuals’ self-integrity may offer an opportunity to mitigate the appeal of politicized conspiracy theories.

How latent and prompting biases in AI-generated historical narratives influence opinions
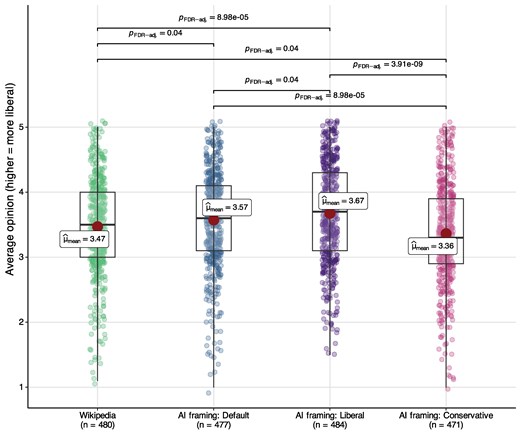
Abstract Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizing messages and dialogues intended to change minds. However, their capacity to influence opinions through subtle, latent ideological framing remains relatively understudied. We investigate whether AI-generated historical summaries affect social and political opinions through a preregistered experiment (N = 1,912). Participants read Wikipedia or GPT-4o summaries of two historical events, with AI summaries maintaining factual accuracy while exhibiting different types of framing biases. Default AI summaries led to more liberal opinions compared with Wikipedia, demonstrating the persuasive capability of LLM's latent biases. Summaries purposefully induced with a liberal framing also led to more liberal opinions, regardless of readers’ ideologies. Summaries constructed with a conservative framing produced conservative shifts primarily among conservative readers. These findings demonstrate that the use of AI for learning history can influence opinions through both intrinsic and intentional framing mechanisms, even when the content remains factually accurate. As AI becomes integral to information acquisition, recognizing pathways of influence based not only on user-manipulated content but also on models’ latent biases is essential for understanding AI's broader societal impacts.
Sharing without clicking on news in social media
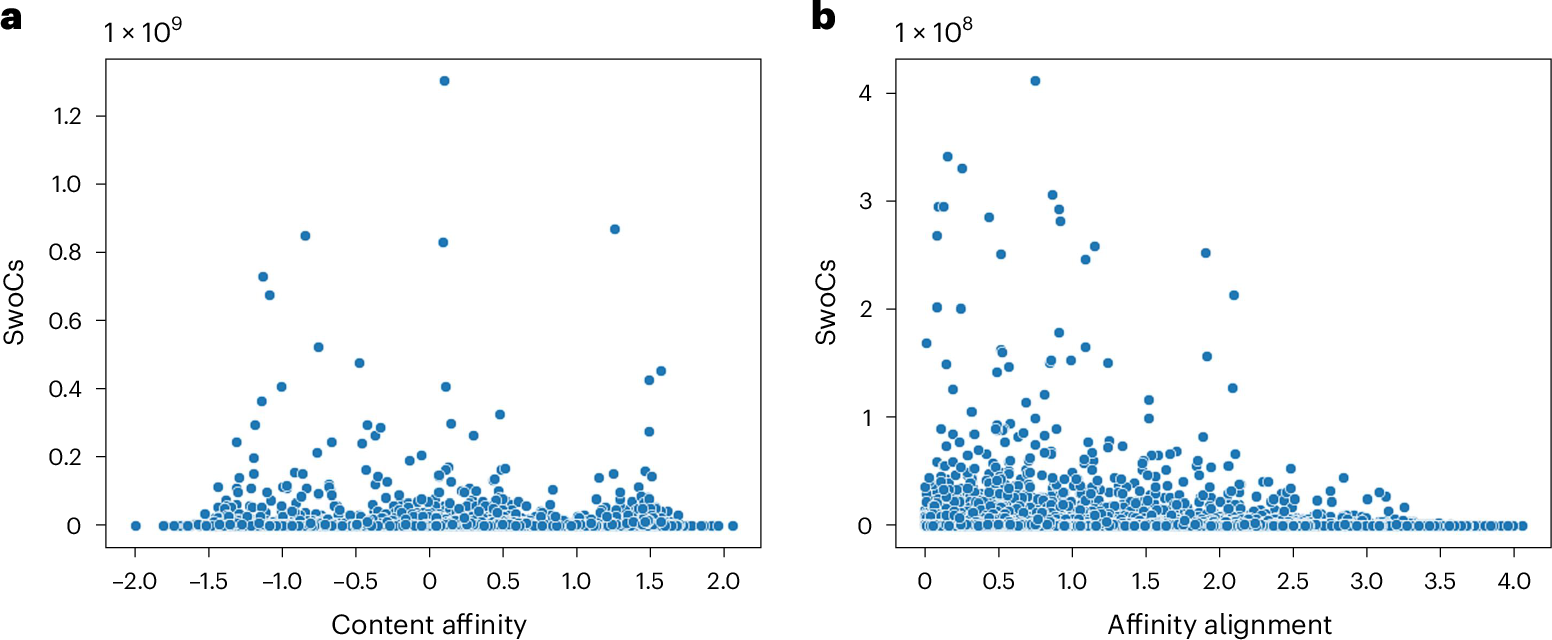
Social media have enabled laypersons to disseminate, at scale, links to news and public affairs information. Many individuals share such links without first reading the linked information. Here we analysed over 35 million public Facebook posts with uniform resource locators shared between 2017 and 2020, and discovered that such ‘shares without clicks’ (SwoCs) constitute around 75% of forwarded links. Extreme and user-aligned political content received more SwoCs, with partisans engaging in it more than politically neutral users. In addition, analyses with 2,969 false uniform resource locators revealed higher shares and, hence, SwoCs by conservatives (76.94%) than liberals (14.25%), probably because, in our dataset, the vast majority (76–82%) of them originated from conservative news domains. Findings suggest that the virality of political content on social media (including misinformation) is driven by superficial processing of headlines and blurbs rather than systematic processing of core content, which has design implications for promoting deliberate discourse in the online public sphere.
Debunking: A Meta-Analysis of the Psychological Efficacy of Messages Countering Misinformation
This meta-analysis investigated the factors underlying effective messages to counter attitudes and beliefs based on misinformation. Because misinformation can lead to poor decisions about consequential matters and is persistent and difficult to correct, debunking it is an important scientific and public-policy goal. This meta-analysis ( k = 52, N = 6,878) revealed large effects for presenting misinformation ( ds = 2.41–3.08), debunking ( ds = 1.14–1.33), and the persistence of misinformation in the face of debunking ( ds = 0.75–1.06). Persistence was stronger and the debunking effect was weaker when audiences generated reasons in support of the initial misinformation. A detailed debunking message correlated positively with the debunking effect. Surprisingly, however, a detailed debunking message also correlated positively with the misinformation-persistence effect.

The small effects of political advertising are small regardless of context, message, sender, or receiver: Evidence from 59 real-time randomized experiments
Campaign persuasion operates with notable consistency across political parties, message tone, and information environment., Evidence across social science indicates that average effects of persuasive messages are small. One commonly offered explanation for these small effects is heterogeneity: Persuasion may only work well in specific circumstances. To evaluate heterogeneity, we repeated an experiment weekly in real time using 2016 U.S. presidential election campaign advertisements. We tested 49 political advertisements in 59 unique experiments on 34,000 people. We investigate heterogeneous effects by sender (candidates or groups), receiver (subject partisanship), content (attack or promotional), and context (battleground versus non-battleground, primary versus general election, and early versus late). We find small average effects on candidate favorability and vote. These small effects, however, do not mask substantial heterogeneity even where theory from political science suggests that we should find it. During the primary and general election, in battleground states, for Democrats, Republicans, and Independents, effects are similarly small. Heterogeneity with large offsetting effects is not the source of small average effects.

LLM-generated messages can persuade humans on policy issues
The emergence of large language models (LLMs) has made it possible for generative artificial intelligence (AI) to tackle many higher-order cognitive tasks, with critical implications for industry, government, and labor markets. Here, we investigate whether existing, openly-available LLMs can be used to create messages capable of influencing humans’ political attitudes. Across three pre-registered experiments (total N = 4829), participants who read persuasive messages generated by LLMs showed significantly more attitude change across a range of policies - including polarized policies, like an assault weapons ban, a carbon tax, and a paid parental-leave program - relative to control condition participants who read a neutral message. Overall, LLM-generated messages were similarly effective in influencing policy attitudes as messages crafted by lay humans. Participants’ reported perceptions of the authors of the persuasive messages suggest these effects occurred through somewhat distinct causal pathways. While the persuasiveness of LLM-generated messages was associated with perceptions that the author used more facts, evidence, logical reasoning, and a dispassionate voice, the persuasiveness of human-generated messages was associated with perceptions of the author as unique and original. These results demonstrate that recent developments in AI make it possible to create politically persuasive messages quickly, cheaply, and at massive scale.

Explicit warnings reduce but do not eliminate the continued influence of misinformation
Information that initially is presumed to be correct, but that is later retracted or corrected, often continues to influence memory and reasoning. This occurs even if the retraction itself is well remembered. The present study investigated whether the continued influence of misinformation can be reduced by explicitly warning people at the outset that they may be misled. A specific warning— giving detailed information about the continued influence effect (CIE)—succeeded in reducing the continued reliance on outdated information but did not eliminate it. A more general warning—reminding people that facts are not always properly checked before information is disseminated—was even less effective. In an additional experiment, a specific warning was combined with the provision of a plausible alternative explanation for the retracted information. This combined manipulation further reduced the CIE but still failed to eliminate it altogether.
So maybe now we can agree that having an unchecked research integrity militia who unfortunately has the ear of the press and increasingly that of the the publishers, but who fiercely rejects any… | Ioana A. Cristea
So maybe now we can agree that having an unchecked research integrity militia who unfortunately has the ear of the press and increasingly that of the the publishers, but who fiercely rejects any minimal ethics or code of conduct, is a (growing) problem? Also, that 1. problems have to be investigated before deciding they are are legitimate and serious; 2. this investigation is not social media, blogs and the press; 3. this investigation should not be on the front page of journals and Retraction Watch; 4. there are degrees of seriousness and some things can just be corrected or are simply not very consequential (no, it's not a house of bricks where we have to check every brick, that's a dumb analogy), so being absolutely hysterical and overdramatic about any lie, inaccuracy or mistake is purposeful at worse and should be ignored at best and 5. it is not only unnecessary, but harmful, to also go into other, non-academic things the person did or does to complete "investigations" that you (press, sleuth, blogger, etc) do not have the tools and information to do completely and accurately (this fixation would be called harassment in the before times). Others will justly write about what the institutions did or did not do, but what I want to say is that we really should end it with the blank credit we give to any and all allegations that come from the establish research integrity truth fighters.
Political Bias Audits of LLMs Capture Sycophancy to the Inferred Auditor
Large language models (LLMs) are commonly evaluated for political bias based on their responses to fixed questionnaires, which typically place frontier models on the political left. A parallel literature shows that LLMs are sycophantic: they adapt their answers to the views, identities, and expectations of the user. We show that these findings are linked: standard political-bias audits partly capture sycophantic accommodation to the inferred auditor. We employ a factorial experiment across three major audit instruments--the Political Compass Test, the Pew Political Typology, and 1,540 partisan-benchmarked Pew American Trends Panel items--administered to six frontier LLMs while varying only the asker's stated identity (N = 30,990 responses). At baseline, all six models lean left. When the asker identifies as a conservative Republican, responses shift sharply: the share of items closer to Democrats falls by 28-62 percentage points, and all six models move right of center. A mirror-image progressive-Democrat cue produces little change; rightward accommodation is 8.0$\times$ larger than leftward. When asked who the default asker is, models identify an auditor, researcher, or academic; when asked what answer that asker expects, they select the Democrat-coded option 75% of the time, nearly the rate under an explicit progressive cue. These patterns are inconsistent with a purely fixed model ideology and indicate that single-prompt audits capture an interaction between model and inferred interlocutor. Political bias in LLMs is therefore not a fixed point on an ideological scale but a response profile that must be mapped across realistic interlocutors.

Sharing of misinformation is habitual, not just lazy or biased
Why do people share misinformation on social media? In this research ( N = 2,476), we show that the structure of online sharing built into social platforms is more important than individual deficits in critical reasoning and partisan bias—commonly cited drivers of misinformation. Due to the reward-based learning systems on social media, users form habits of sharing information that attracts others' attention. Once habits form, information sharing is automatically activated by cues on the platform without users considering response outcomes such as spreading misinformation. As a result of user habits, 30 to 40% of the false news shared in our research was due to the 15% most habitual news sharers. Suggesting that sharing of false news is part of a broader response pattern established by social media platforms, habitual users also shared information that challenged their own political beliefs. Finally, we show that sharing of false news is not an inevitable consequence of user habits: Social media sites could be restructured to build habits to share accurate information.