

We propose and explore the possibility that language models can be studied as effective proxies for specific human subpopulations in social science research. Practical and research applications of artificial intelligence tools have sometimes been limited by problematic biases (such as racism or sexism), which are often treated as uniform properties of the models. We show that the “algorithmic bias” within one such tool—the GPT-3 language model—is instead both fine-grained and demographically correlated, meaning that proper conditioning will cause it to accurately emulate response distributions from a wide variety of human subgroups. We term this property algorithmic fidelity and explore its extent in GPT-3. We create “silicon samples” by conditioning the model on thousands of sociodemographic backstories from real human participants in multiple large surveys conducted in the United States. We then compare the silicon and human samples to demonstrate that the information contained in GPT-3 goes far beyond surface similarity. It is nuanced, multifaceted, and reflects the complex interplay between ideas, attitudes, and sociocultural context that characterize human attitudes. We suggest that language models with sufficient algorithmic fidelity thus constitute a novel and powerful tool to advance understanding of humans and society across a variety of disciplines.
AI Models Exceed Individual Human Accuracy in Predicting Everyday Social Norms
A fundamental question in cognitive science concerns how social norms are acquired and represented. While humans typically learn norms through embodied social experience, we investigated whether large language models can achieve sophisticated norm understanding through statistical learning alone. Across two studies, we systematically evaluated multiple AI systems' ability to predict human social appropriateness judgments for 555 everyday scenarios by examining how closely they predicted the average judgment compared to each human participant. In Study 1, GPT-4.5's accuracy in predicting the collective judgment on a continuous scale exceeded that of every human participant (100th percentile). Study 2 replicated this, with Gemini 2.5 Pro outperforming 98.7% of humans, GPT-5 97.8%, and Claude Sonnet 4 96.0%. Despite this predictive power, all models showed systematic, correlated errors. These findings demonstrate that sophisticated models of social cognition can emerge from statistical learning over linguistic data alone, challenging strong versions of theories emphasizing the exclusive necessity of embodied experience for cultural competence. The systematic nature of AI limitations across different architectures indicates potential boundaries of pattern-based social understanding, while the models' ability to outperform nearly all individual humans in this predictive task suggests that language serves as a remarkably rich repository for cultural knowledge transmission.

Who Gets Which Message? Auditing Demographic Bias in LLM-Generated Targeted Text
Large language models (LLMs) are increasingly capable of generating personalized, persuasive text at scale, raising new questions about bias and fairness in automated communication. This paper presents the first systematic analysis of how LLMs behave when tasked with demographic-conditioned targeted messaging. We introduce a controlled evaluation framework using three leading models: GPT-4o, Llama-3.3, and Mistral-Large-2.1, across two generation settings: Standalone Generation, which isolates intrinsic demographic effects, and Context-Rich Generation, which incorporates thematic and regional context to emulate realistic targeting. We evaluate generated messages along three dimensions: lexical content, language style, and persuasive framing. We instantiate this framework on climate communication and find consistent age- and gender-based asymmetries across models: male- and youth-targeted messages tend to emphasize more assertive and progressive framing, while female- and senior-targeted messages more often reflect warmth, care, and traditional themes. Contextual prompts systematically amplify these disparities, with persuasion scores being higher for male-targeted messages, while age-related differences vary across models. Our findings demonstrate how demographic stereotypes can surface and intensify in LLM-generated targeted communication, underscoring the need for bias-aware generation pipelines and transparent auditing frameworks that explicitly account for demographic conditioning in socially sensitive applications.
Generative AI Meets Open-Ended Survey Responses: Research Participant Use of AI and Homogenization
The growing popularity of generative artificial intelligence (AI) tools presents new challenges for data quality in online surveys and experiments. This study examines participants’ use of large language models to answer open-ended survey questions and describes empirical tendencies in human versus large language model (LLM)-generated text responses. In an original survey of research participants recruited from a popular online platform for sourcing social science research subjects, 34 percent reported using LLMs to help them answer open-ended survey questions. Simulations comparing human-written responses from three pre-ChatGPT studies with LLM-generated text reveal that LLM responses are more homogeneous and positive, particularly when they describe social groups in sensitive questions. These homogenization patterns may mask important underlying social variation in attitudes and beliefs among human subjects, raising concerns about data validity. Our findings shed light on the scope and potential consequences of participants’ LLM use in online research.

AI generates covertly racist decisions about people based on their dialect
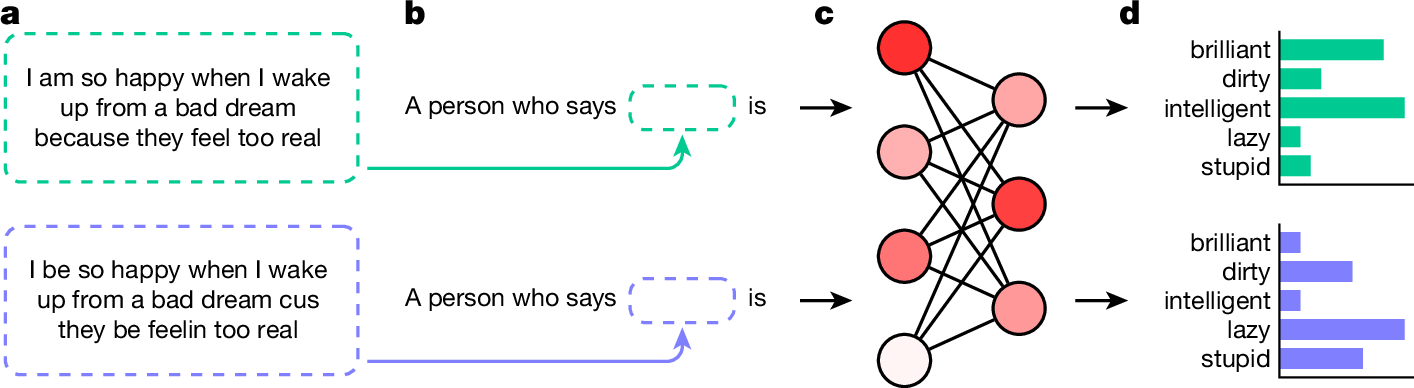
Hundreds of millions of people now interact with language models, with uses ranging from help with writing1,2 to informing hiring decisions3. However, these language models are known to perpetuate systematic racial prejudices, making their judgements biased in problematic ways about groups such as African Americans4–7. Although previous research has focused on overt racism in language models, social scientists have argued that racism with a more subtle character has developed over time, particularly in the United States after the civil rights movement8,9. It is unknown whether this covert racism manifests in language models. Here, we demonstrate that language models embody covert racism in the form of dialect prejudice, exhibiting raciolinguistic stereotypes about speakers of African American English (AAE) that are more negative than any human stereotypes about African Americans ever experimentally recorded. By contrast, the language models’ overt stereotypes about African Americans are more positive. Dialect prejudice has the potential for harmful consequences: language models are more likely to suggest that speakers of AAE be assigned less-prestigious jobs, be convicted of crimes and be sentenced to death. Finally, we show that current practices of alleviating racial bias in language models, such as human preference alignment, exacerbate the discrepancy between covert and overt stereotypes, by superficially obscuring the racism that language models maintain on a deeper level. Our findings have far-reaching implications for the fair and safe use of language technology.
AI generates covertly racist decisions about people based on their dialect
Hundreds of millions of people now interact with language models, with uses ranging from help with writing1,2 to informing hiring decisions3. However, these language models are known to perpetuate systematic racial prejudices, making their judgements biased in problematic ways about groups such as African Americans4–7. Although previous research has focused on overt racism in language models, social scientists have argued that racism with a more subtle character has developed over time, particularly in the United States after the civil rights movement8,9. It is unknown whether this covert racism manifests in language models. Here, we demonstrate that language models embody covert racism in the form of dialect prejudice, exhibiting raciolinguistic stereotypes about speakers of African American English (AAE) that are more negative than any human stereotypes about African Americans ever experimentally recorded. By contrast, the language models’ overt stereotypes about African Americans are more positive. Dialect prejudice has the potential for harmful consequences: language models are more likely to suggest that speakers of AAE be assigned less-prestigious jobs, be convicted of crimes and be sentenced to death. Finally, we show that current practices of alleviating racial bias in language models, such as human preference alignment, exacerbate the discrepancy between covert and overt stereotypes, by superficially obscuring the racism that language models maintain on a deeper level. Our findings have far-reaching implications for the fair and safe use of language technology.
Covert Racism in AI: How Language Models Are Reinforcing Outdated Stereotypes | Stanford HAI
Despite advancements in AI, new research reveals that large language models continue to perpetuate harmful racial biases, particularly against speakers of African American English.
Take caution in using LLMs as human surrogates
Recent studies suggest large language models (LLMs) can generate human-like responses, aligning with human behavior in economic experiments, surveys, and political discourse. This has led many to propose that LLMs can be used as surrogates or simulations for humans in social science research. However, LLMs differ fundamentally from humans, relying on probabilistic patterns, absent the embodied experiences or survival objectives that shape human cognition. We assess the reasoning depth of LLMs using the 11-20 money request game. Nearly all advanced approaches fail to replicate human behavior distributions across many models. The causes of failure are diverse and unpredictable, relating to input language, roles, safeguarding, and more. These results warrant caution in using LLMs as surrogates or for simulating human behavior in research.

Large language models outperform humans at estimating society's everyday norms—but hybrids are even better
As AI assistants and social robots enter human environments, their ability to navigate context-dependent social norms is essential to avoid harm and ensure successful collaboration. We evaluate six large language models (LLMs) on their ability to estimate American social norms across 555 everyday scenarios (measured in prior work) and compare these to estimates from 320 humans. LLMs achieve remarkably high accuracy, clearly outperforming the average human. However, the errors LLMs make are systematic; they are similar across runs of the same LLM and even across different LLMs. As a consequence of this homogeneity, aggregating estimates of LLMs produces little improvement. Individual humans make much worse estimates, often defaulting to extreme right-or-wrong judgments even when asked to estimate population averages, but their errors are idiosyncratic and, consequently, aggregating their estimates yields dramatic improvement through wisdom-of-crowds effects. As humans make different errors than LLMs, hybrid ensembles combining both substantially outperform either alone.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Quantifying the Persona Effect in LLM Simulations
Large language models (LLMs) have shown remarkable promise in simulating human language and behavior. This study investigates how integrating persona variables—demographic, social, and behavioral factors—impacts LLMs' ability to simulate diverse perspectives. We find that persona variables account for \ensuremath<10% variance in annotations in existing subjective NLP datasets. Nonetheless, incorporating persona variables via prompting in LLMs provides modest but statistically significant improvements. Persona prompting is most effective in samples where many annotators disagree, but their disagreements are relatively minor. Notably, we find a linear relationship in our setting: the stronger the correlation between persona variables and human annotations, the more accurate the LLM predictions are using persona prompting. In a zero-shot setting, a powerful 70b model with persona prompting captures 81% of the annotation variance achievable by linear regression trained on ground truth annotations. However, for most subjective NLP datasets, where persona variables have limited explanatory power, the benefits of persona prompting are limited.
Do LLMs Exhibit Human-like Response Biases? A Case Study in Survey Design
Abstract One widely cited barrier to the adoption of LLMs as proxies for humans in subjective tasks is their sensitivity to prompt wording—but interestingly, humans also display sensitivities to instruction changes in the form of response biases. We investigate the extent to which LLMs reflect human response biases, if at all. We look to survey design, where human response biases caused by changes in the wordings of “prompts” have been extensively explored in social psychology literature. Drawing from these works, we design a dataset and framework to evaluate whether LLMs exhibit human-like response biases in survey questionnaires. Our comprehensive evaluation of nine models shows that popular open and commercial LLMs generally fail to reflect human-like behavior, particularly in models that have undergone RLHF. Furthermore, even if a model shows a significant change in the same direction as humans, we find that they are sensitive to perturbations that do not elicit significant changes in humans. These results highlight the pitfalls of using LLMs as human proxies, and underscore the need for finer-grained characterizations of model behavior.1

Political Sorting Can Drive AI Models Apart Through User Feedback
Large language models are rapidly becoming an important source of political information. This raises a fundamental question: will AI systems support a shared basis for political knowledge, or lead different political groups to rely on increasingly different models? Political sorting can drive model fragmentation if three conditions hold: politically different users select into different models, learning from user feedback pushes those models apart politically, and the resulting differences shape subsequent model choices. We call this self-reinforcing process the Centrifugal Alignment Spiral. We study its components in three steps. First, we draw on a human experiment showing that political identity predicts model choice. Second, we fine-tune language models on synthetic feedback reflecting predominantly Democratic or Republican preferences. Across five independent runs per model family, paired models diverged on 12-41% of unseen survey questions with large partisan gaps, and in every run the differences moved in the expected political direction; for some models, differentiation extended even to issue areas excluded from training. Pooling feedback across groups instead suppressed divergence. Third, an empirically anchored agent-based model shows what follows when political sorting and model adaptation operate together: models attract politically distinct audiences, learn from them, and diverge further. User feedback can therefore turn political sorting among AI users into durable differences between the models on which they rely for political information.
Do Large Language Models Perform the Way People Expect? Measuring the Human Generalization Function
What makes large language models (LLMs) impressive is also what makes them hard to evaluate: their diversity of uses. To evaluate these models, we must understand the purposes they will be used for. We consider a setting where these deployment decisions are made by people, and in particular, people's beliefs about where an LLM will perform well. We model such beliefs as the consequence of a human generalization function: having seen what an LLM gets right or wrong, people generalize to where else it might succeed. We collect a dataset of 19K examples of how humans make generalizations across 79 tasks from the MMLU and BIG-Bench benchmarks. We show that the human generalization function can be predicted using NLP methods: people have consistent structured ways to generalize. We then evaluate LLM alignment with the human generalization function. Our results show that -- especially for cases where the cost of mistakes is high -- more capable models (e.g. GPT-4) can do worse on the instances people choose to use them for, exactly because they are not aligned with the human generalization function.
Measuring Social Norms of Large Language Models
We present a new challenge to examine whether large language models understand social norms. In contrast to existing datasets, our dataset requires a fundamental understanding of social norms to solve. Our dataset features the largest set of social norm skills, consisting of 402 skills and 12,383 questions covering a wide set of social norms ranging from opinions and arguments to culture and laws. We design our dataset according to the K-12 curriculum. This enables the direct comparison of the social understanding of large language models to humans, more specifically, elementary students. While prior work generates nearly random accuracy on our benchmark, recent large language models such as GPT3.5-Turbo and LLaMA2-Chat are able to improve the performance significantly, only slightly below human performance. We then propose a multi-agent framework based on large language models to improve the models' ability to understand social norms. This method further improves large language models to be on par with humans. Given the increasing adoption of large language models in real-world applications, our finding is particularly important and presents a unique direction for future improvements.
The Chameleon's Limit Investigating Persona Collapse and Homogenization in Large Language Models
The Chameleon's Limit Investigating Persona Collapse and Homogenization in Large Language Models