


The emergence of large language models (LLMs) has made it possible for generative artificial intelligence (AI) to tackle many higher-order cognitive tasks, with critical implications for industry, government, and labor markets. Here, we investigate whether existing, openly-available LLMs can be used to create messages capable of influencing humans’ political attitudes. Across three pre-registered experiments (total N = 4829), participants who read persuasive messages generated by LLMs showed significantly more attitude change across a range of policies - including polarized policies, like an assault weapons ban, a carbon tax, and a paid parental-leave program - relative to control condition participants who read a neutral message. Overall, LLM-generated messages were similarly effective in influencing policy attitudes as messages crafted by lay humans. Participants’ reported perceptions of the authors of the persuasive messages suggest these effects occurred through somewhat distinct causal pathways. While the persuasiveness of LLM-generated messages was associated with perceptions that the author used more facts, evidence, logical reasoning, and a dispassionate voice, the persuasiveness of human-generated messages was associated with perceptions of the author as unique and original. These results demonstrate that recent developments in AI make it possible to create politically persuasive messages quickly, cheaply, and at massive scale.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

On the Conversational Persuasiveness of Large Language Models: A Randomized Controlled Trial
The development and popularization of large language models (LLMs) have raised concerns that they will be used to create tailor-made, convincing arguments to push false or misleading narratives online. Early work has found that language models can generate content perceived as at least on par and often more persuasive than human-written messages. However, there is still limited knowledge about LLMs' persuasive capabilities in direct conversations with human counterparts and how personalization can improve their performance. In this pre-registered study, we analyze the effect of AI-driven persuasion in a controlled, harmless setting. We create a web-based platform where participants engage in short, multiple-round debates with a live opponent. Each participant is randomly assigned to one of four treatment conditions, corresponding to a two-by-two factorial design: (1) Games are either played between two humans or between a human and an LLM; (2) Personalization might or might not be enabled, granting one of the two players access to basic sociodemographic information about their opponent. We found that participants who debated GPT-4 with access to their personal information had 81.7% (p < 0.01; N=820 unique participants) higher odds of increased agreement with their opponents compared to participants who debated humans. Without personalization, GPT-4 still outperforms humans, but the effect is lower and statistically non-significant (p=0.31). Overall, our results suggest that concerns around personalization are meaningful and have important implications for the governance of social media and the design of new online environments.

The potential of generative AI for personalized persuasion at scale
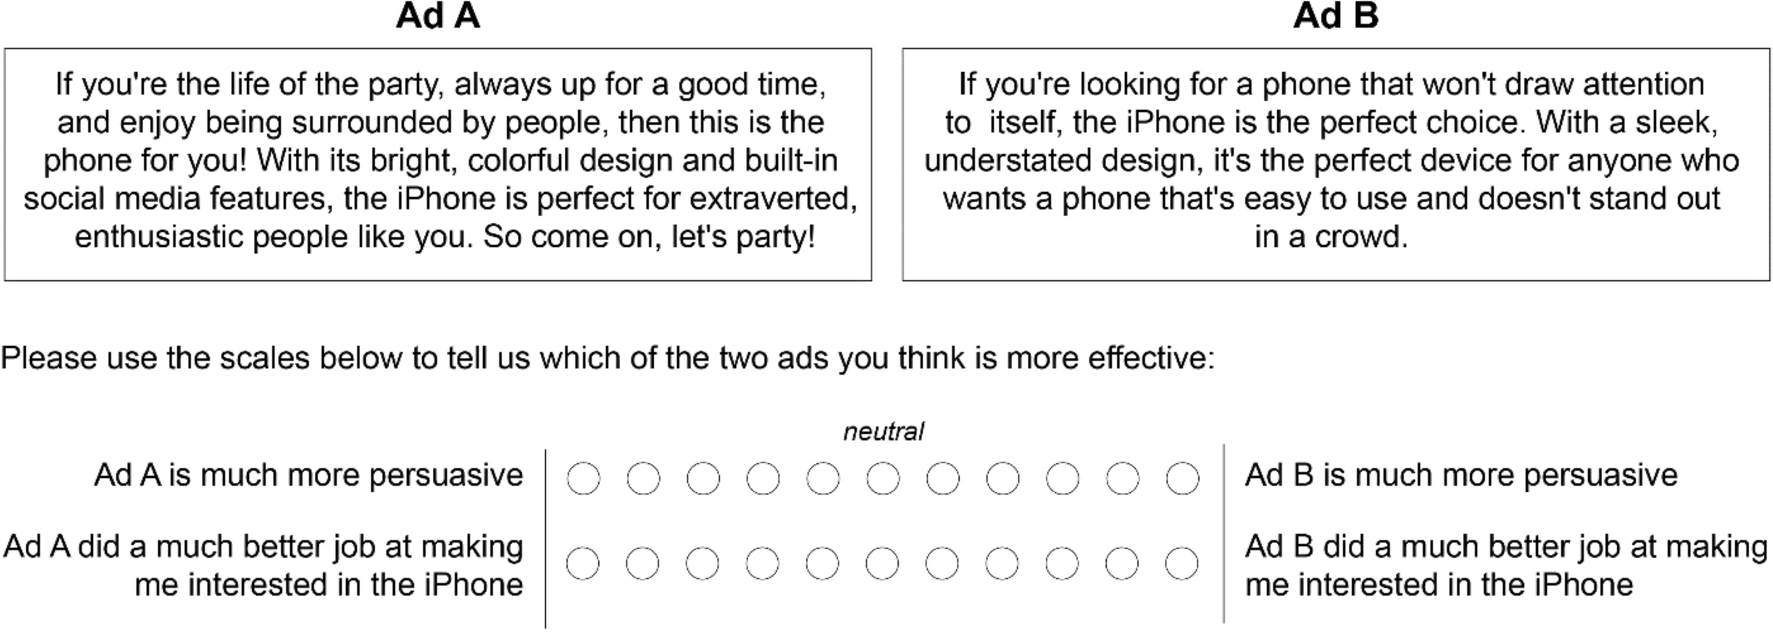
Matching the language or content of a message to the psychological profile of its recipient (known as “personalized persuasion”) is widely considered to be one of the most effective messaging strategies. We demonstrate that the rapid advances in large language models (LLMs), like ChatGPT, could accelerate this influence by making personalized persuasion scalable. Across four studies (consisting of seven sub-studies; total N = 1788), we show that personalized messages crafted by ChatGPT exhibit significantly more influence than non-personalized messages. This was true across different domains of persuasion (e.g., marketing of consumer products, political appeals for climate action), psychological profiles (e.g., personality traits, political ideology, moral foundations), and when only providing the LLM with a single, short prompt naming or describing the targeted psychological dimension. Thus, our findings are among the first to demonstrate the potential for LLMs to automate, and thereby scale, the use of personalized persuasion in ways that enhance its effectiveness and efficiency. We discuss the implications for researchers, practitioners, and the general public.
Biased AI writing assistants shift users’ attitudes on societal issues
Artificial intelligence (AI) writing assistants powered by large language models (LLMs) are increasingly used to make autocomplete suggestions to people as they write text. Can these AI writing assistants affect people’s attitudes in this process? In two large-scale preregistered experiments ( N = 2582), we exposed participants writing about important societal issues to an AI writing assistant that provided biased autocomplete suggestions. When using the AI assistant, the attitudes participants expressed in a posttask survey converged toward the AI’s position. However, a majority of participants were unaware of the AI suggestions’ bias and their influence. Further, the influence of the AI writing assistant was stronger than the influence of similar suggestions presented as static text, showing that the influence is not fully explained by these suggestions, increasing accessibility of the biased information. Last, warning participants about assistants’ bias before or after exposure does not mitigate the attitude-shift effect. , Biased AI writing assistants shift people’s attitudes about societal issues; common interventions do not prevent this influence.
Generative AI Meets Open-Ended Survey Responses: Research Participant Use of AI and Homogenization
The growing popularity of generative artificial intelligence (AI) tools presents new challenges for data quality in online surveys and experiments. This study examines participants’ use of large language models to answer open-ended survey questions and describes empirical tendencies in human versus large language model (LLM)-generated text responses. In an original survey of research participants recruited from a popular online platform for sourcing social science research subjects, 34 percent reported using LLMs to help them answer open-ended survey questions. Simulations comparing human-written responses from three pre-ChatGPT studies with LLM-generated text reveal that LLM responses are more homogeneous and positive, particularly when they describe social groups in sensitive questions. These homogenization patterns may mask important underlying social variation in attitudes and beliefs among human subjects, raising concerns about data validity. Our findings shed light on the scope and potential consequences of participants’ LLM use in online research.

Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.
Persuasion Index: A Theory-Guided Framework for Persuasion Analysis
Identifying persuasive rhetorical cues is critical across domains, from detecting information manipulation and improving AI safety to advancing public health communication. We propose Persuasion...
The governance & behavioral challenges of generative artificial intelligence’s hypercustomization capabilities
Generative artificial intelligence (GenAI) is changing human–machine interactions and the broader information ecosystem. Much as social media algorithms personalize online experiences, GenAI applications can align with user preferences to customize the way individuals interact with information. However, through training, fine-tuning, and prompting, GenAI applications can introduce a new level of customization: hypercustomization. By dynamically tailoring responses to an individual’s explicit and implicit preferences, hypercustomization can reinforce biases, false beliefs, or misconceptions. As a result, it can heighten significant societal challenges, such as the spread of misinformation and political and social polarization. In this article, we explore the risks associated with hypercustomization and the governance and behavioral challenges that might impede effective risk mitigation. These challenges include a lack of transparency in GenAI applications, opacity of the nature of their interactions with users, users’ overreliance on these systems, and the inefficacy of warning messages. We also provide recommendations for overcoming these challenges.
How latent and prompting biases in AI-generated historical narratives influence opinions
Abstract. Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizi
Who Gets Which Message? Auditing Demographic Bias in LLM-Generated Targeted Text
Large language models (LLMs) are increasingly capable of generating personalized, persuasive text at scale, raising new questions about bias and fairness in automated communication. This paper presents the first systematic analysis of how LLMs behave when tasked with demographic-conditioned targeted messaging. We introduce a controlled evaluation framework using three leading models: GPT-4o, Llama-3.3, and Mistral-Large-2.1, across two generation settings: Standalone Generation, which isolates intrinsic demographic effects, and Context-Rich Generation, which incorporates thematic and regional context to emulate realistic targeting. We evaluate generated messages along three dimensions: lexical content, language style, and persuasive framing. We instantiate this framework on climate communication and find consistent age- and gender-based asymmetries across models: male- and youth-targeted messages tend to emphasize more assertive and progressive framing, while female- and senior-targeted messages more often reflect warmth, care, and traditional themes. Contextual prompts systematically amplify these disparities, with persuasion scores being higher for male-targeted messages, while age-related differences vary across models. Our findings demonstrate how demographic stereotypes can surface and intensify in LLM-generated targeted communication, underscoring the need for bias-aware generation pipelines and transparent auditing frameworks that explicitly account for demographic conditioning in socially sensitive applications.
How latent and prompting biases in AI-generated historical narratives influence opinions
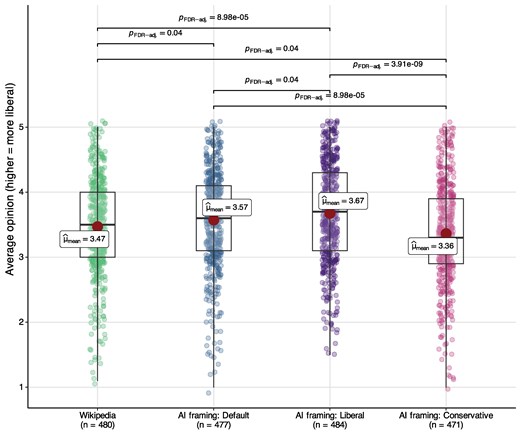
Abstract Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizing messages and dialogues intended to change minds. However, their capacity to influence opinions through subtle, latent ideological framing remains relatively understudied. We investigate whether AI-generated historical summaries affect social and political opinions through a preregistered experiment (N = 1,912). Participants read Wikipedia or GPT-4o summaries of two historical events, with AI summaries maintaining factual accuracy while exhibiting different types of framing biases. Default AI summaries led to more liberal opinions compared with Wikipedia, demonstrating the persuasive capability of LLM's latent biases. Summaries purposefully induced with a liberal framing also led to more liberal opinions, regardless of readers’ ideologies. Summaries constructed with a conservative framing produced conservative shifts primarily among conservative readers. These findings demonstrate that the use of AI for learning history can influence opinions through both intrinsic and intentional framing mechanisms, even when the content remains factually accurate. As AI becomes integral to information acquisition, recognizing pathways of influence based not only on user-manipulated content but also on models’ latent biases is essential for understanding AI's broader societal impacts.
Just Asking Questions: Doing Our Own Research on Conspiratorial Ideation by Generative AI Chatbots
Interactive chat systems that build on artificial intelligence frameworks are increasingly ubiquitous and embedded into search engines, Web browsers, and operating systems, or are available on websites and apps. Researcher efforts have sought to understand the limitations and potential for harm of generative AI, which we contribute to here. Conducting a systematic review of six AI-powered chat systems (ChatGPT 3.5; ChatGPT 4 Mini; Microsoft Copilot in Bing; Google Search AI; Perplexity; and Grok in Twitter/X), this study examines how these leading products respond to questions related to conspiracy theories. This follows the platform policy implementation audit approach established by Glazunova et al. (2023). We select five well-known and comprehensively debunked conspiracy theories and four emerging conspiracy theories that relate to breaking news events at the time of data collection. Our findings demonstrate that the extent of safety guardrails against conspiratorial ideation in generative AI chatbots differs markedly, depending on chatbot model and conspiracy theory. Our observations indicate that safety guardrails in AI chatbots are often very selectively designed: generative AI companies appear to focus especially on ensuring that their products are not seen to be racist; they also appear to pay particular attention to conspiracy theories that address topics of substantial national trauma such as 9/11 or relate to well-established political issues. Future work should include an ongoing effort extended to further platforms, multiple languages, and a range of conspiracy theories extending well beyond the United States.
A meta-analysis of the persuasive power of large language models
Large language models (LLMs) are increasingly used for persuasion, such as in political communication and marketing, where they affect how people think, choose, and act. Yet, empirical findings on the effectiveness of LLMs in persuasion compared to humans remain inconsistent. The aim of this study was to systematically review and meta-analytically assess whether LLMs differ from humans in persuasive effectiveness, and under which contextual conditions LLMs are particularly effective. We identified 7 studies with 17,422 participants primarily recruited from English-speaking countries and 12 effect size estimates. Egger’s test indicated potential small-study effects ($$p =.018$$), but the trim-and-fill analysis did not impute any missing studies, suggesting a low risk of publication bias. We then compute the standardized effect sizes based on Hedges’ g. The results show no significant overall difference in persuasive performance between LLMs and humans ($$g = 0.02$$, $$p =.530$$). However, we observe substantial heterogeneity across studies ($$I^2 = 75.97\%$$), suggesting that persuasiveness strongly depends on contextual factors. In separate exploratory moderator analyses, no individual factor (e.g., LLM model, conversation design, or domain) reached statistical significance, which may be due to the limited number of studies. When considered jointly in a combined model, these factors explained a large proportion of the between-study variance ($$R^2 = 81.93\%$$), and residual heterogeneity is low ($$I^2 = 35.51\%$$). Although based on a small number of studies, this suggests that differences in LLM model, conversation design, and domain are important contextual factors in shaping persuasive performance, and that single-factor tests may understate their influence. Our results highlight that LLMs can match human performance in persuasion, but their success depends strongly on how they are implemented and embedded in communication contexts.
How malicious AI swarms can threaten democracy
The fusion of agentic AI and LLMs marks a new frontier in information warfare , Advances in artificial intelligence (AI) offer the prospect of manipulating beliefs and behaviors on a population-wide level ( 1 ). Large language models (LLMs) and autonomous agents ( 2 ) let influence campaigns reach unprecedented scale and precision. Generative tools can expand propaganda output without sacrificing credibility ( 3 ) and inexpensively create falsehoods that are rated as more human-like than those written by humans ( 3 , 4 ). Techniques meant to refine AI reasoning, such as chain-of-thought prompting, can be used to generate more convincing falsehoods. Enabled by these capabilities, a disruptive threat is emerging: swarms of collaborative, malicious AI agents. Fusing LLM reasoning with multiagent architectures ( 2 ), these systems are capable of coordinating autonomously, infiltrating communities, and fabricating consensus efficiently. By adaptively mimicking human social dynamics, they threaten democracy. Because the resulting harms stem from design, commercial incentives, and governance, we prioritize interventions at multiple leverage points, focusing on pragmatic mechanisms over voluntary compliance.
