

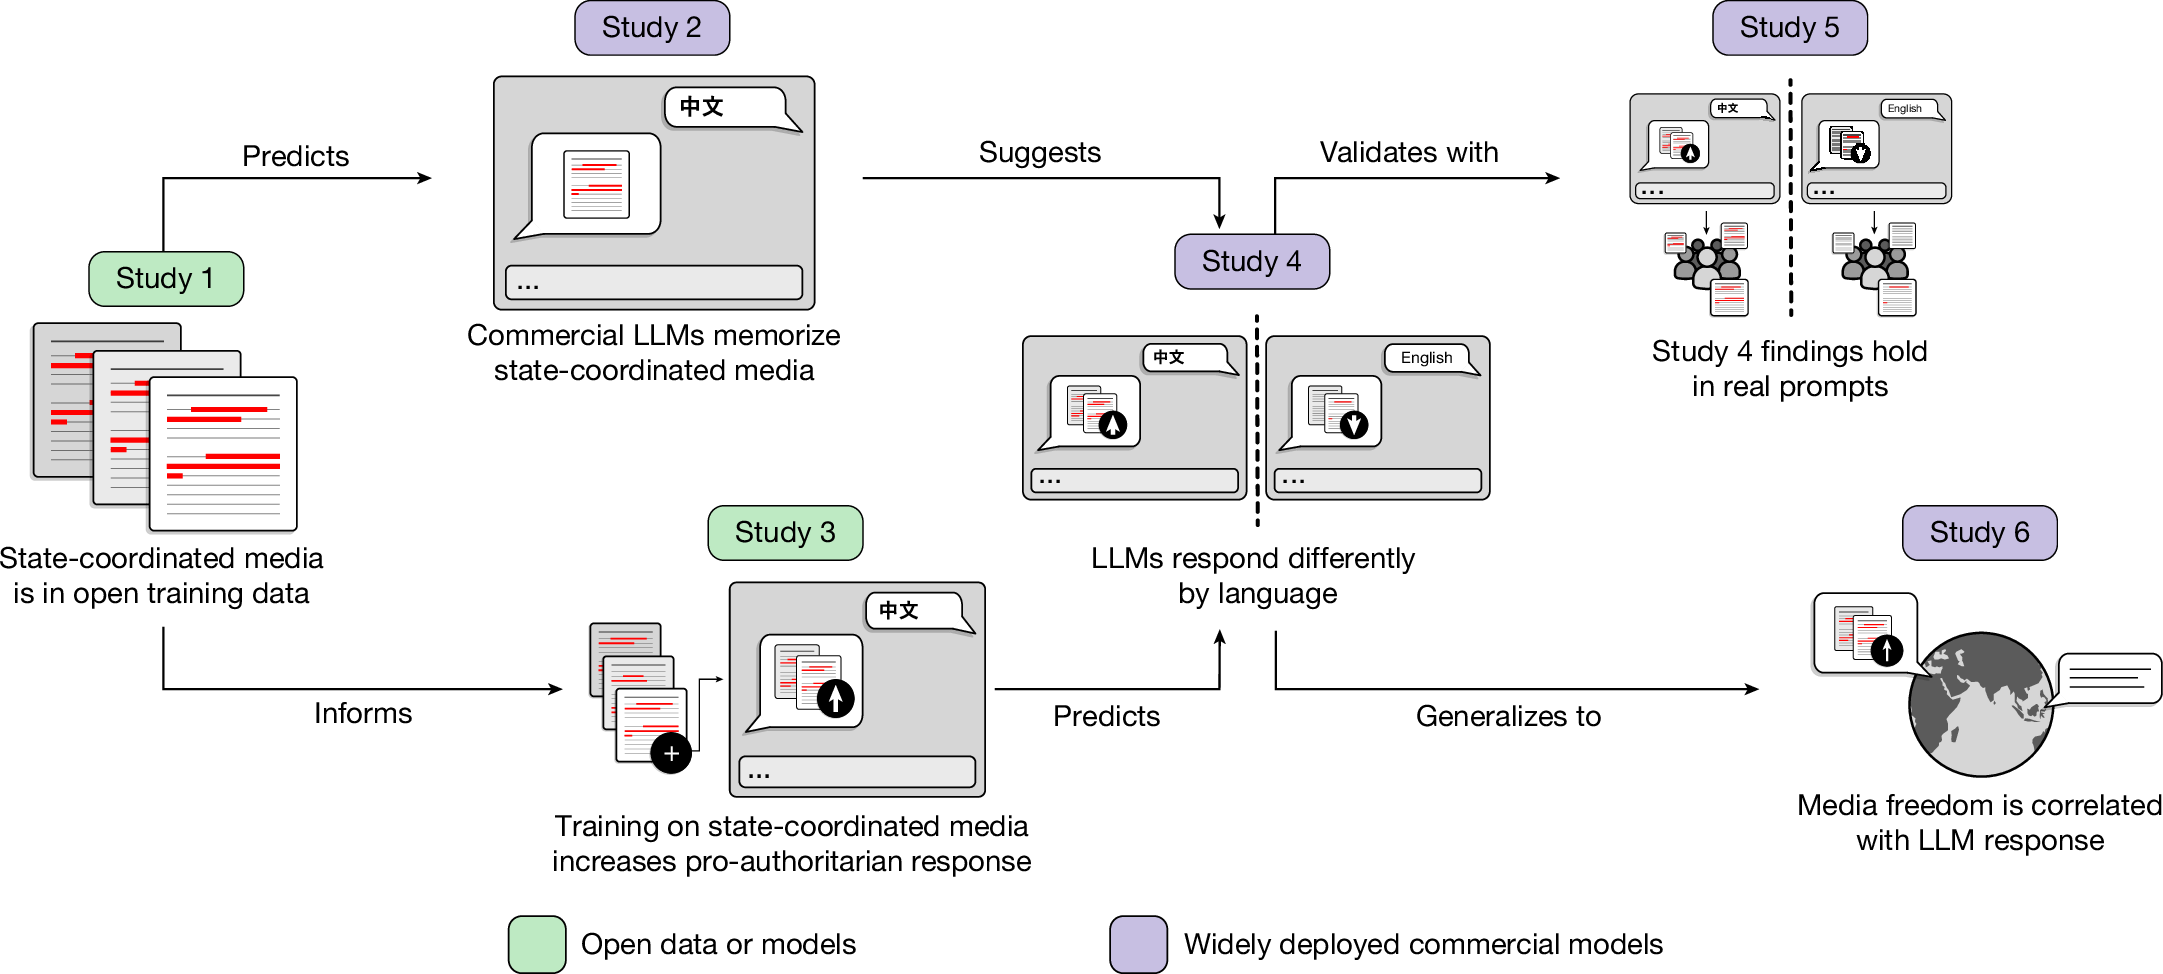
Millions of people around the world query large language models (LLMs) for information. Although several studies have compellingly documented the persuasive potential of these models1–10, there is limited evidence of who or what influences the models themselves, leading to a flurry of concerns about which companies and governments build and regulate the models. Here we show through six studies that government control of the media across the world already influences the output of LLMs via their training data. We use a cross-national audit to show that LLMs exhibit a stronger pro-government valence in the languages of countries with lower media freedom than in those with higher media freedom. This result is correlational, so to triangulate the specific mechanism of how state media control can influence LLMs, we develop a multi-part case study on China’s media. We demonstrate that media scripted and curated by the Chinese state appears in LLM training datasets. To evaluate the plausible effect of this inclusion, we use an open-weight model to show that additional pretraining on Chinese state-coordinated media generates more positive answers to prompts about Chinese political institutions and leaders. We link this phenomenon to commercial models through two audit studies demonstrating that prompting models in Chinese generates more positive responses about China’s institutions and leaders than do the same queries in English. The combination of influence and persuasive potential across languages suggests the troubling conclusion that states and powerful institutions have increased strategic incentives to leverage media control in the hopes of shaping LLM output.
State media control influences large language models
Millions of people around the world query large language models (LLMs) for information. Although several studies have compellingly documented the persuasive potential of these models1–10, there is limited evidence of who or what influences the models themselves, leading to a flurry of concerns about which companies and governments build and regulate the models. Here we show through six studies that government control of the media across the world already influences the output of LLMs via their training data. We use a cross-national audit to show that LLMs exhibit a stronger pro-government valence in the languages of countries with lower media freedom than in those with higher media freedom. This result is correlational, so to triangulate the specific mechanism of how state media control can influence LLMs, we develop a multi-part case study on China’s media. We demonstrate that media scripted and curated by the Chinese state appears in LLM training datasets. To evaluate the plausible effect of this inclusion, we use an open-weight model to show that additional pretraining on Chinese state-coordinated media generates more positive answers to prompts about Chinese political institutions and leaders. We link this phenomenon to commercial models through two audit studies demonstrating that prompting models in Chinese generates more positive responses about China’s institutions and leaders than do the same queries in English. The combination of influence and persuasive potential across languages suggests the troubling conclusion that states and powerful institutions have increased strategic incentives to leverage media control in the hopes of shaping LLM output.
Replication Data for "State Media Control Influences Large Language Models"
Replication dataset for "State Media Control Influences Large Language Models," forthcoming in Nature (https://doi.org/10.1038/s41586-026-10506-7). We show through six studies that government control of the media across the world influences the output of large language models (LLMs) via their training data.
State Media Control Influences Large Language Models – State Media & LLMs
Hannah Waight1,2, Eddie Yang1,3, Yin Yuan4, Solomon Messing5, Margaret E. Roberts4, Brandon M. Stewart6, Joshua A. Tucker5,7
Language Models Trained on State Media Sources Launder Propaganda
Tech Policy Press is a nonprofit media and community venture intended to provoke new ideas, debate and discussion at the intersection of technology and democracy. We publish opinion and analysis.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.
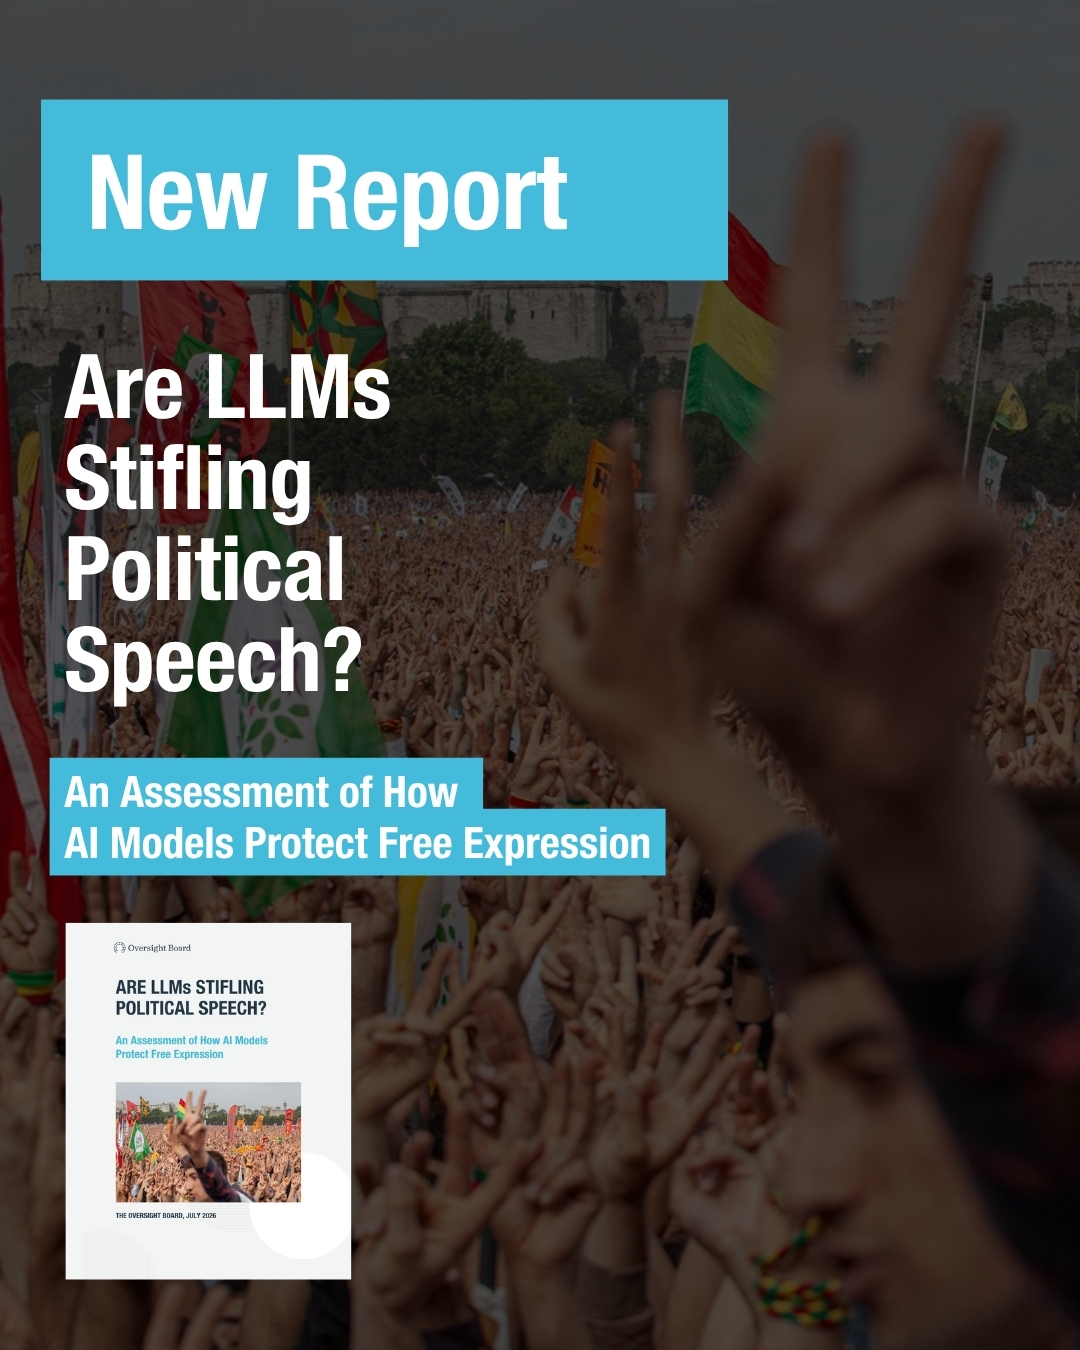
Are LLMs Stifling Political Speech? An Assessment of How AI Models Protect Free Expression | Oversight Board
The Oversight Board’s first evaluation of large language models (LLMs) shows that some of the world’s most-used models from Anthropic, DeepSeek, Google, Meta
How a Chinese marketing network quietly injects political narratives into Taiwanese lifestyle content
A new investigation by Reporters Without Borders (RSF) reveals how certain Facebook pages posing as lifestyle hubs for hobbies and health tips inject Beijing’s political narratives into their feeds to influence public opinion in Taiwan. These pages are tied to the China-based digital marketing company Wubianjie, which blends entertainment, disinformation and political messaging in cognitive warfare campaigns that are difficult to detect.

AI Large Language Model Training: The Potential Risks of Ideological Skewing — PSG Consulting
LLMs (AI Large Language Models) have become part of everyday life. Systems such as ChatGPT, Claude, Gemini, Meta AI (Llama) and X.ai's Grok handle billions of interactions daily. They increasingly shape what information people encounter and in what order, subtly deciding what's important and even what is true, sometimes without users realizing it. Because LLMs wield growing power over information exposure, it is vital to recognize the political and ideological structures at multiple stages of their design, and to identify manipulation risks.

Manufacturing Consent: The Political Economy of the Mass Media
A bold and eye-opening exposé on how power and propaganda distort the news, now more relevant than ever • With an updated introduction“[A] compelling indictment of the news media’s role in covering up errors and deceptions in American foreign policy.”—The New York Times Book Review Renowned scholars Edward S. Herman and Noam Chomsky reveal how U.S. news media, far from being independent watchdogs, often function as tools of elite influence. With probing analysis, they present their Propaganda Model, a framework that explains how systemic bias shapes the stories we’re told, the voices we hear, and the truths that remain hidden.Through deeply researched case studies, from the Vietnam War to coverage of “worthy” vs. “unworthy” victims, Manufacturing Consent exposes the structural forces that drive news organizations to reinforce power rather than question it. It’s a sobering portrait of a media system more interested in maintaining order than informing the public.This edition includes an introduction updating key examples and expanding the Propaganda Model’s relevance to issues like the coverage of NAFTA, the media’s treatment of global protests, and environmental regulation.Manufacturing Consent is a powerful assessment of how propagandistic the U.S. mass media are, how they systematically fail to live up to their self-image as providers of the kind of information that people need to make sense of the world, and how we can understand their function in a radically new way.Whether you’re a student, activist, or citizen looking to see beyond the headlines, this book will transform how you understand the media—and the world around you.

State Media Monitor Global Dataset 2025
This dataset provides comprehensive information on the governance, funding, and editorial independence of state and public media outlets worldwide. In 2025, the State Media Monitor covers 170 countries, tracking changes in media governance models, funding mechanisms, and degrees of political control. The dataset underpins the annual State Media Monitor Global Study and supports comparative research in journalism, media policy, and governance. Access the full dataset here: https://www.statemediamonitor.com
People are getting their news from AI – and it’s altering their views
Even when information is factually accurate, how it’s presented can introduce subtle biases. As large language models increasingly bring people the news, this bias is a looming problem.
People are getting their news from AI – and it’s altering their views
Even when information is factually accurate, how it’s presented can introduce subtle biases. As large language models increasingly bring people the news, this bias is a looming problem.
Grok in the Wild: Characterizing the Roles and Uses of Large Language Models on Social Media
xAI's large language model, Grok, is called by millions of people each week on the social media platform X. Prior work characterizing how large language models are used has focused on private, one-on-one interactions. Grok's deployment on X represents a major departure from this setting, with interactions occurring in a public social space. In this paper, we systematically sample three months of interaction data to investigate how, when, and to what effect Grok is used on X. At the platform level, we find that Grok responds to 62% of requests, that the majority (51%) are in English, and that engagement is low, with half of Grok's responses receiving 20 or fewer views after 48 hours. We also inductively build a taxonomy of 10 roles that LLMs play in mediating social interactions and use these roles to analyze 41,735 interactions with Grok on X. We find that Grok most often serves as an information provider but, in contrast to LLM use in private one-on-one settings, also takes on roles related to dispute management, such as truth arbiter, advocate, and adversary. Finally, we characterize the population of X users who prompted Grok and find that their self-expressed interests are closely related to the roles the model assumes in the corresponding interactions. Our findings provide an initial quantitative description of human-AI interactions on X, and a broader understanding of the diverse roles that large language models might play in our online social spaces.