

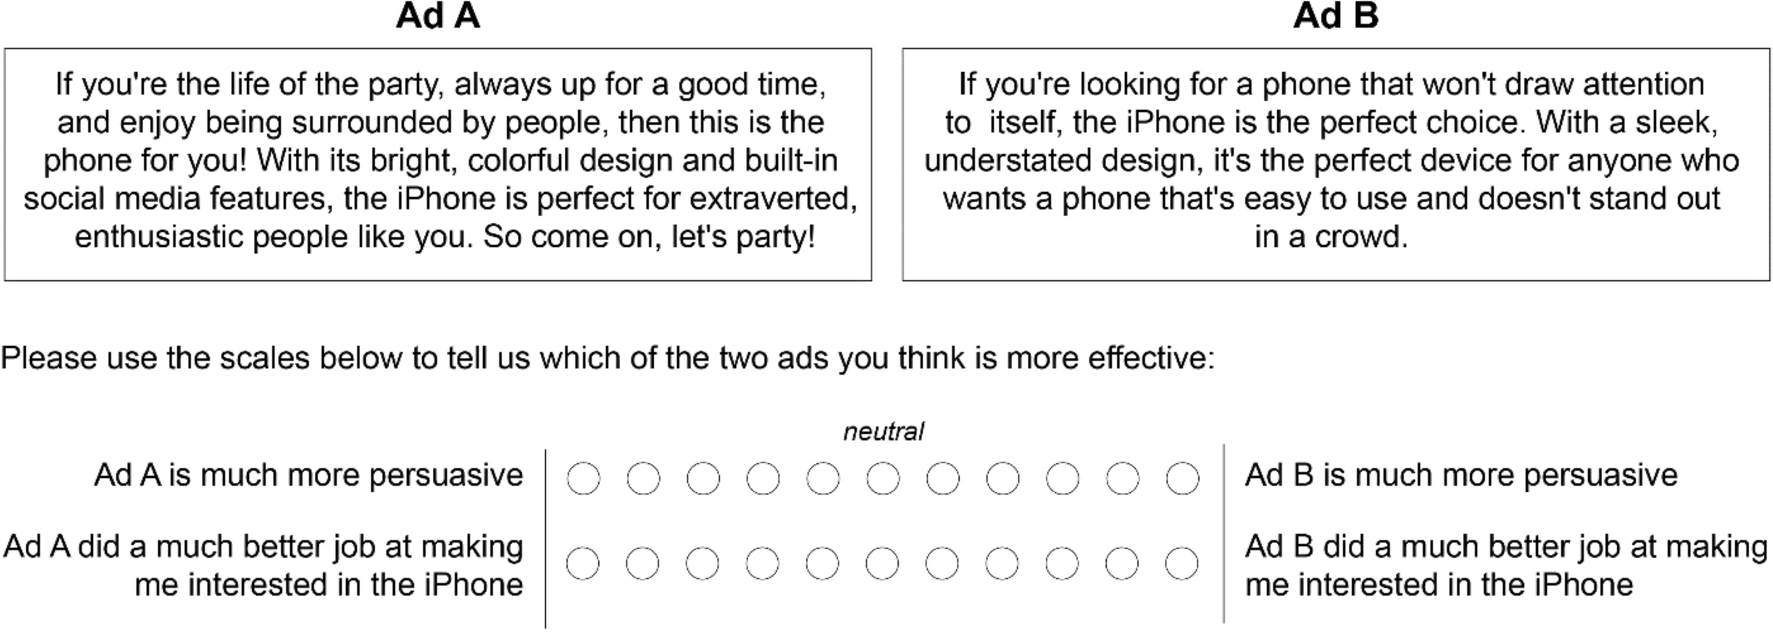
Matching the language or content of a message to the psychological profile of its recipient (known as “personalized persuasion”) is widely considered to be one of the most effective messaging strategies. We demonstrate that the rapid advances in large language models (LLMs), like ChatGPT, could accelerate this influence by making personalized persuasion scalable. Across four studies (consisting of seven sub-studies; total N = 1788), we show that personalized messages crafted by ChatGPT exhibit significantly more influence than non-personalized messages. This was true across different domains of persuasion (e.g., marketing of consumer products, political appeals for climate action), psychological profiles (e.g., personality traits, political ideology, moral foundations), and when only providing the LLM with a single, short prompt naming or describing the targeted psychological dimension. Thus, our findings are among the first to demonstrate the potential for LLMs to automate, and thereby scale, the use of personalized persuasion in ways that enhance its effectiveness and efficiency. We discuss the implications for researchers, practitioners, and the general public.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

On the Conversational Persuasiveness of Large Language Models: A Randomized Controlled Trial
The development and popularization of large language models (LLMs) have raised concerns that they will be used to create tailor-made, convincing arguments to push false or misleading narratives online. Early work has found that language models can generate content perceived as at least on par and often more persuasive than human-written messages. However, there is still limited knowledge about LLMs' persuasive capabilities in direct conversations with human counterparts and how personalization can improve their performance. In this pre-registered study, we analyze the effect of AI-driven persuasion in a controlled, harmless setting. We create a web-based platform where participants engage in short, multiple-round debates with a live opponent. Each participant is randomly assigned to one of four treatment conditions, corresponding to a two-by-two factorial design: (1) Games are either played between two humans or between a human and an LLM; (2) Personalization might or might not be enabled, granting one of the two players access to basic sociodemographic information about their opponent. We found that participants who debated GPT-4 with access to their personal information had 81.7% (p < 0.01; N=820 unique participants) higher odds of increased agreement with their opponents compared to participants who debated humans. Without personalization, GPT-4 still outperforms humans, but the effect is lower and statistically non-significant (p=0.31). Overall, our results suggest that concerns around personalization are meaningful and have important implications for the governance of social media and the design of new online environments.

LLM-generated messages can persuade humans on policy issues
The emergence of large language models (LLMs) has made it possible for generative artificial intelligence (AI) to tackle many higher-order cognitive tasks, with critical implications for industry, government, and labor markets. Here, we investigate whether existing, openly-available LLMs can be used to create messages capable of influencing humans’ political attitudes. Across three pre-registered experiments (total N = 4829), participants who read persuasive messages generated by LLMs showed significantly more attitude change across a range of policies - including polarized policies, like an assault weapons ban, a carbon tax, and a paid parental-leave program - relative to control condition participants who read a neutral message. Overall, LLM-generated messages were similarly effective in influencing policy attitudes as messages crafted by lay humans. Participants’ reported perceptions of the authors of the persuasive messages suggest these effects occurred through somewhat distinct causal pathways. While the persuasiveness of LLM-generated messages was associated with perceptions that the author used more facts, evidence, logical reasoning, and a dispassionate voice, the persuasiveness of human-generated messages was associated with perceptions of the author as unique and original. These results demonstrate that recent developments in AI make it possible to create politically persuasive messages quickly, cheaply, and at massive scale.

Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.
A Model of Multi-turn Human Persuadability Using Probabilistic Belief Tracing
Large language models can shift human beliefs across high-stakes domains, but most persuasion studies rely on pre/post belief change. These endpoint measures identify whether persuasion occurred, yet miss where and how beliefs moved within a dialogue. We present PERSUASIONTRACE, a framework for studying persuasion in human–LLM interaction. Built on a web-based experimental platform, PERSUASIONTRACE contributes a tool for multi-turn persuasion studies and a process-level evaluation protocol: it records multi-turn belief reports from human or simulated targets of persuasion, annotates persuader turns with rhetorical dimensions (logos/pathos/ethos), and evaluates simulators by fidelity to real human belief dynamics. Using this framework, we find that human targets group into two clusters of multi-turn belief updates and exhibit susceptibility to rhetorical strategies, and that LLMs are persuasive across generic and personalized topics, text and audio modalities, and multi-turn interactions. Prior work has chiefly used vanilla-prompted LLMs to simulate human targets, but we show that these simulators fail to replicate human belief dynamics. We introduce a Bayesian-network simulated target that maintains an explicit latent belief state over time so each persuader message yields cognitively realistic belief updates. In human-likeness evaluation, our Bayesian target scores near a human reference (81 vs 80), while baseline LLM targets score substantially lower (64). PERSUASIONTRACE reframes persuasion evaluation from endpoint movement alone to process fidelity, providing a stronger basis for scientific analysis and safer optimization of persuasive systems.
Who Gets Which Message? Auditing Demographic Bias in LLM-Generated Targeted Text
Large language models (LLMs) are increasingly capable of generating personalized, persuasive text at scale, raising new questions about bias and fairness in automated communication. This paper presents the first systematic analysis of how LLMs behave when tasked with demographic-conditioned targeted messaging. We introduce a controlled evaluation framework using three leading models: GPT-4o, Llama-3.3, and Mistral-Large-2.1, across two generation settings: Standalone Generation, which isolates intrinsic demographic effects, and Context-Rich Generation, which incorporates thematic and regional context to emulate realistic targeting. We evaluate generated messages along three dimensions: lexical content, language style, and persuasive framing. We instantiate this framework on climate communication and find consistent age- and gender-based asymmetries across models: male- and youth-targeted messages tend to emphasize more assertive and progressive framing, while female- and senior-targeted messages more often reflect warmth, care, and traditional themes. Contextual prompts systematically amplify these disparities, with persuasion scores being higher for male-targeted messages, while age-related differences vary across models. Our findings demonstrate how demographic stereotypes can surface and intensify in LLM-generated targeted communication, underscoring the need for bias-aware generation pipelines and transparent auditing frameworks that explicitly account for demographic conditioning in socially sensitive applications.
Commercial Persuasion in AI-Mediated Conversations
As Large Language Models (LLMs) become a primary interface between users and the web, companies face growing economic incentives to embed commercial influence into AI-mediated conversations. We present two preregistered experiments (N = 2,012) in which participants selected a book to receive from a large eBook catalog using either a traditional search engine or a conversational LLM agent powered by one of five frontier models. Unbeknownst to participants, a fifth of all products were randomly designated as sponsored and promoted in different ways. We find that LLM-driven persuasion nearly triples the rate at which users select sponsored products compared to traditional search placement (61.2% vs. 22.4%), while the vast majority of participants fail to detect any promotional steering. Explicit "Sponsored" labels do not significantly reduce persuasion, and instructing the model to conceal its intent makes its influence nearly invisible (detection accuracy < 10%). Altogether, our results indicate that conversational AI can covertly redirect consumer choices at scale, and that existing transparency mechanisms may be insufficient to protect users.
Generative AI Meets Open-Ended Survey Responses: Research Participant Use of AI and Homogenization
The growing popularity of generative artificial intelligence (AI) tools presents new challenges for data quality in online surveys and experiments. This study examines participants’ use of large language models to answer open-ended survey questions and describes empirical tendencies in human versus large language model (LLM)-generated text responses. In an original survey of research participants recruited from a popular online platform for sourcing social science research subjects, 34 percent reported using LLMs to help them answer open-ended survey questions. Simulations comparing human-written responses from three pre-ChatGPT studies with LLM-generated text reveal that LLM responses are more homogeneous and positive, particularly when they describe social groups in sensitive questions. These homogenization patterns may mask important underlying social variation in attitudes and beliefs among human subjects, raising concerns about data validity. Our findings shed light on the scope and potential consequences of participants’ LLM use in online research.

The benefits, risks and bounds of personalizing the alignment of large language models to individuals
Large language models (LLMs) undergo ‘alignment’ so that they better reflect human values or preferences, and are safer or more useful. However, alignment is intrinsically difficult because the hundreds of millions of people who now interact with LLMs have different preferences for language and conversational norms, operate under disparate value systems and hold diverse political beliefs. Typically, few developers or researchers dictate alignment norms, risking the exclusion or under-representation of various groups. Personalization is a new frontier in LLM development, whereby models are tailored to individuals. In principle, this could minimize cultural hegemony, enhance usefulness and broaden access. However, unbounded personalization poses risks such as large-scale profiling, privacy infringement, bias reinforcement and exploitation of the vulnerable. Defining the bounds of responsible and socially acceptable personalization is a non-trivial task beset with normative challenges. This article explores ‘personalized alignment’, whereby LLMs adapt to user-specific data, and highlights recent shifts in the LLM ecosystem towards a greater degree of personalization. Our main contribution explores the potential impact of personalized LLMs via a taxonomy of risks and benefits for individuals and society at large. We lastly discuss a key open question: what are appropriate bounds of personalization and who decides? Answering this normative question enables users to benefit from personalized alignment while safeguarding against harmful impacts for individuals and society.

GermanPartiesQA: Benchmarking Commercial Large Language Models and AI Companions for Political Alignment and Sycophancy
Large language models (LLMs) are increasingly shaping citizens’ information ecosystems. Products incorporating LLMs, such as chatbots and AI Companions, are now widely used for decision support and information retrieval, including in sensitive domains, raising concerns about hidden biases and growing potential to shape individual decisions and public opinion. This paper introduces GermanPartiesQA, a benchmark of 418 political statements from German Voting Advice Applications across 11 elections to evaluate six commercial LLMs. We evaluate their political alignment based on role-playing experiments with political personas. Our evaluation reveals three specific findings: (1) Factual limitations: LLMs show limited ability to accurately generate factual party positions, particularly for centrist parties. (2) Model-specific ideological alignment: We identify consistent alignment patterns and degree of political steerability for each model across temperature settings and experiments. (3) Claim of sycophancy: While models adjust to political personas during role-play, we find this reflects persona-based steerability rather than the increasingly popular, yet contested concept of sycophancy. Our study contributes to evaluating the political alignment of closed-source LLMs that are increasingly embedded in electoral decision support tools and AI Companion chatbots.
GermanPartiesQA: Benchmarking Commercial Large Language Models and AI Companions for Political Alignment and Sycophancy
Large language models (LLMs) are increasingly shaping citizens’ information ecosystems. Products incorporating LLMs, such as chatbots and AI Companions, are now widely used for decision support and information retrieval, including in sensitive domains, raising concerns about hidden biases and growing potential to shape individual decisions and public opinion. This paper introduces GermanPartiesQA, a benchmark of 418 political statements from German Voting Advice Applications across 11 elections to evaluate six commercial LLMs. We evaluate their political alignment based on role-playing experiments with political personas. Our evaluation reveals three specific findings: (1) Factual limitations: LLMs show limited ability to accurately generate factual party positions, particularly for centrist parties. (2) Model-specific ideological alignment: We identify consistent alignment patterns and degree of political steerability for each model across temperature settings and experiments. (3) Claim of sycophancy: While models adjust to political personas during role-play, we find this reflects persona-based steerability rather than the increasingly popular, yet contested concept of sycophancy. Our study contributes to evaluating the political alignment of closed-source LLMs that are increasingly embedded in electoral decision support tools and AI Companion chatbots.
How latent and prompting biases in AI-generated historical narratives influence opinions
Abstract. Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizi
A Survey of Personalized Large Language Models: Progress and Future Directions
Large Language Models (LLMs) excel in handling general knowledge tasks, yet they struggle with user-specific personalization, such as understanding individual emotions, writing styles, and preferences. Personalized Large Language Models (PLLMs) tackle these challenges by leveraging individual user data, such as user profiles, historical dialogues, content, and interactions, to deliver responses that are contextually relevant and tailored to each user's specific needs. This is a highly valuable research topic, as PLLMs can significantly enhance user satisfaction and have broad applications in conversational agents, recommendation systems, emotion recognition, medical assistants, and more. This survey reviews recent advancements in PLLMs from three technical perspectives: prompting for personalized context (input level), finetuning for personalized adapters (model level), and alignment for personalized preferences (objective level). To provide deeper insights, we also discuss current limitations and outline several promising directions for future research. Updated information about this survey can be found at the https://github.com/JiahongLiu21/Awesome-Personalized-Large-Language-Models.
Quantifying the Persona Effect in LLM Simulations
Large language models (LLMs) have shown remarkable promise in simulating human language and behavior. This study investigates how integrating persona variables—demographic, social, and behavioral factors—impacts LLMs' ability to simulate diverse perspectives. We find that persona variables account for \ensuremath<10% variance in annotations in existing subjective NLP datasets. Nonetheless, incorporating persona variables via prompting in LLMs provides modest but statistically significant improvements. Persona prompting is most effective in samples where many annotators disagree, but their disagreements are relatively minor. Notably, we find a linear relationship in our setting: the stronger the correlation between persona variables and human annotations, the more accurate the LLM predictions are using persona prompting. In a zero-shot setting, a powerful 70b model with persona prompting captures 81% of the annotation variance achievable by linear regression trained on ground truth annotations. However, for most subjective NLP datasets, where persona variables have limited explanatory power, the benefits of persona prompting are limited.
Personalization Increases Affective Alignment but Has Role-Dependent Effects on Epistemic Independence in LLMs
Large Language Models (LLMs) are prone to sycophantic behavior, uncritically conforming to user beliefs. As models increasingly condition responses on user-specific context (personality traits, preferences, conversation history), they gain information to tailor agreement more effectively. Understanding how personalization modulates sycophancy is critical, yet systematic evaluation across models and contexts remains limited. We present a rigorous evaluation of personalization's impact on LLM sycophancy across nine frontier models and five benchmark datasets spanning advice, moral judgment, and debate contexts. We find that personalization generally increases affective alignment (emotional validation, hedging/deference), but affects epistemic alignment (belief adoption, position stability, resistance to influence) with context-dependent role modulation. When the LLM's role is to give advice, personalization strengthens epistemic independence (models challenge user presuppositions). When its role is that of a social peer, personalization decreases epistemic independence. In this role, extensively personalized user challenges causing LLMs to abandon their position at significantly higher rates. Robustness tests confirm that the effects are driven by personalized conditioning, not by additional input tokens per se or demographic information alone. Our work provides measurement frameworks for evaluating personalized AI systems, demonstrates the necessity of role-sensitive evaluation, and establishes a novel benchmark to assess goal alignment.
AI is More Persuasive Than People in Online Debates - Slashdot
Chatbots are more persuasive in online debates than people -- especially when they are able to personalize their arguments using information about their opponent. From a report: The finding, published in Nature Human Behaviour on 19 May, highlights how large language models (LLMs) could be used to i...
