


This work advances and tests a theory of how news information evolves as it is successively retold by consumers. Drawing on data from over 11,000 participants across ten experiments, the authors offer evidence that when news is repeatedly retold, it undergoes a stylistic transformation termed “disagreeable personalization,” wherein original facts are increasingly supplanted by opinions and interpretations with a slant toward negativity. The central thesis is that when retellers believe they are more (vs. less) knowledgeable than their recipient about the information they are relaying, they feel more compelled to provide guidance on its meaning and to do so in a persuasive manner. This enhanced motivation to guide persuasively, in turn, leads retellers to not only select the subset of facts they deem most essential but, critically, to provide their interpretations and opinions on those facts, with negativity being used as a means of grabbing their audience’s attention. Implications of this work for research on retelling and consumer information diffusion are explored.
How latent and prompting biases in AI-generated historical narratives influence opinions
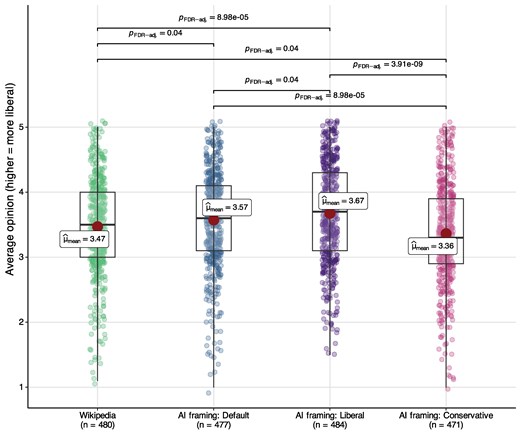
Abstract Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizing messages and dialogues intended to change minds. However, their capacity to influence opinions through subtle, latent ideological framing remains relatively understudied. We investigate whether AI-generated historical summaries affect social and political opinions through a preregistered experiment (N = 1,912). Participants read Wikipedia or GPT-4o summaries of two historical events, with AI summaries maintaining factual accuracy while exhibiting different types of framing biases. Default AI summaries led to more liberal opinions compared with Wikipedia, demonstrating the persuasive capability of LLM's latent biases. Summaries purposefully induced with a liberal framing also led to more liberal opinions, regardless of readers’ ideologies. Summaries constructed with a conservative framing produced conservative shifts primarily among conservative readers. These findings demonstrate that the use of AI for learning history can influence opinions through both intrinsic and intentional framing mechanisms, even when the content remains factually accurate. As AI becomes integral to information acquisition, recognizing pathways of influence based not only on user-manipulated content but also on models’ latent biases is essential for understanding AI's broader societal impacts.
The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Sharing of misinformation is habitual, not just lazy or biased
Why do people share misinformation on social media? In this research ( N = 2,476), we show that the structure of online sharing built into social platforms is more important than individual deficits in critical reasoning and partisan bias—commonly cited drivers of misinformation. Due to the reward-based learning systems on social media, users form habits of sharing information that attracts others' attention. Once habits form, information sharing is automatically activated by cues on the platform without users considering response outcomes such as spreading misinformation. As a result of user habits, 30 to 40% of the false news shared in our research was due to the 15% most habitual news sharers. Suggesting that sharing of false news is part of a broader response pattern established by social media platforms, habitual users also shared information that challenged their own political beliefs. Finally, we show that sharing of false news is not an inevitable consequence of user habits: Social media sites could be restructured to build habits to share accurate information.
Illusion of knowledge through Facebook news? Effects of snack news in a news feed on perceived knowledge, attitude strength, and willingness for discussions
Research indicates that using social network sites as a source for news increases perceived knowledge even if, objectively, people fail to acquire knowledge. This might result from the frequent repetition of topics in news posts caused by multiple news outlets posting about the same news topics and the algorithm that favors similar postings. These repeated encounters can have a positive effect on the perception of knowing more, even if actual learning hardly occurs. An experiment (N = 810, representative of German Internet users) tested these assumptions. Participants were assigned to one of four groups and received a news feed with no information, few news posts, many news posts, or a full-length news article. Results indicate that many news posts increased perceived knowledge that is not paralleled by a gain in factual knowledge. Perceived knowledge mediates effects of reading many news posts on more extreme attitudes and the willingness for discussions. Even if participants who read the news article gained factual knowledge, they did not feel more knowledgeable than participants who were exposed to a news feed containing news posts. The results emphasize the meaning of engaging with full news articles, both for learning facts and for more accurate knowledge assessments.
Are Large Language Models Sensitive to the Motives Behind Communication?
Human communication is $\textit{motivated}$: people speak, write, and create content with a particular communicative intent in mind. As a result, information that large language models (LLMs) and AI agents process is inherently framed by humans' intentions and incentives. People are adept at navigating such nuanced information: we routinely identify benevolent or self-serving motives in order to decide what statements to trust. For LLMs to be effective in the real world, they too must critically evaluate content by factoring in the motivations of the source---for instance, weighing the credibility of claims made in a sales pitch. In this paper, we undertake a comprehensive study of whether LLMs have this capacity for $\textit{motivational vigilance}$. We first employ controlled experiments from cognitive science to verify that LLMs' behavior is consistent with rational models of learning from motivated testimony, and find they successfully discount information from biased sources in a human-like manner. We then extend our evaluation to sponsored online adverts, a more naturalistic reflection of LLM agents' information ecosystems. In these settings, we find that LLMs' inferences do not track the rational models' predictions nearly as closely---partly due to additional information that distracts them from vigilance-relevant considerations. However, a simple steering intervention that boosts the salience of intentions and incentives substantially increases the correspondence between LLMs and the rational model. These results suggest that LLMs possess a basic sensitivity to the motivations of others, but generalizing to novel real-world settings will require further improvements to these models.
The echo chamber effect on social media
Significance We explore the key differences between the main social media platforms and how they are likely to influence information spreading and the formation of echo chambers. To assess the different dynamics, we perform a comparative analysis on more than 100 million pieces of content concerning controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. The analysis focuses on two main dimensions: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation in homophilic clusters of users dominates online dynamics. However, a direct comparison of news consumption on Facebook and Reddit shows higher segregation on Facebook. , Social media may limit the exposure to diverse perspectives and favor the formation of groups of like-minded users framing and reinforcing a shared narrative, that is, echo chambers. However, the interaction paradigms among users and feed algorithms greatly vary across social media platforms. This paper explores the key differences between the main social media platforms and how they are likely to influence information spreading and echo chambers’ formation. We perform a comparative analysis of more than 100 million pieces of content concerning several controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. We quantify echo chambers over social media by two main ingredients: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation of users in homophilic clusters dominate online interactions on Facebook and Twitter. We conclude the paper by directly comparing news consumption on Facebook and Reddit, finding higher segregation on Facebook.

The Role of Media in Political Polarization| Inoculation Can Reduce the Perceived Reliability of Polarizing Social Media Content
Little research is available on psychological interventions that counter susceptibility to polarizing online content. We conducted 3 studies (n1 = 472, n2 = 193, n3 = 772) to evaluate whether psychological resistance against polarizing social media content can be conferred, using the Bad News game, a “technique-based inoculation” intervention that simulates a social media feed. We investigate (1) whether technique-based inoculation can reduce susceptibility to content designed to fuel intergroup polarization; (2) whether technique-based inoculation can offer cross-protection against misinformation techniques that people were not inoculated against; and (3) whether political ideology plays a role in how people engage with anti-misinformation interventions. In Studies 1 and 3 (but not Study 2), we found that technique-based inoculation significantly reduces the perceived reliability of polarizing content and offers partial cross-protection against untreated misinformation techniques. We found no effect for attitudinal certainty and news-sharing intentions. Finally, we report preliminary evidence that people may choose to engage with politically congruent news topics within the intervention.
Persuasion: Empirical Evidence
We provide a selective survey of empirical evidence on the effects as well as the drivers of persuasive communication. We consider persuasion directed at consumers, voters, donors, and investors. We organize our review around four questions. First, to what extent does persuasion affect the behavior of each of these groups? Second, what models best capture the response to persuasive communication? Third, what are persuaders' incentives, and what limits their ability to distort communications? Finally, what evidence exists on the way persuasion affects equilibrium outcomes in economics and politics?

A Model of Multi-turn Human Persuadability Using Probabilistic Belief Tracing
Large language models can shift human beliefs across high-stakes domains, but most persuasion studies rely on pre/post belief change. These endpoint measures identify whether persuasion occurred, yet miss where and how beliefs moved within a dialogue. We present PERSUASIONTRACE, a framework for studying persuasion in human–LLM interaction. Built on a web-based experimental platform, PERSUASIONTRACE contributes a tool for multi-turn persuasion studies and a process-level evaluation protocol: it records multi-turn belief reports from human or simulated targets of persuasion, annotates persuader turns with rhetorical dimensions (logos/pathos/ethos), and evaluates simulators by fidelity to real human belief dynamics. Using this framework, we find that human targets group into two clusters of multi-turn belief updates and exhibit susceptibility to rhetorical strategies, and that LLMs are persuasive across generic and personalized topics, text and audio modalities, and multi-turn interactions. Prior work has chiefly used vanilla-prompted LLMs to simulate human targets, but we show that these simulators fail to replicate human belief dynamics. We introduce a Bayesian-network simulated target that maintains an explicit latent belief state over time so each persuader message yields cognitively realistic belief updates. In human-likeness evaluation, our Bayesian target scores near a human reference (81 vs 80), while baseline LLM targets score substantially lower (64). PERSUASIONTRACE reframes persuasion evaluation from endpoint movement alone to process fidelity, providing a stronger basis for scientific analysis and safer optimization of persuasive systems.
On the Conversational Persuasiveness of Large Language Models: A Randomized Controlled Trial
The development and popularization of large language models (LLMs) have raised concerns that they will be used to create tailor-made, convincing arguments to push false or misleading narratives online. Early work has found that language models can generate content perceived as at least on par and often more persuasive than human-written messages. However, there is still limited knowledge about LLMs' persuasive capabilities in direct conversations with human counterparts and how personalization can improve their performance. In this pre-registered study, we analyze the effect of AI-driven persuasion in a controlled, harmless setting. We create a web-based platform where participants engage in short, multiple-round debates with a live opponent. Each participant is randomly assigned to one of four treatment conditions, corresponding to a two-by-two factorial design: (1) Games are either played between two humans or between a human and an LLM; (2) Personalization might or might not be enabled, granting one of the two players access to basic sociodemographic information about their opponent. We found that participants who debated GPT-4 with access to their personal information had 81.7% (p < 0.01; N=820 unique participants) higher odds of increased agreement with their opponents compared to participants who debated humans. Without personalization, GPT-4 still outperforms humans, but the effect is lower and statistically non-significant (p=0.31). Overall, our results suggest that concerns around personalization are meaningful and have important implications for the governance of social media and the design of new online environments.

Redesigning algorithms to intervene on social norm misperceptions during a national election
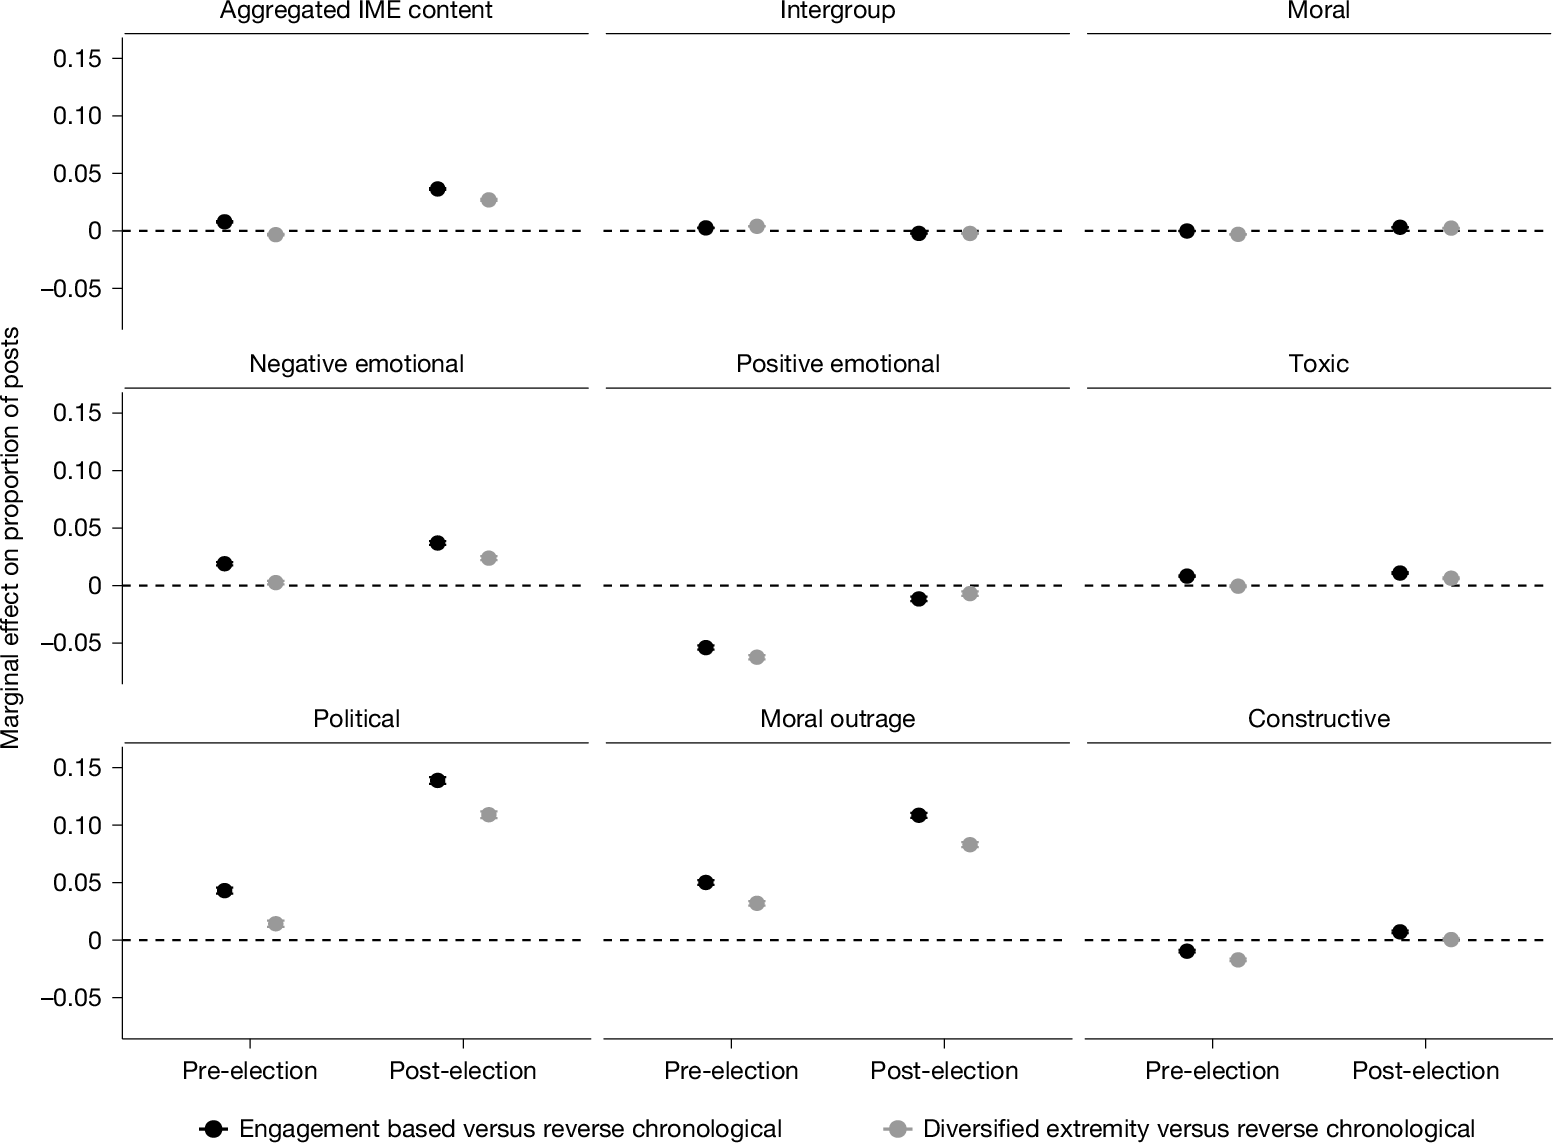
For the first time in history, civic discourse commonly occurs in digital environments in which algorithms influence exposure to social information1,2. It is increasingly important to understand whether and how these algorithms affect political discourse3–5. Here we built custom feed-ranking algorithms with full control over their features, and randomly assigned 2,000 participants to use them for 8 weeks (before and after the 2024 US presidential election). We tested whether an engagement-based algorithm (used on major social media platforms6,7) amplifies intergroup, moralized and emotional (IME) information in ways that skew perceptions of social norms around political dialogue5,8, and whether it increased engagement with IME content and perceptions of partisan animosity (compared with a reverse-chronological feed9,10). We also developed and tested a ‘diversified extremity’ algorithm to reduce the influence of extreme users11–13 to improve the accuracy of social norm perception14–16 and reduce perceptions of partisan animosity. We found that engagement-based feeds amplified IME and toxic content relative to reverse-chronological feeds, with the largest increases in moral outrage and political content. Engagement-based feeds also reduced prescriptive norm perception accuracy (albeit in an unexpected direction) and increased perceived partisan animosity. However, they did not significantly alter users’ own engagement behaviours. The diversified extremity algorithm reduced IME and toxic content exposure, improved prescriptive norm accuracy, yet maintained comparable platform enjoyment—suggesting that reducing the influence of extreme users can curb algorithmic distortions without diminishing user experience.
Modelling Opinion Dynamics in the Age of Algorithmic Personalisation
Modern technology has drastically changed the way we interact and consume information. For example, online social platforms allow for seamless communication exchanges at an unprecedented scale. However, we are still bounded by cognitive and temporal constraints. Our attention is limited and extremely valuable. Algorithmic personalisation has become a standard approach to tackle the information overload problem. As result, the exposure to our friends' opinions and our perception about important issues might be distorted. However, the effects of algorithmic gatekeeping on our hyper-connected society are poorly understood. Here, we devise an opinion dynamics model where individuals are connected through a social network and adopt opinions as function of the view points they are exposed to. We apply various filtering algorithms that select the opinions shown to users i) at random ii) considering time ordering or iii) their current beliefs. Furthermore, we investigate the interplay between such mechanisms and crucial features of real networks. We found that algorithmic filtering might influence opinions' share and distributions, especially in case information is biased towards the current opinion of each user. These effects are reinforced in networks featuring topological and spatial correlations where echo chambers and polarisation emerge. Conversely, heterogeneity in connectivity patterns reduces such tendency. We consider also a scenario where one opinion, through nudging, is centrally pushed to all users. Interestingly, even minimal nudging is able to change the status quo moving it towards the desired view point. Our findings suggest that simple filtering algorithms might be powerful tools to regulate opinion dynamics taking place on social networks
The political effects of X’s feed algorithm
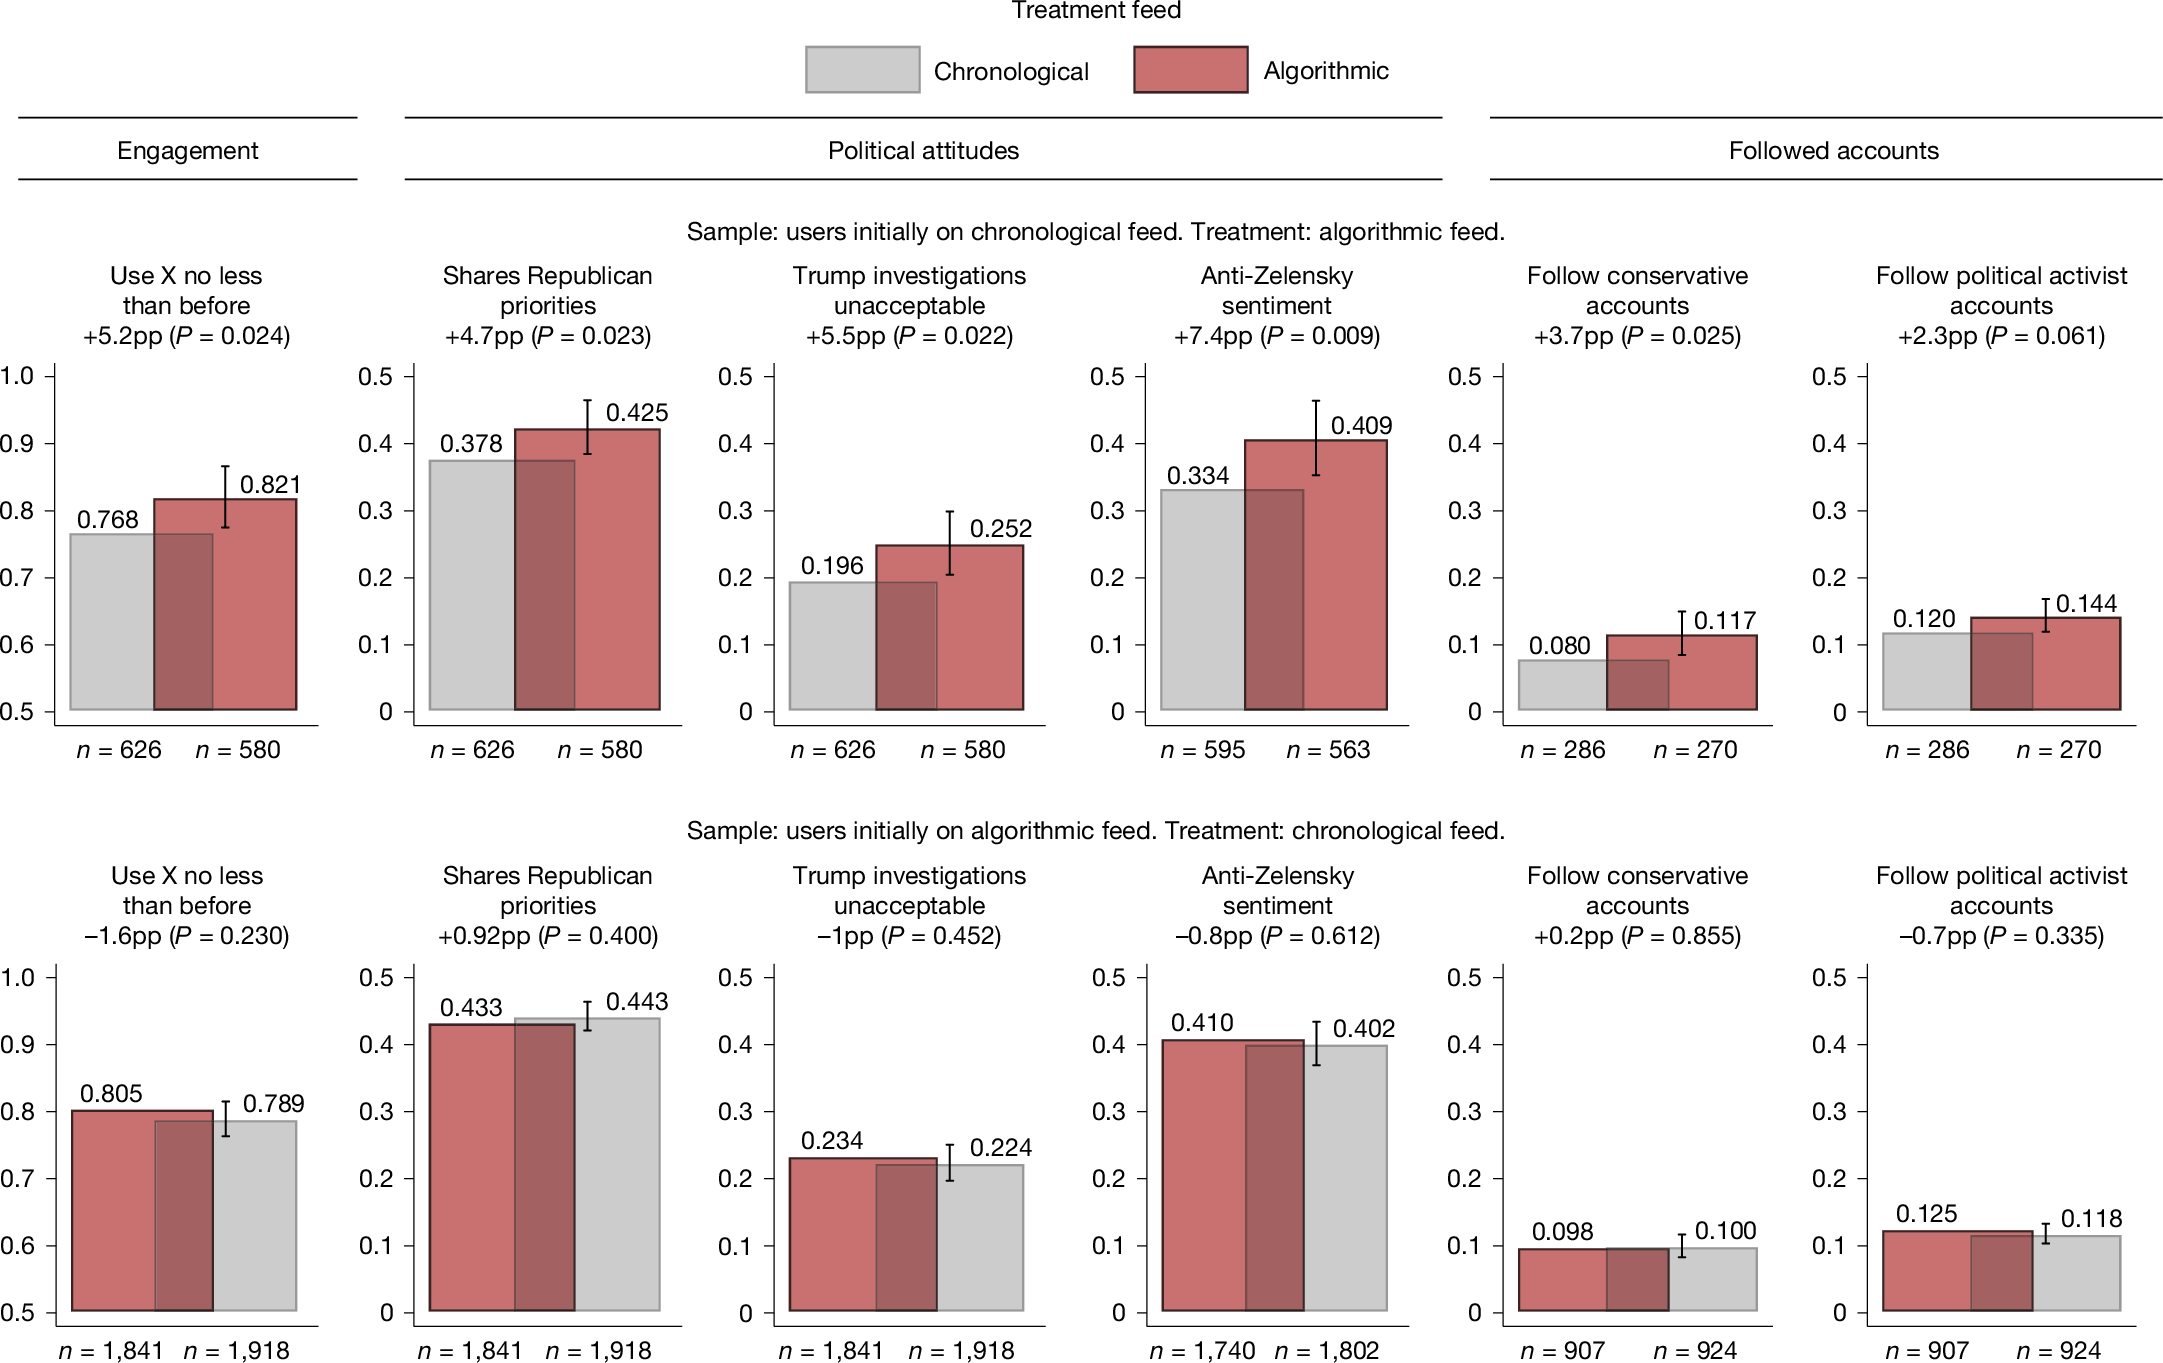
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
The political effects of X’s feed algorithm
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
How latent and prompting biases in AI-generated historical narratives influence opinions
Abstract. Large language models (LLMs) can be used to persuade people on a range of issues, particularly through user-driven strategies such as personalizi