


Generative artificial intelligence (GenAI) is changing human–machine interactions and the broader information ecosystem. Much as social media algorithms personalize online experiences, GenAI applications can align with user preferences to customize the way individuals interact with information. However, through training, fine-tuning, and prompting, GenAI applications can introduce a new level of customization: hypercustomization. By dynamically tailoring responses to an individual’s explicit and implicit preferences, hypercustomization can reinforce biases, false beliefs, or misconceptions. As a result, it can heighten significant societal challenges, such as the spread of misinformation and political and social polarization. In this article, we explore the risks associated with hypercustomization and the governance and behavioral challenges that might impede effective risk mitigation. These challenges include a lack of transparency in GenAI applications, opacity of the nature of their interactions with users, users’ overreliance on these systems, and the inefficacy of warning messages. We also provide recommendations for overcoming these challenges.
Misinformation reloaded? Fears about the impact of generative AI on misinformation are overblown
Many observers of the current explosion of generative AI worry about its impact on our information environment, with concerns being raised about the increased quantity, quality, and personalization of misinformation. We assess these arguments with evidence from communication studies, cognitive science, and political science. We argue that current concerns about the effects of generative AI

The levers of political persuasion with conversational artificial intelligence
There are widespread fears that conversational artificial intelligence (AI) could soon exert unprecedented influence over human beliefs. In this work, in three large-scale experiments ( N = 76,977 participants), we deployed 19 large language models (LLMs)—including some post-trained explicitly for persuasion—to evaluate their persuasiveness on 707 political issues. We then checked the factual accuracy of 466,769 resulting LLM claims. We show that the persuasive power of current and near-future AI is likely to stem more from post-training and prompting methods—which boosted persuasiveness by as much as 51 and 27%, respectively—than from personalization or increasing model scale, which had smaller effects. We further show that these methods increased persuasion by exploiting LLMs’ ability to rapidly access and strategically deploy information and that, notably, where they increased AI persuasiveness, they also systematically decreased factual accuracy. , Editor’s summary Many fear that we are on the precipice of unprecedented manipulation by large language models (LLMs), but techniques driving their persuasiveness are poorly understood. In the initial “pretrained” phase, LLMs may exhibit flawed reasoning. Their power unlocks during vital “posttraining,” when developers refine pretrained LLMs to sharpen their reasoning and align with users’ needs. Posttraining also enables LLMs to maintain logical, sophisticated conversations. Hackenburg et al . examined which techniques made diverse, conversational LLMs most persuasive across 707 British political issues (see the Perspective by Argyle). LLMs were most persuasive after posttraining, especially when prompted to use facts and evidence (information) to argue. However, information-dense LLMs produced the most inaccurate claims, raising concerns about the spread of misinformation during rollouts of future models. —Ekeoma Uzogara , INTRODUCTION Rapid advances in artificial intelligence (AI) have sparked widespread concerns about its potential to influence human beliefs. One possibility is that conversational AI could be used to manipulate public opinion on political issues through interactive dialogue. Despite extensive speculation, however, fundamental questions about the actual mechanisms, or “levers,” responsible for driving advances in AI persuasiveness—e.g., computational power or sophisticated training techniques—remain largely unanswered. In this work, we systematically investigate these levers and chart the horizon of persuasiveness with conversational AI. RATIONALE We considered multiple factors that could enhance the persuasiveness of conversational AI: raw computational power (model scale), specialized post-training methods for persuasion, personalization to individual users, and instructed rhetorical strategies. Across three large-scale experiments with 76,977 total UK participants, we deployed 19 large language models (LLMs) to persuade on 707 political issues while varying these factors independently. We also analyzed more than 466,000 AI-generated claims, examining the relationship between persuasiveness and truthfulness. RESULTS We found that the most powerful levers of AI persuasion were methods for post-training and rhetorical strategy (prompting), which increased persuasiveness by as much as 51 and 27%, respectively. These gains were often larger than those obtained from substantially increasing model scale. Personalizing arguments on the basis of user data had a comparatively small effect on persuasion. We observe that a primary mechanism driving AI persuasiveness was information density: Models were most persuasive when they packed their arguments with a high volume of factual claims. Notably, however, we documented a concerning trade-off between persuasion and accuracy: The same levers that made AI more persuasive—including persuasion post-training and information-focused prompting—also systematically caused the AI to produce information that was less factually accurate. CONCLUSION Our findings suggest that the persuasive power of current and near-future AI is likely to stem less from model scale or personalization and more from post-training and prompting techniques that mobilize an LLM’s ability to rapidly generate information during conversation. Further, we reveal a troubling trade-off: When AI systems are optimized for persuasion, they may increasingly deploy misleading or false information. This research provides an empirical foundation for policy-makers and technologists to anticipate and address the challenges of AI-driven persuasion, and it highlights the need for safeguards that balance AI’s legitimate uses in political discourse with protections against manipulation and misinformation. Persuasiveness of conversational AI increases with model scale. The persuasive impact in percentage points on the y axis is plotted against effective pretraining compute [floating-point operations (FLOPs)] on the x axis. Point estimates are persuasive effects of different AI models. Colored lines show trends for models that we uniformly chat-tuned for open-ended conversation (purple) versus those that were post-trained using heterogeneous, opaque methods by AI developers (green). pp, percentage points; CI, confidence interval.

Sociotechnical Implications of Generative Artificial Intelligence for Information Access
Robust access to trustworthy information is a critical need for society with implications for knowledge production, public health education, and promoting informed citizenry in democratic societies. Generative AI technologies may enable new ways to access information and improve effectiveness of existing information retrieval systems but we are only starting to understand and grapple with their long-term social implications. In this chapter, we present an overview of some of the systemic consequences and risks of employing generative AI in the context of information access. We also provide recommendations for evaluation and mitigation, and discuss challenges for future research.

LLM-generated messages can persuade humans on policy issues
The emergence of large language models (LLMs) has made it possible for generative artificial intelligence (AI) to tackle many higher-order cognitive tasks, with critical implications for industry, government, and labor markets. Here, we investigate whether existing, openly-available LLMs can be used to create messages capable of influencing humans’ political attitudes. Across three pre-registered experiments (total N = 4829), participants who read persuasive messages generated by LLMs showed significantly more attitude change across a range of policies - including polarized policies, like an assault weapons ban, a carbon tax, and a paid parental-leave program - relative to control condition participants who read a neutral message. Overall, LLM-generated messages were similarly effective in influencing policy attitudes as messages crafted by lay humans. Participants’ reported perceptions of the authors of the persuasive messages suggest these effects occurred through somewhat distinct causal pathways. While the persuasiveness of LLM-generated messages was associated with perceptions that the author used more facts, evidence, logical reasoning, and a dispassionate voice, the persuasiveness of human-generated messages was associated with perceptions of the author as unique and original. These results demonstrate that recent developments in AI make it possible to create politically persuasive messages quickly, cheaply, and at massive scale.

Rational Silence and False Polarization: How Viewpoint Organizations and Recommender Systems Distort the Expression of Public Opinion
Social media platforms are one of the most important domains in which artificial intelligence (AI) has already transformed the nature of economic and social interaction. AI enables the massive scale and highly personalized nature of online information sharing that we now take for granted. Extensive attention has been devoted to the polarization that social media platforms appear to facilitate. However, a key implication of the transformation we are experiencing due to these AI-powered platforms has received much less attention: how platforms impact what observers of online discourse come to believe about community views. These observers include policymakers and legislators, who look to social media to gauge the prospects for policy and legislative change, as well as developers of AI models trained on large-scale internet data, whose outputs may similarly reflect a distorted view of public opinion. In this paper, we present a nested game-theoretic model to show how observed online opinion is produced by the interaction of the decisions made by users about whether and with what rhetorical intensity to share their opinions on a platform, the efforts of viewpoint organizations (such as traditional media and advocacy organizations) that seek to encourage or discourage opinion-sharing online, and the operation of AI-powered recommender systems controlled by social media platforms. We show that signals from ideological viewpoint organizations encourage an increase in rhetorical intensity, leading to the rational silence of moderate users. This, in turn, creates a polarized impression of where average opinions lie. We also show that this observed polarization can also be amplified by recommender systems that, pursuant to a platform’s incentive to maximize engagement, encourage the formation of viewpoint communities online that end up seeing a skewed sample of opinion. Unlike existing models, these well-known online phenomena are not here attributed to distortion in the formation of opinions nor to the seeking out of like-minded others, but rather to the interaction of the incentives of users, viewpoint organizations, and platforms implementing recommender systems. In addition to showing how these interactions can play out in simulations, we also identify practical strategies platforms can implement, such as reducing exposure to signals from ideological viewpoint organizations and a tailored approach to content moderation.
The potential of generative AI for personalized persuasion at scale
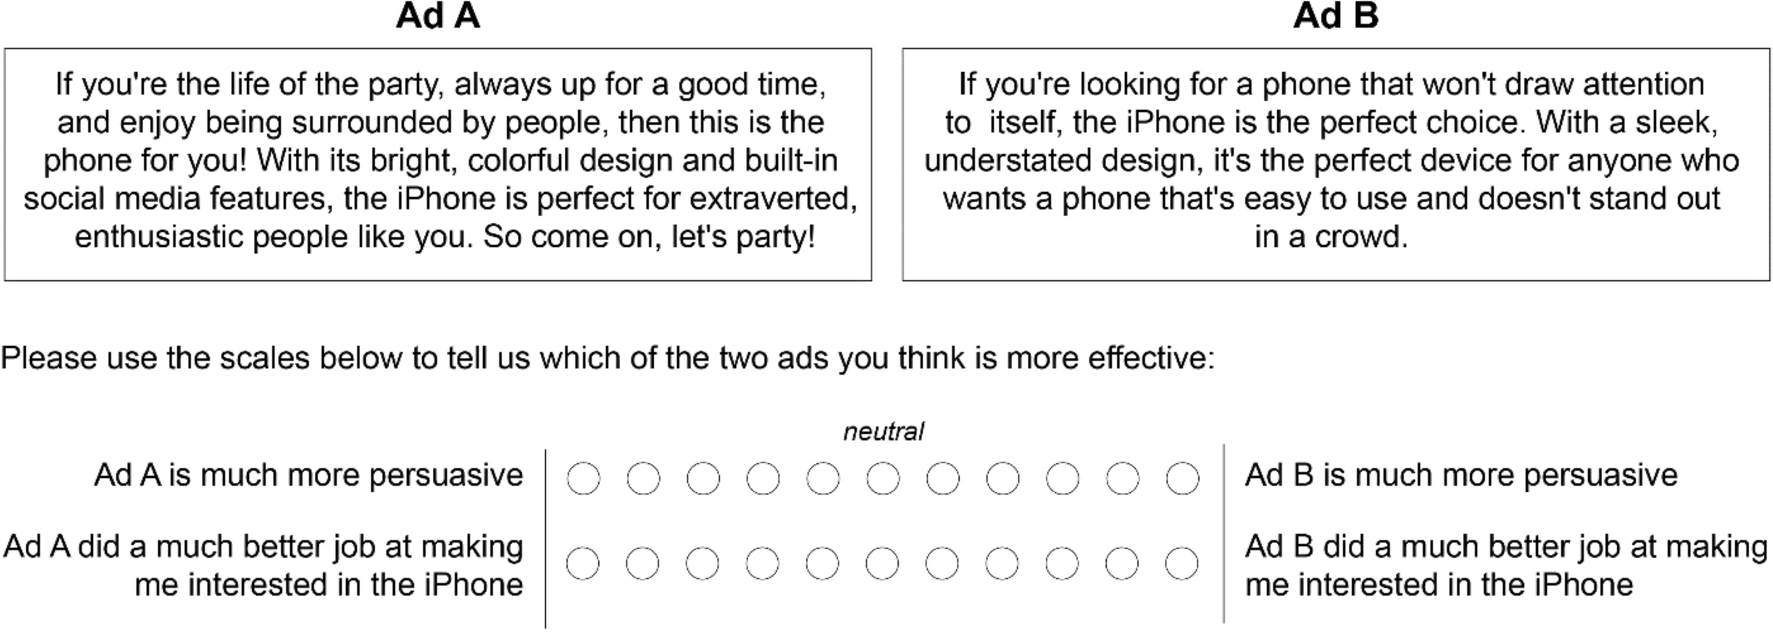
Matching the language or content of a message to the psychological profile of its recipient (known as “personalized persuasion”) is widely considered to be one of the most effective messaging strategies. We demonstrate that the rapid advances in large language models (LLMs), like ChatGPT, could accelerate this influence by making personalized persuasion scalable. Across four studies (consisting of seven sub-studies; total N = 1788), we show that personalized messages crafted by ChatGPT exhibit significantly more influence than non-personalized messages. This was true across different domains of persuasion (e.g., marketing of consumer products, political appeals for climate action), psychological profiles (e.g., personality traits, political ideology, moral foundations), and when only providing the LLM with a single, short prompt naming or describing the targeted psychological dimension. Thus, our findings are among the first to demonstrate the potential for LLMs to automate, and thereby scale, the use of personalized persuasion in ways that enhance its effectiveness and efficiency. We discuss the implications for researchers, practitioners, and the general public.
"Okay, I've Actually Softened My Take on This": How People in Decentralized Social Media Reason about the Appropriateness of Generative AI
Generative AI (GenAI) is increasingly integrated into social media, raising questions about whether, where, and how it belongs. In decentralized social media (DSM), these decisions are distributed across users, developers, moderators, and administrators, making GenAI a collective governance challenge. At the same time, public discourse often flattens arguments to broad pro- or anti-AI positions that offer little insight into what people actually find (in)appropriate and why. Through 20 semi-structured interviews with people from Mastodon and Bluesky, structured around seven GenAI scenarios, we examine how people reason about GenAI's appropriateness in DSM. We find that participants drew conditional boundaries around particular GenAI configurations through distinct, salient, and weighted considerations spanning technology, integration, and use. We conceptualize this as boundary drawing and show how making such boundaries visible can support more grounded design, policy, and collective deliberation around GenAI in DSM.
"Okay, I've Actually Softened My Take on This": How People in Decentralized Social Media Reason about the Appropriateness of Generative AI
Generative AI (GenAI) is increasingly integrated into social media, raising questions about whether, where, and how it belongs. In decentralized social media (DSM), these decisions are distributed across users, developers, moderators, and administrators, making GenAI a collective governance challenge. At the same time, public discourse often flattens arguments to broad pro- or anti-AI positions that offer little insight into what people actually find (in)appropriate and why. Through 20 semi-structured interviews with people from Mastodon and Bluesky, structured around seven GenAI scenarios, we examine how people reason about GenAI's appropriateness in DSM. We find that participants drew conditional boundaries around particular GenAI configurations through distinct, salient, and weighted considerations spanning technology, integration, and use. We conceptualize this as boundary drawing and show how making such boundaries visible can support more grounded design, policy, and collective deliberation around GenAI in DSM.
On the Conversational Persuasiveness of Large Language Models: A Randomized Controlled Trial
The development and popularization of large language models (LLMs) have raised concerns that they will be used to create tailor-made, convincing arguments to push false or misleading narratives online. Early work has found that language models can generate content perceived as at least on par and often more persuasive than human-written messages. However, there is still limited knowledge about LLMs' persuasive capabilities in direct conversations with human counterparts and how personalization can improve their performance. In this pre-registered study, we analyze the effect of AI-driven persuasion in a controlled, harmless setting. We create a web-based platform where participants engage in short, multiple-round debates with a live opponent. Each participant is randomly assigned to one of four treatment conditions, corresponding to a two-by-two factorial design: (1) Games are either played between two humans or between a human and an LLM; (2) Personalization might or might not be enabled, granting one of the two players access to basic sociodemographic information about their opponent. We found that participants who debated GPT-4 with access to their personal information had 81.7% (p < 0.01; N=820 unique participants) higher odds of increased agreement with their opponents compared to participants who debated humans. Without personalization, GPT-4 still outperforms humans, but the effect is lower and statistically non-significant (p=0.31). Overall, our results suggest that concerns around personalization are meaningful and have important implications for the governance of social media and the design of new online environments.
The benefits, risks and bounds of personalizing the alignment of large language models to individuals
Large language models (LLMs) undergo ‘alignment’ so that they better reflect human values or preferences, and are safer or more useful. However, alignment is intrinsically difficult because the hundreds of millions of people who now interact with LLMs have different preferences for language and conversational norms, operate under disparate value systems and hold diverse political beliefs. Typically, few developers or researchers dictate alignment norms, risking the exclusion or under-representation of various groups. Personalization is a new frontier in LLM development, whereby models are tailored to individuals. In principle, this could minimize cultural hegemony, enhance usefulness and broaden access. However, unbounded personalization poses risks such as large-scale profiling, privacy infringement, bias reinforcement and exploitation of the vulnerable. Defining the bounds of responsible and socially acceptable personalization is a non-trivial task beset with normative challenges. This article explores ‘personalized alignment’, whereby LLMs adapt to user-specific data, and highlights recent shifts in the LLM ecosystem towards a greater degree of personalization. Our main contribution explores the potential impact of personalized LLMs via a taxonomy of risks and benefits for individuals and society at large. We lastly discuss a key open question: what are appropriate bounds of personalization and who decides? Answering this normative question enables users to benefit from personalized alignment while safeguarding against harmful impacts for individuals and society.

How malicious AI swarms can threaten democracy
The fusion of agentic AI and LLMs marks a new frontier in information warfare , Advances in artificial intelligence (AI) offer the prospect of manipulating beliefs and behaviors on a population-wide level ( 1 ). Large language models (LLMs) and autonomous agents ( 2 ) let influence campaigns reach unprecedented scale and precision. Generative tools can expand propaganda output without sacrificing credibility ( 3 ) and inexpensively create falsehoods that are rated as more human-like than those written by humans ( 3 , 4 ). Techniques meant to refine AI reasoning, such as chain-of-thought prompting, can be used to generate more convincing falsehoods. Enabled by these capabilities, a disruptive threat is emerging: swarms of collaborative, malicious AI agents. Fusing LLM reasoning with multiagent architectures ( 2 ), these systems are capable of coordinating autonomously, infiltrating communities, and fabricating consensus efficiently. By adaptively mimicking human social dynamics, they threaten democracy. Because the resulting harms stem from design, commercial incentives, and governance, we prioritize interventions at multiple leverage points, focusing on pragmatic mechanisms over voluntary compliance.

How malicious AI swarms can threaten democracy
The fusion of agentic AI and LLMs marks a new frontier in information warfare , Advances in artificial intelligence (AI) offer the prospect of manipulating beliefs and behaviors on a population-wide level ( 1 ). Large language models (LLMs) and autonomous agents ( 2 ) let influence campaigns reach unprecedented scale and precision. Generative tools can expand propaganda output without sacrificing credibility ( 3 ) and inexpensively create falsehoods that are rated as more human-like than those written by humans ( 3 , 4 ). Techniques meant to refine AI reasoning, such as chain-of-thought prompting, can be used to generate more convincing falsehoods. Enabled by these capabilities, a disruptive threat is emerging: swarms of collaborative, malicious AI agents. Fusing LLM reasoning with multiagent architectures ( 2 ), these systems are capable of coordinating autonomously, infiltrating communities, and fabricating consensus efficiently. By adaptively mimicking human social dynamics, they threaten democracy. Because the resulting harms stem from design, commercial incentives, and governance, we prioritize interventions at multiple leverage points, focusing on pragmatic mechanisms over voluntary compliance.
AI-driven disinformation running rampant on social media before US midterms, experts warn
Social media companies including Meta have pulled back on efforts to protect voters from election-meddling lies
Human-Algorithm Collaboration with Private Information: Naïve Advice-Weighting Behavior and Mitigation
Even if algorithms make better predictions than humans on average, humans may sometimes have private information that an algorithm does not have access to that can improve performance. How can we help humans effectively use and adjust recommendations made by algorithms in such situations? When deciding whether and how to override an algorithm’s recommendations, we hypothesize that people are biased toward following naïve advice-weighting (NAW) behavior; they take a weighted average between their own prediction and the algorithm’s prediction, with a constant weight across prediction instances regardless of whether they have valuable private information. This leads to humans overadhering to the algorithm’s predictions when their private information is valuable and underadhering when it is not. In an online experiment where participants were tasked with making demand predictions for 20 products while having access to an algorithm’s predictions, we confirm this bias toward NAW and find that it leads to a 20%–61% increase in prediction error. In a second experiment, we find that feature transparency—even when the underlying algorithm is a black box—helps users more effectively discriminate how to deviate from algorithms, resulting in a 25% reduction in prediction error. We make further improvements in a third experiment via an intervention designed to move users away from advice weighting and instead, use only their private information to inform deviations, leading to a 34% reduction in prediction error. This paper was accepted by Elena Katok, Special Issue on the Human-Algorithm Connection. Supplemental Material: The online appendix and data files are available at https://doi.org/10.1287/mnsc.2022.03850 .

Agency Among Agents: Designing with Hypertextual Friction in the Algorithmic Web
Today's algorithm-driven interfaces, from recommendation feeds to GenAI tools, often prioritize engagement and efficiency at the expense of user agency. As systems take on more decision-making, users have less control over what they see and how meaning or relationships between content are constructed. This paper introduces "Hypertextual Friction," a conceptual design stance that repositions classical hypertext principles--friction, traceability, and structure--as actionable values for reclaiming agency in algorithmically mediated environments. Through a comparative analysis of real-world interfaces--Wikipedia vs. Instagram Explore, and Are.na vs. GenAI image tools--we examine how different systems structure user experience, navigation, and authorship. We show that hypertext systems emphasize provenance, associative thinking, and user-driven meaning-making, while algorithmic systems tend to obscure process and flatten participation. We contribute: (1) a comparative analysis of how interface structures shape agency in user-driven versus agent-driven systems, and (2) a conceptual stance that offers hypertextual values as design commitments for reclaiming agency in an increasingly algorithmic web.
Agency Among Agents: Designing with Hypertextual Friction in the Algorithmic Web
Today's algorithm-driven interfaces, from recommendation feeds to GenAI tools, often prioritize engagement and efficiency at the expense of user agency. As systems take on more decision-making, users have less control over what they see and how meaning or relationships between content are constructed. This paper introduces "Hypertextual Friction," a conceptual design stance that repositions classical hypertext principles--friction, traceability, and structure--as actionable values for reclaiming agency in algorithmically mediated environments. Through a comparative analysis of real-world interfaces--Wikipedia vs. Instagram Explore, and Are.na vs. GenAI image tools--we examine how different systems structure user experience, navigation, and authorship. We show that hypertext systems emphasize provenance, associative thinking, and user-driven meaning-making, while algorithmic systems tend to obscure process and flatten participation. We contribute: (1) a comparative analysis of how interface structures shape agency in user-driven versus agent-driven systems, and (2) a conceptual stance that offers hypertextual values as design commitments for reclaiming agency in an increasingly algorithmic web.