

Online ideological segregation—often described as “echo chambers”—is commonly attributed to algorithmic personalization (“filter bubbles”) or users’ preferences for like-minded environments. We propose a different mechanism. Using a minimal agent-based model, we show that strong segregation can arise even without algorithmic personalization and without users preferring homogeneous environments. Even when users exit communities only after finding themselves almost entirely surrounded by disagreement, cascading exits can push initially mixed communities toward high homogeneity. Once small imbalances arise, feedback between exit and regrouping generates a self-reinforcing process of system-level sorting. Extending the model further reveals that algorithmic personalization can, under some conditions, reduce segregation by lowering dissatisfaction, slowing exit cascades, and stabilizing mixed communities. As an empirical illustration, a longitudinal analysis of the subreddit r/MensRights shows that users whose language is more distant from the community’s evolving semantic center are more likely to exit. Taken together, these findings suggest that echo chambers need not depend on users seeking homogeneous environments or algorithmic personalization alone, but can also emerge from exit dynamics in the interaction structures characteristic of online platforms. More broadly, they show how interventions aimed at individual exposure can produce aggregate dynamics that differ from their intended effects, complicating both scientific and policy debates over online polarization.
Echo chambers can emerge without algorithmic personalization or a preference for homogeneity
Online ideological segregation—often described as “echo chambers”—is commonly attributed to algorithmic personalization (“filter bubbles”) or users’ preferences for like-minded environments. We propose a different mechanism. Using a minimal agent-based model, we show that strong segregation can arise even without algorithmic personalization and without users preferring homogeneous environments. Even when users exit communities only after finding themselves almost entirely surrounded by disagreement, cascading exits can push initially mixed communities toward high homogeneity. Once small imbalances arise, feedback between exit and regrouping generates a self-reinforcing process of system-level sorting. Extending the model further reveals that algorithmic personalization can, under some conditions, reduce segregation by lowering dissatisfaction, slowing exit cascades, and stabilizing mixed communities. As an empirical illustration, a longitudinal analysis of the subreddit r/MensRights shows that users whose language is more distant from the community’s evolving semantic center are more likely to exit. Taken together, these findings suggest that echo chambers need not depend on users seeking homogeneous environments or algorithmic personalization alone, but can also emerge from exit dynamics in the interaction structures characteristic of online platforms. More broadly, they show how interventions aimed at individual exposure can produce aggregate dynamics that differ from their intended effects, complicating both scientific and policy debates over online polarization.
Modelling Opinion Dynamics in the Age of Algorithmic Personalisation
Modern technology has drastically changed the way we interact and consume information. For example, online social platforms allow for seamless communication exchanges at an unprecedented scale. However, we are still bounded by cognitive and temporal constraints. Our attention is limited and extremely valuable. Algorithmic personalisation has become a standard approach to tackle the information overload problem. As result, the exposure to our friends' opinions and our perception about important issues might be distorted. However, the effects of algorithmic gatekeeping on our hyper-connected society are poorly understood. Here, we devise an opinion dynamics model where individuals are connected through a social network and adopt opinions as function of the view points they are exposed to. We apply various filtering algorithms that select the opinions shown to users i) at random ii) considering time ordering or iii) their current beliefs. Furthermore, we investigate the interplay between such mechanisms and crucial features of real networks. We found that algorithmic filtering might influence opinions' share and distributions, especially in case information is biased towards the current opinion of each user. These effects are reinforced in networks featuring topological and spatial correlations where echo chambers and polarisation emerge. Conversely, heterogeneity in connectivity patterns reduces such tendency. We consider also a scenario where one opinion, through nudging, is centrally pushed to all users. Interestingly, even minimal nudging is able to change the status quo moving it towards the desired view point. Our findings suggest that simple filtering algorithms might be powerful tools to regulate opinion dynamics taking place on social networks

The echo chamber effect on social media
Significance We explore the key differences between the main social media platforms and how they are likely to influence information spreading and the formation of echo chambers. To assess the different dynamics, we perform a comparative analysis on more than 100 million pieces of content concerning controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. The analysis focuses on two main dimensions: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation in homophilic clusters of users dominates online dynamics. However, a direct comparison of news consumption on Facebook and Reddit shows higher segregation on Facebook. , Social media may limit the exposure to diverse perspectives and favor the formation of groups of like-minded users framing and reinforcing a shared narrative, that is, echo chambers. However, the interaction paradigms among users and feed algorithms greatly vary across social media platforms. This paper explores the key differences between the main social media platforms and how they are likely to influence information spreading and echo chambers’ formation. We perform a comparative analysis of more than 100 million pieces of content concerning several controversial topics (e.g., gun control, vaccination, abortion) from Gab, Facebook, Reddit, and Twitter. We quantify echo chambers over social media by two main ingredients: 1) homophily in the interaction networks and 2) bias in the information diffusion toward like-minded peers. Our results show that the aggregation of users in homophilic clusters dominate online interactions on Facebook and Twitter. We conclude the paper by directly comparing news consumption on Facebook and Reddit, finding higher segregation on Facebook.

An Experimental Method to Study Opinion Diffusion in Human-AI Hybrid Societies
As artificial intelligence increasingly mediates public discourse, it becomes important to understand how human-AI collectives shape opinion formation, deliberation, and democratic outcomes. We present a novel experimental method for studying opinion dynamics in hybrid human-AI social networks. Participants, human or AI, were embedded in $5\times5$ grid lattice networks and iteratively asked to select and revise statements on a given polarizing topic over eight rounds. We compared three conditions: human-only, AI-only, and hybrid networks with equal proportions of human and AI participants. Hybrid human-AI networks achieved the lowest final polarization while, in contrast, human-only networks exhibited higher polarization with lower neighbor agreement. We also ran additional experiments varying Large Language Model (LLM) prompt framing to explore whether instruction design might influence convergence patterns. Although these early findings are preliminary and cannot yet support broad generalizations, they highlight the potential value of experimental social networks for understanding opinion dynamics in human-AI hybrid societies.
Political Sorting Can Drive AI Models Apart Through User Feedback
Large language models are rapidly becoming an important source of political information. This raises a fundamental question: will AI systems support a shared basis for political knowledge, or lead different political groups to rely on increasingly different models? Political sorting can drive model fragmentation if three conditions hold: politically different users select into different models, learning from user feedback pushes those models apart politically, and the resulting differences shape subsequent model choices. We call this self-reinforcing process the Centrifugal Alignment Spiral. We study its components in three steps. First, we draw on a human experiment showing that political identity predicts model choice. Second, we fine-tune language models on synthetic feedback reflecting predominantly Democratic or Republican preferences. Across five independent runs per model family, paired models diverged on 12-41% of unseen survey questions with large partisan gaps, and in every run the differences moved in the expected political direction; for some models, differentiation extended even to issue areas excluded from training. Pooling feedback across groups instead suppressed divergence. Third, an empirically anchored agent-based model shows what follows when political sorting and model adaptation operate together: models attract politically distinct audiences, learn from them, and diverge further. User feedback can therefore turn political sorting among AI users into durable differences between the models on which they rely for political information.
The political effects of X’s feed algorithm
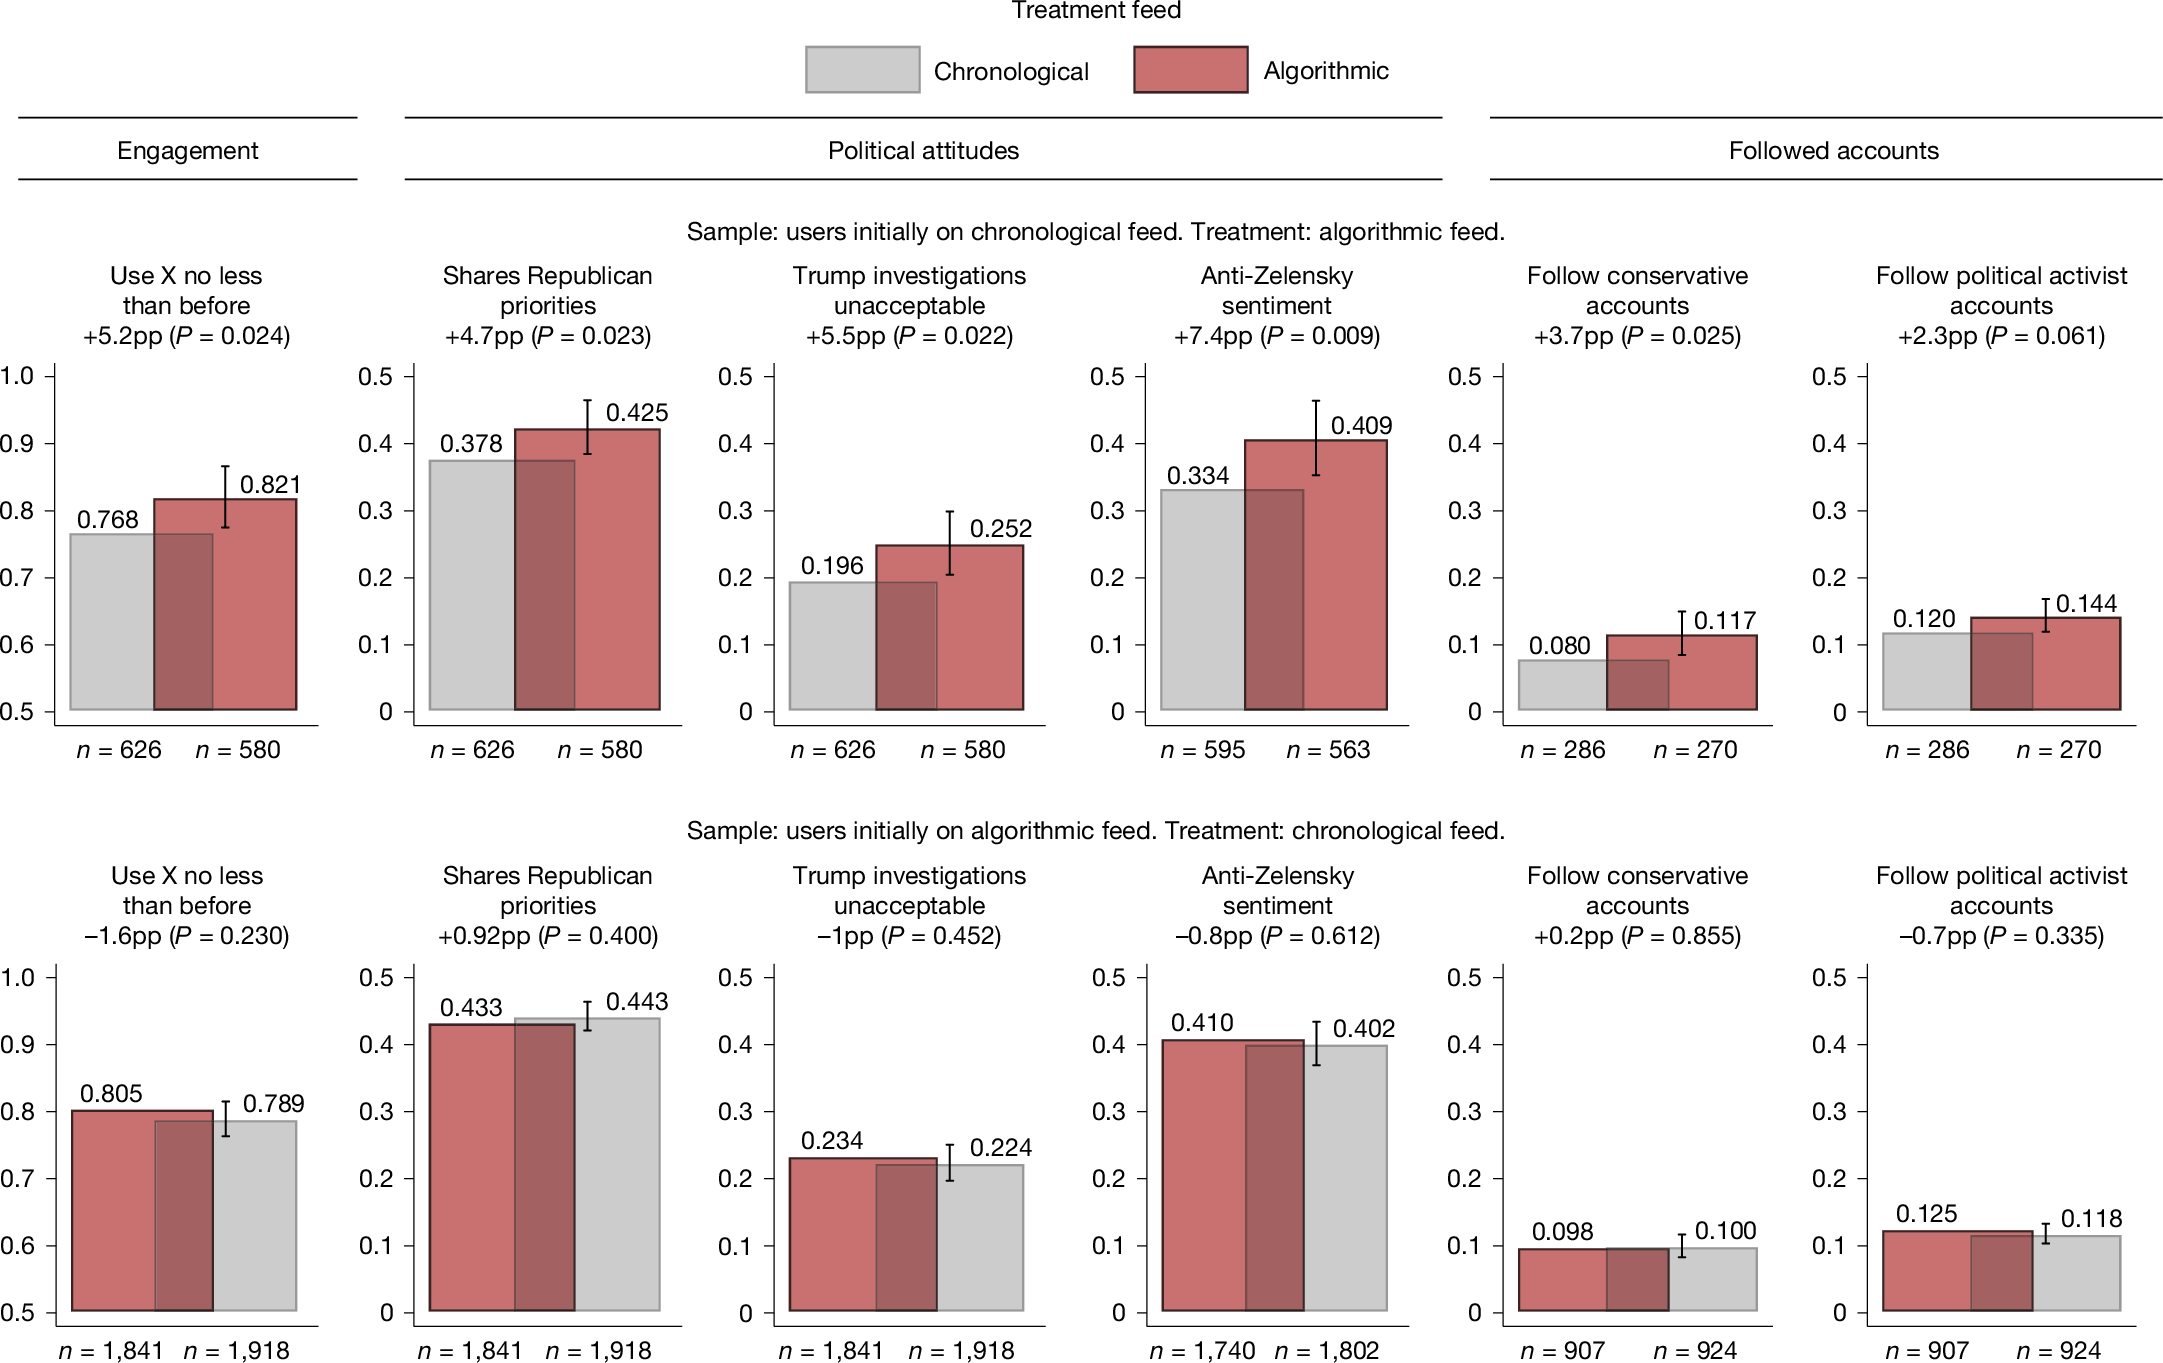
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
The political effects of X’s feed algorithm
Feed algorithms are widely suspected to influence political attitudes. However, previous evidence from switching off the algorithm on Meta platforms found no political effects1. Here we present results from a 2023 field experiment on Elon Musk’s platform X shedding light on this puzzle. We assigned active US-based users randomly to either an algorithmic or a chronological feed for 7 weeks, measuring political attitudes and online behaviour. Switching from a chronological to an algorithmic feed increased engagement and shifted political opinion towards more conservative positions, particularly regarding policy priorities, perceptions of criminal investigations into Donald Trump and views on the war in Ukraine. In contrast, switching from the algorithmic to the chronological feed had no comparable effects. Neither switching the algorithm on nor switching it off significantly affected affective polarization or self-reported partisanship. To investigate the mechanism, we analysed users’ feed content and behaviour. We found that the algorithm promotes conservative content and demotes posts by traditional media. Exposure to algorithmic content leads users to follow conservative political activist accounts, which they continue to follow even after switching off the algorithm, helping explain the asymmetry in effects. These results suggest that initial exposure to X’s algorithm has persistent effects on users’ current political attitudes and account-following behaviour, even in the absence of a detectable effect on partisanship.
Can We Fix Social Media? Testing Prosocial Interventions using Generative Social Simulation
Social media platforms have been widely linked to societal harms, including rising polarization and the erosion of constructive debate. Can these problems be mitigated through prosocial interventions? We address this question using a novel method - generative social simulation - that embeds Large Language Models within Agent-Based Models to create socially rich synthetic platforms. We create a minimal platform where agents can post, repost, and follow others. We find that the resulting following-networks reproduce three well-documented dysfunctions: (1) partisan echo chambers; (2) concentrated influence among a small elite; and (3) the amplification of polarized voices - creating a 'social media prism' that distorts political discourse. We test six proposed interventions, from chronological feeds to bridging algorithms, finding only modest improvements - and in some cases, worsened outcomes. These results suggest that core dysfunctions may be rooted in the feedback between reactive engagement and network growth, raising the possibility that meaningful reform will require rethinking the foundational dynamics of platform architecture.
Physics of Agents: Statistical Mechanics Predicts Collective Behavior of AI Agents
AI agents increasingly operate as part of interacting systems rather than in isolation. As agents exchange information and jointly make decisions, their interactions can improve collective reasoning but may also produce herding, polarization, or amplify shared biases. Understanding and predicting these collective dynamics is therefore important for designing effective and aligned multi-agent systems. Here, we study over 10,000 communities of language-model agents that repeatedly exchange messages and revise their opinions across objective mathematics questions and subjective political statements. Despite substantial diversity in possible behavior, the individual and group dynamics can be represented by three characteristic regimes: indifference, polarization, and consensus. AI agents start indifferent and build conviction as they interact. On objective questions, communication improves collective accuracy, while on subjective questions it often drifts group opinions toward the right in the political spectrum. We explain these observations with a statistical-mechanics formalism in which agents stochastically favor lower social pressure. Given only initial opinions, our model predicts individual trajectories, outperforms all standard baselines, generalizes to unseen community graphs, and reproduces the observed group archetype distributions. Our fitted model parameters reveal the mechanics underlying our key observations: i) communities operate below the critical social temperature, which explains conviction buildup; ii) attractive ties outweigh repulsive ones, which favors consensus; and iii) agents holding the correct answer exert the strongest pull, which drives truth-seeking. Overall, our results demonstrate that collective behavior of AI agents, like that of other complex systems, follows compact and predictive dynamical laws.
Redesigning algorithms to intervene on social norm misperceptions during a national election
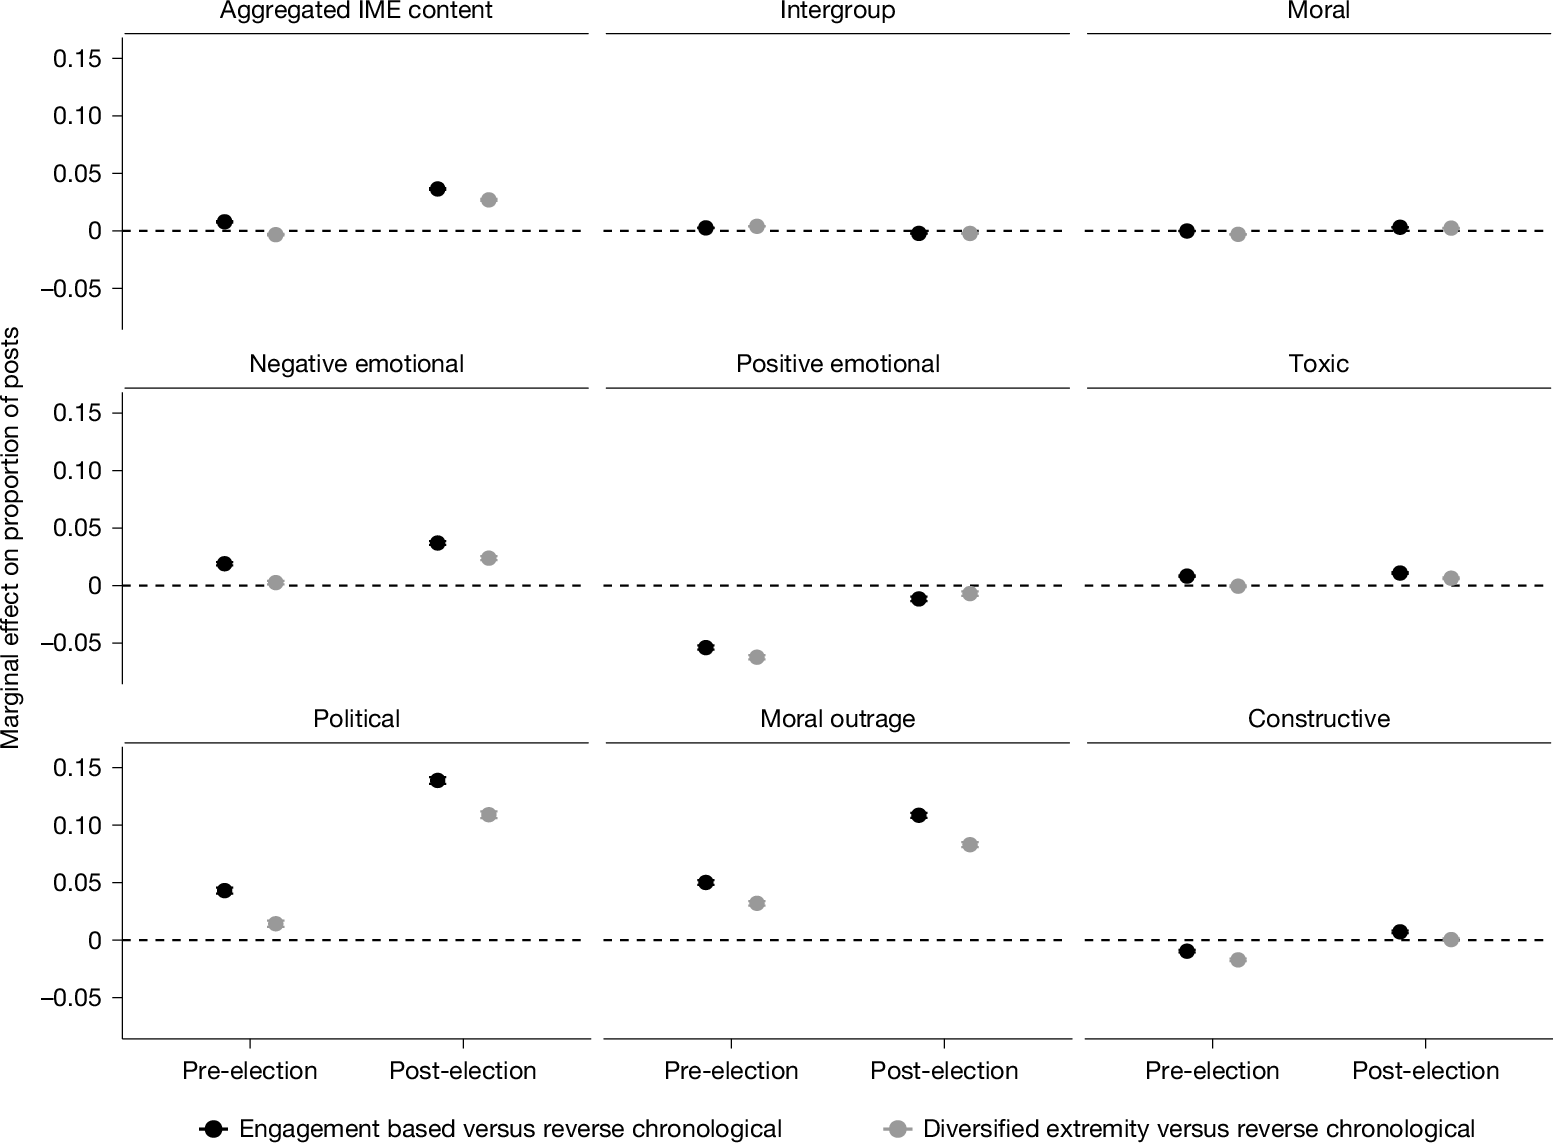
For the first time in history, civic discourse commonly occurs in digital environments in which algorithms influence exposure to social information1,2. It is increasingly important to understand whether and how these algorithms affect political discourse3–5. Here we built custom feed-ranking algorithms with full control over their features, and randomly assigned 2,000 participants to use them for 8 weeks (before and after the 2024 US presidential election). We tested whether an engagement-based algorithm (used on major social media platforms6,7) amplifies intergroup, moralized and emotional (IME) information in ways that skew perceptions of social norms around political dialogue5,8, and whether it increased engagement with IME content and perceptions of partisan animosity (compared with a reverse-chronological feed9,10). We also developed and tested a ‘diversified extremity’ algorithm to reduce the influence of extreme users11–13 to improve the accuracy of social norm perception14–16 and reduce perceptions of partisan animosity. We found that engagement-based feeds amplified IME and toxic content relative to reverse-chronological feeds, with the largest increases in moral outrage and political content. Engagement-based feeds also reduced prescriptive norm perception accuracy (albeit in an unexpected direction) and increased perceived partisan animosity. However, they did not significantly alter users’ own engagement behaviours. The diversified extremity algorithm reduced IME and toxic content exposure, improved prescriptive norm accuracy, yet maintained comparable platform enjoyment—suggesting that reducing the influence of extreme users can curb algorithmic distortions without diminishing user experience.
Auditing Political Exposure Bias: Algorithmic Amplification on Twitter/X During the 2024 U.S. Presidential Election
Approximately 50% of tweets in X's user timelines are personalized recommendations from accounts they do not follow. This raises a critical question: What political content are users exposed to beyond their established networks, and what implications does this have for democratic discourse online? In this paper, we present a six-week audit of X's algorithmic content recommendations during the 2024 U.S. Presidential Election by deploying 120 sock-puppet monitoring accounts to capture tweets from their personalized "For You" timelines. Our objective is to quantify out-of-network content exposure for right- and left-leaning user profiles and assess any potential inequalities and biases in political exposure. Our findings indicate that X's algorithm skews exposure toward a few high-popularity accounts across all users, with right-leaning users experiencing the highest level of exposure inequality. Both left- and right-leaning users encounter amplified exposure to accounts aligned with their own political views and reduced exposure to opposing viewpoints. Additionally, we observe that new accounts experience a right-leaning bias in exposure within their default timelines. Our work contributes to understanding how content recommendation systems may induce and reinforce biases while exacerbating vulnerabilities among politically polarized user groups. We underscore the importance of transparency-aware algorithms in addressing critical issues such as safeguarding election integrity and fostering a more informed digital public sphere.
The governance & behavioral challenges of generative artificial intelligence’s hypercustomization capabilities
Generative artificial intelligence (GenAI) is changing human–machine interactions and the broader information ecosystem. Much as social media algorithms personalize online experiences, GenAI applications can align with user preferences to customize the way individuals interact with information. However, through training, fine-tuning, and prompting, GenAI applications can introduce a new level of customization: hypercustomization. By dynamically tailoring responses to an individual’s explicit and implicit preferences, hypercustomization can reinforce biases, false beliefs, or misconceptions. As a result, it can heighten significant societal challenges, such as the spread of misinformation and political and social polarization. In this article, we explore the risks associated with hypercustomization and the governance and behavioral challenges that might impede effective risk mitigation. These challenges include a lack of transparency in GenAI applications, opacity of the nature of their interactions with users, users’ overreliance on these systems, and the inefficacy of warning messages. We also provide recommendations for overcoming these challenges.

LLM-Augmented Agent-Based Simulation of Cyber Social Agents
Social media bots are often portrayed as malicious automations to be detected and removed, but automation on social media platforms encompasses a wide spectrum of roles, behaviors, and rhetorical strategies that can shape online discourse in both constructive and destructive ways. This work conceptualizes these automated actors as \textbf{Cyber Social Agents} through a taxonomy of archetypes characterized by their operational tactics and rhetorical style. We integrate this taxonomy into an LLM-driven social simulation, where agents communicate and coordinate in a network environment. Using empirically grounded CSA personas, we simulate heterogeneous online societies to study how agent diversity shapes information diffusion and social influence. Our approach bridges the gap between rule-based agent models and LLM-powered simulations with generated agents that are parameterized from empirical data.
Value misalignment in X’s feed algorithm is a reflection of value tensions in engagement
Social media feed algorithms rank content that is purported to be preferred by users, but the engagement behaviors that drive these algorithms are (at best) indirect proxies for users’ explicitly self-stated values. Are the resulting feeds value aligned, and if not, why? We investigate this question by annotating the basic human values expressed in participants’ X (Twitter) feeds (N = 715 US users), analyzing the relationship between the posts’ value expressions and the posts’ amplification in the ranked “For You” Page feed, and then comparing the amplified values to users’ own values. We observe that the inventory of posts from followed accounts reflects users’ self-stated values—but that there is an overall negative correlation (misalignment) between users’ explicit values and the value expressions the algorithm is more likely to amplify. We turn to engagement behavior to understand this misalignment and observe that users’ engagement behaviors can be misaligned with their stated values—likely causing the algorithm to learn and reflect these misaligned values. We also detect partisan differences consistent with this theory: While the algorithm amplifies values negatively correlated with both Democrats’ and Republicans’ self-stated values, they are more misaligned for Democrats. And in fact replying, a heavily weighted form of engagement, is associated with values that are less aligned for both Democrats’ and Republicans’ self-stated values, and is even more misaligned for Democrats. Taken together, these findings offer a glimpse into the tensions between the values that people hold and those that provoke reactions, and how these value tensions can produce misaligned outcomes.