Social norms—the unspoken commonsense rules about acceptable social behavior—are crucial in understanding the underlying causes and intents of people's actions in narratives. For example, underlying an action such as “wanting to call cops on my neighbor” are social norms that inform our conduct, such as “It is expected that you report crimes.” We present SOCIAL CHEMISTRY, a new conceptual formalism to study people's everyday social norms and moral judgments over a rich spectrum of real life situations described in natural language. We introduce SOCIAL-CHEM-101, a large-scale corpus that catalogs 292k rules-of-thumb such as “It is rude to run a blender at 5am” as the basic conceptual units. Each rule-of-thumb is further broken down with 12 different dimensions of people's judgments, including social judgments of good and bad, moral foundations, expected cultural pressure, and assumed legality, which together amount to over 4.5 million annotations of categorical labels and free-text descriptions. Comprehensive empirical results based on state-of-the-art neural models demonstrate that computational modeling of social norms is a promising research direction. Our model framework, Neural Norm Transformer, learns and generalizes SOCIAL-CHEM-101 to successfully reason about previously unseen situations, generating relevant (and potentially novel) attribute-aware social rules-of-thumb.
Assessing Moral Judgment by Large Language Models – A Survey of Available Datasets
Recent advances in language modeling have contributed to a growing emphasis on machine ethics, including researching and assessing moral judgments made by large language models (LLMs). This paper provides a critical survey of the existing datasets for exactly this assessment, with a special focus on the respective data sources. We address the current lack of theoretical grounding by providing an introduction to ethics and different frameworks from moral philosophy and moral psychology. Moreover, we identify four main data sources: webcrawled corpora, scholars, laypeople, and synthetic data generation. By discussing the strengths and weaknesses of these sources, we analyze their implications for the assessment of moral judgment. Importantly, systemizing the available datasets reveals an over-reliance on previous work, reinforcing existing shortcomings. Addressing the current limitations, we recommend adopting a consistent terminology and creating independently curated datasets based on interdisciplinary work. To ensure a clear delineation of normative approaches, we propose focusing on the assessment of moral consistency and certainty of LLMs as effective and well-defined indicators of their performance on moral judgment.
Moral Stories: Situated Reasoning about Norms, Intents, Actions, and their Consequences
In social settings, much of human behavior is governed by unspoken rules of conduct rooted in societal norms. For artificial systems to be fully integrated into social environments, adherence to such norms is a central prerequisite. To investigate whether language generation models can serve as behavioral priors for systems deployed in social settings, we evaluate their ability to generate action descriptions that achieve predefined goals under normative constraints. Moreover, we examine if models can anticipate likely consequences of actions that either observe or violate known norms, or explain why certain actions are preferable by generating relevant norm hypotheses. For this purpose, we introduce Moral Stories, a crowd-sourced dataset of structured, branching narratives for the study of grounded, goal-oriented social reasoning. Finally, we propose decoding strategies that combine multiple expert models to significantly improve the quality of generated actions, consequences, and norms compared to strong baselines.
AI Models Exceed Individual Human Accuracy in Predicting Everyday Social Norms
A fundamental question in cognitive science concerns how social norms are acquired and represented. While humans typically learn norms through embodied social experience, we investigated whether large language models can achieve sophisticated norm understanding through statistical learning alone. Across two studies, we systematically evaluated multiple AI systems' ability to predict human social appropriateness judgments for 555 everyday scenarios by examining how closely they predicted the average judgment compared to each human participant. In Study 1, GPT-4.5's accuracy in predicting the collective judgment on a continuous scale exceeded that of every human participant (100th percentile). Study 2 replicated this, with Gemini 2.5 Pro outperforming 98.7% of humans, GPT-5 97.8%, and Claude Sonnet 4 96.0%. Despite this predictive power, all models showed systematic, correlated errors. These findings demonstrate that sophisticated models of social cognition can emerge from statistical learning over linguistic data alone, challenging strong versions of theories emphasizing the exclusive necessity of embodied experience for cultural competence. The systematic nature of AI limitations across different architectures indicates potential boundaries of pattern-based social understanding, while the models' ability to outperform nearly all individual humans in this predictive task suggests that language serves as a remarkably rich repository for cultural knowledge transmission.

Values in the Wild: Discovering and Analyzing Values in Real-World Language Model Interactions
AI assistants can impart value judgments that shape people's decisions and worldviews, yet little is known empirically about what values these systems rely on in practice. To address this, we develop a bottom-up, privacy-preserving method to extract the values (normative considerations stated or demonstrated in model responses) that Claude 3 and 3.5 models exhibit in hundreds of thousands of real-world interactions. We empirically discover and taxonomize 3,307 AI values and study how they vary by context. We find that Claude expresses many practical and epistemic values, and typically supports prosocial human values while resisting values like "moral nihilism". While some values appear consistently across contexts (e.g. "transparency"), many are more specialized and context-dependent, reflecting the diversity of human interlocutors and their varied contexts. For example, "harm prevention" emerges when Claude resists users, "historical accuracy" when responding to queries about controversial events, "healthy boundaries" when asked for relationship advice, and "human agency" in technology ethics discussions. By providing the first large-scale empirical mapping of AI values in deployment, our work creates a foundation for more grounded evaluation and design of values in AI systems.
AI for identifying social norm violation
Identifying social norms and their violation is a challenge facing several projects in computational science. This paper presents a novel approach to identifying social norm violations. We used GPT-3, zero-shot classification, and automatic rule discovery to develop simple predictive models grounded in psychological knowledge. Tested on two massive datasets, the models present significant predictive performance and show that even complex social situations can be functionally analyzed through modern computational tools.
The Psychology of Normative Cognition
From an early age, humans exhibit a tendency to identify, adopt, andenforce the norms of their local communities. Norms are the socialrules that mark out what is appropriate, allowed, required, orforbidden in different situations for various community members. Theserules are informal in the sense that although they are sometimesrepresented in formal laws, like the rule governing which side of theroad to drive on, they need not be explicitly codified to effectivelyinfluence behavior. There are rules that forbid theft or the breakingof promises, but also rules that govern how close it is appropriate tostand to someone while talking to them, or how loud one should talkduring the conversation. Thus understood, norms regulate a wide rangeof activity. They exhibit cultural variability in their prescriptionsand proscriptions, but the presence of norms in general appears to beculturally universal. Some norms exhibit characteristics that areoften associated with morality, such as a rule that applies toeveryone and prohibits causing unnecessary harm. Other norms applyonly to certain people, such as those that delimit appropriateclothing for members of different genders, or those concerning theexpectations and responsibilities ascribed to individuals who occupypositions of leadership. The norms that prevail in a community can bemore or less fair, reasonable, or impartial, and can be subject tocritique and change.
Measuring Social Norms of Large Language Models
We present a new challenge to examine whether large language models understand social norms. In contrast to existing datasets, our dataset requires a fundamental understanding of social norms to solve. Our dataset features the largest set of social norm skills, consisting of 402 skills and 12,383 questions covering a wide set of social norms ranging from opinions and arguments to culture and laws. We design our dataset according to the K-12 curriculum. This enables the direct comparison of the social understanding of large language models to humans, more specifically, elementary students. While prior work generates nearly random accuracy on our benchmark, recent large language models such as GPT3.5-Turbo and LLaMA2-Chat are able to improve the performance significantly, only slightly below human performance. We then propose a multi-agent framework based on large language models to improve the models' ability to understand social norms. This method further improves large language models to be on par with humans. Given the increasing adoption of large language models in real-world applications, our finding is particularly important and presents a unique direction for future improvements.
AI language model rivals expert ethicist in perceived moral expertise
People view AI as possessing expertise across various fields, but the perceived quality of AI-generated moral expertise remains uncertain. Recent work suggests that large language models (LLMs) perform well on tasks designed to assess moral alignment, reflecting moral judgments with relatively high accuracy. As LLMs are increasingly employed in decision-making roles, there is a growing expectation for them to offer not just aligned judgments but also demonstrate sound moral reasoning. Here, we advance work on the Moral Turing Test and find that Americans rate ethical advice from GPT-4o as slightly more moral, trustworthy, thoughtful, and correct than that of the popular New York Times advice column, The Ethicist. Participants perceived GPT models as surpassing both a representative sample of Americans and a renowned ethicist in delivering moral justifications and advice, suggesting that people may increasingly view LLM outputs as viable sources of moral expertise. This work suggests that people might see LLMs as valuable complements to human expertise in moral guidance and decision-making. It also underscores the importance of carefully programming ethical guidelines in LLMs, considering their potential to influence users’ moral reasoning.

The Fragility Of Moral Judgment In Large Language Models
People increasingly use large language models (LLMs) for everyday moral and interpersonal guidance, yet these systems cannot interrogate missing context and judge dilemmas as presented. We introduce a perturbation framework for testing the stability and manipulability of LLM moral judgments while holding the underlying moral conflict constant. Using 2,939 dilemmas from r/AmItheAsshole (January-March 2025), we generate three families of content perturbations: surface edits (lexical/structural noise), point-of-view shifts (voice and stance neutralization), and persuasion cues (self-positioning, social proof, pattern admissions, victim framing). We also vary the evaluation protocol (output ordering, instruction placement, and unstructured prompting). We evaluated all variants with four models (GPT-4.1, Claude 3.7 Sonnet, DeepSeek V3, Qwen2.5-72B) (N=129,156 judgments). Surface perturbations produce low flip rates (7.5%), largely within the self-consistency noise floor (4-13%), whereas point-of-view shifts induce substantially higher instability (24.3%). A large subset of dilemmas (37.9%) is robust to surface noise yet flips under perspective changes, indicating that models condition on narrative voice as a pragmatic cue. Instability concentrates in morally ambiguous cases; scenarios where no party is assigned blame are most susceptible. Persuasion perturbations yield systematic directional shifts. Protocol choices dominate all other factors: agreement between structured protocols is only 67.6% (kappa=0.55), and only 35.7% of model-scenario units match across all three protocols. These results show that LLM moral judgments are co-produced by narrative form and task scaffolding, raising reproducibility and equity concerns when outcomes depend on presentation skill rather than moral substance.
Judging facts, judging norms: Training machine learning models to judge humans requires a modified approach to labeling data
As governments and industry turn to increased use of automated decision systems, it becomes essential to consider how closely such systems can reproduce human judgment. We identify a core potential failure, finding that annotators label objects differently depending on whether they are being asked a factual question or a normative question. This challenges a natural assumption maintained in many standard machine-learning (ML) data acquisition procedures: that there is no difference between predicting the factual classification of an object and an exercise of judgment about whether an object violates a rule premised on those facts. We find that using factual labels to train models intended for normative judgments introduces a notable measurement error. We show that models trained using factual labels yield significantly different judgments than those trained using normative labels and that the impact of this effect on model performance can exceed that of other factors (e.g., dataset size) that routinely attract attention from ML researchers and practitioners. , Machine learning systems trained with factual features as labels do not reproduce human rule violation judgments on the same data.

Norm theory: Comparing reality to its alternatives.
Discover this 1986 paper in Psychological Review by Kahneman, Daniel; and, Miller, Dale T. focusing on: Attribution; Emotional Responses; Social Norms; Judgment; Models Abstract: Presents a theory of norms and normality and applies the theory to phenomena of emotional responses, social judgment, and conversations about causes. Norms are assumed to be constructed ad hoc by recruiting specific representations. Category norms are derived by recruiting exemplars. Specific objects or events generate their own norms by retrieval of similar experiences stored in memory or by construction of counterfactual alternatives. The normality of a stimulus is evaluated by comparing it with the norms that it evokes after the fact, rather than to precomputed expectations. Norm theory is applied in analyses of the enhanced emotional response to events that have abnormal causes, of the generation of predictions and inferences from observations of behavior, and of the role of norms in causal questions and answers. (3 p ref) (PsycInfo Database Record (c) 2025 APA, all rights reserved)
Bayesian Inference of Social Norms as Shared Constraints on Behavior
People act upon their desires, but often, also act in adherence to implicit social norms. How do people infer these unstated social norms from others' behavior, especially in novel social contexts? We propose that laypeople have intuitive theories of social norms as behavioral constraints shared across different agents in the same social context. We formalize inference of norms using a Bayesian Theory of Mind approach, and show that this computational approach provides excellent predictions of how people infer norms in two scenarios. Our results suggest that people separate the influence of norms and individual desires on others' actions, and have implications for modelling generalizations of hidden causes of behavior.
Practicing with Language Models Cultivates Human Empathic Communication
Empathy is central to human connection, yet people often struggle to express it effectively. In blinded evaluations, large language models (LLMs) generate responses that are often judged more empathic than human-written ones. Yet when a response is attributed to AI, recipients feel less heard than when comparable responses are attributed to a human. We built a conversation platform in which participants are asked to offer empathic support to an LLM expressing realistic troubles and conducted a randomized experiment collecting 33,938 messages spanning 2,904 text-based conversations between 968 participants and their LLM conversational partners. We find participants report feeling empathy but systematically fail to express it, but an LLM coaching intervention offering personalized feedback on effective empathic communication significantly boosts it without homogenizing participants' responses. Moreover, we derive a data-driven taxonomy of idiomatic empathic expressions in naturalistic dialogues across personal and workplace trouble scenarios. These results advance the scientific understanding of how empathy is expressed and demonstrate a scalable, AI-based intervention for scaffolding and cultivating it.
Rethinking Norm Psychology
Norms permeate human life. Most of people’s activities can be characterized by rules about what is appropriate, allowed, required, or forbidden—rules that are crucial in making people hyper-cooperative animals. In this article, I examine the current cognitive-evolutionary account of “norm psychology” and propose an alternative that is better supported by evidence and better placed to promote interdisciplinary dialogue. The incumbent theory focuses on rules and claims that humans genetically inherit cognitive and motivational mechanisms specialized for processing these rules. The cultural-evolutionary alternative defines normativity in relation to behavior—compliance, enforcement, and commentary—and suggests that it depends on implicit and explicit processes. The implicit processes are genetically inherited and domain-general; rather than being specialized for normativity, they do many jobs in many species. The explicit processes are culturally inherited and domain-specific; they are constructed from mentalizing and reasoning by social interaction in childhood. The cultural-evolutionary, or “cognitive gadget,” perspective suggests that people alive today—parents, educators, elders, politicians, lawyers—have more responsibility for sustaining normativity than the nativist view implies. People’s actions not only shape and transmit the rules, but they also create in each new generation mental processes that can grasp the rules and put them into action.

Reason-Mediated Behavioral Models for Auditing LLM Social Simulators
Large language models are increasingly used as social simulators, including as synthetic survey respondents. Most evaluations ask whether simulated outcomes resemble human outcomes. We argue that this is necessary but too weak: a simulator can match the final answer while using the wrong behavioral mechanism. We study this problem through a 94-person sunscreen concept test in which each respondent evaluated three product concepts and wrote open-ended rationales. We map those rationales into signed reason states $Z$, where positive signs support adoption and negative signs block it. This gives a practical audit: holding respondent descriptors $D$, category context $K$, and concept treatment $X$ fixed, do human-stated reasons help predict behavior $Y$, and can an LLM simulate the same reason state without seeing the human rationale or outcome? Human-stated reasons substantially improve held-out prediction of purchase intent. LLM-simulated reasons are more brittle: they often sound plausible, but frequently echo the concept board rather than recover the respondent's acceptance or rejection path. The paper contributes an evaluation framework for social simulators. Reason states do not identify natural causal effects by themselves, but they provide an interpretable test of whether a simulator's stated reasons align with human evidence.
Redesigning algorithms to intervene on social norm misperceptions during a national election
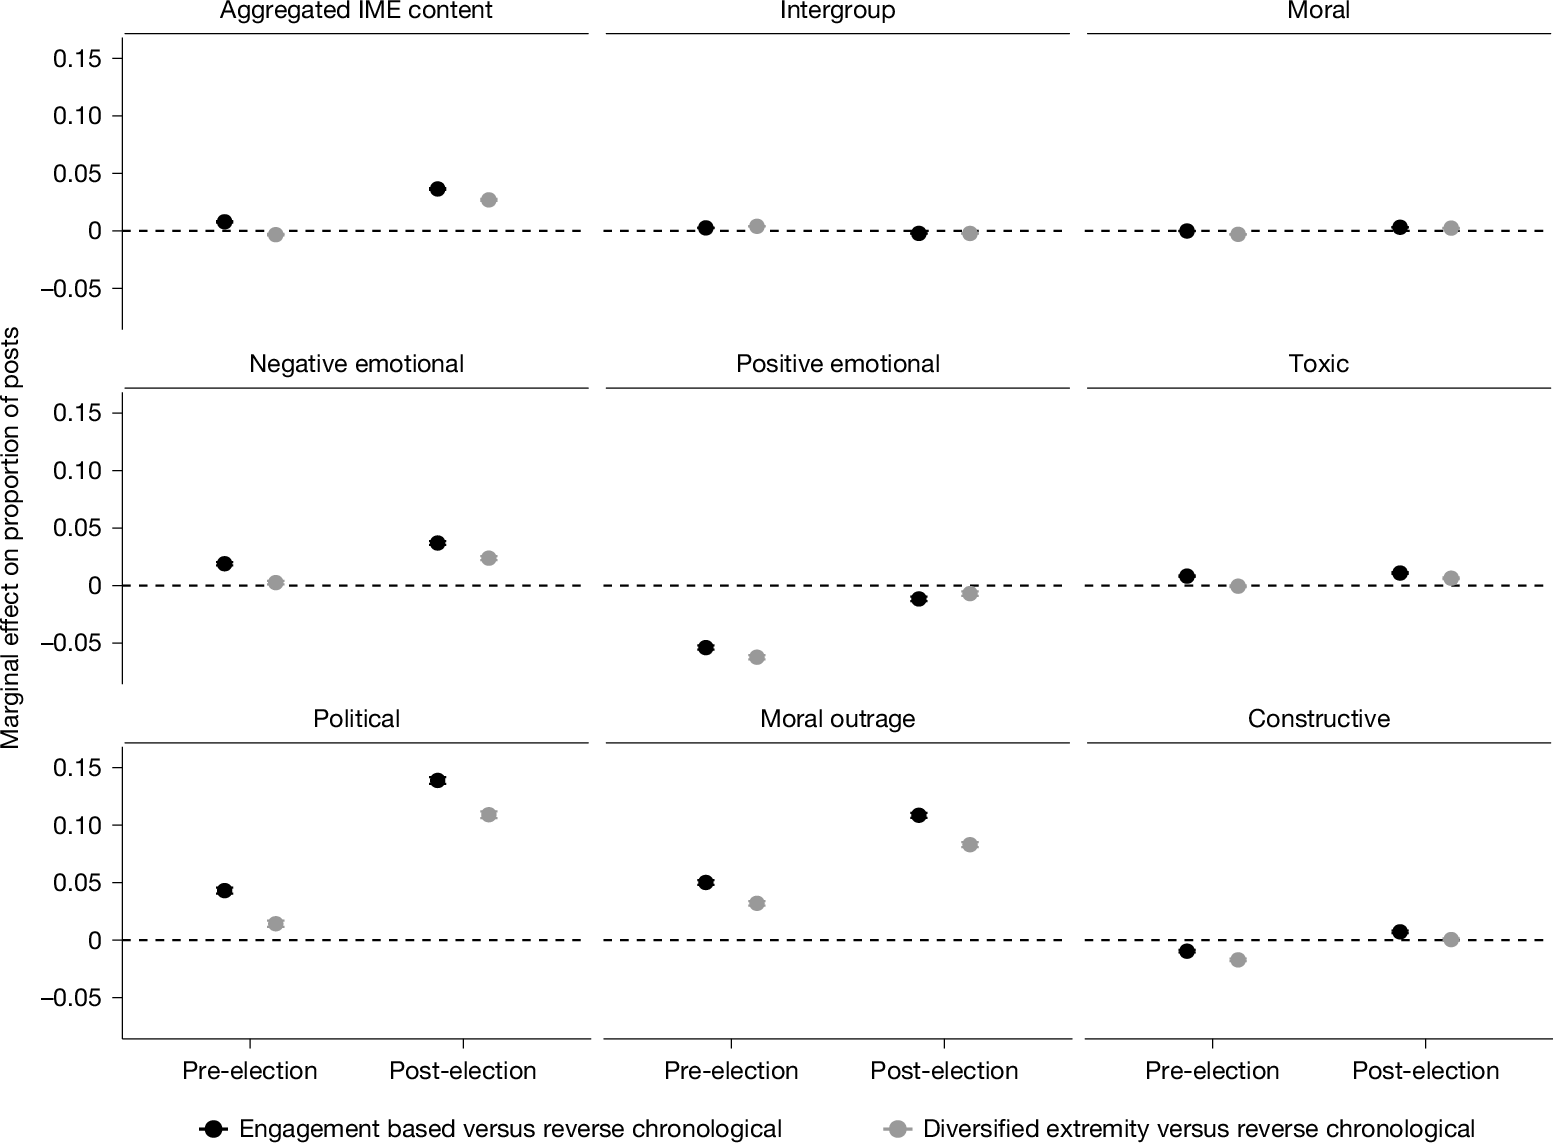
For the first time in history, civic discourse commonly occurs in digital environments in which algorithms influence exposure to social information1,2. It is increasingly important to understand whether and how these algorithms affect political discourse3–5. Here we built custom feed-ranking algorithms with full control over their features, and randomly assigned 2,000 participants to use them for 8 weeks (before and after the 2024 US presidential election). We tested whether an engagement-based algorithm (used on major social media platforms6,7) amplifies intergroup, moralized and emotional (IME) information in ways that skew perceptions of social norms around political dialogue5,8, and whether it increased engagement with IME content and perceptions of partisan animosity (compared with a reverse-chronological feed9,10). We also developed and tested a ‘diversified extremity’ algorithm to reduce the influence of extreme users11–13 to improve the accuracy of social norm perception14–16 and reduce perceptions of partisan animosity. We found that engagement-based feeds amplified IME and toxic content relative to reverse-chronological feeds, with the largest increases in moral outrage and political content. Engagement-based feeds also reduced prescriptive norm perception accuracy (albeit in an unexpected direction) and increased perceived partisan animosity. However, they did not significantly alter users’ own engagement behaviours. The diversified extremity algorithm reduced IME and toxic content exposure, improved prescriptive norm accuracy, yet maintained comparable platform enjoyment—suggesting that reducing the influence of extreme users can curb algorithmic distortions without diminishing user experience.