

Research is rarely limited to a single contributor performing a single role. Behind every research output are people contributing in various ways: software development, data analyses, methodology design, and much more. Often, the same person contributes in several of these ways. Until now, Crossref metadata could only capture part of that picture, but this is changing with Schema 5.5.
You are Crossref - Crossref
Crossref runs open infrastructure to link research objects, entities, and actions—creating a lasting and reusable scholarly record that underpins open science. Together with our >25,000 members in 167 countries, we drive metadata exchange and support 2.1 billion monthly API queries, facilitating global research communication, for the benefit of society.

Manuscript submission systems and metadata completeness in Crossref: Patterns and associations
The importance of open research information, particularly publication metadata, is widely recognised. Crossref is one of the most important infrastructures for registering open metadata as part of DOI record registration. It is widely known, however, that the metadata of many publications is far from complete, with many publishers making certain metadata openly available, but failing to do so for other metadata elements. Publishers’ ability to register this metadata with Crossref depends on their capacity to capture and retain this data in their production workflows. Manuscript submission systems are an important, yet largely overlooked, factor in the extent to which publishers make metadata available through Crossref. In this paper, we present the results of an analysis investigating the relation between the level of metadata that publishers deposit with Crossref and the submission systems that they deploy for their journals. We have looked at the 153 publishers with the largest amounts of publications in Crossref and concentrate on the four most commonly used systems: Editorial Manager, ScholarOne, Open Journal Systems (OJS) and eJournalPress. We show that some submission systems appear better suited to capturing certain metadata elements. However, there are always cases where publishers using the same system differ widely in the level of metadata they register, suggesting that technology is not the only prohibiting factor and other considerations are at play.
Crossref: The sustainable source of community-owned scholarly metadata
This paper describes the scholarly metadata collected and made available by Crossref, as well as its importance in the scholarly research ecosystem. Containing over 106 million records and expanding at an average rate of 11% a year, Crossref’s metadata has become one of the major sources of scholarly data for publishers, authors, librarians, funders, and researchers. The metadata set consists of 13 content types, including not only traditional types, such as journals and conference papers, but also data sets, reports, preprints, peer reviews, and grants. The metadata is not limited to basic publication metadata, but can also include abstracts and links to full text, funding and license information, citation links, and the information about corrections, updates, retractions, etc. This scale and breadth make Crossref a valuable source for research in scientometrics, including measuring the growth and impact of science and understanding new trends in scholarly communications. The metadata is available through a number of APIs, including REST API and OAI-PMH. In this paper, we describe the kind of metadata that Crossref provides and how it is collected and curated. We also look at Crossref’s role in the research ecosystem and trends in metadata curation over the years, including the evolution of its citation data provision. We summarize the research used in Crossref’s metadata and describe plans that will improve metadata quality and retrieval in the future.
Two billion citation links in Crossref help research travel further - Crossref
We’ve recently reached an important milestone for the research nexus: the works in our metadata corpus are now connected with over 2 billion citation links! This is a great opportunity to share a dedicated dataset and discuss why these are important for science.
How Grobid uses Crossref metadata to enrich bibliographic information - Crossref
Crossref members register around 37,000 records daily. All this metadata is openly shared with the global scholarly community through our free APIs. We receive over two billion calls to our API each month, signalling its use by hundreds of tools and services worldwide, supporting the discovery and assessment of scholarly metadata. As part of a new series in our blog, we will spotlight the diversity of tools and integrations that rely on Crossref metadata to serve the scholarly community. In this initial post, we chat to Luca Foppiano, the developer and maintainer of Grobid1, to learn about how Grobid uses Crossref metadata to improve the extraction and enrichment of bibliographic information from scholarly PDFs.
Scholarly blogs and their place in the research nexus - Crossref
If you are reading this blog on our website, you may have noticed that alongside each post we now list a Crossref DOI link, which was not the case a few months ago (though we have retroactively added DOIs to all older posts too). You can find the persistent link for this post right above this paragraph. Go on, click on it, we’ll wait.
The Research Nexus vision for a more connected scholarly community
Crossref envisions “a rich and reusable open network of relationships connecting research organizations, people, things, and actions; a scholarly record that the global community can build on forever, for the benefit of society”. This Research Nexus expands on the importance of research objects being persistently and uniquely identified. The scholarly community has an established practice of connecting things such as citations to others’ work and it is increasingly critical to identify relationships beyond citations, bringing together published work, unpublished work, institutions, individuals, and identifying the actions that they take e.g., funding, publishing, creating, modifying, citing, and sharing. The Research Nexus brings together metadata and relationships to build a joined-up picture of the scholarly ecosystem and helps everyone identify these relationships and how they change through time. This vision is possible if all parts of the scholarly ecosystem (and beyond) work together, including various scholarly infrastructure organizations.

Crossmark - Crossref
The Crossmark button gives readers quick and easy access to the current status of an item of content, including any corrections, retractions, or updates to that record. Crossmark provides a cross-platform way for readers to quickly discover the status of a research output along with additional metadata related to the editorial process. Crucially, the Crossmark button can also be embedded in PDFs, which means that members have a way of alerting readers to changes months or even years after it’s been downloaded.
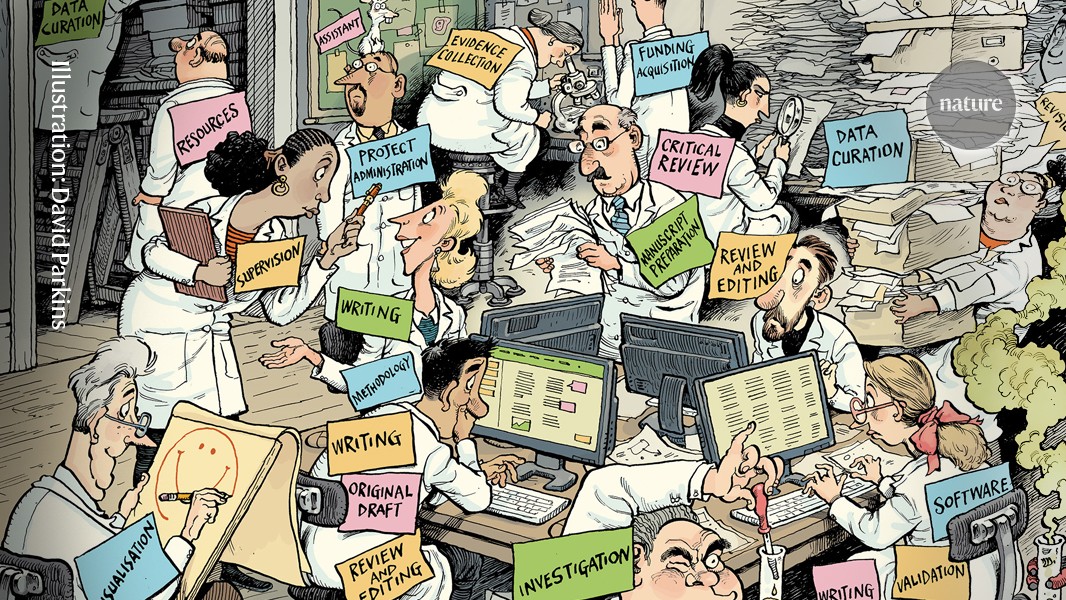
A ten-year drive to credit authors for their work — and why there’s still more to do
Nature - Information about the roles of each author of a paper can help to build trust, integrity and responsible research assessment. Coordinated efforts are needed to consolidate progress.
MIRA 2026 - Modular Interoperable Research Attribution
Catalyzing Modular Interoperable Research Attribution - A workshop to design and prototype interoperable frameworks for modular research attribution. June 7-11, 2026 in Ireland.
MIRA 2026 - Modular Interoperable Research Attribution
Catalyzing Modular Interoperable Research Attribution - A workshop to design and prototype interoperable frameworks for modular research attribution. June 7-11, 2026 in Ireland.
Composing schema mappings: Second-order dependencies to the rescue: ACM Transactions on Database Systems: Vol 30, No 4
A schema mapping is a specification that describes how data structured under one schema (the source schema) is to be transformed into data structured under a different schema (the target schema). A fundamental problem is composing schema mappings: given ...

SemRepo: A Knowledge Graph for Research Software and Its Scholarly Ecosystem
We present SemRepo, an RDF knowledge graph comprising over 81 million triples describing nearly 200,000 GitHub repositories associated with scientific research. SemRepo captures repository-level metadata, such as contributors, issues, and programming languages, and interlinks this information with external scholarly knowledge graphs. In particular, repository authors are linked to their profiles in SemOpenAlex, repositories are connected to scholarly publications in LPWC, and research artifacts, such as datasets and experiments, are linked via MLSea-KG. This integration enables queries that span publications and their scholarly artifacts, which are typically fragmented across separate platforms. SemRepo supports analyses that are difficult to perform with existing resources in isolation, including provenance reconstruction across repositories and publications, as well as the systematic identification of risks to research reproducibility and software sustainability. By unifying research software with its scholarly context in a single graph, SemRepo provides an important infrastructure for large-scale analysis of software within the broader scientific research ecosystem.

SemRepo.org
SemRepo is a large-scale RDF knowledge graph of GitHub repositories linked to scientific research. SemRepo captures fine-grained repository-level metadata (e.g., contributors, issues, programming languages) and interlinks this with external scholarly knowledge graphs: repositories to publications in LPWC, repository authors to their profiles in SemOpenAlex, and research artifacts (e.g., datasets, experiments) are linked via MLSea.
Scholary infrastructure and the research nexus

The research nexus is "a rich and reusable open network of relationships connecting research organisations, people, things, and actions; a scholarly record that the global community can build on forever, for the benefit of society." (crossref.org/documentation/research-nexus/)
How Grobid uses Crossref metadata to enrich bibliographic information - Crossref
Schema 5.5 now available: adding CRediT, new record types for blogs and posters, and more - Crossref
Scholarly blogs and their place in the research nexus - Crossref
Rogue Scholar
SemRepo.org
Science discussions of retracted articles on Bluesky: public scrutiny or misinformation spreading?