

Drafted between April 24 and July 28, 2024. Published July 28th, 2024.
Pinata | Autonomous File Storage
Add file uploads and retrieval in minutes so you can focus on your app —because you’ve got better things to code than infrastructure.

Computer Files Are Going Extinct
Technology services are changing our internet habits
Karpathy's LLM Knowledge Base Wiki for Enterprise | Vijoy Pandey posted on the topic | LinkedIn
There's a new kind of computer media in the enterprise: Write once, Read never. The docs are perpetually stale, constantly diverging from reality, and scattered across Confluence, SharePoint, GitHub, Webex (or Slack) threads, Notion, Obsidian - and in my personal life, add Apple Notes, Goodnotes, web clippings, and multiple Google Drives worth of docs and slides that nobody is ever going back to. Karpathy tweeted his LLM knowledge base wiki architecture which went viral last weekend and I decided to give it a run yesterday. Verdict: You *have* to try this out. Prediction: You won’t be able to live without it soon. There were a few mods and decisions I made to the base Karpathy provided. First, the vault / folder structure in Obsidian. I already use Obsidian as a human. Instead of creating separate vaults and dealing with the sync nightmare, I just have folders for Human and Agent, and a Raw folder. (1) The Human/ folder is where I write long form articles and notes independent of the knowledge base wiki. No LLM or agent touches this folder. (2) I do have Arnold Layne, my OpenClaw agent, doing background tasks for me. Raw/ is where both Arnold and I, dump raw snippets. Inclusive of diverse kinds of media. (3) The Agent/ folder is where the LLM (Claude in my case) synthesizes the wiki. No human touches this folder. Second, some customizations to CLAUDE.md for enterprise-like usage - (4) Domain extensions - the agent needs to know that quantum computing and agentic AI have different entity types and different provenance thresholds. (5) Primary source protection, when I drop in my own original work, secondary sources can extend it or raise questions against it, but they cannot overwrite it. It sounds like a small thing but its’s not, especially at enterprise scale where provenance actually matters. Karpathy is upfront that what he’s built is working memory for a single agent, and it’s truly remarkable at that. The jump to Shared Context across teams, reconciling conflicting beliefs at org scale, ontologies that don’t collapse under the weight of a hundred contributors - those are much harder problems and what we are exploring with the Internet of Cognition. PS: The screenshot shows my Obsidian vault after just two runs: one with Karpathy’s original tweet and gist file itself (so meta!) and one with our Internet of Cognition paper. Claude (Sonnet) read it, compiled it into structured summaries, entity pages, concept pages, backlinks, merged all the information cohesively, and keeps it all maintained from there. You just read the Wiki. It’s simply magical.

The Comprehensive Digital Preservation Platform
Create, curate, and collaborate on living archives. Start with a FREE GB.
Data Hosting & Sharing: The Open MEG Archive (OMEGA)
Welcome to the Open MEG Archive (OMEGA) The Open MEG Archive (OMEGA) is the fruit of a collaboration between the McConnell Brain Imaging Centre (BIC) of the Montreal Neurological Institute-Hospital
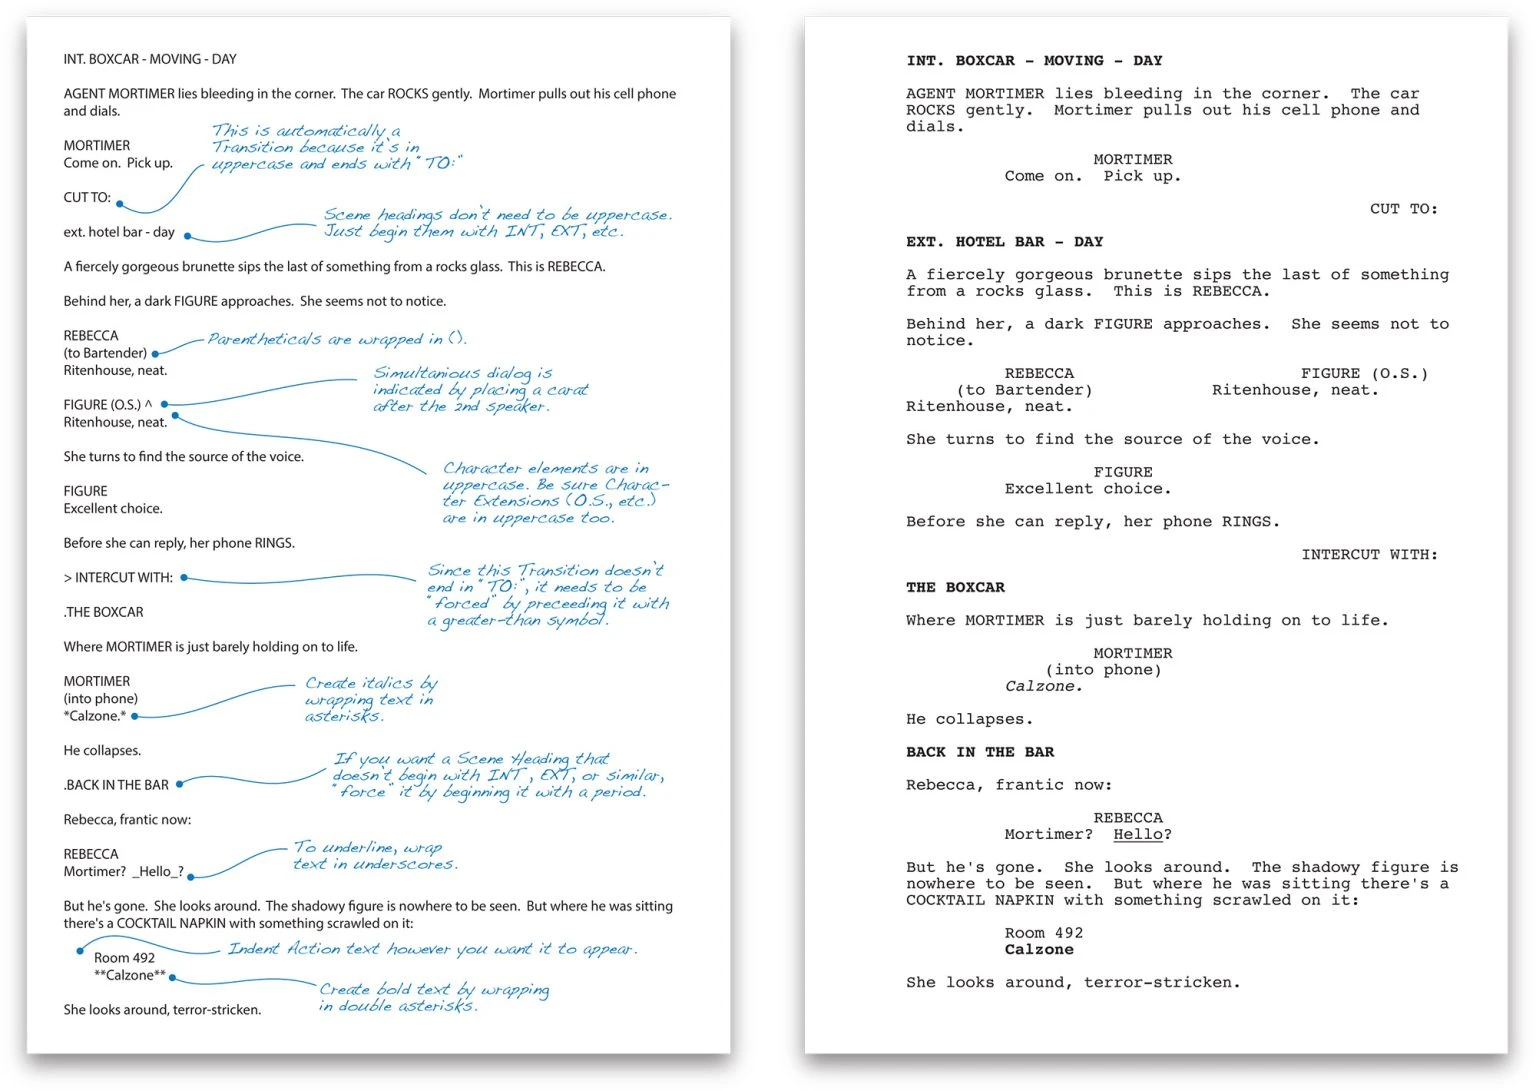
File Over App: A Philosophy for Digital Longevity
My take on the 'file over app' philosophy and why it’s essential for keeping my data resilient and built to last.
A year into the wreckage and salvage
It’s coming up on been a year, somehow, since I started this website/micro-studio/space to think in. What a wild choice that was, setting out in October of 2024, eyes on the horizon! We’d hoped things would turn out differently. The research and thinking I came
I asked Meta’s Muse for its filesystem and it sent me 6.8 GB | Mouse
I asked Muse to archive the files it could see and send them to my Google Drive. It did.
I asked Meta’s Muse for its filesystem and it sent me 6.8 GB | Mouse
I asked Muse to archive the files it could see and send them to my Google Drive. It did.
Collapse OS — Bootstrap post-collapse technology
This text was written in october 2020 (Collapse OS itself was created in early 2019).
Save Open Source, Save the World. Following up on “Why Open Source… |…
archived 17 May 2023 07:18:18 UTC

2024-09-23-TPAC-Integrity-for-the-Web.pdf
Ryan Carson on Twitter / X
I can see a future where it's much faster for all employees to use an IDE with .md files + git instead of Notion, Google Docs or Office.— Ryan Carson (@ryancarson) July 9, 2025
as a little pre-show surprise, here's an early draft of the permissioned data proposal! github.com/bluesky-social/proposals/pull…

Permissioned data by dholms · Pull Request #94 · bluesky-social/proposals
github.com
AT Protocol Developers
Don't forget, @dholms.at is joining us for the livestream TOMORROW for a permissioned data AMA.
Needed more proof the age of personal software is here? I got this Xteink X4 pocket e-reader. I flashed it with open source firmware. Then vibecoded a backend running on @val.town that pulls `toread` tagged articles from @kipclip.com and converts them to epub ...
as a little pre-show surprise, here's an early draft of the permissioned data proposal! github.com/bluesky-social/proposals/pull…
Permissioned data by dholms · Pull Request #94 · bluesky-social/proposals
github.comAT Protocol Developers
Don't forget, @dholms.at is joining us for the livestream TOMORROW for a permissioned data AMA.

