


Computational statistics, or statistical computing, is the study which is the intersection of statistics and computer science, and refers to the statistical methods that are enabled by using computational methods. It is the area of computational science specific to the mathematical science of statistics. This area is fast developing. The view that the broader concept of computing must be taught as part of general statistical education is gaining momentum.
Interleaving Computational and Inferential Thinking: Data Science for Undergraduates at Berkeley · Issue 3.2, Spring 2021
The undergraduate data science curriculum at the University of California, Berkeley is anchored in five new courses that emphasize computational thinking, inferential thinking, and the perspective gained by working on real-world problems. We believe that interleaving these elements within our core courses is essential to preparing students to engage in data-driven inquiry at the scale that contemporary scientific and industrial applications demand. This new curriculum is already reshaping the undergraduate experience at Berkeley, where these courses have become some of the most popular on campus and have led to a surging interest in a new undergraduate major and minor program in data science.

Computational Thinking for All Students
Posted by Maggie Johnson, Director of Education and University Relations, Google(Crossposted on the Google for Education Blog, and the the Huffingt...

Undergraduate Computational Science and Engineering Education
It is widely acknowledged that computational science and engineering (CSE) will play a critical role in the future of the scientific discovery process and engineering design. However, in recent years computational skills have been deemphasized in the curricula of many undergraduate programs in science and engineering. There is a clear need to provide training in CSE fundamentals at the undergraduate level. An undergraduate CSE program can train students for careers in industry, education, and for graduate CSE study. The courses developed for such a program will have an impact throughout the science, technology, engineering, and mathematics (STEM) undergraduate curriculum. This paper outlines the content of a CSE curriculum, the skills needed by successful graduates, the structure and experiences of some recently developed CSE undergraduate programs, and the potential career paths following a CSE undergraduate education.

Feminist Computer Science Education: "'Women in Computing' As Problematic": A Summary
I've long been interested in why, despite so much organized effort, there percentage of women in CS has been so stagnant. One hypothesis I h...
Niklaus Wirth
Niklaus Wirth (born 1934 in Switzerland) is one of the most prominent computer scientists, mostly known for creating Pascal and several other programming languages.
Turing: Probabalistic Programming in Julia | Cameron Pfiffer | JuliaCon 2019
About Us - Siegel Family Endowment
About Our Chairman “Computational thinking is more than just a way to approach problem solving. It’s a way of processing and understanding the world through […]
Modular: The Claude C Compiler: What It Reveals About the Future of Software
Compilers occupy a special place in computer science. They're a canonical course in computer science education. Building one is a rite of passage. It forces you to confront how software actually works, by examining languages, abstractions, hardware, and the boundary between human intent and machine execution.
zach lieberman on Twitter / X
Today I was able to weave a line from Myron Krueger in a talk I gave : Computation is the medium of our lifetimes - it’s not just a technical medium but a cultural medium as well. We should explore the culture of computation.— zach lieberman (@zachlieberman) April 10, 2024
The education of a computer
An Introduction To Robust-First Computation
Did you know there's an entire field of computer science barely yet explored? Join me at the entrance to a deep rabbit hole as we take a look at Robust-First Computation.
Konrad Hinsen's blog
How can we document software and computational analyses in such a way that others can convince themselves of their validity, and build on them for their own work? The question has been around for many years, and a number of attempts have been made to provide partial answers. This post provides a brief review and describes my own tentative answer, inviting you to play with it.
Data Structures for Statistical Computing in Python
In this paper we are concerned with the practical issues of working with data sets common to finance, statistics, and other related fields. pandas is a new library which aims to facilitate working with these data sets and to provide a set of fundamental building blocks for implementing statistical models.
And this includes any all scientific uses of AI and indeed any computational system, weather prediction, cancer research, medical imaging, mathematics, please just don't claim it's fine if you don't research automation in those areas. I'll post further resources below...

Emily M. Bender
But speaking of staying in one's lane, can we PLEASE switch the default position from "It's fine to use 'AI' for this thing I'm not an expert in" to "Yeah, I'd be really skeptical of any use cases and need to see strong evidence that it's okay, but I'm not the one who can produce that evidence"?
Computational reproducibility

The why and how of making scientific computations reproducible
The future of programming and computing

Trends and adjacent possibles for the future of how computers are used and programmed
Konrad Hinsen's blog
Home Page - Software Heritage
GNU Guix transactional package manager and distribution — GNU Guix

Keynote: Reproducibility and replicability of computer simulations | Canal U
Reproducible research: methodological principles for transparent…
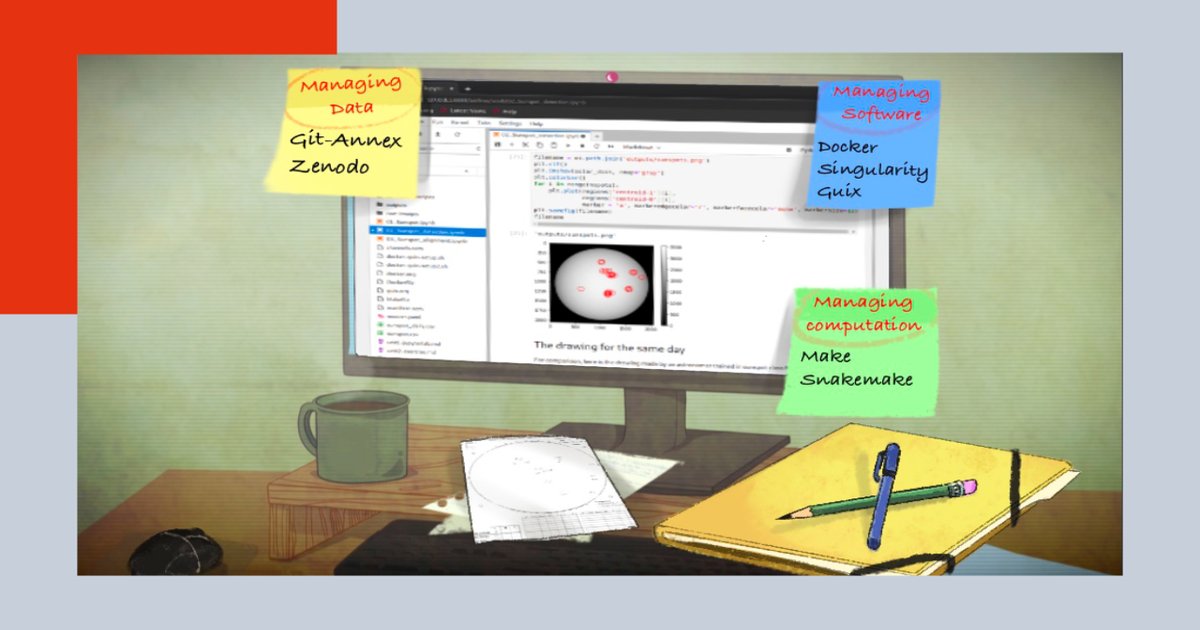
Reproducible Research II: Practices and tools for managing compu…
What Even Is An OS Now?

Maybe We Should Stop Investing in GUI-Centric Software Companies
LIMITS 2026 -- Workshop on Computing within Limits
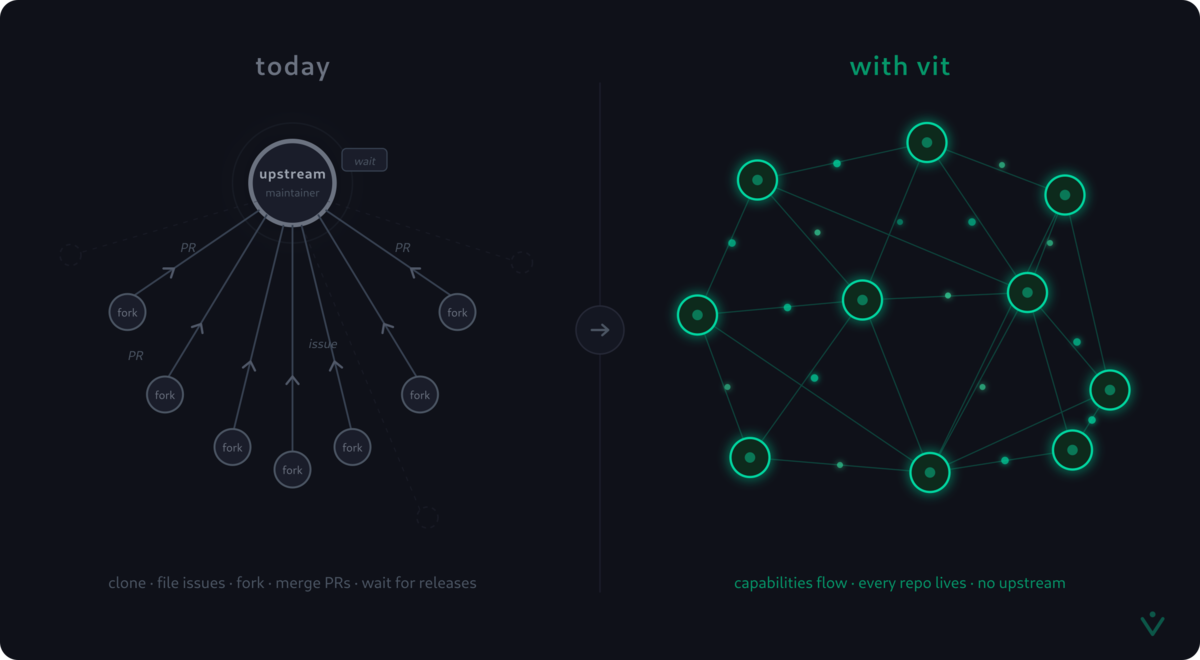
vit — open source is social

Humans approve intent, machines prove conformance
Introducing System One Models and Jev - TypeSafe AI Blog
