

In machine learning, diffusion models, also known as diffusion-based generative models or score-based generative models, are a class of latent variable generative models. A diffusion model consists of two major components: the forward diffusion process, and the reverse sampling process.[1] The goal of diffusion models is to learn a diffusion process for a given dataset, such that the process can generate new elements that are distributed similarly as the original dataset. A diffusion model models data as generated by a diffusion process, whereby a new datum performs a random walk with drift through the space of all possible data.[2] A trained diffusion model can be sampled in many ways, with different efficiency and quality.
What are Diffusion Models? | IBM
Diffusion models are generative models that “diffuse” training data with random noise, then learn to reverse the diffusion process to output new images.

The physics behind diffusion models
Diffusion Models: A Comprehensive Survey of Methods and Applications
Diffusion models have emerged as a powerful new family of deep generative models with record-breaking performance in many applications, including image synthesis, video generation, and molecule...

Optimal and Diffusion Transports in Machine Learning
Slides for a general introduction to the use of Optimal Transport methods in learning, with an emphasis on diffusion models, flow matching, training 2 l…

Introducing OUI-1: world's first model for Generative UI
A DiffusionGemma finetune at 71.7% on the Generative UI Benchmark, 5.5x its base.
Inference-Time Scaling for Generative Pre-Training | Jiaming Song
A short note on the false dichotomy between autoregression and diffusion, why flow maps help, and what this might mean for language models.
Complete guide to samplers in Stable Diffusion
Dive into the world of Stable Diffusion samplers and unlock the potential of image generation.

Research – Inception
We are leveraging diffusion technology to develop a new generation of LLMs. Our dLLMs are much faster and more efficient than traditional autoregressive LLMs.
AI models collapse when trained on recursively generated data
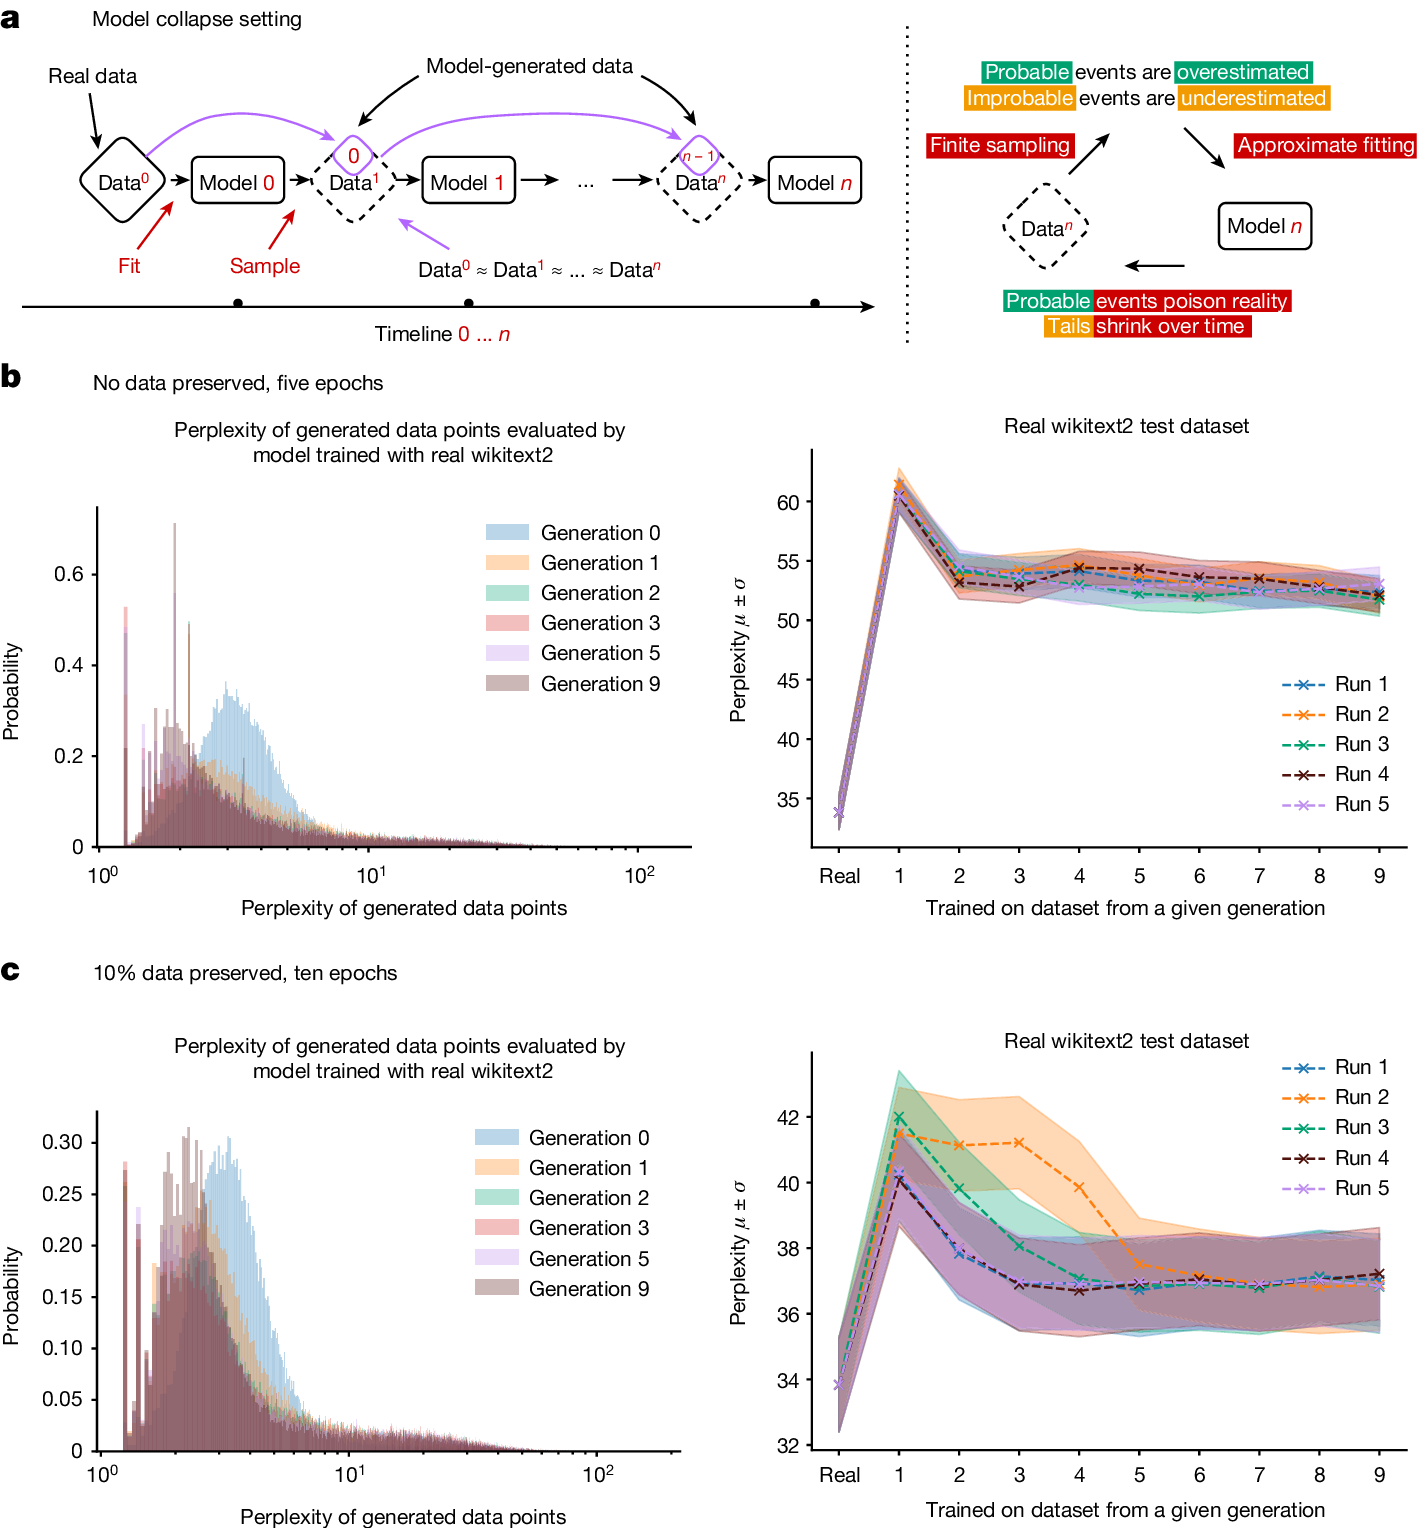
Stable diffusion revolutionized image creation from descriptive text. GPT-2 (ref. 1), GPT-3(.5) (ref. 2) and GPT-4 (ref. 3) demonstrated high performance across a variety of language tasks. ChatGPT introduced such language models to the public. It is now clear that generative artificial intelligence (AI) such as large language models (LLMs) is here to stay and will substantially change the ecosystem of online text and images. Here we consider what may happen to GPT-{n} once LLMs contribute much of the text found online. We find that indiscriminate use of model-generated content in training causes irreversible defects in the resulting models, in which tails of the original content distribution disappear. We refer to this effect as ‘model collapse’ and show that it can occur in LLMs as well as in variational autoencoders (VAEs) and Gaussian mixture models (GMMs). We build theoretical intuition behind the phenomenon and portray its ubiquity among all learned generative models. We demonstrate that it must be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of LLM-generated content in data crawled from the Internet.
AI models collapse when trained on recursively generated data
Stable diffusion revolutionized image creation from descriptive text. GPT-2 (ref. 1), GPT-3(.5) (ref. 2) and GPT-4 (ref. 3) demonstrated high performance across a variety of language tasks. ChatGPT introduced such language models to the public. It is now clear that generative artificial intelligence (AI) such as large language models (LLMs) is here to stay and will substantially change the ecosystem of online text and images. Here we consider what may happen to GPT-{n} once LLMs contribute much of the text found online. We find that indiscriminate use of model-generated content in training causes irreversible defects in the resulting models, in which tails of the original content distribution disappear. We refer to this effect as ‘model collapse’ and show that it can occur in LLMs as well as in variational autoencoders (VAEs) and Gaussian mixture models (GMMs). We build theoretical intuition behind the phenomenon and portray its ubiquity among all learned generative models. We demonstrate that it must be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of LLM-generated content in data crawled from the Internet.
mlx-examples/stable_diffusion at main · ml-explore/mlx-examples
Examples in the MLX framework. Contribute to ml-explore/mlx-examples development by creating an account on GitHub.
DiffusionGemma Technical Report
We introduce DiffusionGemma, an experimental open-weight language model that uses discrete diffusion to generate text at exceptionally high speed. Rather than decoding one token at a time, DiffusionGemma iteratively refines blocks of 256 tokens in parallel, avoiding the sequential decoding bottleneck of conventional autoregressive (AR) large language models. Instead of training from scratch, we obtain DiffusionGemma by fine-tuning the mixture-of-experts Gemma 4 model with 3.8B activated and 25.2B total parameters. Our compute-efficient two-stage training pipeline uses fewer than 10% of the starting AR model's total training token budget. The first stage uses supervised fine-tuning to teach bidirectional denoising, while the second stage combines reinforcement learning with sampler distillation to jointly improve generation quality and inference efficiency. DiffusionGemma establishes a new Pareto frontier for the trade-off between generation speed and model capability. Averaged across our full evaluation suite, it generates around 20 tokens per forward pass and achieves roughly 1,500 output tokens per second on a single NVIDIA H100 GPU, which is substantially faster than AR models even with state-of-the-art speculative decoding. DiffusionGemma also retains the starting model's support for thinking mode, multimodal inputs, and long contexts. Despite diffusion fine-tuning, it remains capable of AR generation with only minor performance degradation, suggesting a path toward hybrid diffusion-AR decoding.
The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such...
Stanford CS25: V5 I Transformers in Diffusion Models for Image Generation and Beyond
How Stable Diffusion works
Understand in a simple way how Stable Diffusion transforms a few words into a spectacular image.

The Curse of Recursion: Training on Generated Data Makes Models Forget
Stable Diffusion revolutionised image creation from descriptive text. GPT-2, GPT-3(.5) and GPT-4 demonstrated astonishing performance across a variety of language tasks. ChatGPT introduced such language models to the general public. It is now clear that large language models (LLMs) are here to stay, and will bring about drastic change in the whole ecosystem of online text and images. In this paper we consider what the future might hold. What will happen to GPT-{n} once LLMs contribute much of the language found online? We find that use of model-generated content in training causes irreversible defects in the resulting models, where tails of the original content distribution disappear. We refer to this effect as Model Collapse and show that it can occur in Variational Autoencoders, Gaussian Mixture Models and LLMs. We build theoretical intuition behind the phenomenon and portray its ubiquity amongst all learned generative models. We demonstrate that it has to be taken seriously if we are to sustain the benefits of training from large-scale data scraped from the web. Indeed, the value of data collected about genuine human interactions with systems will be increasingly valuable in the presence of content generated by LLMs in data crawled from the Internet.