

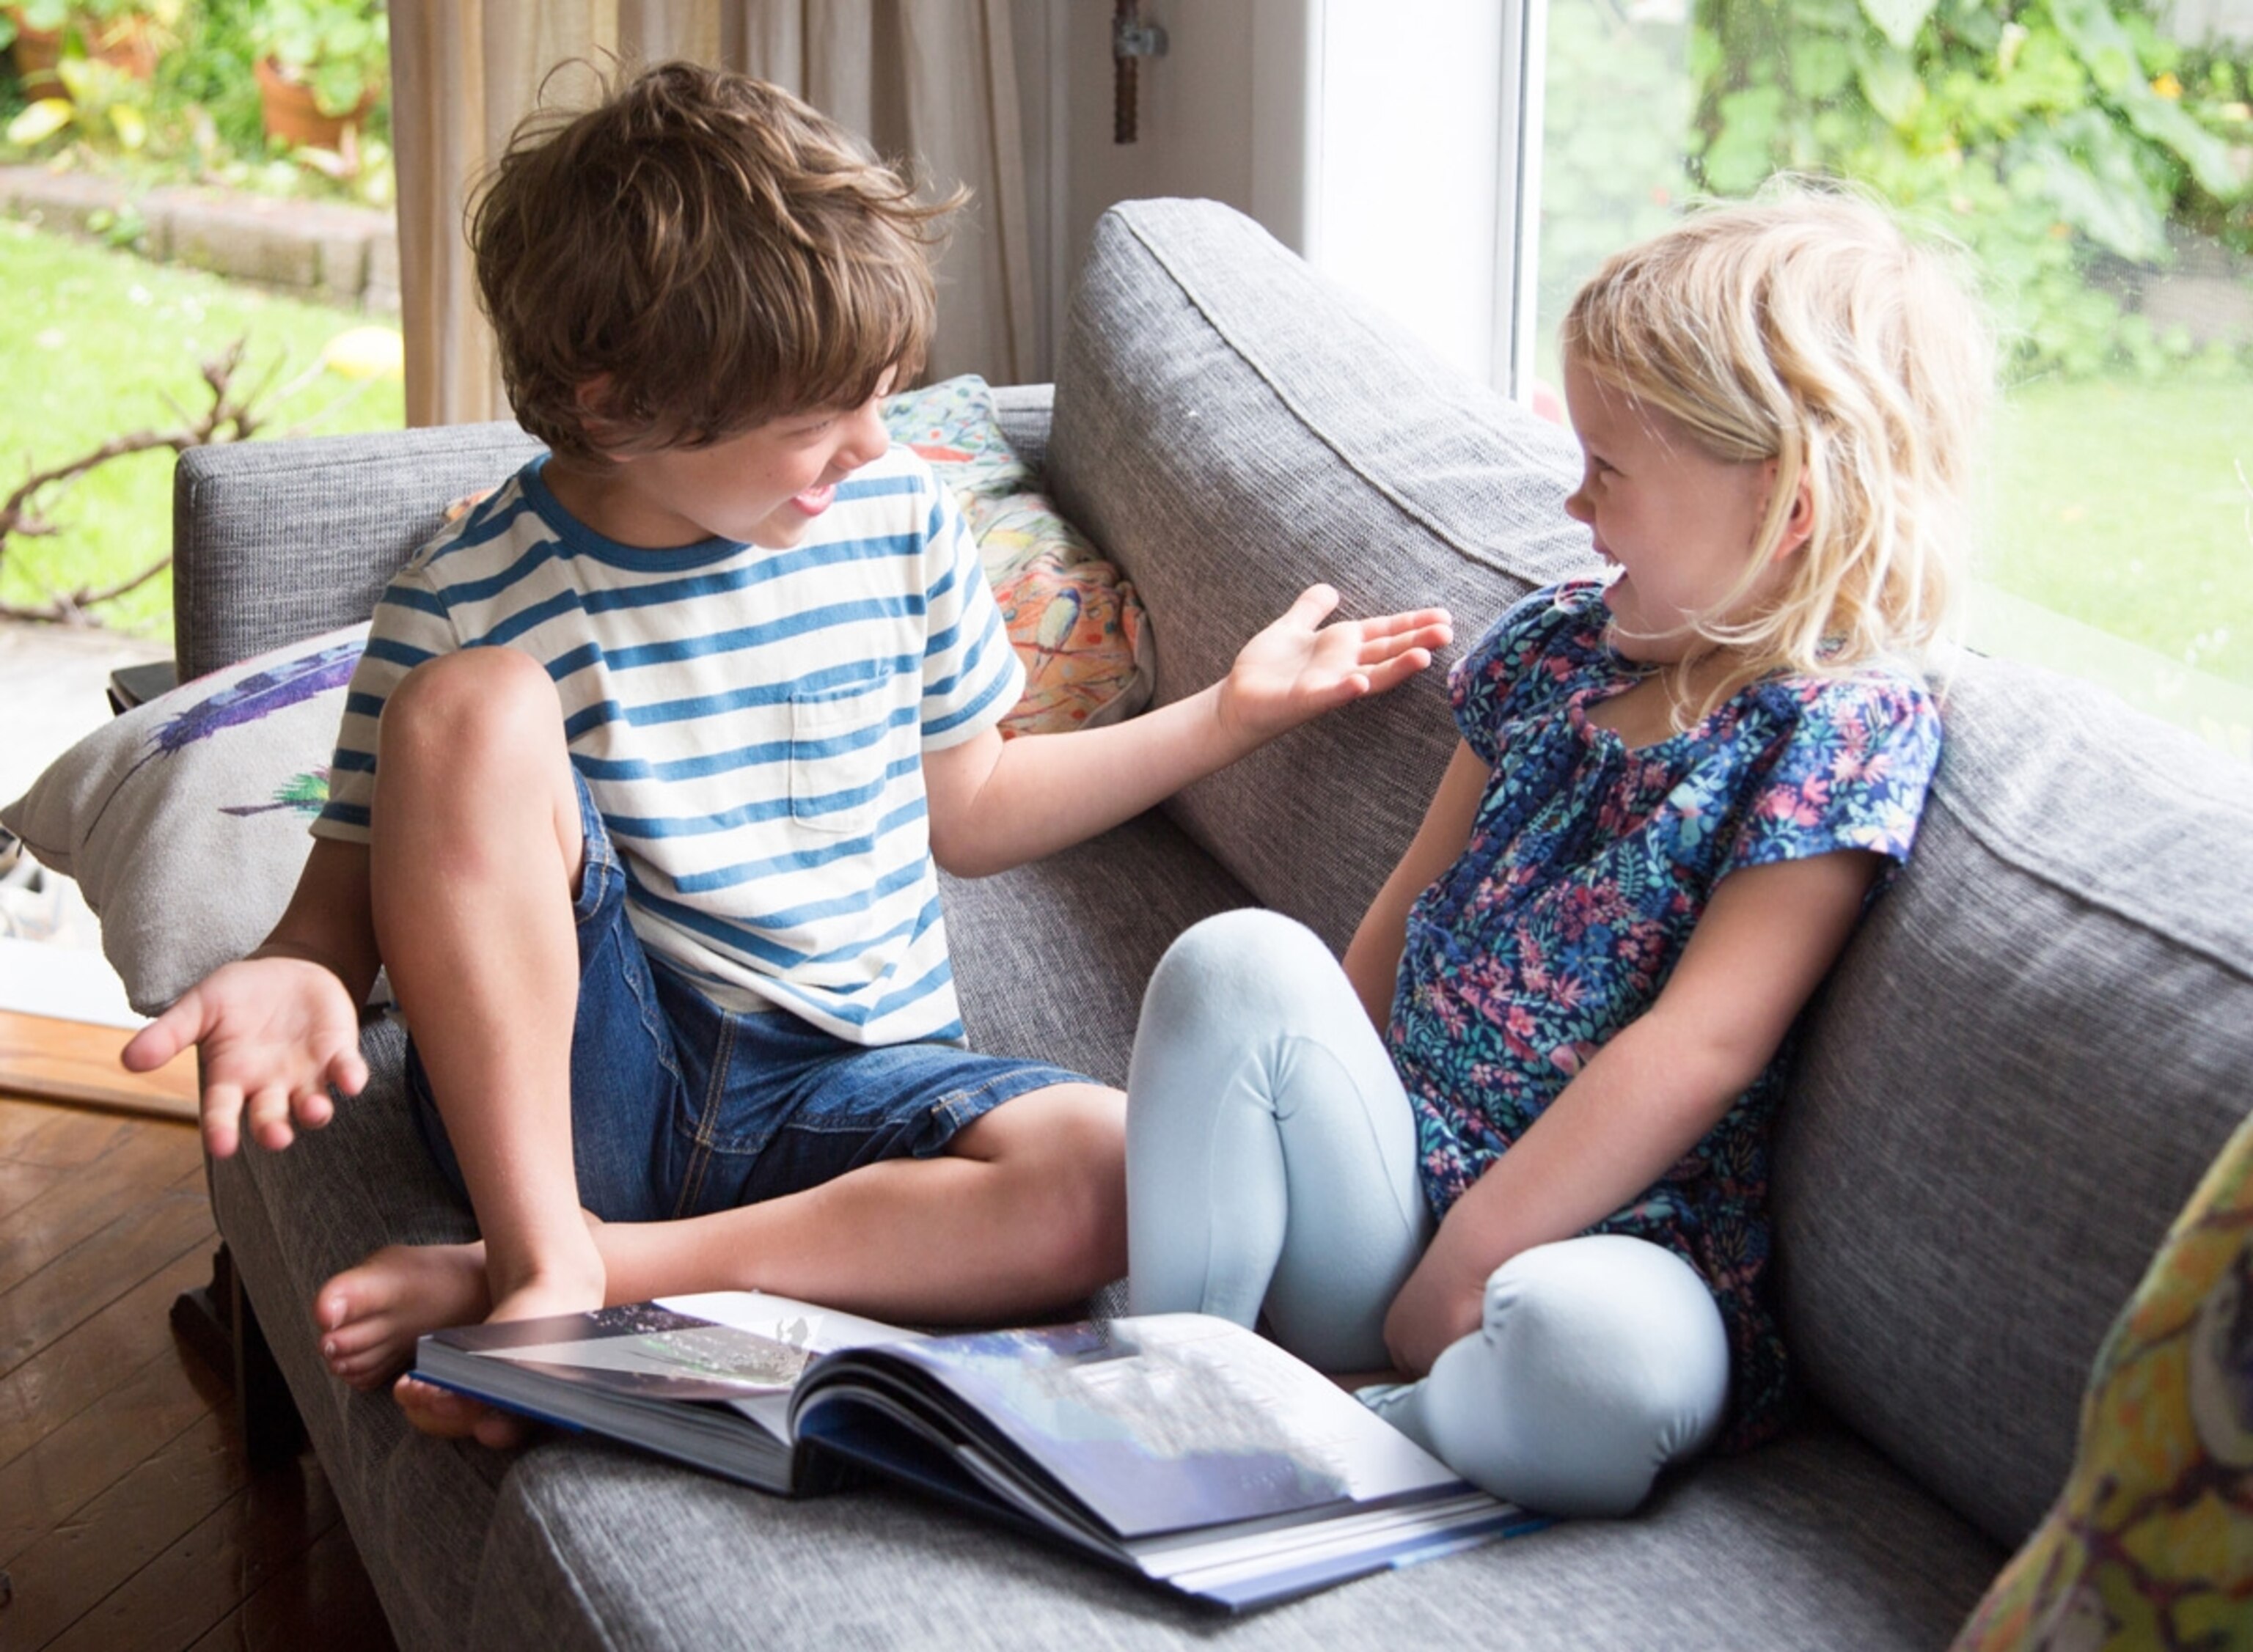
Familects often gain vocabulary through the words young children create as they learn to talk, when these words are adopted by the family.[1][2] Familects also gain vocabulary through slips of the tongue and word invention.[3]
Every family has a secret language. Experts call it ‘familect.’
The memory and meaning in our weird, family-specific words, often born of the wild minds of children.

1K views | A "familect" is a family's own private language. The word...
A "familect" is a family's own private language. The word comes from a blend of "family" and "dialect."

Why your family’s secret language is good for kids
‘That whoa-whoa is chasing the hodgie!’ Your household’s familect can strengthen bonds and develop language skills.
Word family
A word family is the base form of a word plus its inflected forms and derived forms made with suffixes and prefixes[1] plus its cognates, i.e. all words that have a common etymological origin, some of which even native speakers don't recognize as being related (e.g. "wrought (iron)" and "work(ed)").[2] In the English language, inflectional affixes include third person -s, verbal -ed and -ing, plural -s, possessive -s, comparative -er and superlative -est. Derivational affixes include -able, -er, -ish, -less, -ly, -ness, -th, -y, non-, un-, -al, -ation, -ess, -ful, -ism, -ist, -ity, -ize/-ise, -ment, in-.[1] The idea is that a base word and its inflected forms support the same core meaning, and can be considered learned words if a learner knows both the base word and the affix. Bauer and Nation proposed seven levels of affixes based on their frequency in English.[3] It has been shown that word families can assist with deriving related words via affixes, along with decreasing the time needed to derive and recognize such words.[4]
How to Implement Cognate Instruction
Teaching with cognates can help multilingual learners draw on prior knowledge to understand new vocabulary.
What is a word that is used in your family all the time, and you wish everyone else used it, too.
149 votes, 880 comments. Could be a word your family invented, or just an obscure one. UPDATE: So many great words! Anyway we can turn this into an…
What Exactly is Acquired During Skill Acquisition? | Request PDF
Request PDF | What Exactly is Acquired During Skill Acquisition? | In this paper we propose that the term skill acquisition, as commonly used in traditional psychology, and the philosophy, education, movement... | Find, read and cite all the research you need on ResearchGate
A folksonomy of lexicons - Chris's Corner
On the design and intent of different lexicons
Stephen Krashen: Language Acquisition and Comprehensible Input
Chimbridge Singlish Dictionary
Etymology, Definitions, Meaning, Usage, Synonyms, Antonyms, Origins, Languages, and more

An AT Proto lexicon currently under consideration and development
An AT Proto lexicon currently under consideration and development · GitHub

The Triadic Mind: How Language Reveals the Limits of Human Cognition
Languages are the most complex symbolic systems humans have ever created. Yet children acquire them effortlessly, without formal…
You Don’t Need Words to Think
Brain studies show that language is not essential for the cognitive processes that underlie thought
Lexicon Garden is growing - Nick's Blog
Lexicon Garden is growing and moving! With community support, the service is migrating to new infrastructure in Europe, offering better hardware and more space for new features.
Why Does ChatGPT "Delve" So Much? Exploring the Sources of Lexical Overrepresentation in Large Language Models
Scientific English is currently undergoing rapid change, with words like "delve," "intricate," and "underscore" appearing far more frequently than just a few years ago. It is widely assumed that scientists' use of large language models (LLMs) is responsible for such trends. We develop a formal, transferable method to characterize these linguistic changes. Application of our method yields 21 focal words whose increased occurrence in scientific abstracts is likely the result of LLM usage. We then pose "the puzzle of lexical overrepresentation": WHY are such words overused by LLMs? We fail to find evidence that lexical overrepresentation is caused by model architecture, algorithm choices, or training data. To assess whether reinforcement learning from human feedback (RLHF) contributes to the overuse of focal words, we undertake comparative model testing and conduct an exploratory online study. While the model testing is consistent with RLHF playing a role, our experimental results suggest that participants may be reacting differently to "delve" than to other focal words. With LLMs quickly becoming a driver of global language change, investigating these potential sources of lexical overrepresentation is important. We note that while insights into the workings of LLMs are within reach, a lack of transparency surrounding model development remains an obstacle to such research.
