


R-trees are tree data structures used for spatial access methods, i.e., for indexing multi-dimensional information such as geographical coordinates, rectangles or polygons. The R-tree was proposed by Antonin Guttman in 1984[2] and has found significant use in both theoretical and applied contexts.[3] A common real-world usage for an R-tree might be to store spatial objects such as restaurant locations or the polygons that typical maps are made of: streets, buildings, outlines of lakes, coastlines, etc. and then find answers quickly to queries such as "Find all museums within 2 km of my current location", "retrieve all road segments within 2 km of my location" (to display them in a navigation system) or "find the nearest gas station" (although not taking roads into account). The R-tree can also accelerate nearest neighbor search[4] for various distance metrics, including great-circle distance.[5]
The SQLite R*Tree Module
An R-Tree is a special index that is designed for doing range queries. R-Trees are most commonly used in geospatial systems where each entry is a rectangle with minimum and maximum X and Y coordinates. Given a query rectangle, an R-Tree is able to quickly find all entries that are contained within the query rectangle or which overlap the query rectangle. This idea is easily extended to three dimensions for use in CAD systems. R-Trees also find use in time-domain range look-ups. For example, suppose a database records the starting and ending times for a large number of events. A R-Tree is able to quickly find all events that were active at any time during a given time interval, or all events that started during a particular time interval, or all events that both started and ended within a given time interval. And so forth.
Public trees
The public tree dataset includes a listing of public trees on boulevards and public trees in parks, in the City of Vancouver and provides data on tree coordinates, species and other related characteristics. Private trees are not included in the inventory.Tree records that do not have coordinates data will not show up in the list. Data currencyThe dataset refreshes daily on weekdays. Tree attributes are updated on a regular basis but it may be several years between updates for some attributes. Priorities and resources determine how fast a change in reality is reflected in the data. The coordinates were originally provided by the 2016 Geospatial Data for City of Vancouver Street Trees project. Data accuracyTree attributes are updated on a regular basis but it may be several years for some attributes. Note: 0 value in latitude and longitude fields mean there is no related information available Websites for further informationStreet Tree BylawCity trees
TreeKIT: Measuring, Mapping, and Collaboratively Managing Urban Forests
As cities across the United States expand their stock of street trees to address a range of environmental sustainability goals, municipal foresters are increasingly turning to volunteers to supplement their tree care efforts. TreeKIT is a small non-profit organization that helps city dwellers collaboratively measure, map, and manage urban forests. Using TreeKIT’s mapping methods, volunteers are able to create spatially accurate inventories of street trees. In the process, volunteers learn to identify street trees and develop an effective appreciation for their local urban forest. The following article describes the TreeKIT mapping methods and ongoing efforts to scale these techniques for large, synchronous street tree census initiatives.
CompactLTJ: Space & Time Efficient Leapfrog Triejoin on Graph Databases
Leapfrog Triejoin (LTJ) is arguably the most practical and popular worst-case-optimal (wco) algorithm for solving basic graph patterns in graph databases. Its main drawback is that it needs the database triples (subject, predicate, object) represented as paths in a trie, for each of the six orders of subject, predicate, and object. The resulting blowup in space makes most systems disregard LTJ or implement it only partially, which makes their corresponding algorithms non-wco. In this paper we show that, by using compact data structures, it is possible to build an index that at the same time matches the query time performance of the fastest classic wco index, and uses a fraction of the space of non-wco indices (which are much slower). Concretely, we make use of compact tree representations to store functional tries using one bit per trie edge, instead of one pointer, and further reduce the space by storing partial tries. Our most compact variant uses 5–6 times less space than classic wco implementations and 2–3 times less than classic non-wco systems. At solving queries, it is on par with the fastest classic wco system, and 30–40 times faster than non-wco systems. We further incorporate improved query resolution strategies into CompactLTJ variants, which makes it considerably faster than classic wco systems as well, on queries that do not output too many results. Finally, we show how CompactLTJ can incorporate dynamism without altering its performance, even under very demanding update regimes. We leave a public fully-functional implementation of CompactLTJ that can be directly used by practitioners.

A dive into spatial search algorithms
Searching through millions of points in an instant
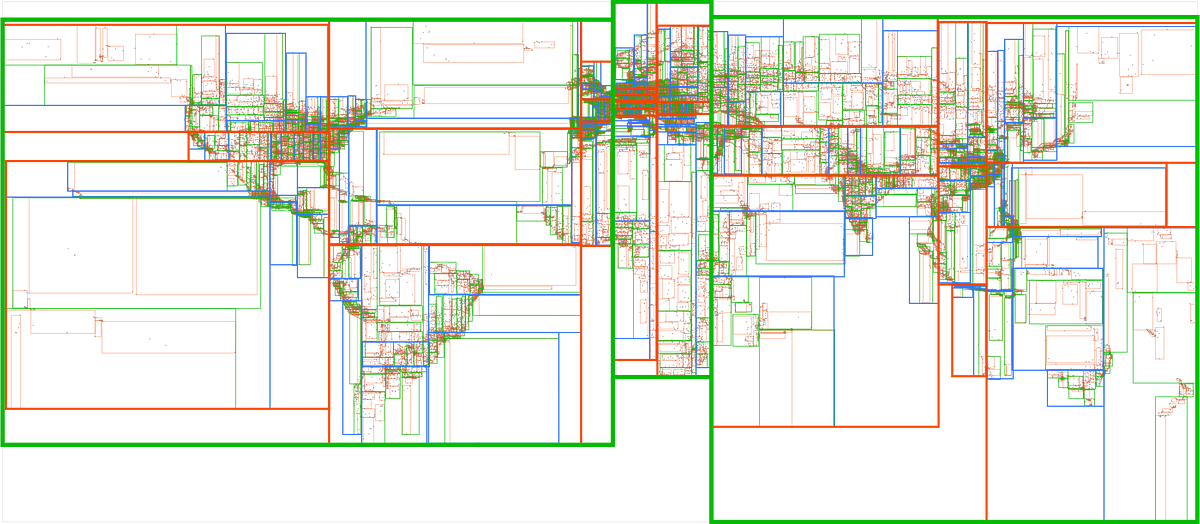
An interactive intro to quadtrees
An interactive exploration of quadtrees. Start with brute-force spatial search, build recursive space partitioning step by step, then use it for point lookups, range queries, nearest-neighbor search, collision detection, and image compression.
On Querying Historical Connectivity in Temporal Graphs
We study the historical connectivity query in temporal graphs where edges continuously arrive. Given an arbitrary time window, and two query vertices, the problem aims to identify if two vertices are connected by a path in the snapshot of the window. The state-of-the-art method designs an index based on the two-hop cover, and updating the index is costly when new edges arrive. In this paper, we propose a new framework and design a novel forest-based index for historical connectivity queries. The index enables us to answer queries by searching if two vertices are connected in the forest. We update the index by modifying a forest structure. Our techniques also work for connectivity query processing in a sliding window of temporal graphs. Extensive experiments have been conducted to show the considerable advantages of our approach compared with the state-of-the-art methods in both historical connectivity queries and sliding-window connectivity queries.

tree.fm – Tune Into Forests From Around The World 🌳🔈
People around the world recorded the sounds of their forests, so you can escape into nature, while in lockdown or unable to travel. Use this site to chill, meditate or do some digital shinrin-yoku.

GitHub - clarisma/geodesk: Fast and storage-efficient spatial database engine for OpenStreetMap data
Fast and storage-efficient spatial database engine for OpenStreetMap data - clarisma/geodesk
turbopuffer: fast search on object storage
Inaugural blog post about the development of turbopuffer, a search engine that uses object storage and SSD caching for cost-effective, low latency search. This post describes into the motivation behind its creation, its unique architecture, and how it significantly reduces costs for large-scale vector searches. Discover how turbopuffer is transforming search infrastructure for companies like Cursor and Suno, offering a scalable and reliable solution.
OldMapsOnline
The easy-to-use getaway to historical maps in libraries around the world.

Spatial Data Science
Data science is concerned with finding answers to questions on the basis of available data, and communicating that effort. Besides showing the results, this communication involves sharing the data used, but also exposing the path that led to the answers in a comprehensive and reproducible way. It also acknowledges the fact that available data may not be sufficient to answer questions, and that any answers are conditional on the data collection or sampling protocols employed.
AI could help push Neo4j graph database growth | TechCrunch
Graph databases have always been useful to help find connections across a vast data set, and it turns out that capability is quite handy in artificial

Did you know you can search for R packages by what they do, as opposed to just their names? Look! 👉🏼 rwarehouse.netlify.app @kylieainslie.bsky.social made The Warehouse for just this purpose. Send it to a new R programmer today ❤️ because it's the resource we all wish we'd had at some point #rstats
