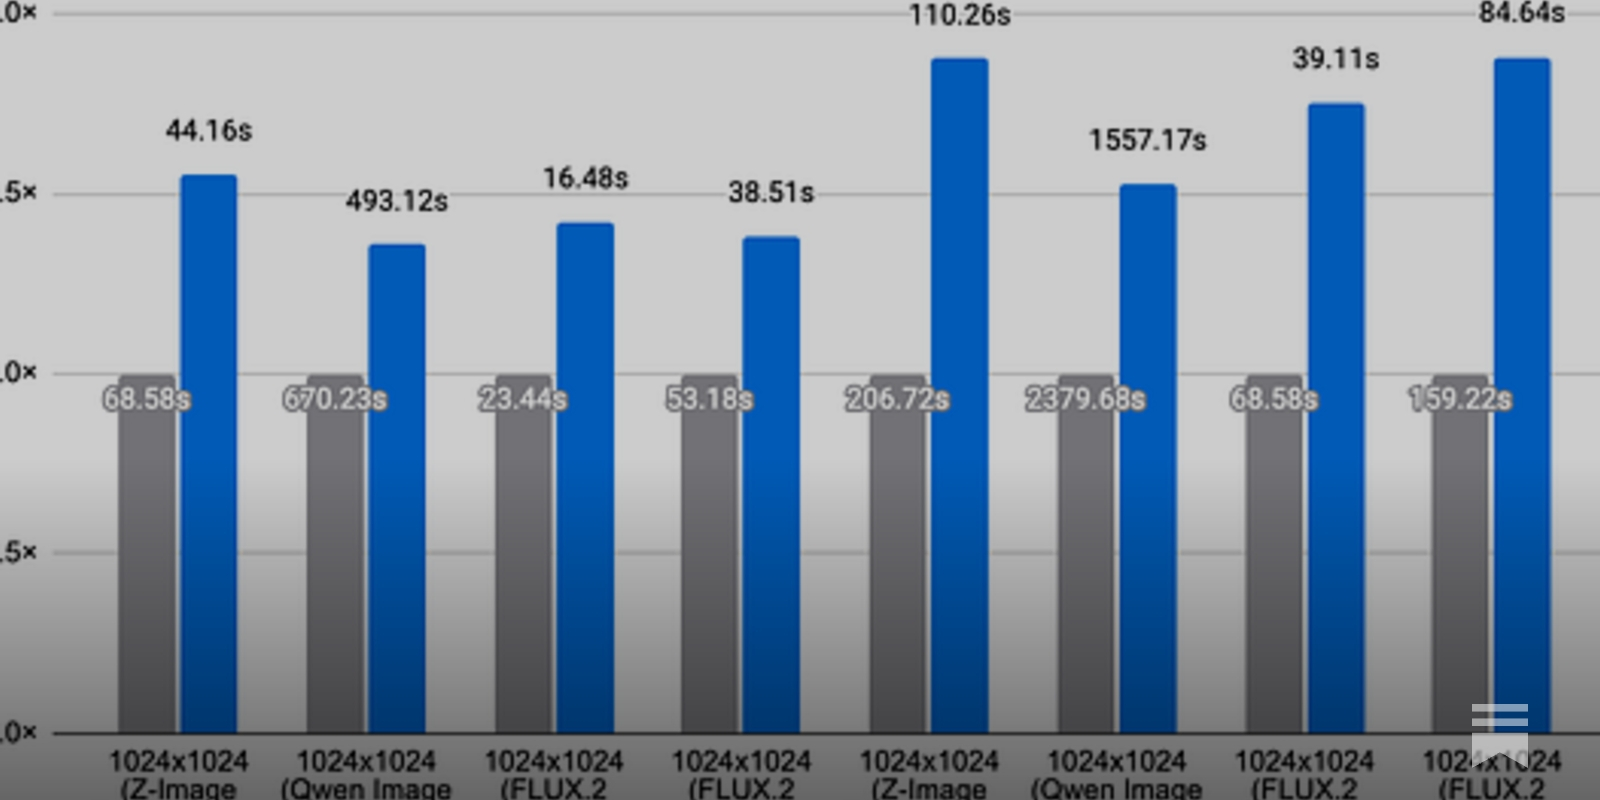
Apple Neural Engine always looked appealing on paper, but using it inside a custom runtime was harder. In 1.20260410.1, we made ANE practical for 8-bit S models by using CoreML only as an accelerator.
videlalvaro/ane-book
Production LLM inference on the Apple Neural Engine — a practitioner's guide, complete with converters, Swift runtimes, and validated model manifests
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
Anemll on Twitter / X
Up to 3.5x faster LLM inference on Apple Neural Engine:ANE is a Tensor Processing Unit, unlike GPU, it requires fixed-shape tensors. The KV cache size is set at compile time. A fixed 4096 context always runs at the slowest speed, even for short replies.Variable Context: start… pic.twitter.com/a1mLlmMYq7— Anemll (@anemll) February 16, 2026

Part 4: Brief history of Apple ML Stack
By Mirai Labs, frontier on-device AI lab. Building the models, inference runtime, and quantization stack from the device constraint up.
Ivan Fioravanti ᯅ on Twitter / X
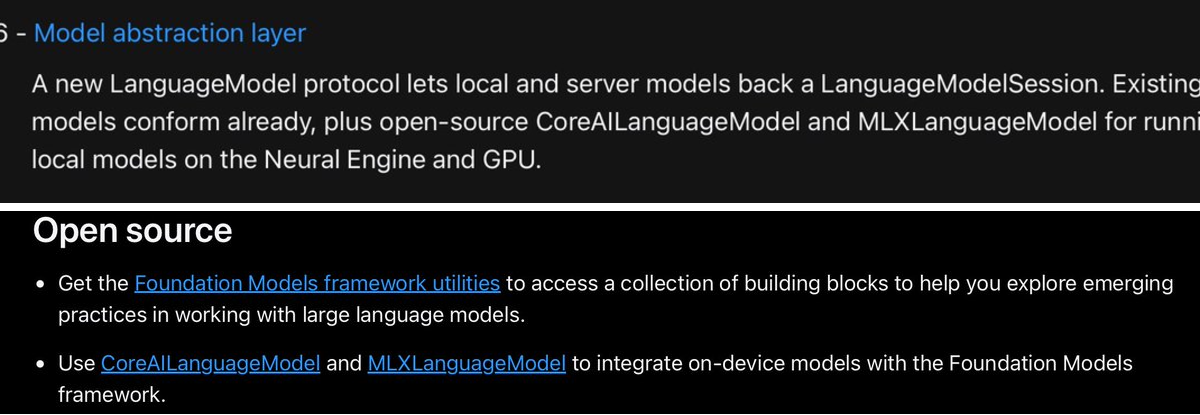
"We are releasing Open Source implementations for CoreAILanguageModel and MLXLanguageModel for running a myriad of local models on the Apple Neural Engine or your Mac's GPU" 👀 From #WWDC26: What’s new in the Foundation Models framework video: https://t.co/1NtKWYhNRs pic.twitter.com/HVtBsr3tjL— Ivan Fioravanti ᯅ (@ivanfioravanti) June 9, 2026
kerryrm/systemANE
Proof of concept using Apple's Neural Engine as a "System One" Decision Engine that escalates to Apple's Foundation Models (macOS 27)
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
raullenchai/Rapid-MLX
The fastest local AI engine for Apple Silicon. 4.2x faster than Ollama, 0.08s cached TTFT, 100% tool calling. 17 tool parsers, prompt cache, reasoning separation, cloud routing. Drop-in OpenAI replacement. Works with Claude Code, Cursor, Aider.
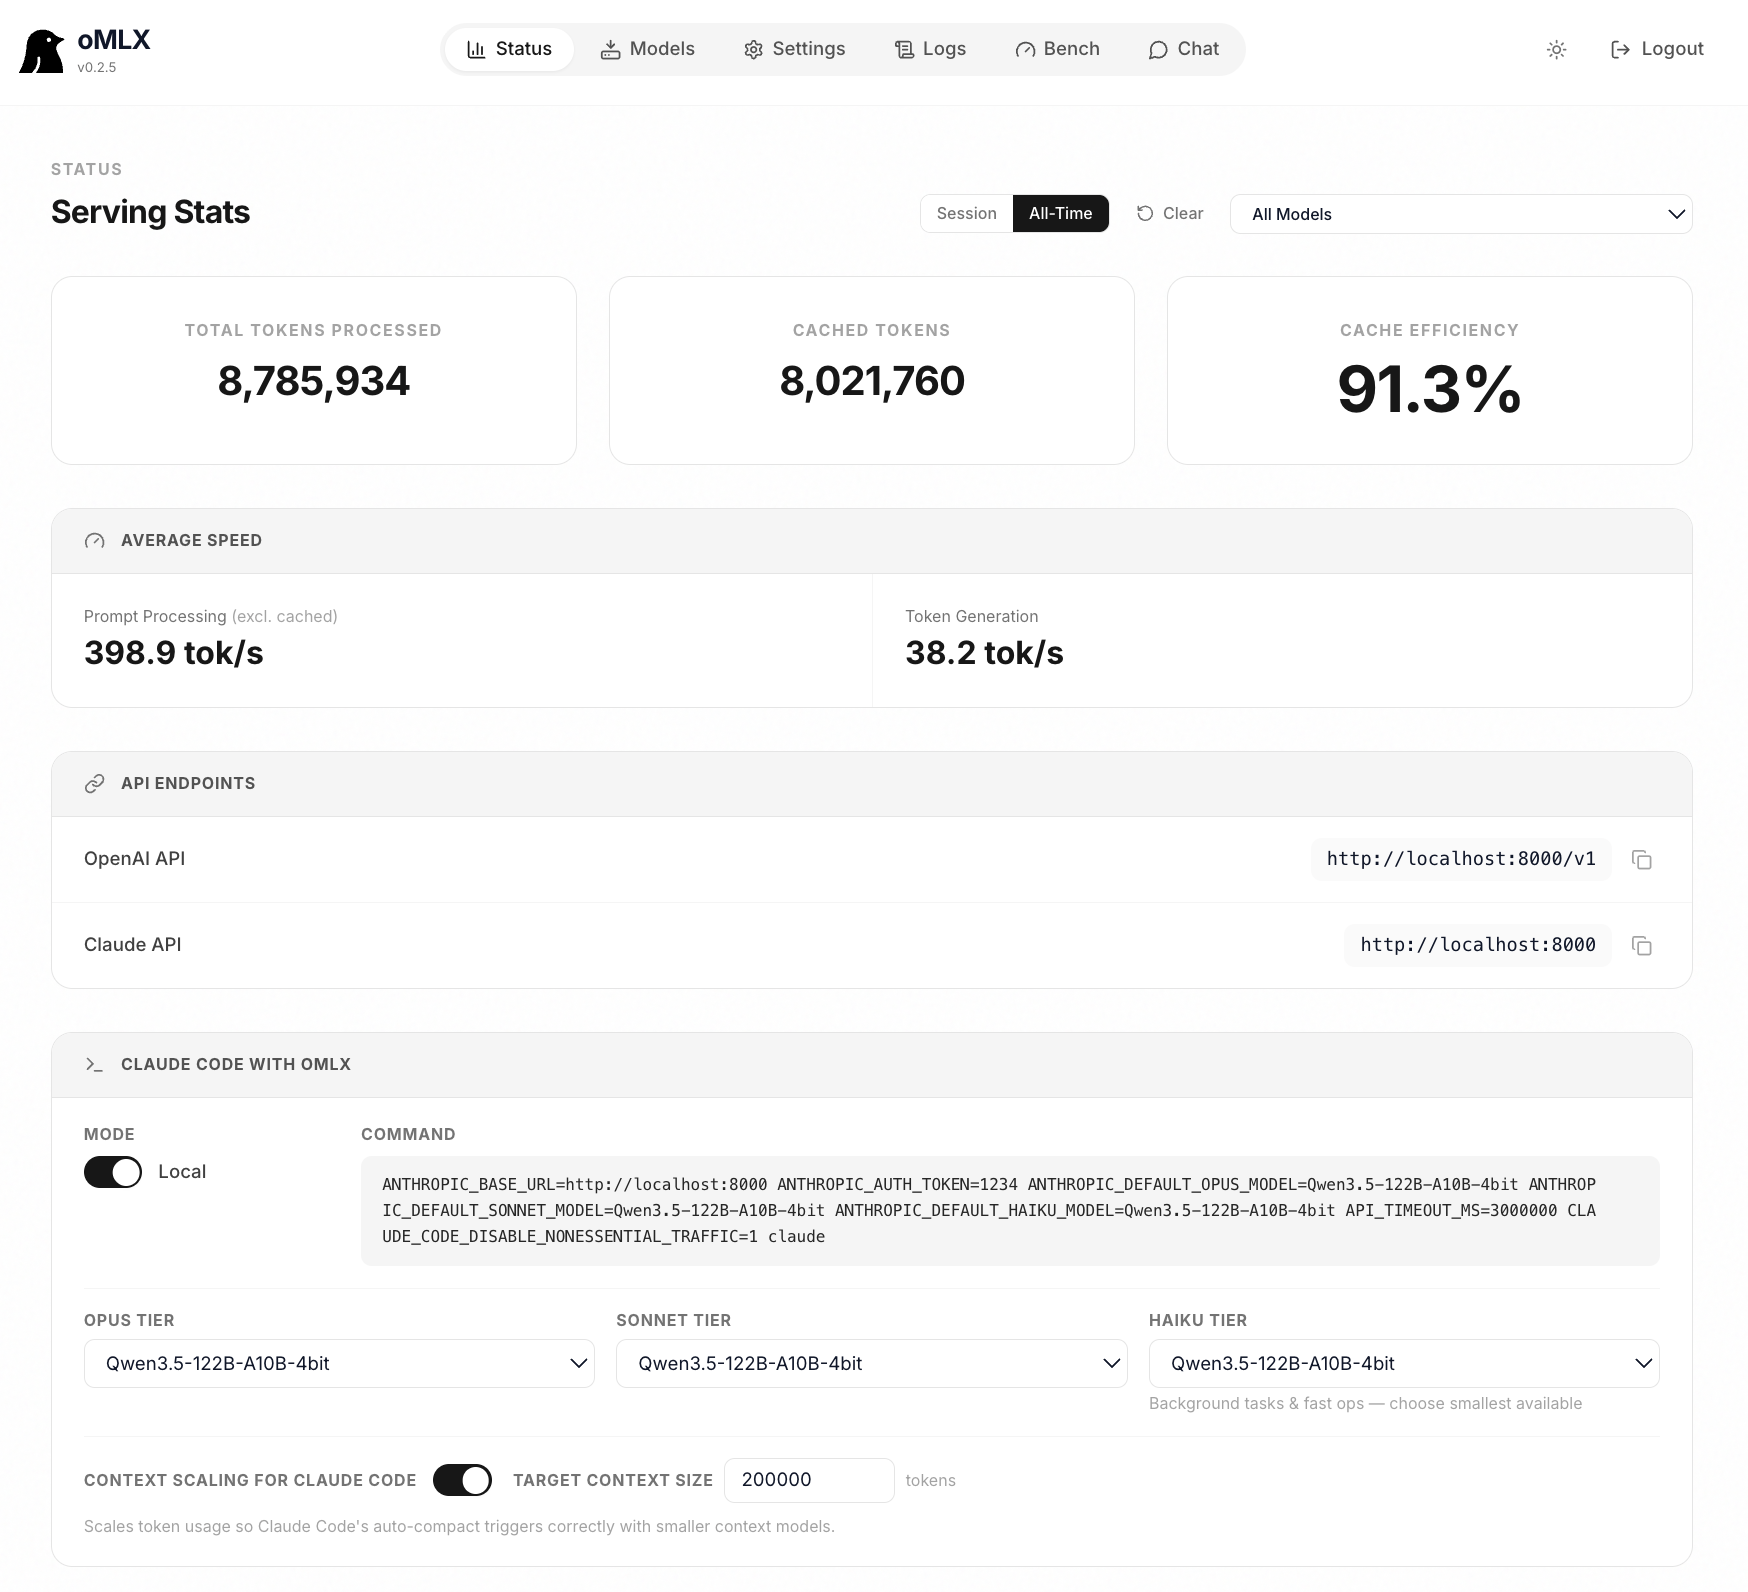
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
Introduction - How to Write an Inference Engine
A zero-to-hero guide to Muse Glimmer on Apple Metal, kvpack, and disaggregated NVFP4 prefill.
Mount Thor — AI Execution Environments on Apple Hardware
Managed macOS environments for AI workloads that require native desktop access, persistent state, or model inference on Apple silicon.
Updates to Apple’s On-Device and Server Foundation Language Models
With Apple Intelligence, we're integrating powerful generative AI right into the apps and experiences people use every day, all while…
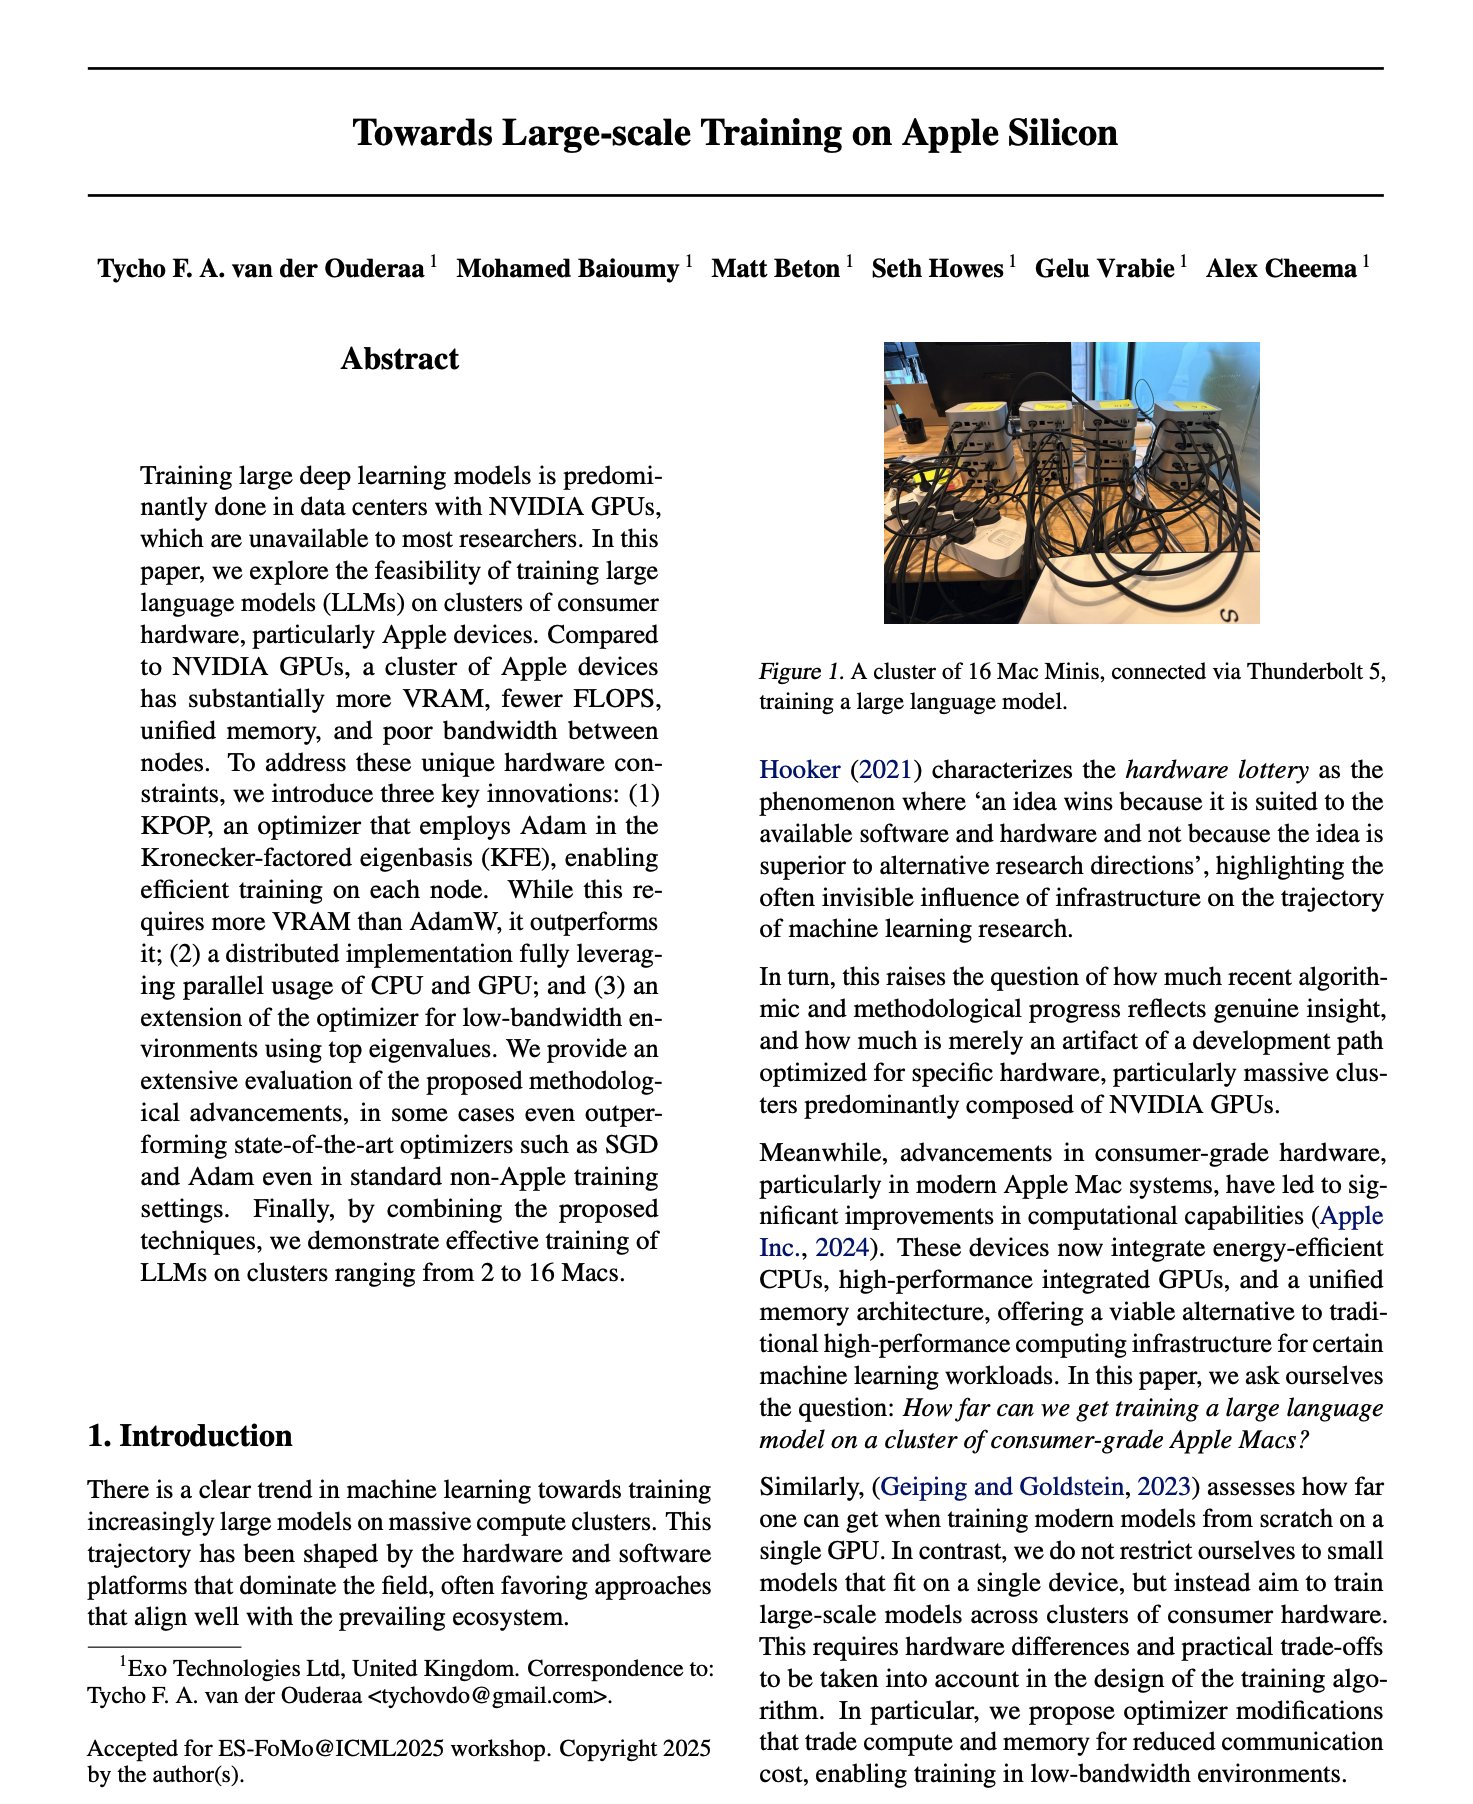
Alex Cheema on Twitter / X
A new approach to efficient large scale distributed training on Apple Silicon.Most AI research today is focused on traditional GPUs. These GPUs have a LOT of FLOPS but not much memory. They have a low memory:flops ratio. Apple Silicon has a lot more memory available for the GPU… https://t.co/FsNFnsvphJ pic.twitter.com/LFE1gtAm33— Alex Cheema (@alexocheema) July 11, 2025
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…