

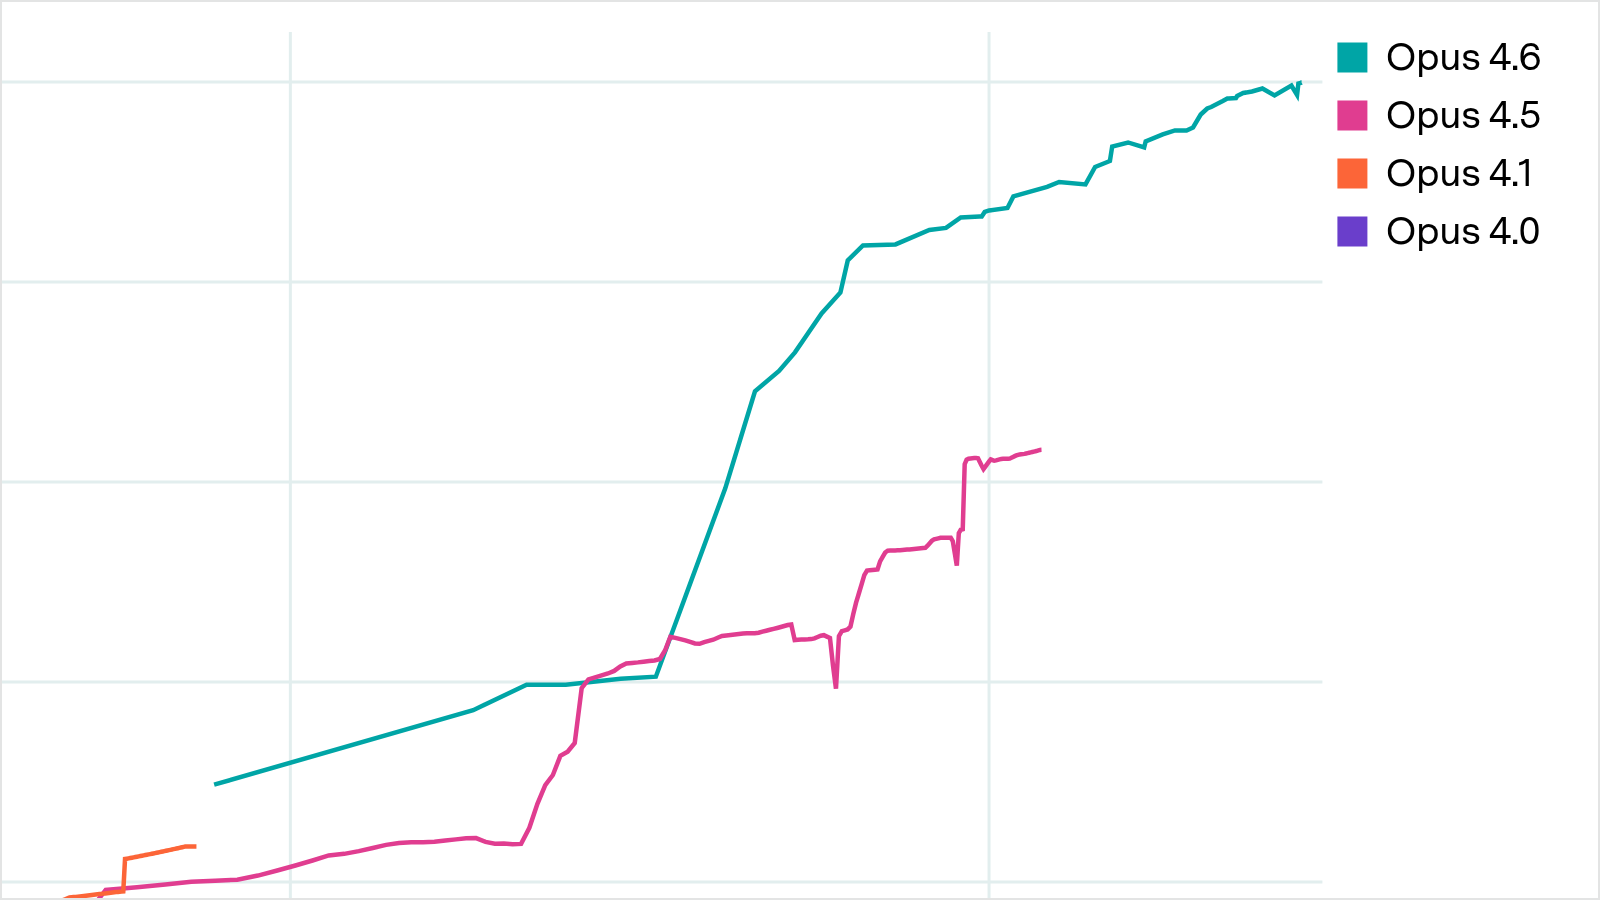
Early results from MirrorCode benchmark with METR: AI agents can complete weeks-long coding tasks, including reimplementing a 16,000-line codebase.
MirrorCode: A benchmark for real-world software projects
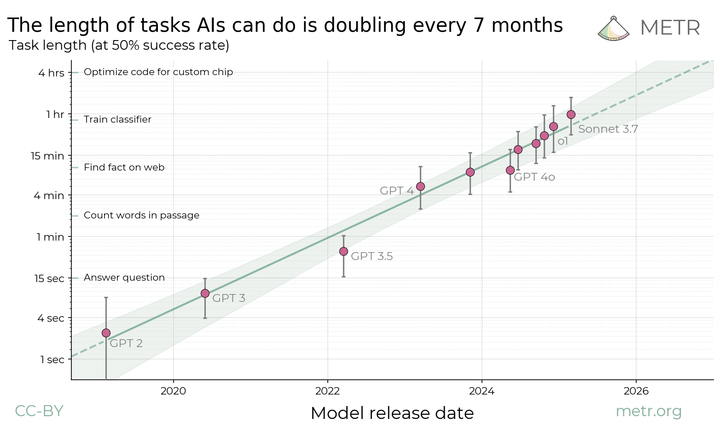
Measuring AI Ability to Complete Long Tasks
We propose measuring AI performance in terms of the *length* of tasks AI agents can complete. We show that this metric has been consistently exponentially increasing over the past 6 years, with a doubling time of around 7 months. Extrapolating this trend predicts that, in under a decade, we will see AI agents that can independently complete a large fraction of software tasks that currently take humans days or weeks.
What We Learned from Letting AI Posttrain AI
We built a posttraining task that runs for 20 hours with the Tinker API. The core bottleneck is research intuition.
AI research speeds up. Monitoring gets harder. - Sensemaker
OpenAI says coding agents now run 3.1 days for every human research day, while its chief scientist warns the lab’s main monitoring method is weakening.
scaleapi/SWE-bench_Pro-os
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
What AI coding costs you | Tom Wojcik
What's the effect of the prolonged AI usage among coders and is it tracked correctly, if it all?
Scaling long-running autonomous coding · Cursor
We've been experimenting with running coding agents autonomously for weeks at a time.
Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity
Despite widespread adoption, the impact of AI tools on software development in the wild remains understudied. We conduct a randomized controlled trial (RCT) to understand how AI tools at the February-June 2025 frontier affect the productivity of experienced open-source developers. 16 developers with moderate AI experience complete 246 tasks in mature projects on which they have an average of 5 years of prior experience. Each task is randomly assigned to allow or disallow usage of early 2025 AI tools. When AI tools are allowed, developers primarily use Cursor Pro, a popular code editor, and Claude 3.5/3.7 Sonnet. Before starting tasks, developers forecast that allowing AI will reduce completion time by 24%. After completing the study, developers estimate that allowing AI reduced completion time by 20%. Surprisingly, we find that allowing AI actually increases completion time by 19%--AI tooling slowed developers down. This slowdown also contradicts predictions from experts in economics (39% shorter) and ML (38% shorter). To understand this result, we collect and evaluate evidence for 20 properties of our setting that a priori could contribute to the observed slowdown effect--for example, the size and quality standards of projects, or prior developer experience with AI tooling. Although the influence of experimental artifacts cannot be entirely ruled out, the robustness of the slowdown effect across our analyses suggests it is unlikely to primarily be a function of our experimental design.

Separating signal from noise in coding evaluations
A new analysis from OpenAI reveals issues in SWE-Bench Pro, a popular coding benchmark, raising concerns about reliability and accuracy in evaluating AI models.
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
Large Language Model (LLM) agents have been widely adopted in modern software development workflows. SWE-bench [13] and related works [23, 24, 22, 25, 15] establish the task of issue resolution as a de-facto standard for assessing their capability and usefulness. In this setting, an agent is given an entire codebase, a task description (e.g., a bug report or feature request) in natural language and is instructed to produce a code patch that resolves the issue and passes the repository’s test suite. These benchmarks have been instrumental in demonstrating both the substantial potential and the persistent limitations of current models as SWE agents.
TasteVal: Measuring the Experimental Research Taste of AI Systems Against Human Experts
We introduce TasteVal, a benchmark to evaluate the experimental research taste of frontier models. We define research taste as the ability to pick interesting problems to solve, design experiments, and interpret experimental results. TasteVal measures the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes. We operationalize experimental research taste as compute efficiency; a Researcher who reaches the same score as an expert human using half the serial experimental compute has twice the experimental taste. Experimental taste thus acts as a multiplier on experimental compute, making it a key input to forecasts of AI progress. TasteVal consists of 8 novel, challenging, open-ended tasks representative of frontier AI R&D. To isolate taste from coding ability, the model under evaluation acts as a Researcher that iteratively designs experiments while a fixed Coder agent implements them and reports their results. The Researcher executes until either the 40 H100 hour or 120 wall-clock hour budgets are exhausted. We recruit 24 human experts, at least 2 per task, and take the best expert attempt per task as the expert baseline. We evaluate 20 models released between 2023 and 2026. The best-performing model, Opus 5.5, exceeds our expert baseline, with a compute multiplier of 2.3x (95% CI 1.15-4.37), at roughly 1/30 of our baseliners' average per-run cost. On TasteVal, the compute multiplier of frontier models has doubled approximately every 3.0 months since December 2025 (95% CI 1.7-5.0), up from every 14 months between 2023 and December 2025. Measured by final normalized performance, frontier models show no trend break, doubling every 14.6 months. To keep TasteVal uncontaminated, we do not release the tasks.
Verification in the Age of AI Scientists
AI Scientists now operate at a scale that outpaces human capacity for manual review. Systems such as Sakana’s AI Scientist write entire workshop papers end-to-end. Lila Sciences runs autonomous ``AI Science Factories’’ that hypothesize, experiment, and iterate without human guidance. FutureHouse’s Kosmos and Robin generate thousands of candidate hypotheses in a single run, and Google’s Co-Scientist proposes testable experiments at a rate no laboratory can fully evaluate. Each of these systems emphasizes verified results, yet that standard ranges from near-perfect formal proof in mathematics to decade-long clinical trials in medicine, with no shared framework for judging sufficiency across domains. As outputs scale beyond what humans can manually inspect, the question of which results to trust becomes as hard as generating them. The bottleneck for AI for Science is no longer hypothesis generation, it is verification.
AI coding agents generate more code, but not more software
Study finds coding efficiency gains get "absorbed" by human review "bottleneck."
Agent Skills
AI coding agents take the shortest path to done, which usually means skipping the specs, tests, and reviews that make software reliable at scale. Agent Skill...
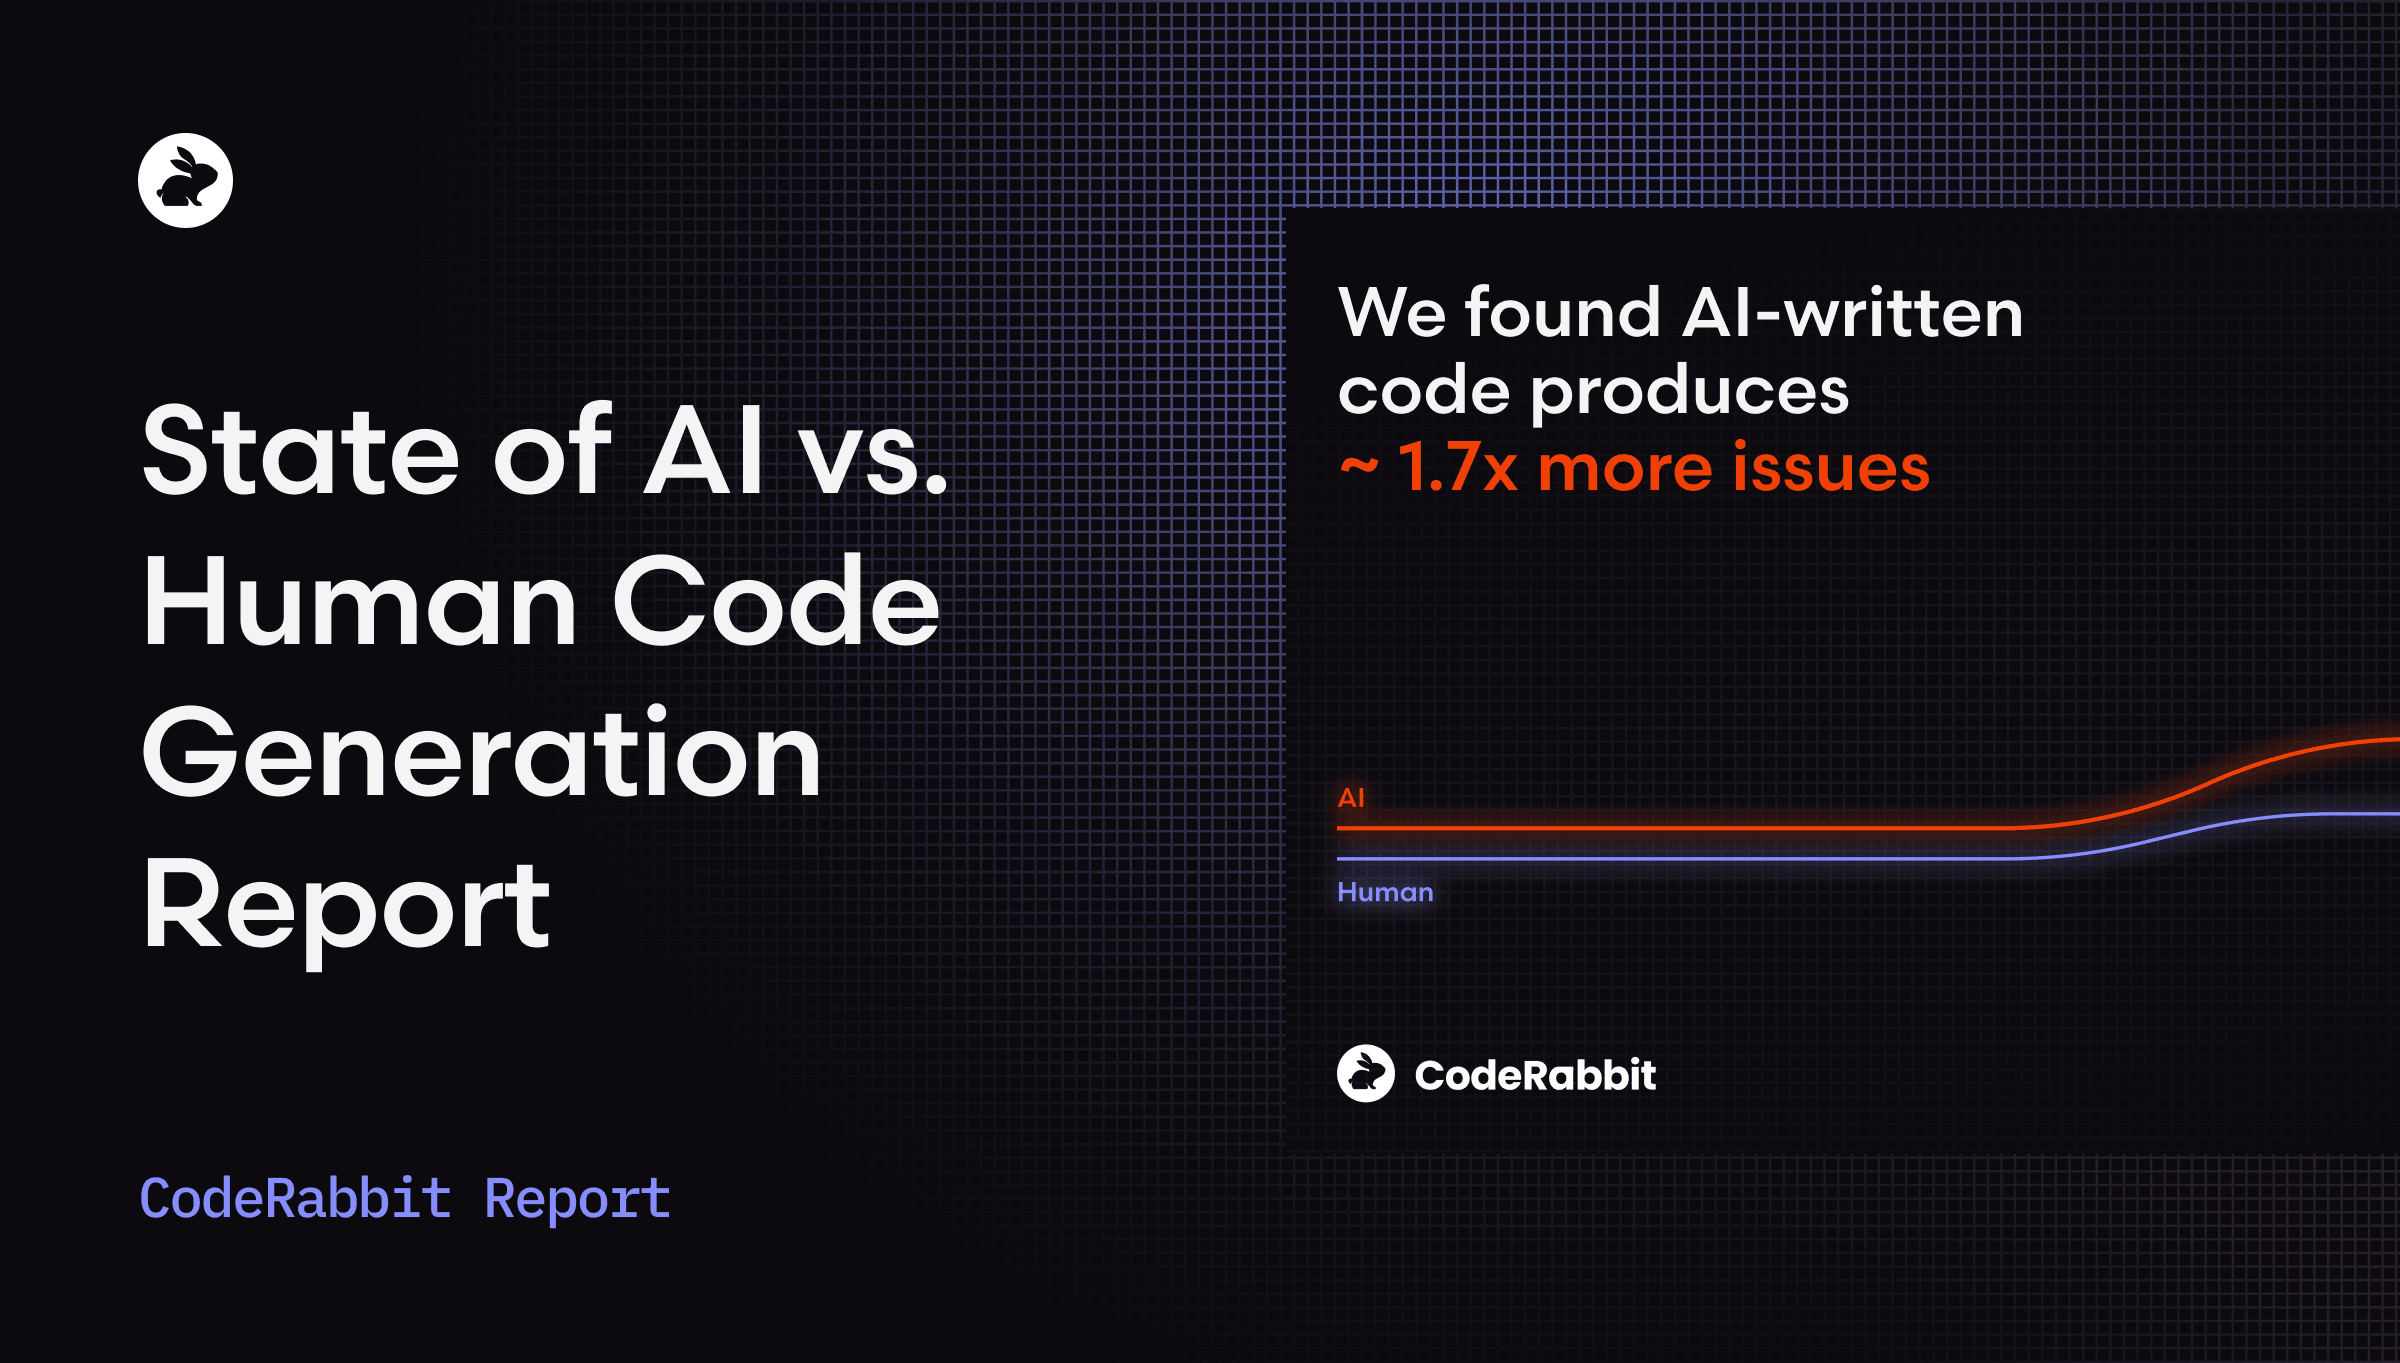
AI vs human code gen report: AI code creates 1.7x more issues
We analyzed 470 open-source GitHub pull requests, using CodeRabbit’s structured issue taxonomy and found that AI generated code creates 1.7x more issues.
AI Coding Agent Benchmarks & Leaderboard | Artificial Analysis
We measure real-world performance of coding agents on software engineering tasks, including cost, token usage, and execution time. We compare how performance changes across agents, models, and execution settings.