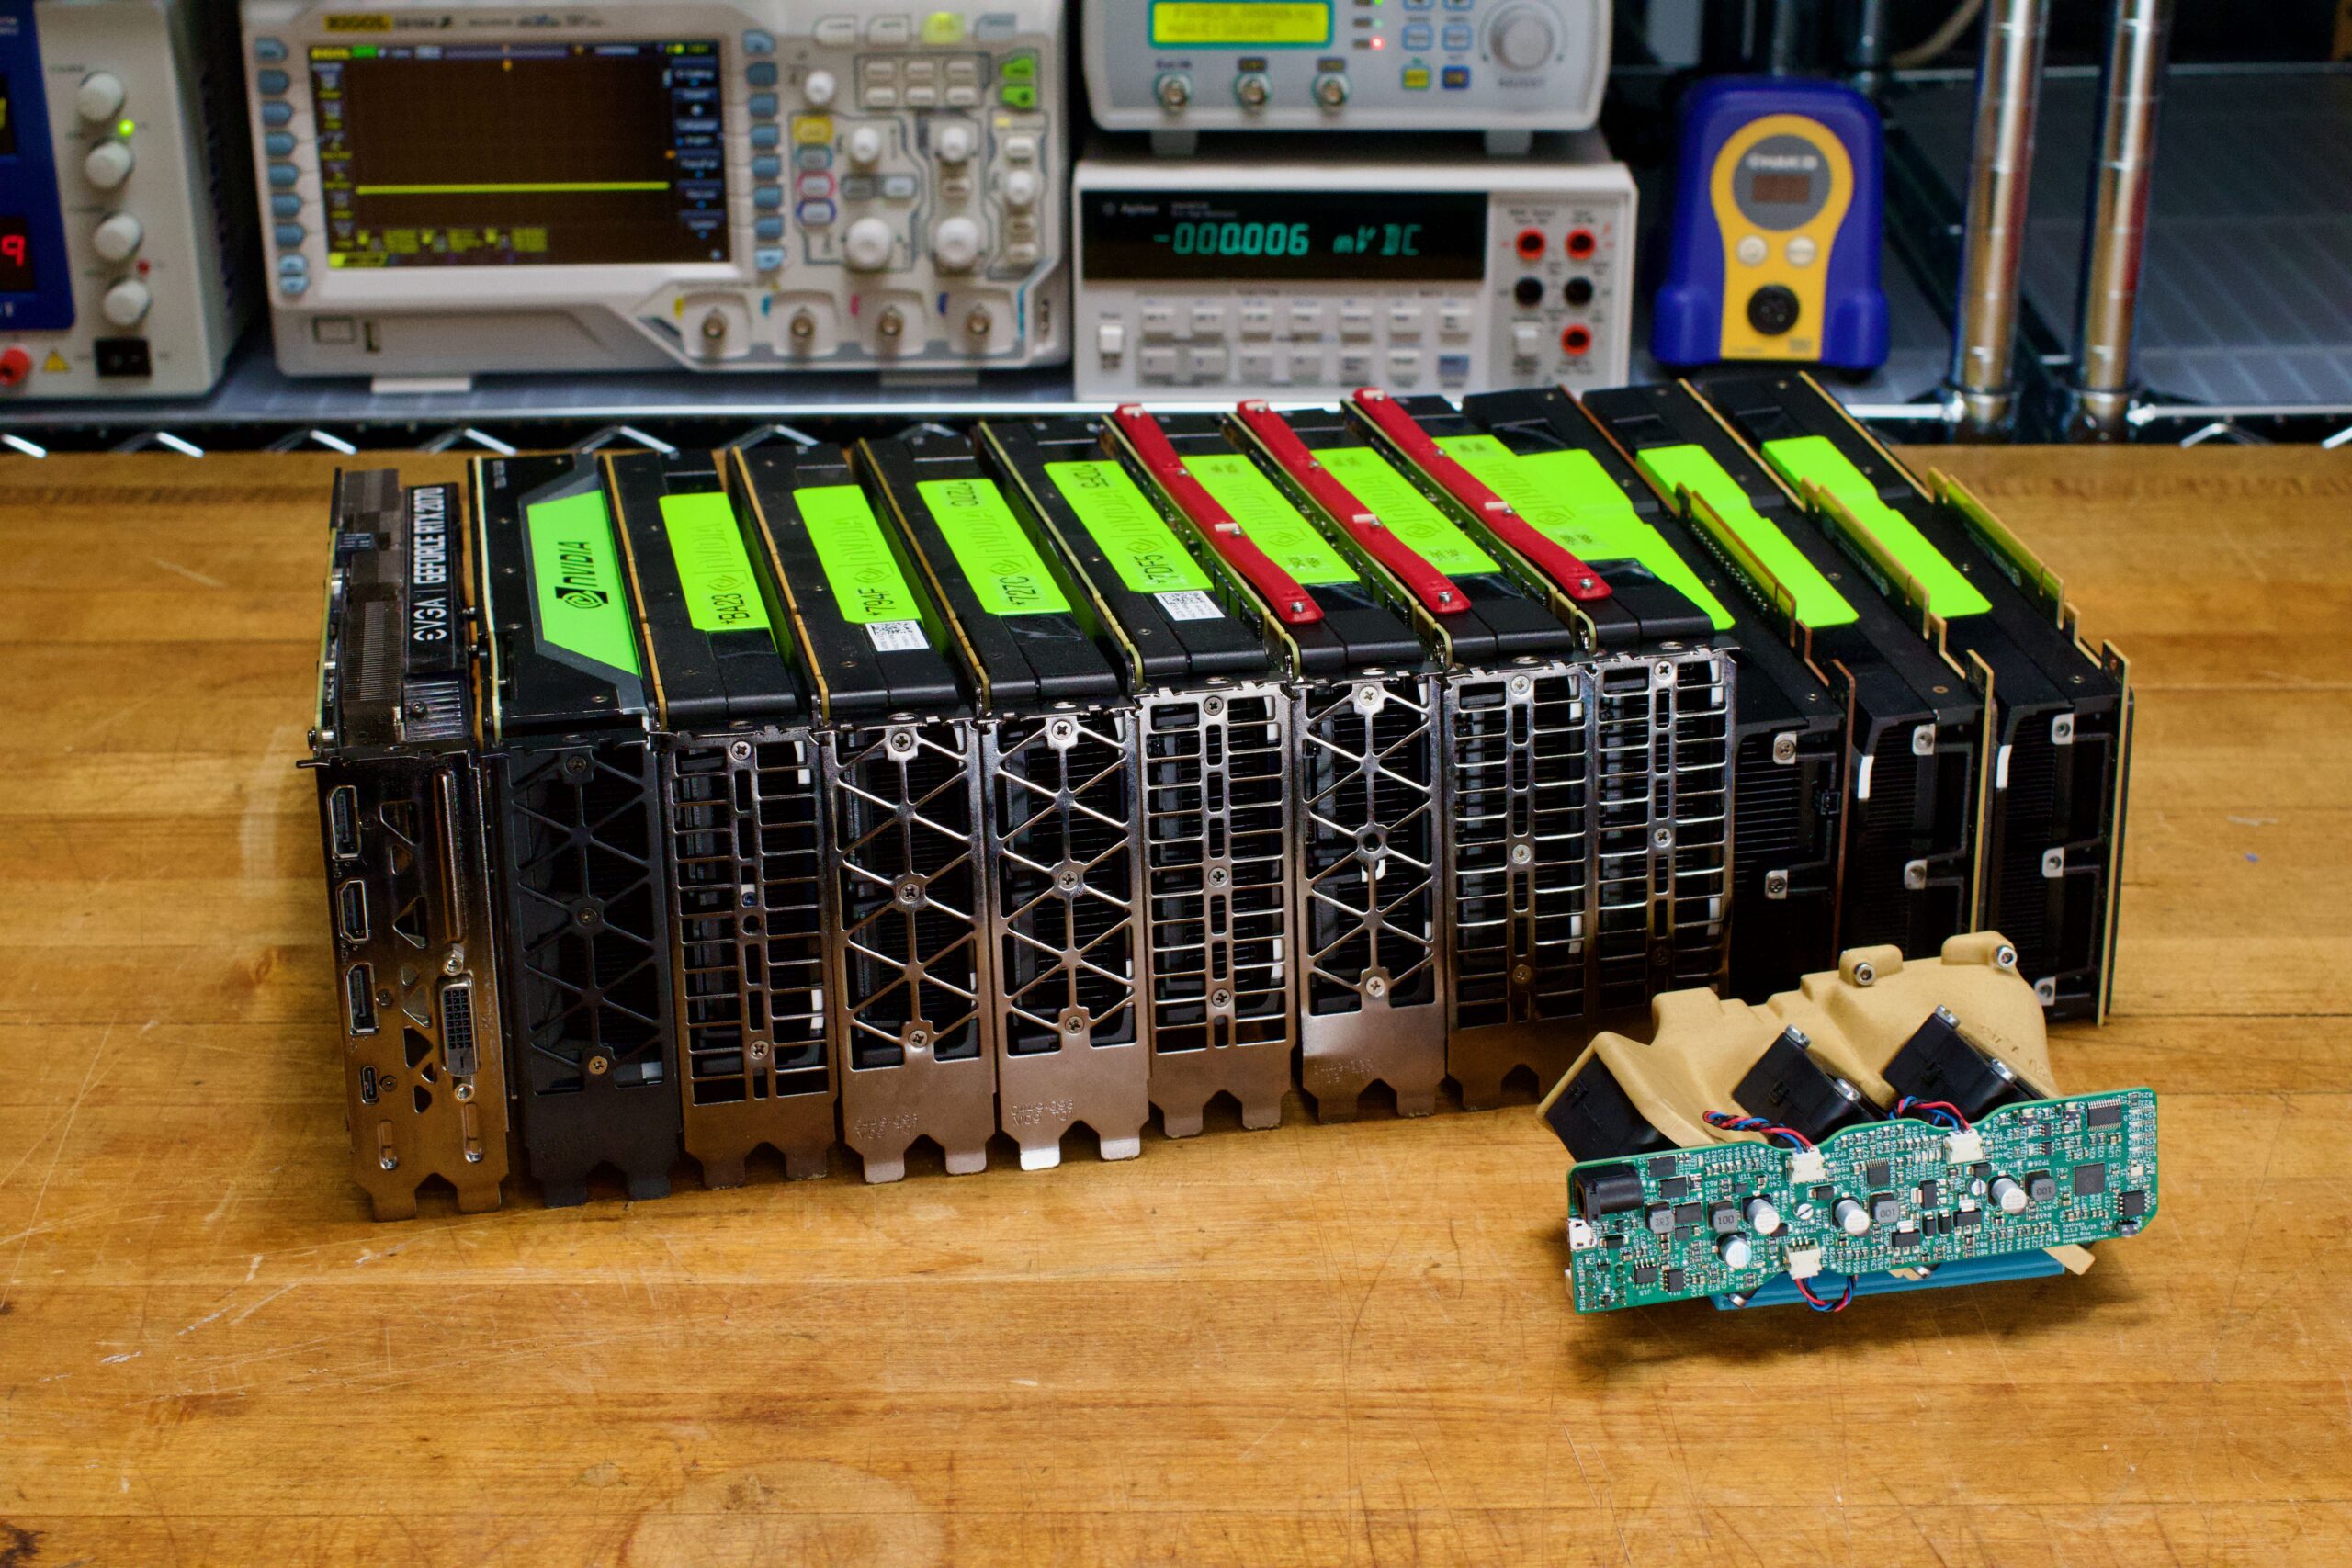
Decommissioned enterprise tesla GPUs are widely available and extremely cheap. In this post, I benchmark tesla GPUs to see if they are useful
InferenceMAX™: Open Source Inference Benchmarking
NVIDIA GB200 NVL72, AMD MI355X, Throughput Token per GPU, Latency Tok/s/user, Perf per Dollar, Tokens per Provisioned Megawatt, DeepSeek R1 670B, GPTOSS 120B, Llama3 70B
vik on Twitter / X
Photon, our inference engine, isn't fast just because of GPU kernels. A lot of the speedup comes from engine-level work: request scheduling, prefix caching, image processing, all tuned to keep the GPU saturated. https://t.co/3M7eFcFKo5— vik (@vikhyatk) May 2, 2026
Christian Legnitto Interview, Maintainer: rust-gpu, rust-cuda [Rust Project Content @ RustConf 2025]
Open Source AI Inference Benchmark | InferenceX
Compare AI inference performance across GPUs and frameworks. Real benchmarks on NVIDIA GB200, B200, AMD MI355X, and more. Free, open-source, continuously updated.
RightNow AI - YC-Backed GPU Research Lab
YC-backed GPU research lab building the RightNow CUDA editor, RunInfra inference infra, Forge kernels, and publishing AutoMegaKernel and related papers on arXiv.
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
H100 PCIe vs SXM vs NVL: Which H100 GPU Is Fastest and Most Cost-Effective for Fine-Tuning LLMs?
Benchmarking all three H100 variants for full, LoRA, and QLoRA fine-tuning
ASUS Ascent GX10
Desktop AI supercomputer delivering up to 1 petaFLOP performance, powered by NVIDIA GB10 Grace Blackwell Superchip, supporting OpenClaw and Hermes Agent.
Modern GPU Programming For MLSys — Modern GPU Programming For MLSys
Machine learning systems sit at the heart of modern AI workloads. In these systems, performance often comes down to the quality of a small number of GPU kernels. Attention kernels, LLM prefill and decode kernels, low-precision block-scaled GEMMs, fused MoE layers, and other large fused kernels all directly shape end-to-end speed in both training and serving.
XiongjieDai/GPU-Benchmarks-on-LLM-Inference
Multiple NVIDIA GPUs or Apple Silicon for Large Language Model Inference?
Chris Lattner on Twitter / X
Please don’t tell anyone: we aren’t just open sourcing all the models. We are doing the unspeakable: open sourcing all the gpu kernels too. Making them run on multivendor consumer hardware, and opening the door to folks who can beat our work.Plz keep it quiet, ok? 😉— Chris Lattner (@clattner_llvm) March 24, 2026
First Drive in Fully Autonomous Tesla!
NVIDIA DGX Spark· Ollama Blog
The latest NVIDIA DGX Spark is here! Ollama has partnered with NVIDIA to ensure it runs fast and efficiently out-of-the-box.