

Explore OpenSEO's architecture: SEO data APIs, Cloudflare Workers, its audit crawler, MCP tools, AI agents, storage, and self-hosting trade-offs.
Cloudflare and OpenAI: making AI discovery better for everyone
How Cloudflare and OpenAI are working together to help AI find useful content, keep up with changes, and make fewer wasted requests – making the experience better for users and website owners alike.

Google for Developers Blog - News about Web, Mobile, AI and Cloud
Explore how Google, Amazon, and Cisco form the Agent2Agent Foundation under the Linux Foundation to drive AI innovation via interoperability as an industry standard.
"Build protocols, not platforms"
Exploring the 'Protocols, Not Platforms' paper alongside a curated digest of recent AI crawler policy shifts and developer experiments.
Google for Developers Blog - News about Web, Mobile, AI and Cloud
An open specification for finding and verifying tools, skills, and agents across the web.Agents are ...

Google for Developers Blog - News about Web, Mobile, AI and Cloud
An open specification for finding and verifying tools, skills, and agents across the web.Agents are ...
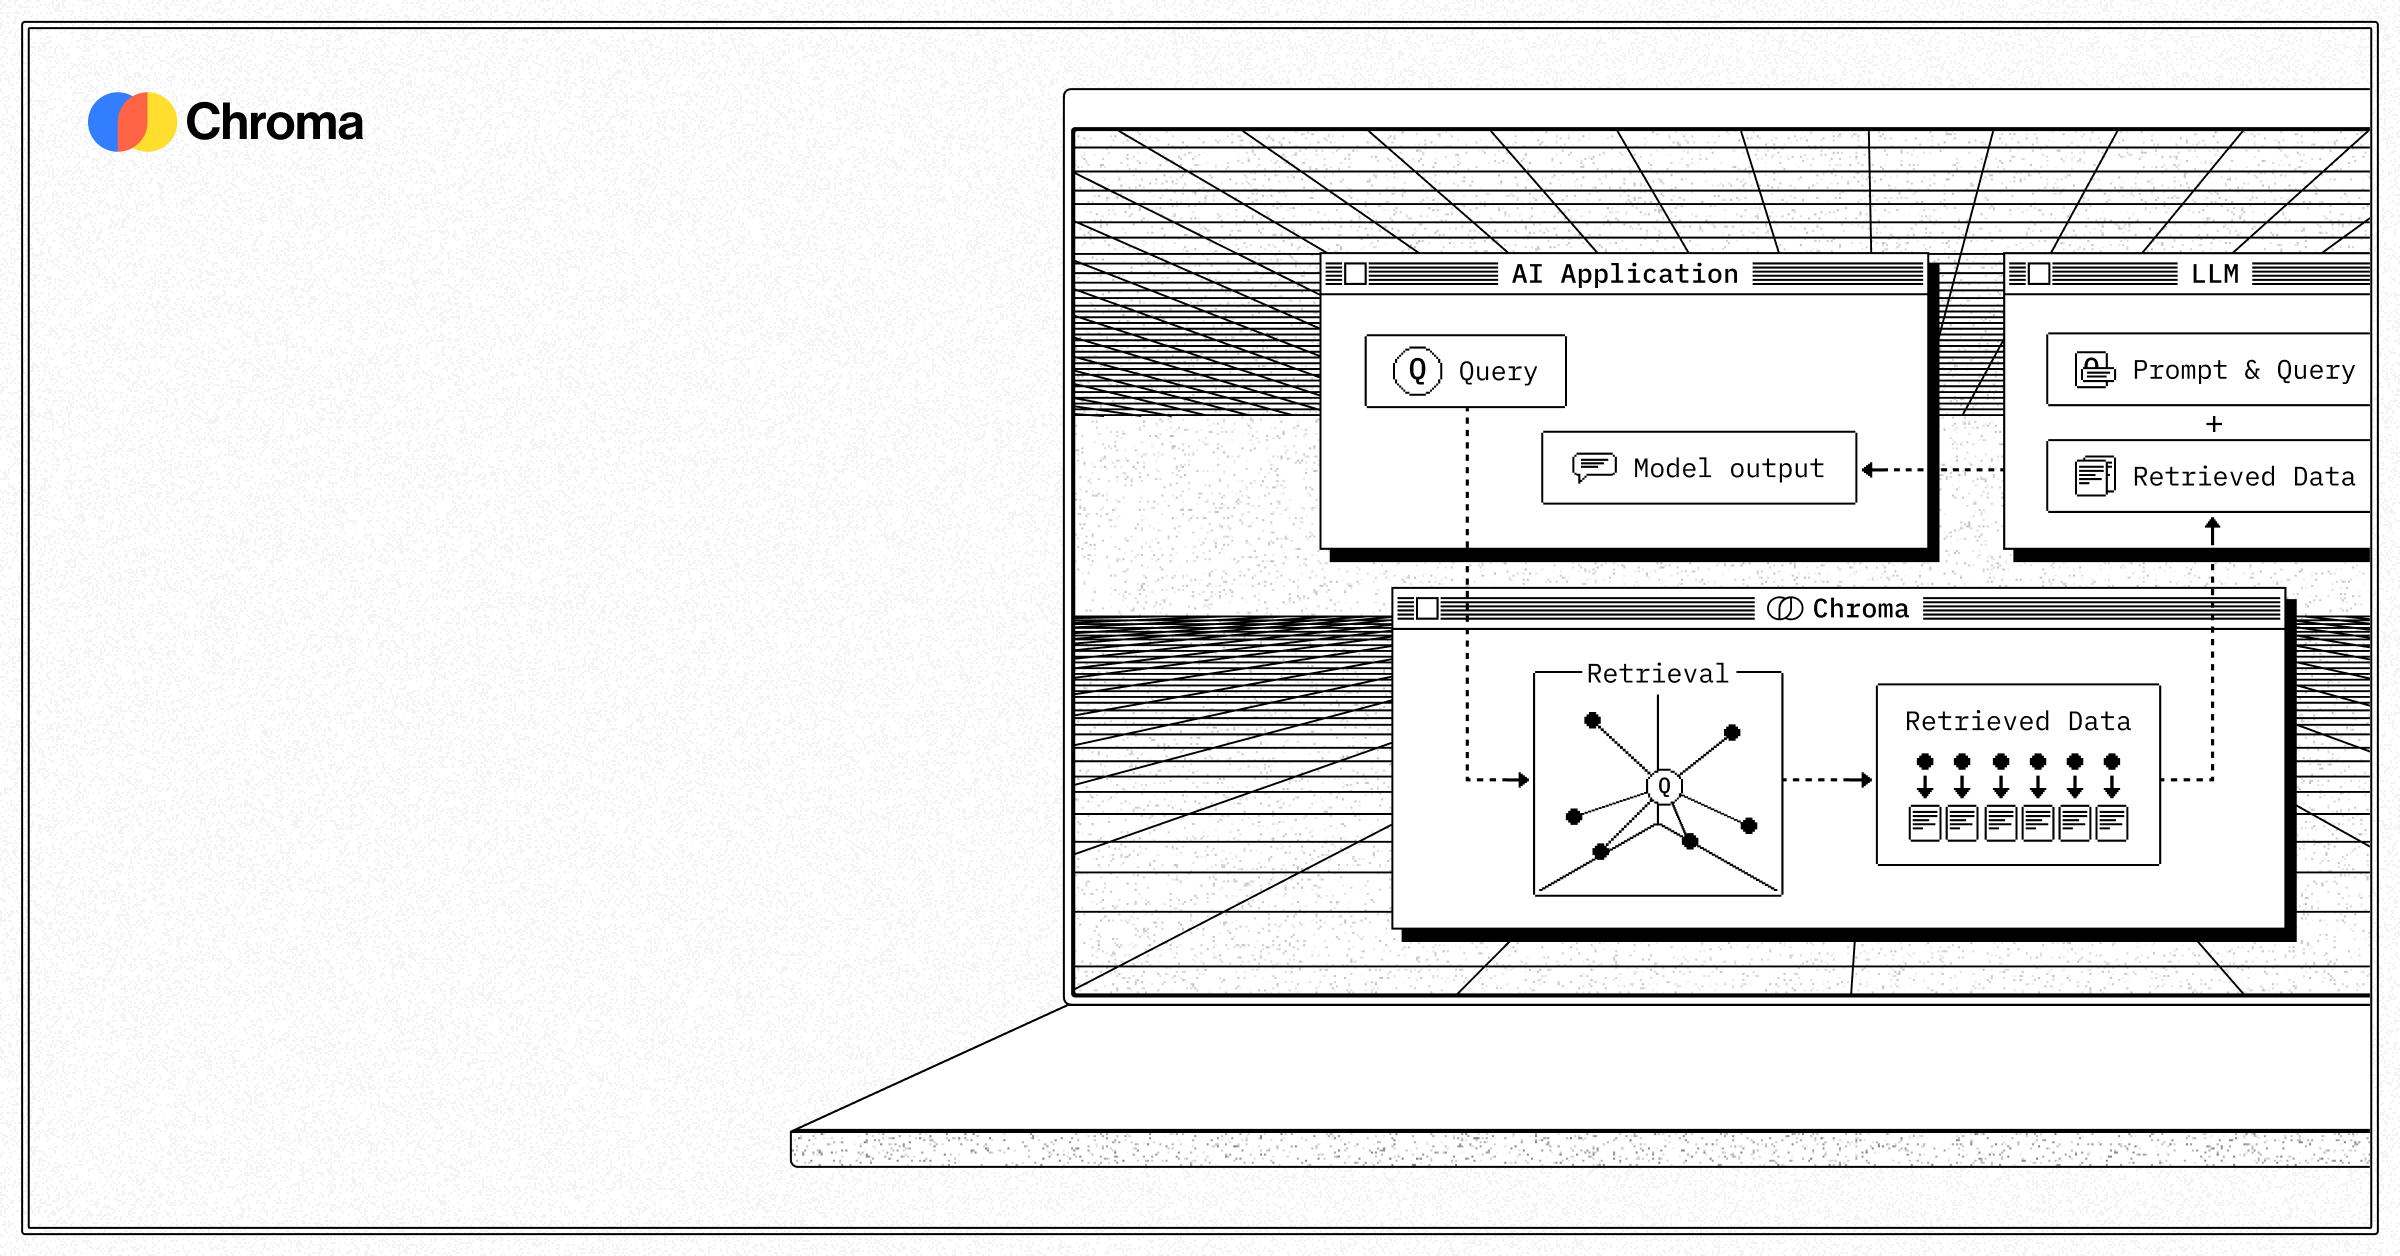
Chroma - open-source search infrastructure for AI
Open-source search infrastructure for AI
Common Crawl - Open Repository of Web Crawl Data
We build and maintain an open repository of web crawl data that can be accessed and analyzed by anyone.
New data agents across the Agentic Data Cloud | Google Cloud Blog
Learn about new data agents and tools for business analysts, data scientists, and database admins to integrate with the Agentic Data Cloud.
goose | Your open source AI agent
Your native open source AI agent. Desktop app, CLI, and API — for code, workflows, and everything in between.
goose | Your open source AI agent
Your native open source AI agent. Desktop app, CLI, and API — for code, workflows, and everything in between.
Is Misinformation More Open? A Study of robots.txt Gatekeeping on the Web
Web scraping, the automated process of extracting information from websites, has long played a foundational role in the Internet ecosystem (Gray, 1995). It supports services such as search engine indexing, price comparison tools, and competitive intelligence. More recently, it has become a core component in the development of large-scale generative AI models. These Large Language Models (LLMs) require enormous volumes of training data, often in the terabyte range (Kaplan et al., 2020; Lehane, 2025), and the public web remains a low-cost, attractive source. Major model developers, including those behind OpenAI’s Chat-GPT (OpenAI, 2025), Google’s Bard (now known as Gemini) & Vertex AI (Romain, Danielle, 2023), and Anthropic’s Claude (Romain, Danielle, 2025), openly acknowledge the use of web scraping to construct their training corpora (Abdin et al., 2024; Brown et al., 2020; Chowdhery et al., 2023; Grattafiori et al., 2024; Team et al., 2024; Touvron et al., 2023).
AI proxy: fostering a more open ecosystem - Blog - Braintrust
Introducing Braintrust's latest feature: an AI proxy that lets you use open source models like LLaMa 2 and Mistral, as well as all of OpenAI's and Anthropic's models, behind a single interface with caching, security, and API key management built in.
Why it's so easy to find open, exposed AI servers on the web
A look at vulnerable AI servers, especially self-hosted Ollama, and how to avoid that exposure.
DataLicenses.org
Machine-readable hints for AI agents/crawlers; easy to adopt, rely on compliance.
Cloudflare's Matthew Prince has a plan to get Google and the AI oliigarchs to pay for your content even though many are used to getting it for free. He might have enough leverage to make them.
AI chatbots are blowing up the 30-year economic relationship publishers have had with search engines. Many think this will kill the web if not addressed. Google needs to change first. It's resisting. Cloudflare's Matthew Prince is going to try and make them.
