Low-latency inference for VLM, TTS, and STT with orchestration for making realtime apps.
Serving Voice AI at $1/hr: Open-source, LoRAs, Latency, Load Balancing - Neil Dwyer, Gabber
Realtime and audio | OpenAI API
Learn which realtime and audio guide to use for each speech application.
How OpenAI delivers low-latency voice AI at scale
How OpenAI rebuilt its WebRTC stack to power real-time Voice AI with low latency, global scale, and seamless conversational turn-taking.
Introducing Open Intelligent UI | The Open-Source Alternative to ChatGPT's Intelligent UI
Chat is not the future interface. It's the future router.
Why AI won't replace your apps, but your home screen
Realtime voice, video, and AI for developers - Daily
Daily is the team behind Pipecat. Ultra low latency, open source SDKs, and enterprise reliability since 2016.

A backend for AI-coded apps
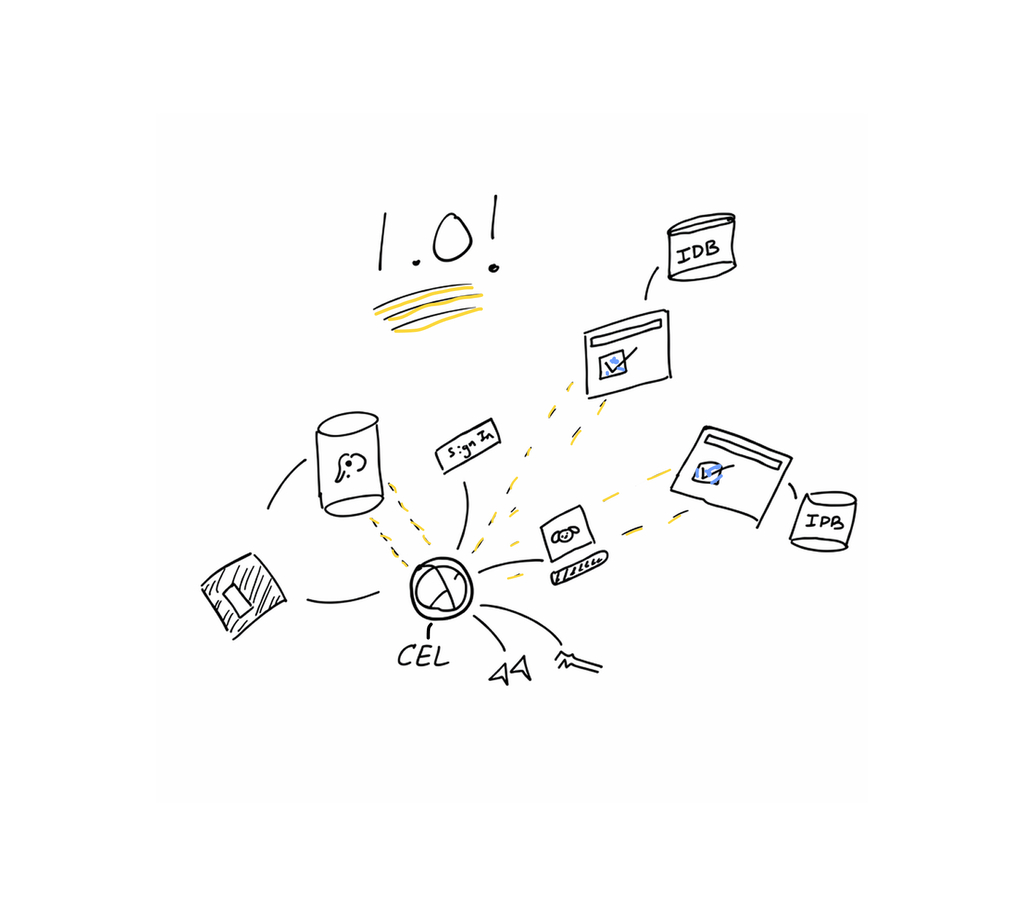
Instant 1.0 is out! This essay shows a bunch of demos, to explain why we think Instant is the best backend for AI-coded apps. We also cover the architecture that makes all of it work.
Pipecat Cloud: Enterprise Voice Agents Built On Open Source - Kwindla Hultman Kramer, Daily
On-device intelligence for every product
We're building a frontier lab for on-device AI. Small, specialized models for audio, vision, and text, faster than the cloud and free.
ChatGPT Voice can keep talking while it works - Sensemaker
OpenAI’s GPT-Live splits live conversation from slower search, reasoning, and agent work in the background.
ICML WhisperKit: On-device Real-time ASR with Billion-Scale Transformers
Real-time Automatic Speech Recognition (ASR) is a fundamental building block for many commercial applications of ML, including live captioning, dictation, meeting transcriptions, and medical scribes. Accuracy and latency are the most important factors when companies select a system to deploy. We present WhisperKit, an optimized on-device inference system for real-time ASR that significantly outperforms leading cloud-based systems. We benchmark against server-side systems that deploy a diverse set of models, including a frontier model (OpenAI gpt-4o-transcribe), a proprietary model (Deepgram nova-3), and an open-source model (Fireworks large-v3-turbo).Our results show that WhisperKit matches the lowest latency at 0.46s while achieving the highest accuracy 2.2\% WER. The optimizations behind the WhisperKit system are described in detail in this paper.
OpenAI partners with Cerebras
OpenAI partners with Cerebras to add 750MW of high-speed AI compute, reducing inference latency and making ChatGPT faster for real-time AI workloads.
What makes a great ChatGPT app | OpenAI Developers
How to build capabilities that make conversations better.
The path to ubiquitous AI | Taalas
By Ljubisa Bajic Many believe AI is the real deal. In narrow domains, it already surpasses human performance. Used well, it is an unprecedented amplifier of human ingenuity and productivity. Its widespread adoption is hindered by two key barriers: high latency and astronomical cost. Interactions with language models lag far...