

Probability-aware evaluation for typed decision models: calibration, selective risk, latency, and reproducible benchmarks. - AbdelStark/jev-benchmarks
JevBench — AI decision model benchmark & leaderboard
Compare AI decision models on accuracy, probability calibration, latency and cost. JevBench by Benchmark Heaven ranks open-weights decision models by the JevBench Capability Score, with methodology and reproducible aggregate results.
Laya — 33ms Multilingual System 1 Decision Engine
Evaluates typed decisions (choice, score, noul) over 100+ languages in a single forward pass with calibrated probabilities. Outperforms TypeSafe Jev.
Decision Index 0.3
Open reproductions of Jev ranked by the Full score: public benchmarks plus private tests and private tasks from new domains. Switch to the public board alone or to the vision board.

Jev Decision Index - a Hugging Face Space by multimodalart
Benchmarks and news on various repros of TypeSafe's Jev
inanna-malick/jev-dsl
Agent-first Haskell DSL for TypeSafe's Jev judgment model: typed packets, inferred types, answers under the same labels
Speed Comparison - Programming Languages
Benchmarks run on GitHub Actions. Results may vary based on runner hardware.
Model Performance Evaluation to SubQ 1.1 Small Preview Performance Evaluation | Appen
A third-party benchmark assessment of Subquadratic's preview models, conducted by Appen across long-context retrieval, code generation, business-workflow automation, and graduate-level reasoning benchmarks.
Perplexity Decider v1.3: Training, eval, and use cases
How we train and evaluate Decider v1.3 and Decider Flash, with locate extraction, real-world results, and costs.
BetterBench: Assessing AI Benchmarks, Uncovering Issues, and Establishing Best Practices
AI models are increasingly prevalent in high-stakes environments, necessitating thorough assessment of their capabilities and risks. Benchmarks are popular for measuring these attributes and for comparing model performance, tracking progress, and identifying weaknesses in foundation and non-foundation models. They can inform model selection for downstream tasks and influence policy initiatives. However, not all benchmarks are the same: their quality depends on their design and usability. In this paper, we develop an assessment framework considering 46 best practices across an AI benchmark's lifecycle and evaluate 24 AI benchmarks against it. We find that there exist large quality differences and that commonly used benchmarks suffer from significant issues. We further find that most benchmarks do not report statistical significance of their results nor allow for their results to be easily replicated. To support benchmark developers in aligning with best practices, we provide a checklist for minimum quality assurance based on our assessment. We also develop a living repository of benchmark assessments to support benchmark comparability, accessible at betterbench.stanford.edu.

SimpleQA Verified: A Reliable Factuality Benchmark to Measure Parametric Knowledge
We introduce SimpleQA Verified, a 1,000-prompt benchmark for evaluating Large Language Model (LLM) short-form factuality based on OpenAI's SimpleQA. It addresses critical limitations in OpenAI's benchmark, including noisy and incorrect labels, topical biases, and question redundancy. SimpleQA Verified was created through a rigorous multi-stage filtering process involving de-duplication, topic balancing, and source reconciliation to produce a more reliable and challenging evaluation set, alongside improvements in the autorater prompt. On this new benchmark, Gemini 2.5 Pro achieves a state-of-the-art F1-score of 55.6, outperforming other frontier models, including GPT-5. This work provides the research community with a higher-fidelity tool to track genuine progress in parametric model factuality and to mitigate hallucinations. The benchmark dataset, evaluation code, and leaderboard are available at: https://www.kaggle.com/benchmarks/deepmind/simpleqa-verified.
SimpleQA Verified: A Reliable Factuality Benchmark to Measure Parametric Knowledge
We introduce SimpleQA Verified, a 1,000-prompt benchmark for evaluating Large Language Model (LLM) short-form factuality based on OpenAI's SimpleQA. It addresses critical limitations in OpenAI's benchmark, including noisy and incorrect labels, topical biases, and question redundancy. SimpleQA Verified was created through a rigorous multi-stage filtering process involving de-duplication, topic balancing, and source reconciliation to produce a more reliable and challenging evaluation set, alongside improvements in the autorater prompt. On this new benchmark, Gemini 2.5 Pro achieves a state-of-the-art F1-score of 55.6, outperforming other frontier models, including GPT-5. This work provides the research community with a higher-fidelity tool to track genuine progress in parametric model factuality and to mitigate hallucinations. The benchmark dataset, evaluation code, and leaderboard are available at: https://www.kaggle.com/benchmarks/deepmind/simpleqa-verified.
Decision-style Model Examples

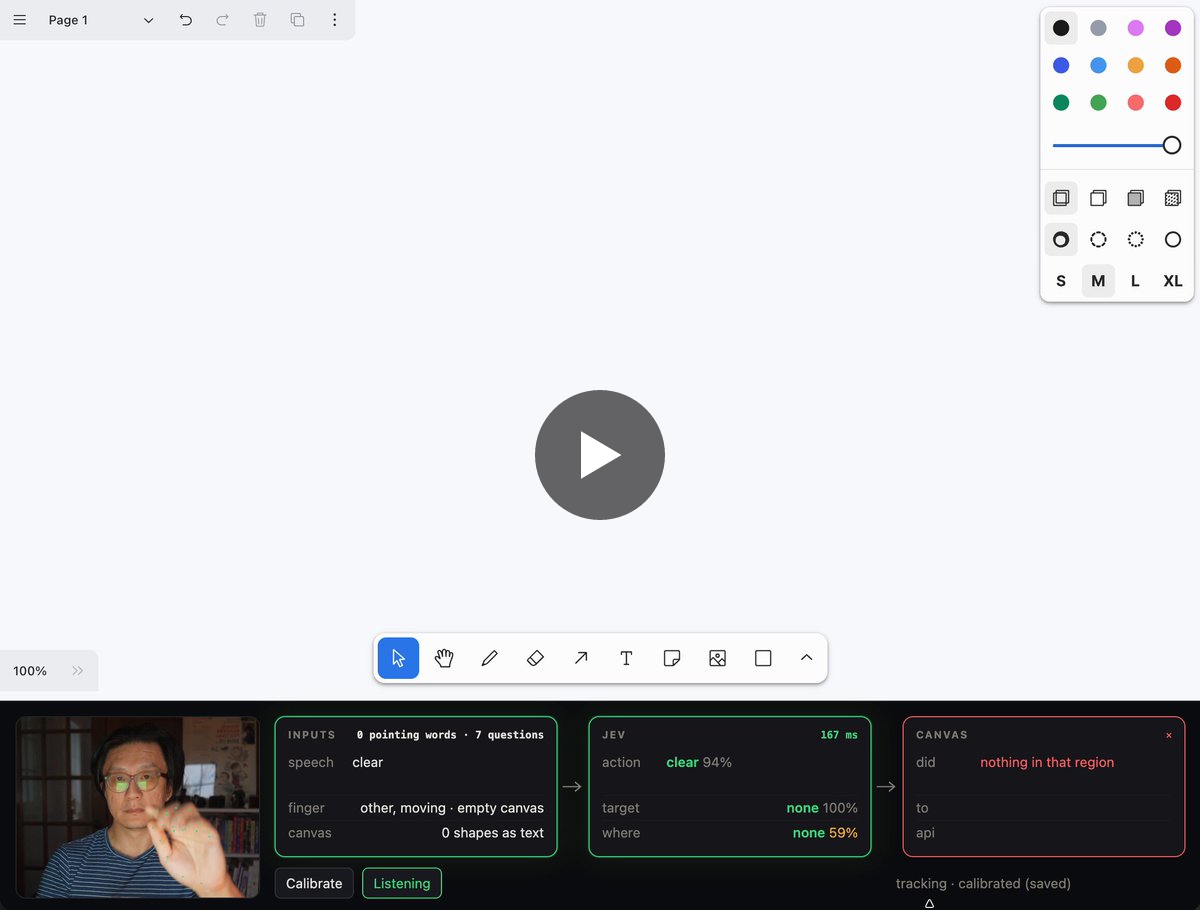
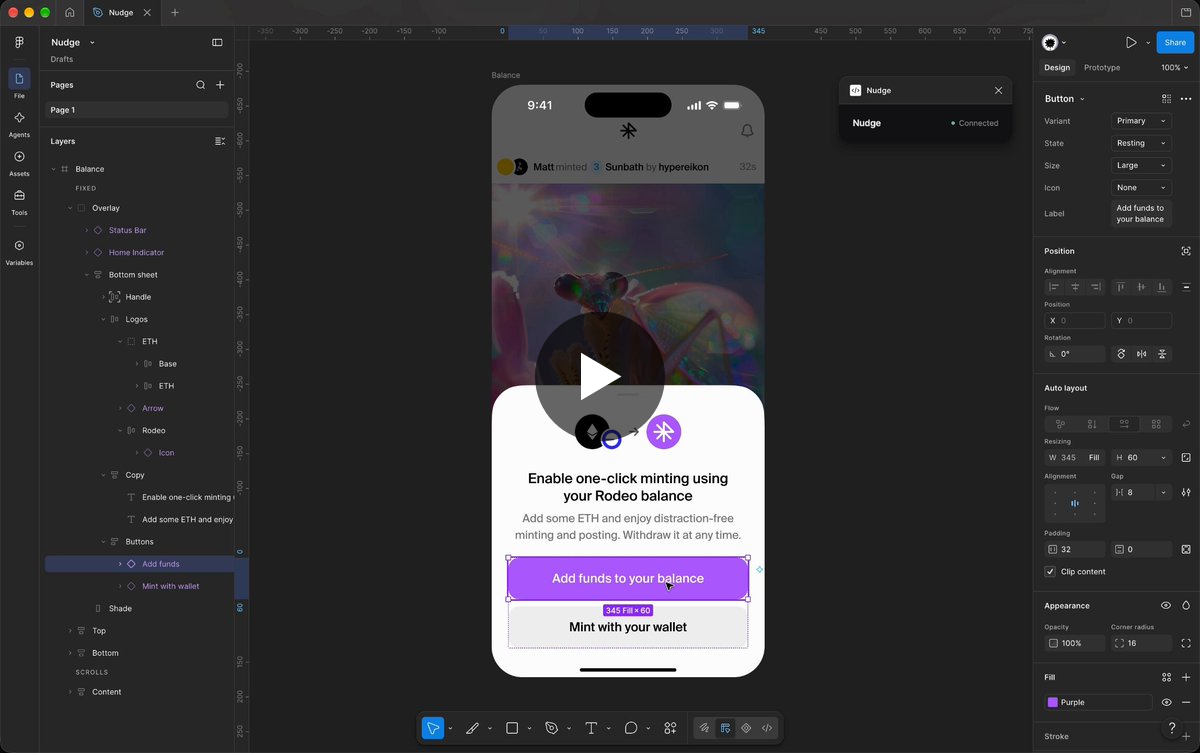
Decision-style models, like TypeSafe's Jev model, are fast and cheap models that output structured data that has been opening a lot of doors for interesting HCI applications. Here I'll collect interesting examples I come across.
Matt DesLauriers on Twitter / X
Jack Cheng on Twitter / X

Andy Gao on Twitter / X

Chris Tate on Twitter / X
mikegee on Twitter / X

Marek Sotak on Twitter / X