Systematic LLM inference benchmark for Apple Silicon: 8 backends, 7 models, 791 measurements - AlexHiesch/apple-silicon-llm-bench
Benchmarks | EXO
Transparent benchmarks for LLMs tested on real hardware. Coming soon.
jundot/omlx
LLM inference server with continuous batching & SSD caching for Apple Silicon — managed from the macOS menu bar
oMLX — LLM inference, optimized for your Mac
Native macOS inference server built on MLX with paged SSD KV caching for Apple Silicon.
XiongjieDai/GPU-Benchmarks-on-LLM-Inference
Multiple NVIDIA GPUs or Apple Silicon for Large Language Model Inference?
Doriandarko/MLX-GRPO
A pure MLX-based training pipeline for fine-tuning LLMs using GRPO on Apple Silicon.
Exploring LLMs with MLX and the Neural Accelerators in the M5 GPU
Mac with Apple silicon is increasingly popular among AI developers and researchers interested in using their Mac to experiment with the…

mzau/broke-cluster
A Poor Man's Apple Silicon LLM Cluster — tuned for MLX, scalable without shame.
Optimizing On-Device Inference for Apple Silicon
A custom local engine that improves prefill and decode throughput
Local and Distributed Large LLM Inference with MLX and RDMA on Mac Studio
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private…
ethicalabs-ai/BlossomTuneLLM-MLX
Federated Fine-Tuning of LLMs on Apple Silicon with Flower.ai and MLX-LM
videlalvaro/ane-book
Production LLM inference on the Apple Neural Engine — a practitioner's guide, complete with converters, Swift runtimes, and validated model manifests
Geek Lite on Twitter / X
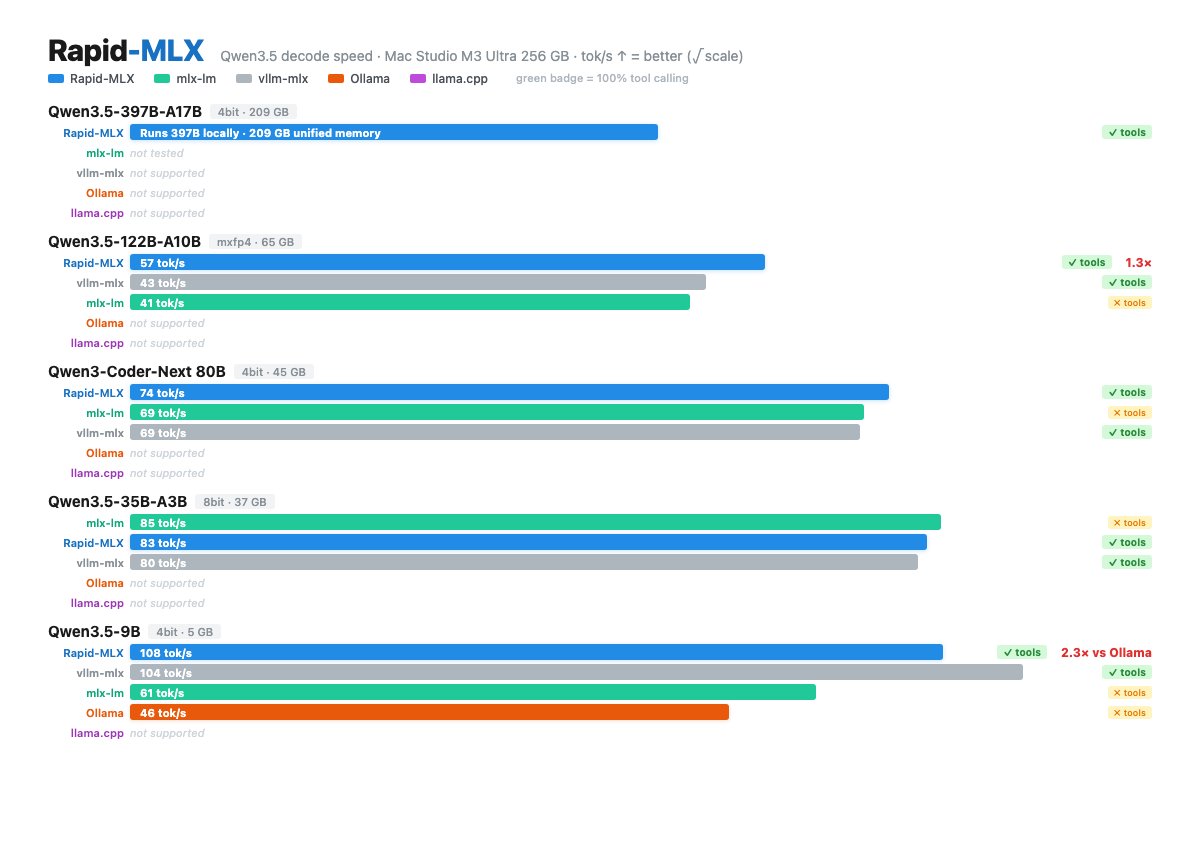
在 Apple Silicon Mac 上本地运行 LLM 推理服务,提供比 Ollama 和 llama.cpp 更快的 OpenAI 兼容 API,同时原生支持工具调用和提示缓存。https://t.co/IXet9GW7x0Rapid-MLX 用 Apple 自家的 MLX 框架做推理,搭了个 FastAPI 服务跑 OpenAI 兼容 API。在 Apple Silicon 上比 Ollama 快 2-4 倍,靠… pic.twitter.com/d9QUbAWJSZ— Geek Lite (@QingQ77) May 3, 2026
The Big LLM Architecture Comparison
From DeepSeek-V3 to Kimi K2: A Look At Modern LLM Architecture Design
Megakernel: Matching Apple Silicon Efficiency at 2x the Throughput on a RTX 3090
The first megakernel for hybrid DeltaNet/Attention LLMs. 413 tok/s at 1.87 tok/J on a 2020 RTX 3090, matching M5 Max efficiency at 1.8x throughput.