

🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
Caveman | Lithic Token Compression
A semantic constraint engine for Claude Code & Codex. Forces agentic communication into minimal-token lithic structures. Retain 100% technical accuracy while destroying up to 87% of output latency.
claude-code/plugins/ralph-wiggum at main · anthropics/claude-code
Claude Code is an agentic coding tool that lives in your terminal, understands your codebase, and helps you code faster by executing routine tasks, explaining complex code, and handling git workflo...
1Password for Claude: Give Claude access without giving up your credentials | 1Password
Give Claude access, without giving up control of your secrets. 1Password now enables AI agents to complete tasks requiring credentialed access, while keeping your credentials encrypted, secure, and inaccessible to AI agents.

tokens are getting more expensive
"language models will get cheaper by 10x" will not save ai subscriptions from the short squeeze
Why Things Like TypeSafe AI Don't Interest Me
A handful of people showed up in the comments asking 'have you tried TypeSafe?'. I use that as a hook to lay out my rule about new AI tools, actually investigate the case, and explain why I don't waste time optimizing token spend.
Pluralistic: It’s extremely good that Claude’s source-code leaked (02 Apr 2026) – Pluralistic: Daily links from Cory Doctorow
Anthropic's developers made an extremely basic configuration error, and as a result, the source-code for Claude Code – the company's flagship coding assistant product – has leaked and is being eagerly analyzed by many parties:
Tokenization Tax 2026: LLM Tokenizer Comparison | ellamind
A measurement study of 20 LLM tokenizers across 12 languages and 21 kinds of text. On German, Claude 4.7+ needs 2.01x the tokens of the OpenAI reference, and Cohere Command A+ the fewest.
Perspective: AI demand is inflated, and only Anthropic is being realistic
The main usage metric for artificial intelligence, called tokens, looks explosive on paper, but it may be significantly overstated.

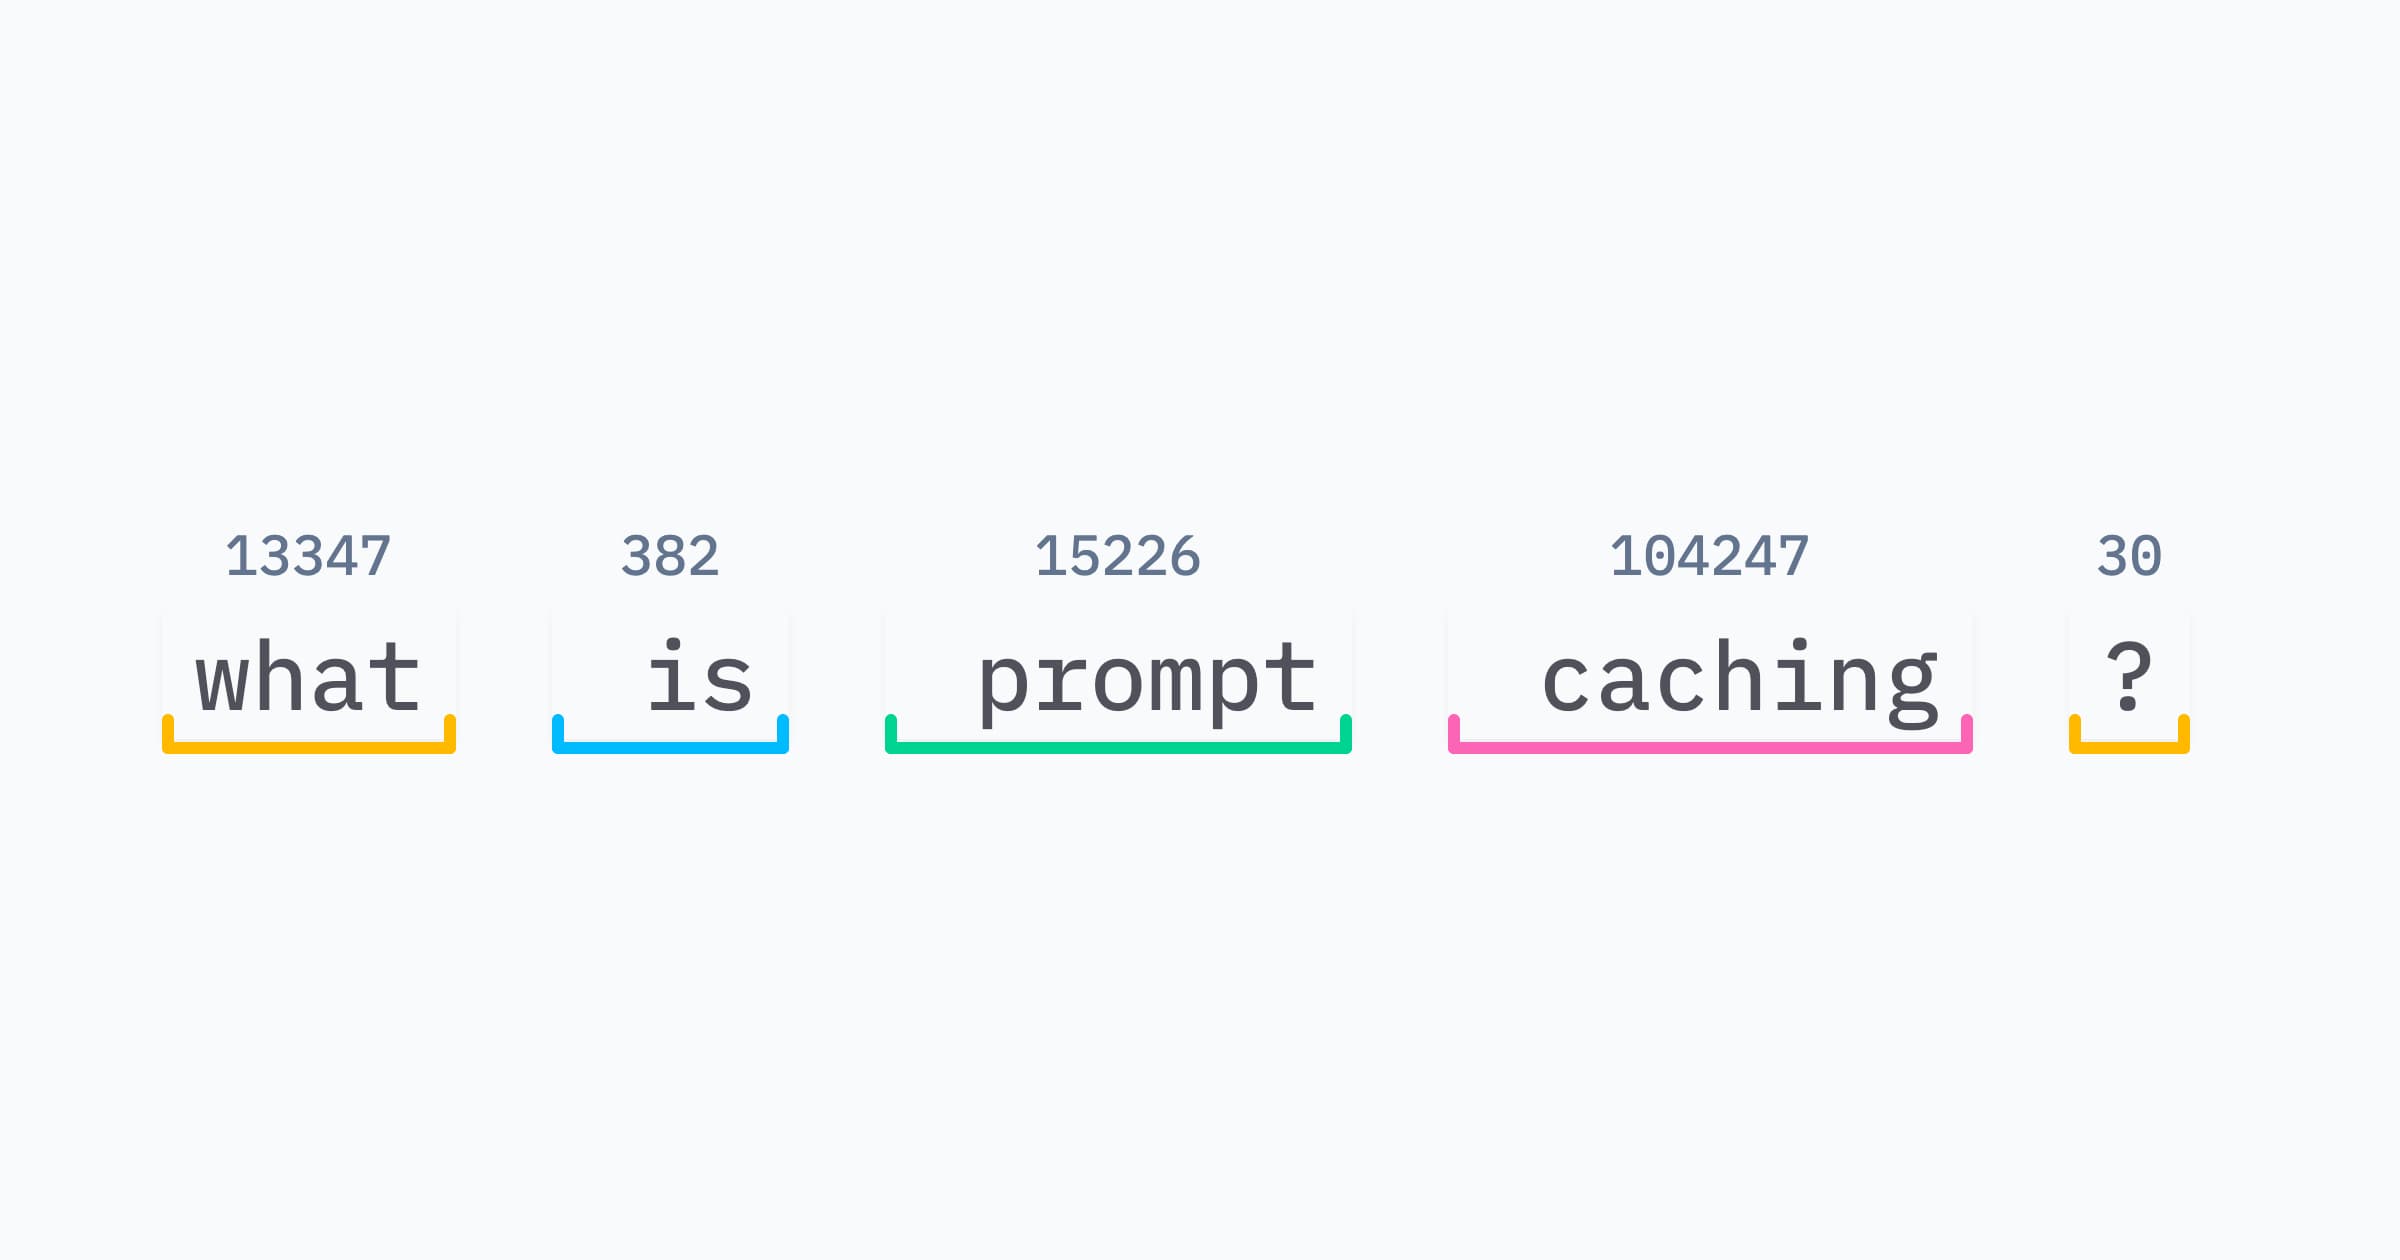
Prompt caching: 10x cheaper LLM tokens, but how? | ngrok blog
A far more detailed explanation of prompt caching than anyone asked for: how tokens, embeddings, and attention make cached LLM tokens 10x cheaper and faster.
Claude for Chrome | Claude
Bring Claude's AI assistance to your browser. Ask questions, analyze data, automate tasks, and navigate sites in Chrome. Works with Claude Code and Desktop.
Using AI to click around on a website burns 45x as many tokens as just using APIs
For AI agents, seeing is expensive
51 Ways to Spell the Image Giraffe: The Hidden Politics of Token Languages in Generative AI
Generative AI models don't operate on human languages – they speak in **tokens**. Tokens are computational fragments that deconstruct lan...
